Category: Blog

  • The Ireland and UK DevOps Roadshow

    We’re taking the roadshow across the water. Hope the plane makes it.

    AUS02544

    The Redgate DevOps Roadshow comes to Ireland and the Northern UK in June. We’ll be in these cities on these dates:

    • June 11 – Dublin (Grant)
    • June 13 – Glasgow (Grant)
    • June 14 – Manchester (Steve)

    We’ll also have one of Redgate’s amazing Solution Engineers, Huxley Kendall. He’ll be there to answer in-depth questions on the products and solutions that Redgate offers.

    This is a great chance to get exposure to the solutions Redgate offers for building and managing your database code, as well as ask questions about the challenges you face and how we might tackle them.

    Register today and join us for a great day in one of these cities.

  • Halfway Through

    I’m halfway through my crazy stretch of travel. I’m leaving today for Syracuse to see my daughter graduate college on Saturday. This is a nice trip, and a little break, but it’s still time away from home.

    I’ve been home 6 full days since Apr 14, with trips to the UK and Australia in that time. I have work trips next week, the following one, and then two weeks in the UK again. All told, in 9 weeks, I’m at home for 11 full days.

    My year so far:

    2024-05-14 12_21_15-TravelReport I’m coping so far, though I am a little worn out with the movement through time zones. I’m going to use the next few days to take it easy, relax, and try to just enjoy the time with family away from home.

  • T-SQL Tuesday #174 – My Favorite Interview Question

    This month is a great topic to me. I think growing and improving your career is a skill that most of  us could improve, especially in our younger years. The invitation from Kevin Feasel is a good one from which you can learn a lot.

    I am looking forward to the responses from others.

    If you want to host an invite one month, ping me and request a date. Most of 2024 is full, but I have a few months, and I certainly am happy to schedule you into 2025. This is a great way to participate in the community, meet others, and challenge yourself. You just need a blog.

    In this post I’m going to give two questions, one as an interviewer and one as interviewee.

    My Favorite Interview Question for Candidates

    When I interview someone, I usually have a list of things to ask them to better help me compare candidates, but these are associated with digging into knowledge, however this question really helps me.

    What have you learned recently?

    I don’t expect candidates to know everything. I expect to have to teach them quite a bit about my environment. However, what I want from them is an effort to learn. My view is that some people are constantly learning things and others are content to rest on their previous knowledge/experience.

    If someone hasn’t learned anything recently, I don’t necessarily write them off, but I might probe about what they have been doing, as well as how they prepared for a new job or the interview. Perhaps they’ve been busy with something (crisis, illness, etc.) and haven’t been improving in the short term, but if someone hasn’t learned anything in the last year they’re proud of, or they can’t remember when they last invested in themselves, I have a hard time investing in them as an employee.

    Note, I will dig into ensure you learned something and aren’t just giving me an answer.

    My Favorite Question as an Interviewee

    In a lot of my jobs as a technologist, or a data professional, the job is the job. It’s very similar in many places. These days I do more architecture and advocacy, but if I were approaching a new job, I’d ask this:

    What are the expectations around working hours?

    I’d add context to this, but what I’m looking for are information for these items:

    • core working hours
    • on-call/non-core hours
    • punctuality

    I don’t mind working hard, but I don’t expect to work a lot of non-core hours every week, or even too regularly. I don’t mind 40 or even 50, but beyond that I’m not going to be happy.

    I’m also not someone that punches a clock. If you expect me to be online (or in an office) every day at 8am, you’re going to be disappointed. I might be there at 7:45 or 8:15. I don’t avoid work, and I do my best to be early for meetings, but if nothing is scheduled, I will vary my start time. I usually warn a potential boss about this.

    I used to ask about travel, but I’m over that. I don’t mind or worry about travel too much.

  • Reading JSON Data with Python

    Recently I’ve been looking at archiving some data at SQL Saturday. As a start, I needed to read some of the archive data I have in Python. This post looks at the basics of reading in JSON data in Python, one of the more versatile languages for working with data.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Reading JSON Files in Python

    I have some data in the SQL Saturday repo in JSON format. This is schedule information, which is exported from Sessionize. I also have XML data, but I decided not to mess with that for now.

    Getting this data into a dataset is actually easy in Python. Here are the basics. First, we need to import a few modules. In Python, lots of functionality is from various modules, which aren’t available until added to your workspace. However, they are easy to import.

    We need a few modules:

    • json – used to work with json data
    • os – used to work with files and call OS functions.
    • pandas – used for creating dataframes
    • chardet – functions to detect encoding

    I’ll import these, though from os I’ll only get a few things.

    # Basic import of a JSON file

    import json
    import chardet
    import pandas as pd
    import os

    Once I’ve done this, I can use these modules in my code.

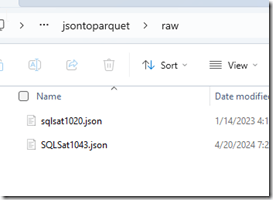
    Now for the code. The first thing is to find my files. I’ve stored json files in a “raw” folder, which I assume is below the place where I’m running the code. In this case, I have two files.
    2024-05-06 14_11_40

    Here’s a little setup code that sets the path (which could be an argument to the file), but creates a path to the files and starts a loop:

    mypath = '.\\raw'
    onlyfiles = [f for f in os.listdir(mypath) if os.path.isfile(os.path.join(mypath, f)) and f.endswith('.json') ]
    # loop through the files
    for f in onlyfiles:

    In Python, once I want to create a set of code in a loop, I need to indent it, so the next few lines are indented below the for statement above. I’ll repeat that for clarity.

    In the loop, I want to do a few things. First, I get a path to the file with the os.path.join  command, which builds me a path that works in various functions. Next, I want to use the chardet module to detect the encoding of the file. They should all be the same, but I had some issues when expecting the default encoding (this post helped). This ensures I get the correct encoding for the file.

    Lastly, I’ll open the file.

    # loop through the files
    for f in onlyfiles:
    
        currentfile = os.path.join(mypath,f)
    
        enc=chardet.detect(open(currentfile,'rb').read())['encoding']
    
    with open(currentfile,'r', encoding=enc) as json_data:

    Again, I have a with statement and want to run other code, so I’ll indent the next line. The next line reads in the file using the json module, which has a load() function. This function knows how to parse a json file so that we can work with it.

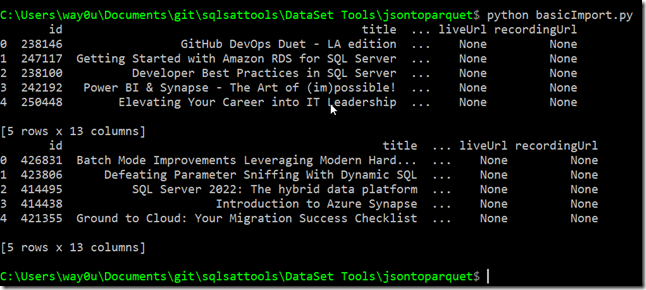
    Lastly, outside of the with command, I’ll return to the for loop be de-indenting one level and calling a pandas function to take a portion of the JSON file and load it into a dataframe. Think of a dataframe like a resultset in SQL or a datatable in C#. In this case, I’ll take the “sessions” structure. I print the first five rows with the head() function.

    The entire code structure looks like this:

    # Basic import of a JSON file
    import json
    import chardet
    import pandas as pd
    import os
    
    mypath = '.\\raw'
    onlyfiles = [f for f in os.listdir(mypath) if os.path.isfile(os.path.join(mypath, f)) and f.endswith('.json') ]
    
    # loop through the files
    for f in onlyfiles:
        currentfile = os.path.join(mypath,f)
        enc=chardet.detect(open(currentfile,'rb').read())['encoding']
        with open(currentfile,'r', encoding=enc) as json_data:
            data = json.load(json_data)
        # get session data from json
        df = pd.DataFrame(data['sessions'])
    
        # print the head
        print(df.head())
    

    The results look like the image below. I’m not covering how to run Python or anything else, but you can see the first five rows with the session title and a couple other elements.
    2024-05-06 14_20_09

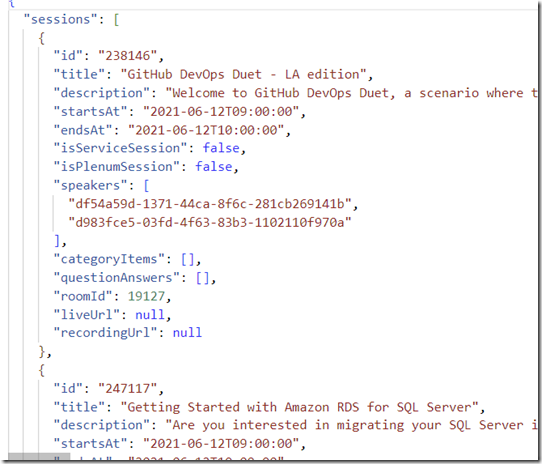
    The raw JSON looks like this for the first file with the sessions element.
    2024-05-06 14_21_21

    Now I can work with the data and query, transform, rewrite, store in a database, whatever. I’ll cover how to move this data in another post.

    SQL New Blogger

    This post took me about 15 minutes to write, mostly because of looking up some links. The code itself was for something I was already doing, so after getting the code working, I wrote this post using it.

    This is a good example of something you could write to show that you are building some data warehouse skills, which are valuable for many employers.