maugry – adj. afraid that you’ve been mentally deranged all your life and everybody around you knows, but none of them mention it to you directly because they feel it’s not their place.
I don’t know that I quite feel maugry, though I certainly sometimes wonder if I view the world much differently (and strangely) than others. I certainly think in polite society that others often won’t point out something that others do or say that is very strange.
I also like to think that often I have lots of empathy and understanding of how others view the world, though maybe that means I am actually deranged from others’ point of view and I should feel maugry.
A customer asked recently why Flyway doesn’t detect the filegroup for some changes. I showed them it does and decided to write a post on this.
I’ve been working with Flyway Desktop for work more and more as we transition from older SSMS plugins to the standalone tool. This series looks at some tips I’ve gotten along the way.
Setting Up Filegroups
I don’t see a lot of SQL Server databases using filegroups. They can be helpful, and they can create complexity, but they aren’t good or bad. Some people use them, and for various reasons. If you use them, you’ve probably run some code like this:
ALTER DATABASE [EngineRoomDemo_1_Dev] ADD FILEGROUP [indexes]
GO
ALTER DATABASE [EngineRoomDemo_1_Dev] ADD FILE ( NAME = N'index1', FILENAME = N'C:\Program Files\Microsoft SQL Server\MSSQL15.MSSQLSERVER\MSSQL\DATA\shadow_index1.ndf' , SIZE = 8192KB , FILEGROWTH = 65536KB ) TO FILEGROUP [indexes]
GO
Here I’ve added a new filegroup, called indexes, and a file in this group. This isn’t set as the default.
Since I’m working with Flyway Enterprise and generating scripts, I do need to also alter my shadow database, so that I can both detect changes and also verify my scripts. I’ll use this code:
ALTER DATABASE [EngineRoomDemo_1_Dev_Shadow] ADD FILEGROUP [indexes]
GO
ALTER DATABASE [EngineRoomDemo_1_Dev_Shadow] ADD FILE ( NAME = N'index1', FILENAME = N'C:\Program Files\Microsoft SQL Server\MSSQL15.MSSQLSERVER\MSSQL\DATA\shadow_index1.ndf' , SIZE = 8192KB , FILEGROWTH = 65536KB ) TO FILEGROUP [indexes]
GO
Now we can detect changes.
Detecting Table Changes
First, let’s actually create a new table on this filegroup. To do that, I create a table, but I add an ON clause, as shown here. After the table creation, I use ON with the name of the filegroup. This ensures this table exists on the file(s) for this filegroup.
CREATE TABLE [dbo].[newtable](
     [myid] [int] NULL,
     [mychar] [varchar](20) NULL
) ON [indexes]
GO
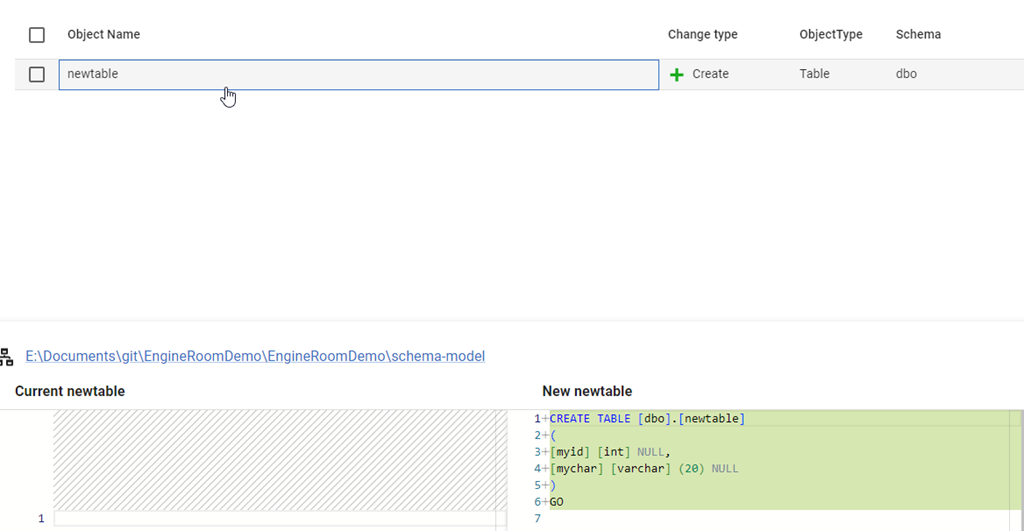
Once this is done, I can go to Flyway Desktop and detect the change. When my schema model refreshes, I see the change, but no filegroup.
Hmmm, what’s wrong?
By default SQL Compare ignores filegroup information. If I click the Comparison options button, I get a dialog.
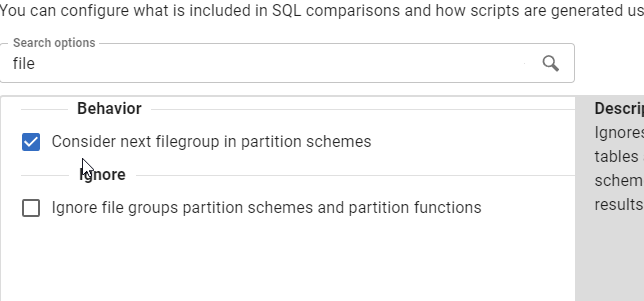
In here, go to the Comparison options dialog and type “file”. Hopefully the lower option below will be fixed to say “filegroups” and also add commas soon (sorry, I’m an editor).
We ignore these by default, so I’ll uncheck the lower box.
I’ll save this and refresh my schema model. Now I see the proper script with the ON clause.
Problem solved. If I care about where objects are created, I now have the filegroup location captured as part of my code.
Try Flyway Enterprise out today. If you haven’t worked with Flyway Desktop, download it today. There is a free version that organizes migrations and paid versions with many more features.
For years I’ve assumed I knew the string defaults, but I realized that’s not right. This post looks at what I learned.
Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.
Declaring VARCHAR variables
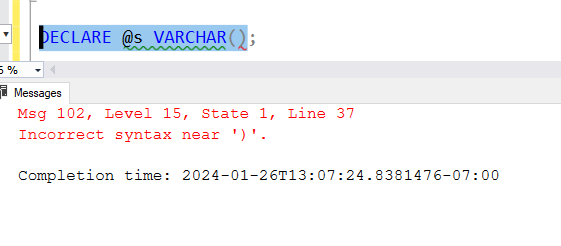
I learned a couple things. First, this is invalid code:
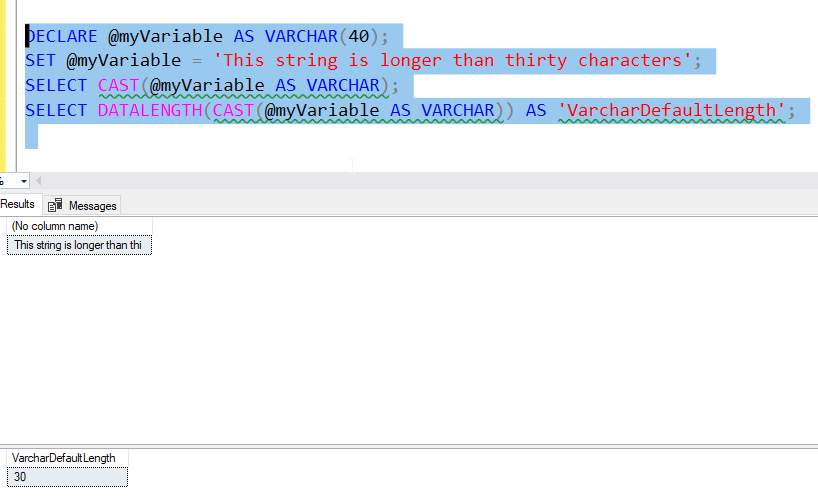
The parenthesis aren’t needed, and cause an error. But if I declare just the word, I can add a string. The string in this code is more than 30 characters, which I’ve always assumed is the default length.
DECLARE @s VARCHAR;

SELECT @s = 'this is a test of a fairly long string'

SELECT @s
When I run this, however, I only get one character back.
When is it 20? When we use CAST/CONVERT. In that case, it’s 30. Code from the docs shows this:
I’ve known this happens with CAST, but I didn’t realize the default length was 1. That’s interesting, and hopefully something no one lets slip into production when it would cause a problem.
A good lesson is to always declare your length, and don’t make that MAX if you don’t need it.
SQL New Blogger
This post took me about 10 minutes to write, once I realized the issue. I spent a few minutes grabbing links, as I’d had some of the code written once I was testing what I’d read.
You could do the same thing. Show some learning, show some code, show how you change things.
It’s that time of the month for a new blog party at T-SQL Tuesday. This month we have Brent Ozar hosing, and it’s a good topic. I wondered what he might ask when he agreed to host and he has surprised me.
If you haven’t participated in this, start a blog, start building your brand, and write a post that answers Brent’s invitation. If you enjoy this and want to host, ping me for a date.
Closing Tickets
I don’t get tickets per se. I get copied on a few of them from customers, but often the things that I fix are things I’ve broken at SQL Saturday or T-SQL Tuesday or one of the sites I run.
However, I do consult with customers and our Solutions Engineers at Redgate on architectures and challenges that customers are facing. Sometimes I even come up with a solution. This was the most recent one, which I found interesting.
I walked into a conversation at a Redgate office one day. A few engineers were talking about a requirement that a customer had to stop a deployment if a particular configuration file had changed. They allow changes, but by few people, however, the configuration file is in the repository with other code and controls some of the deployment parameters.
Our engineers were looking at git hooks or moving the file to another repo, or rearchitecting the pipeline to change the configuration. There were other solutions, but all of them were adding complexity to the situation.
Having grown up in the era of limited RAM and unreliable networks, I immediately thought about detecting changes with a file checksum. It’s a computer science technique used in lots of places, including many database drivers. I thought the simple thing is to store the checksum in a variable in the pipeline, and then add a step that runs something like Get-FileHash and compares that to the variable. Then fail the pipeline if it’s wrong.
If the file needs to change, the privileged users can change the file, run this, and update the variable with the results.
A simple way to detect changes and limit them inside the repo, from outside it.
I have to say I haven’t seen this particular issue before, but I have seen lots of people worry about how to ensure deployments don’t happen in prod if they haven’t happened in test. That’s another whole issue, and a complex solution that I saw a customer implement. It worked great, but that’s for another day.




 Voice of the DBA
