Category: Editorial

  • No R2

    No more R2 for SQL Server (hopefully)
    No more R2 for SQL Server (hopefully)

    At least not for SQL Server. There was an announcement last week at TechEd that the next version of SQL Server will be coming in the next year and will be named SQL Server 2014. No SQL Server 2012 R2, which I think is a good decision. As much as I don’t think naming much matters for many things, releasing a second product with it’s own set of patches, under the moniker of a previous product, makes for confusion. No shortage of people have tried to restore databases from SQL Server 2008 R2 to SQL Server 2008, or apply patches built for one, on the other.

    Three main products were announced: Windows Server 2012 R2, System Center 2012 R2, and SQL Server 2014. I still don’t understand why the branding for the other products hasn’t changed, but as long as SQL Server is moving forward, I’m happy. All three products have lots of changes, but some of the biggest ones are in linking more features from the cloud platform, specifically Azure, to those products. I’m not sure what it means for the other products, but for SQL Server, I was surprised, and a little scared, by this quote:

    “there is no such thing as a SQL Server team anymore. There is, in fact, no code base called SQL Server. There’s only one code base, which is the Azure database code base.”

    It’s been printed a few times that Microsoft is focused on Azure first, and their development will occur there first and slowly make its into the boxed product. I can understand that, even if I don’t like it. I still think Azure needs competition outside of Microsoft, but we’ll see what happens as development moves forward.

    In terms of SQL Server 2014, there are lots of new items to be excited about. The in-memory “Hekaton” structures, updateable columnstore indexes, AlwaysOn expanded to 8 secondaries with online indexing and more. I am anxious to see how the sub-roles work for security, and if we can allow more administration without access to data, I’m very interested. The Resource Governor that handles IO is another one I’ve wanted for quite a few versions.

    I don’t know when we’ll be able to test things, and I don’t know when we’ll get the RTM bits, but if you have instances you’ve been thinking about moving to SQL Server 2012, I might hold off and see how the first CTP shakes out.

    Steve Jones


    The Voice of the DBA Podcast

    We publish three versions of our podcast daily. We do not have any podcasts today due to technical issues. The podcast will return tomorrow.
  • The Decision to Fail

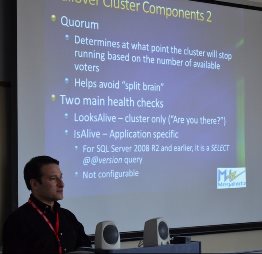
    failoverWe have a number of automated technologies that we can us to seamlessly move from primary to secondary systems without human intervention. SQL Server incorporates a number of these, and many companies use them to ensure their applications are highly available. However things don’t always go as planned in a disaster and sometimes humans get involved.

    Unless you are one of the companies with a very large budget and high risk of business issues when systems failover, you probably have some sort of high availability (HA) or disaster recovery (DR) process that requires human intervention. Log shipping, for example, usually requires that some human reconfigure the application to use secondary servers. Even with Availability Groups, clustering, or database mirroring, you may need to manually fail back to primary systems.

    In those cases, it’s not always a clear decision to do so. Many of the switches are disruptive, or have the potential to be disruptive. Cluster fail-overs should not impact the application, but there is a brief period where clients may not connect. Outside of disasters, Management, and often technical people, usually want to schedule any failovers after they have prepared the end user for potential issues, however brief.

    In disaster situations, when there hasn’t been a complete failure of a system, you may not want to have unscheduled failovers right away. This week I want to know:

    How do you make the decision to fail over from one system to another?

    I’m speaking to you, the data professional or the administrator. I would guess that most of you are not the one that ultimately makes the decision to leave your primary systems. Often I’ve found that someone in management has to make the decision, but with input from the technical people. In that case, think about how you present the situation and pros and cons of the failover. Do you give hard numbers, like latency and relative CPU power in failover machines or do you attempt to quantify the effects on the business when secondary systems are in use.

    I’ve rarely had a large budget for secondary systems. Network bandwidth, CPU and memory, and more are sometimes sacrificed in secondary systems in order to align the cost of these systems with the risk of needing them. In many cases, we didn’t have automatic failover for many systems because we had to know our primary systems would be down for more than 5 or 6 hours before we would switch to the backup environment.

    If you have similar guidelines or processes in place, let us know.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.

  • Quickly Copy Data

    How quickly can you copy data from one place to another?
    How quickly can you copy data from one place to another?

    There’s no magic solution for many of the problems we face in SQL Server. Whether we are trying to maintain concurrency under high write loads, restore databases quicker, or ensure extremely high availability we need to make trade-offs. Sometimes those tradeoffs are frustrating, and people look to other solutions like NoSQL, not realizing that they are just making different trade-offs.

    I see the frustrations and comments constantly on the SQLServerCentral forums, and one recent discussion was no exception. In this particular debate, a user was frustrated by the requirement to copy backup files across the Internet to another location. The transfers were taking too long and the poster were trying to find some magic way of decreasing the transfer time. Increasing the bandwidth, the simplest solution, wasn’t an option, and that usually isn’t easy to do in a corporate environment. The poster seemed to think there had to be some magic way of reducing the time it takes to copy large backup files, and there isn’t any magic solution. The things that help reduce transfer time are often the common things we think of.

    Compression is an obvious solution. There are numerous free programs to compress files and even software that will compress the backups as they occur. There are techniques in Windows for speeding up copies, though many are Windows version dependent. Beware, however, since copies from your server might cause you memory issues. However there might be other, more creative solutions that people come up with.

    Imagine that you track the transfers, keeping meta data about the process. Perhaps you can find a way to send less data overall the next time. In some sense, this is the idea behind log shipping. If you only send the changes (the transaction log backup), you might save a tremendous amount of time and resources. That assumes, of course, that the changes in a period of time contain less data than the overall database. That might not be the case in some  workloads.

    There are other services that might help. Imagine that you back up to the cloud, either because you use a tool, feature, or service if your application exists in the cloud. Spinning up a new instance with a copy of that data in the cloud might eliminate the need for transfers completely if the other location can just access the data in the cloud.

    I’m sure some of you have other ideas, and I’m sure many of us would like to hear what creative ways you might have for moving data between locations.

    Steve Jones


    The Voice of the DBA Podcast

    No podcasts today due to some personal issues. The podcasts should return tomorrow.

  • Fear Fear

    Are you too fearful or just paranoid enough?
    Are you too fearful or just paranoid enough?

    I’m a conservative DBA. I get nervous when backups aren’t running, code isn’t in source control, and developers have access to production systems. I’ve had too many late night pages and weekend phone calls, not to mention many extra hours spent in the office from changes to systems that didn’t go well. That latter item leads me to limit the number of changes I make to systems whenever I can, including avoiding applying Cumulative Updates to SQL Server.

    When I read an editorial from Glenn Berry, I had to stop and think of whether or not I had a healthy respect for the problems that can occur from change, or if I was being overly conservative (or fearful). Glenn makes a good point that so many people do not upgrade or change their drivers, firmware, or other software. People don’t patch their SQL Servers, even with Service Packs. I’m sure some of that is fear, but some of it is neglect as well.

    For me the decision usually comes down to examining the reward/risk ratio, trying to understand if improvements are balanced by the risk of downtime. I do value stability above new features, mostly because if problems do occur, I will be the person fixing them. That doesn’t mean I avoid all changes. I think Service Packs need to be installed, though not necessarily the first month. I’ve also come to embrace some of the continuous integration (CI) and continuous deployment (CD) ideas as ways to both reduce a software inventory as well as hold developers to a higher quality standard. However if you want to deploy (and perhaps patch) in a continuous deployment environment, then you should ensure that your CI process performs strong checks and make sure your developers are holding themselves to a high level of quality.

    We change the way we work, and the tools we use in technology often. Change is a concept we embrace, and we should since the ways in which our systems work are regularly changing. Bugs are patched, new techniques and tools are developed that should make us more efficient and productive. Those don’t always work, and we should be wary, but we should also not fear change. We should evaluate each new possibility with the attitude that our decision to move forward “depends.” It depends on the ease with which we can integrate something or apply a change, and the ease with which we can roll back our changes if they do not perform as expected. It also takes practice to ensure that all those things are easy.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.