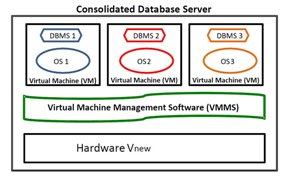
I noticed this week that the Transaction Processing Council (TPC) is working on a new benchmark designed to measure workloads across virtual machines: TPC-VMS. This benchmark builds on the existing benchmarks out there (TPC-C, TPC-E, TPC-H and TPC-DS) with the idea that companies want some idea of how various hardware and software might compare in virtual environments. In this benchmark, there are three systems consolidated onto one host running some type of hypervisor. If you are interested, you can read about the current benchmark, v1.1 (1.9MB PDF).
Companies choose virtualization for efficiency reasons, sacrificing some stable, known level of performance from their systems. In many cases that trade-off isn’t a problem as we have many, many systems that are using only a fraction of their power. However as data professionals, we are often very concerned about the possible complications from virtualization. It’s our phones that ring and each of us that gets the blame when systems are not as responsive as users would like.
This seems to be an ambitious undertaking from the TPC, and I suspect that more than a few hardware and software vendors will be nervous about submitting their wares for evaluation. The very nature of virtualization would seem to imply that as the load increases, the performance from any particular VM might vary from test to test. I will be curious to see how they present these results and how we can interpret them.
I don’t know if the benchmarks will have any relation to the real world. As it stands today, the TPC results don’t seem to relate to actual systems in the real world, though they do confer some bragging rights for platforms. I’ve enjoyed seeing SQL Server in the various rankings, if for no other reason than to show it can perform at the same level as other RDBMS’s.
Shipping is good, but your deployment process needs to be solid.
Years ago the company I worked for would patch the majority of our servers one Friday night each month. The Microsoft patches for the month, and other software patches, would be bundled up into SMS (Systems Management Server) packages and deployed to thousands of servers. We had an amazing administrator who built these packages, and it was quite an experience to walk into the data center and hear thousands of servers shut down and fans spin down for a moment before rebooting.
That was the smoothest deployment system for vendor patches, but I worked in another place that deployed changes to a web application (the system that generated all our revenue and paid our salaries) every Wednesday night. We did this for over 18 months, over 70 deployments, pushing out changes on a consistent basis. We only rolled back three times, but we did roll back three times.
Other jobs have had various levels of success at deploying changes. Many of the companies worked with the ad hoc, patch one machine at a time manually, process. Not very efficient, and probably not even possible at the numbers of systems many companies have today. I wanted to ask you this week how successful your company is.
How often do you have problems during the deployment of some software change?
Do you think that you have issues more often than not? Do you roll back when you have issues? I doubt that. In my experience, even broken deployments are often pushed forward, with the expectation that developers, vendors, or admins will fix things over the next few days. I’ve never thought that was a good plan, since we often fine broken features limping along for months or years, but organizational momentum can be hard to slow down.
Let us know if you think you work inside of a smooth, strong deployment process, or one that’s more fragile and brittle.
Steve Jones
The Voice of the DBA Podcasts
We publish three versions of the podcast each day for you to enjoy.
The biggest concern with cloud computing isn’t security.
When I get feedback about cloud computing from DBAs, the main concern seems to be data security, or the perception of problems with security from a cloud provider. That’s natural as sending your data to the cloud doesn’t necessarily remove the responsibility for security from the purview of the DBA, yet you don’t have complete control over the way the data is managed. Various providers are working on their security and passing certifications, though this doesn’t necessarily make many DBAs feel comfortable with databases in the cloud.
However security may not be your number one concern. Outages and business continuity should be your primary concern. As noted in this article, cloud service outages have been more common than lost data. It’s much more likely that the service will go down, and if it does, what do you do? Contacting a cloud services company, and receiving fast answers aren’t likely when a cloud outage usually affects a large number of customers.
However business continuity is important. If your database, or application server goes down, what would you do? In most cases you would sit in your office waiting for the cloud provider to come back online. That’s not much different from in-house failures where you may wait on the network or OS administrators to recover a host server. In a few of the disasters I’ve experienced, I only had slightly more control than I’d guess a cloud provider gives me.
In either case, having good backups and a strategy to bring your system online in the event of an extended outage is important. I suspect that will mean hybrid public/private cloud applications that can function from an alternative location will need to be an architectural requirement for many businesses.
Steve Jones
The Voice of the DBA Podcasts
We publish three versions of the podcast each day for you to enjoy.
Running out of diesel in a disaster is not something you want to happen.
There was a large hurricane in the US a short while back. It was a devastating storm for many people, and my heart goes out to those that suffered or are still suffering. There are lots of lessons to be learned in many areas, but a few surprising ones for those people that run technology infrastructures. A number of data centers were shut down because of physical flooding, but others were shut down after electrical substations failed and they were unable to run their generators.
When I evaluated data centers a decade ago, I was always shown the number of UPSes on site, and the high capacity diesel generators with large fuel tanks that were available just in case of extended outages. Salespeople would bring out their contracts that showed suppliers would commit to refilling their fuel tanks, providing for every contingency.
Except a lack of diesel. In Denver we wouldn’t have the need for a staircase bucket brigade, but we might have the need for a roadside chain gang carrying containers in a blizzard. You cannot plan for every contingency because there are many factors out of your control. When a disaster gets large enough, it doesn’t matter what you have contracted for. There will be outside influences, like the lack of elevators or the inability of trucks to physically reach your location.
One of the Red Gate customers was in New York and almost lost their data center after the storm. They asked our technical team to help them prepare scripts to restore data backups for their clients in the event they had to send the full, diff, and log backups (along with application code) to the customers. It was an last-ditch effort to allow their customers to continue to run their service. Fortunately they never had to use any of the scripts, but it did help the company realize they need to build more options for business continuity in the event of future disasters.
I hope none of you ever experiences anything like Hurricane Sandy. You can’t completely prepare, but you can practice your recovery skills on a regular basis and be prepared to respond when disaster strikes.
Steve Jones
The Voice of the DBA Podcasts
We publish three versions of the podcast each day for you to enjoy.