Category: Editorial

  • Dress Like Steve

    I hate wearing suits and ties. One of my early jobs in technology required them, and my least favorite part of that job was the dress code. Almost as bad was a company that required a uniform: same pants and shirt every day. I didn’t mind a few jobs that required khaki pants and a collared shirt since I could have a little variety, but my ideal job, which I have now, lets me wear what I want. T-shirts, shorts, sandals, jeans, and more are acceptable in my office.

    These days when I put on a collared shirt, it’s usually one with with design of some sort on it. I have a nice collection of colorful shirts, and I often wear them to events. Can you find me in the picture below?
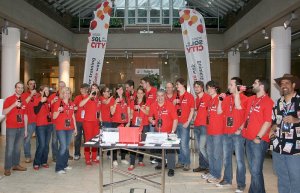
    SQL in the City Staff
    One of these things doesn’t look like the other…

    As we were planning the US tour of SQL in the City and talking about things we might giveaway, someone suggested adding a few shirts to the list of books, pens, balls, etc. I thought that if I were to give away some cool SQLServerCentral shirts to attendees, I ought to make sure that I was modeling one of the prizes all day. My boss agreed, and I got permission to go shopping.

    At each of the US SQL in the City tour stops, I’ll be wearing a new Hawaiian shirt. At the end of the day at each event, I’ll also be giving away 3 of the same shirt to three lucky attendees. You can’t win one if you don’t come, so if you are in any of the cities we are visiting, be sure to register and come get a free day of presentations from Grant, me, and a number of other speakers. I’ve got a series of blog posts on the events, and if you want to run with me in the mornings before an event, drop me a note on Twitter.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.

  • Compress Everything

    zettabyte
    Suddenly a TB doesn’t look so large.

    We are gathering more and more data all the time. There’s no end in sight, and even as storage becomes more dense and cheaper per GB, we are needing more and more of it all the time. I saw a note recently that estimated in 2011 we gathered 1.8ZB worldwide. Not TB, not PB, but ZB. That is crazy. There are estimates that say some industries have more data per company than the US Library of Congress.

    Our own databases are constantly growing, and even though many of them are relatively small, we keep multiple copies of the data. We have production, we have test, we have multiple development copies. Some companies have UAT, some have customer service environments. Overall, we may have a lot of data in our companies that’s redundant, but necessary.

    Managing all this storage can be a hassle for DBAs. It can be a pain for developers that need more drives for their environments. It can lead to arguments with SAN adminstrators for those servers that need additional storage to match production. Time becomes a factor as well when looking to restore, copy, move, or just query the systems.

    An obvious solution is compression. There is data compression built into SQL Server, which works well in some data distributions. Third party products exist to compress backups, or even whole databases. Virtual restores can eliminate the need to have enough space for a backup and the data expanded in an MDF. There are solutions out there, and often they can return a very strong ROI against their costs.

    If you have a storage crunch, take a look at the various third party products out there. You might something that makes your job easier, and perhaps even gets the SAN administrator to smile.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.

  • Three Rules for Database Development

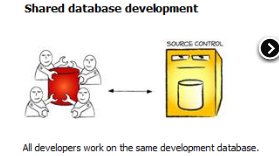
    shared database development
    Do you have rules for database development?

    I’ve always followed a few maxims over the years that have guided me well. One of those is that we must all agree on how we are going to perform any process and then all work that way. We can define whatever standards, rules, frameworks, processes, etc. that the group wants, but once we decide, we all need to work along in the manner we’ve prescribed. That’s worked well for me, and when everyone follow the rules we’ve agreed on, things run smoother.

    I ran across this post on three rules for database work from Scott Allen, a developer that has a lot of experience writing software. The three rules are never use a shared database server for development, always have an authoritative source for your schema, and always version your database. The last two rules are things I’ve always followed in the past since I think these are extremely important for maintaining control over the environment. Not control as a way to ensure developers are hamstrung, but control in that at any point in time you are aware of the state of the database.

    The first rule, never using a shared database, isn’t something I’ve usually done. Most of the time I’ve worked with small enough teams that people are working on separate sections of the database, and they almost never run into any conflicts with each other. A shared database server means changes from one person appear almost immediately to others is valuable. It allows development that is dependent on other changes to take place right away. That was in the past. These days with a tool like SQL Source Control (or custom scripting), you could simulate this on separate databases for separate developers.

    As with most rules in the database world, I think the answer to whether you follow these particular rules in your environment depends. It depends on what your resources are, your needs, your team structure and more. You can choose the framework that works best, whatever it is. You just need to make sure that everyone works within whatever you decide.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.

  • More CPU Means More Data


    sailors
    Better modeling requires more CPU and a lot more data.

    Moore’s law has held true for computer resources for a long time. I don’t know how long it will continue to work in the future, but I am interested to see if it can continue to work for the rest of my career. I don’t know that it will, with our newer CPU designs approaching the limits of physics, but I’m sure that research is under way to find ways to vastly improve our processing capabilities. Look how far we’ve come from the Apollo guidance computer, which landed 3 men on the moon, and had a fraction of the power of almost all of today’s cell phones.

    I ran across an article that talked about modeling sailing conditions to help sailors design faster and more stable boats. Just like many other types of modeling, this is a way to use computer simulations of various real world events to test designs of new products. This can save lots of time and money as fewer prototypes can be built and many more design ideas can be tested before a final design is chosen. More intensive modeling means more processing power is needed, but it also means more data is needed.

    We see this more and more in business. We want to get answers faster, often by running more complex business simulations. To get our answers faster we need more processing power. However as we upgrade our machines and enhance our CPUs, we also add more and more data to our databases. The additional data, while beneficial to making better decisions, also slows down our queries. The additional data is also a challenge to load, manage, and store, which is something we need to ensure we are learning to do better.

    Processing costs are going lower and lower. These days with the large clusters in the cloud that anyone can rent for a few thousand dollars, extremely complex simulations can be run. The code to run them, however, is still something that we need to produce. Just as the scientists  have developed complex models that accurately test new designs, each of us must learn how we can write more efficient queries that analyze our business data and take advantage of the constant improvement we see in processing capabilities. Otherwise the advances in CPU power might be negated by rapid data growth.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.