Tag: AI

  • RANK() vs DENSE_RANK(): #SQLNewBlogger

    I haven’t done one of these in awhile, but I saw an article recently about this and decided to explain it to myself, but in a slightly different way. You’ll see how I checked on RANK() vs DENSE_RANK() below.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Getting Started

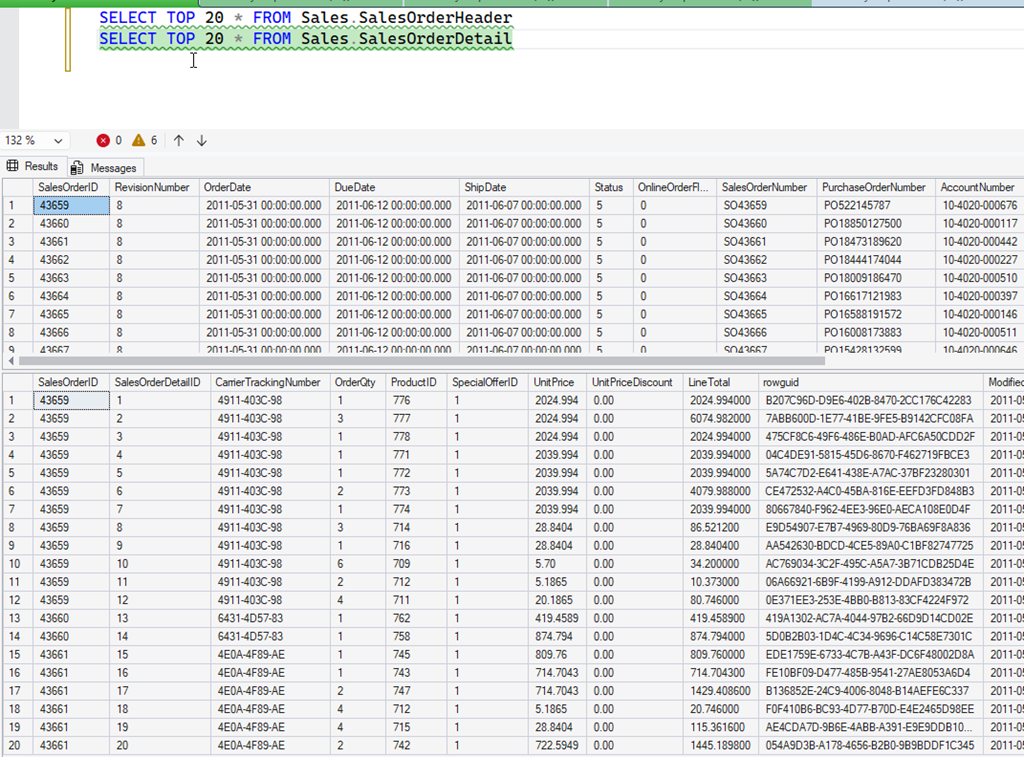
    Imagine you’ve never used these functions, but you need to rank some data. Let’s say that you have a series of things that measure sale and you want to know who has done the best job this week. I’ll start with AdventureWorks, and we’ll assume it’s June 2011. If I look at some data from that database, I see this. Order Headers and Order Details from that range.
    2026-02_0125

    Who are the top 5 salespeople?

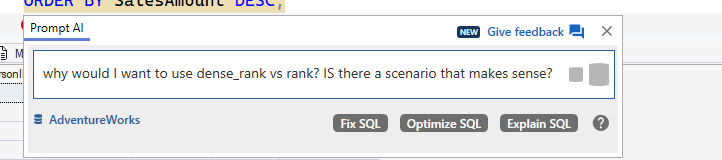
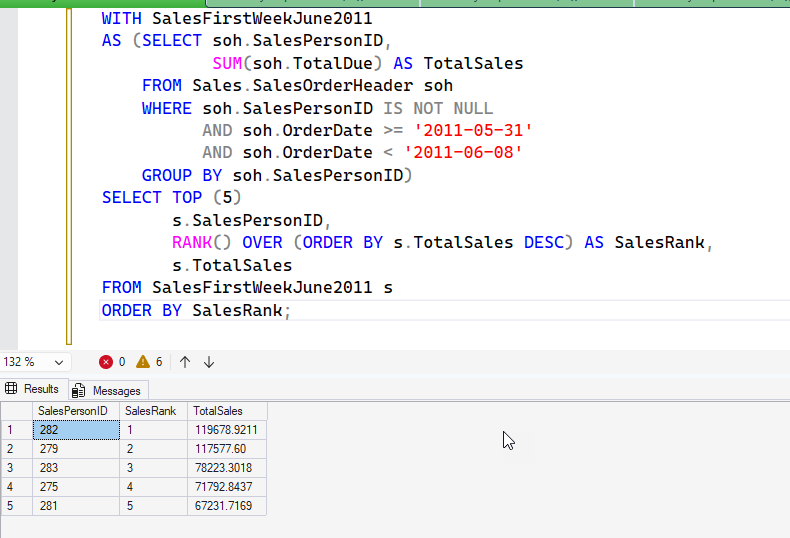
    I put this into SQL Prompt AI: who are the top 5 salespeople with ranking for the first week of june 2011. Give me the salespersonid, the rank and sales total

    I got this code, though with 2011-06-01 as the first date, which didn’t work as there were no orders that week. I adjusted this back to May 31. You can see this uses RANK() as the aggregate.
    2026-02_0126

    I then asked about DENSE_RANK, because I heard about it and might want to use it.
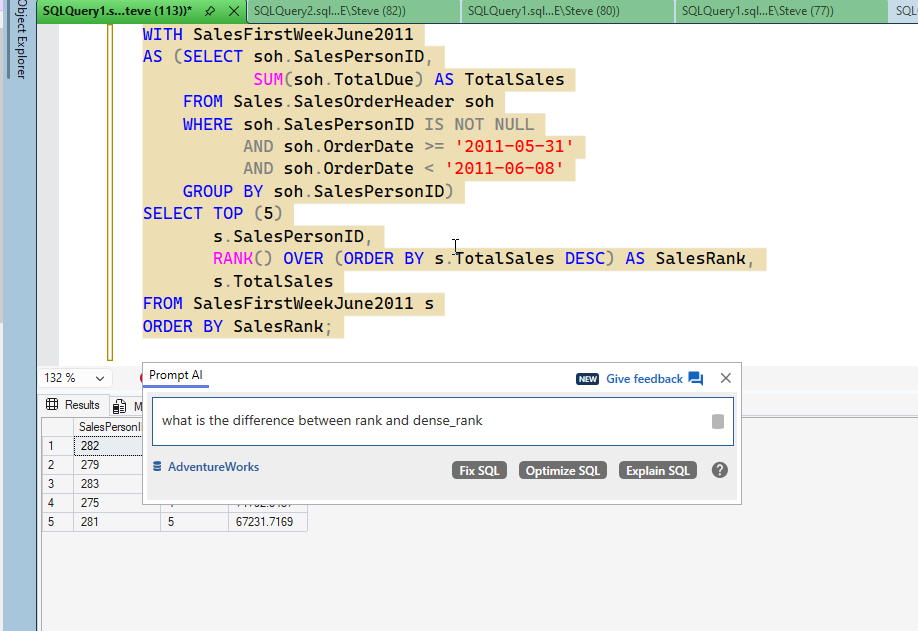
    2026-02_0127

    Prompt adjusted the query to add DENSE_RANK, but I then clicked the “add explanation” next prompt prompt (is that a thing now?)
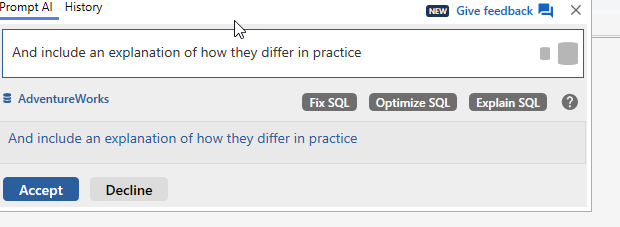
    2026-02_0128

    I now see an explanation, though in this example, this doesn’t help.
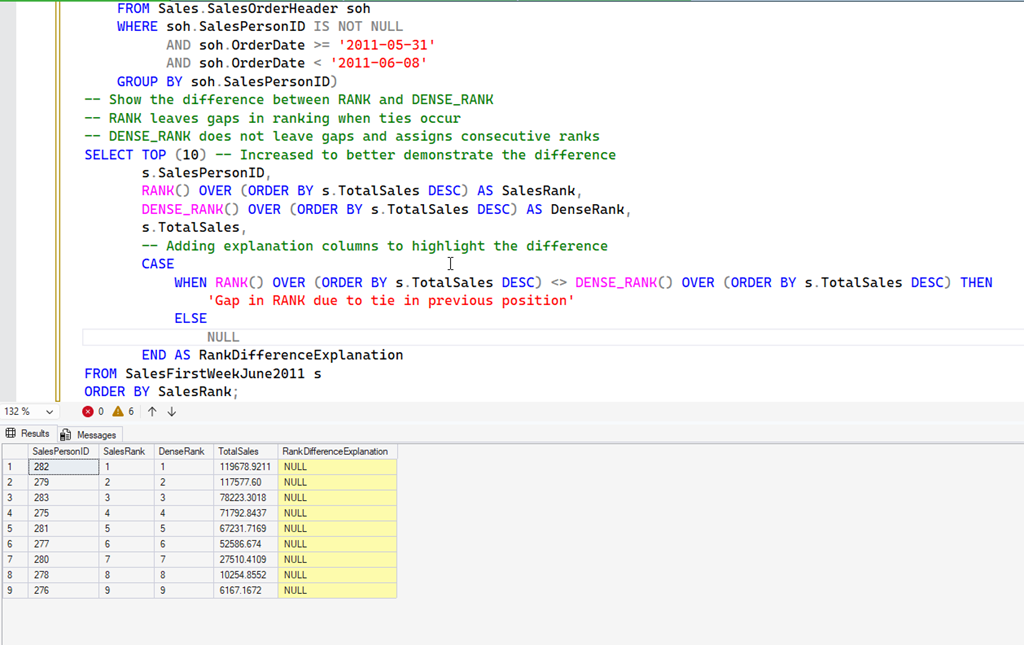
    2026-02_0129

    I then asked Prompt to help me understand.
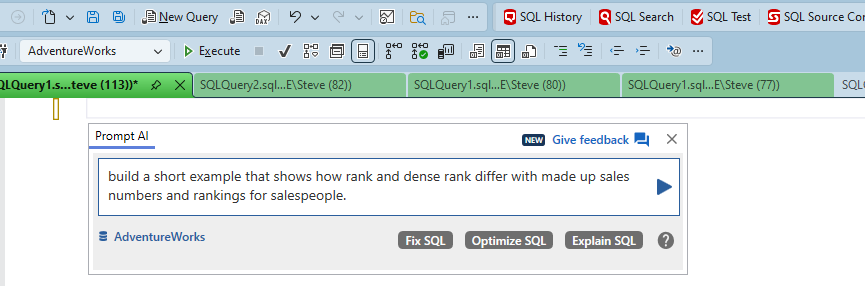
    2026-02_0130

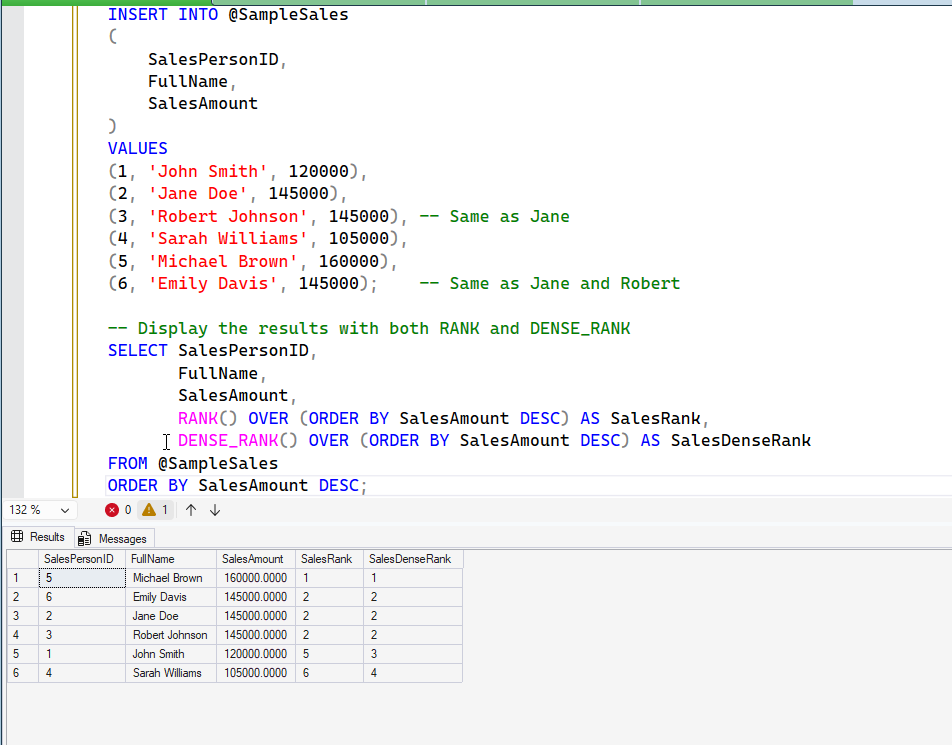
    I got back this code. You can see in the results, that both show me the ties for 2nd with people that have the same sales totals. However, with RANK, we jump to 5, since there are 3 people tied at 2 (presumbly taking 2,3,4th place). The dense ranking goes from the ties at 2 to 3.
    2026-02_0131

    I asked for an explanation:

    2026-02_0132

    I got this. This is the text from SQL Prompt AI (in italics):

    # RANK vs DENSE_RANK: When to Use Each


    The key difference between RANK and DENSE_RANK is how they handle ties:


    ## RANK
    – Assigns the same rank to ties
    – Skips the next rank(s) after ties
    – Creates “gaps” in the ranking sequence
    – Example: 1, 2, 2, 4, 5 (note the missing 3)


    ## DENSE_RANK
    – Also assigns the same rank to ties
    – Does NOT skip ranks after ties
    – Creates a “dense” or consecutive ranking without gaps
    – Example: 1, 2, 2, 3, 4 (no gaps)


    ## When to use DENSE_RANK:
    1. **Consecutive Ranking Systems**: When you need a continuous sequence without gaps, such as in competitions where tied participants should receive the same position, but the next participant should be ranked immediately after.


    2. **Top N Analysis**: When identifying items in the “top 10” or similar groups, DENSE_RANK ensures you get exactly 10 distinct ranks regardless of ties.


    3. **Percentile Calculations**: When calculating percentiles or quartiles where a continuous ranking is needed.


    4. **Educational Grading**: When multiple students with the same score should receive the same rank, but the next student should be ranked immediately after.


    ## When to use RANK:
    1. **Traditional Competition Standings**: Olympic medals and many sports competitions use this approach – if two athletes tie for first place, the next finisher gets bronze (3rd place, not 2nd).


    2. **Statistical Analysis**: When you need to preserve the mathematical properties of ranks where the sum of all ranks should equal the sum of consecutive integers.


    3. **Scenario Where “Skipped” Positions Matter**: When it’s important to account for how many entities are ahead of each entity.


    Your example query perfectly demonstrates this difference:
    – Employees with $145,000 all get rank 2 with DENSE_RANK
    – With RANK, they get position 2, but the next rank is 5 (skipping 3 and 4) because there are three employees sharing rank 2


    Each function has its appropriate use cases depending on whether you want a continuous ranking sequence or one that accounts for the number of entities at each rank level.

    What I Learned Here

    I knew most of this, but in terms of trying to understand better where/why to use each, the explanation made sense. I hadn’t thought about the Educational Grading for DENSE_RANK, but that makes sense. I knew the others, and often that the TOP N needs the correct number of rankings.

    For RANK, we use the competition ranking with volleyball, so I see that all the time, but I don’t do a lot of statistical analysis where this has come up, but it’s good to keep it in mind.

    To me, I often go back to the client, or think about both of these when I rank things. I will do what Prompt AI did and put both in a query, see the differences and then decide (or let someone else decide) how to present the ranking data.

    SQL New Blogger

    When I started to explain this, I first opened the DOC pages and was going to use those to write this and thought, this is a good place to test AI models and see. I took a different tact and incorporated some AI into my work, because that’s where the world is going. Like it or not.

    This went faster with AI, and less cognitive load from me. I wrote this post, but I used AI to help set things up, generate code, and get me there quicker. You could do the same thing and use a blog to showcase that you’re learning how AI is a tool you can use.

    SQL Prompt can help you learn more about your code, in addition to all the cool time saving features. Give it a try today.

    FWIW, I asked CoPilot the same query and got an answer (0 people), without code. When I asked for code, I did get it, but not quite what I wanted.
  • Claude AI Convinced Me Not to Build an iPad App

    I coach volleyball and I do a lot of stat stuff on paper. I decided recently to see if I could find a way to more easily automate things. I’ve tried a few apps on the iPad, but they all have too many restrictions and they are hard to use in the heat of the moment. Paper and pencil have been simple, reliable, and they let me fix something easily.

    However.

    Paper takes some focus, and it’s hard to quickly summarize things. I wanted to make my own app, and Claude convinced me not to do this.

    Read on.

    This is part of a series of experiments with AI systems.

    A Simple Prompt

    I’ve been kicking this around, but I never seem to have time. Listening to podcasts, reading articles, and seeing other experiments is slowly getting me to just try things. I started with this prompt, intending to give this 10 minutes out of my day.

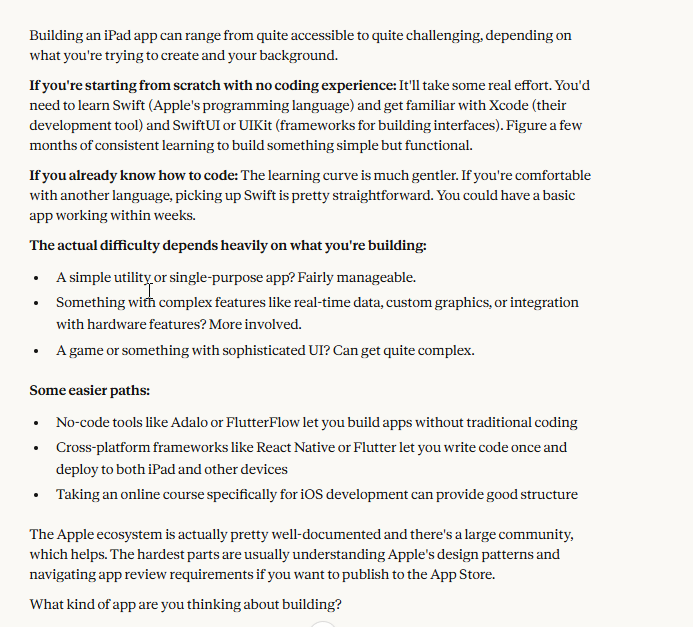
    how hard is it to build an app for an ipad

    I know some of the answers, but you can look at the image below for what Claude gave me.

    2026-01_0335

    I like the conversational nature of this, so I answered with this:

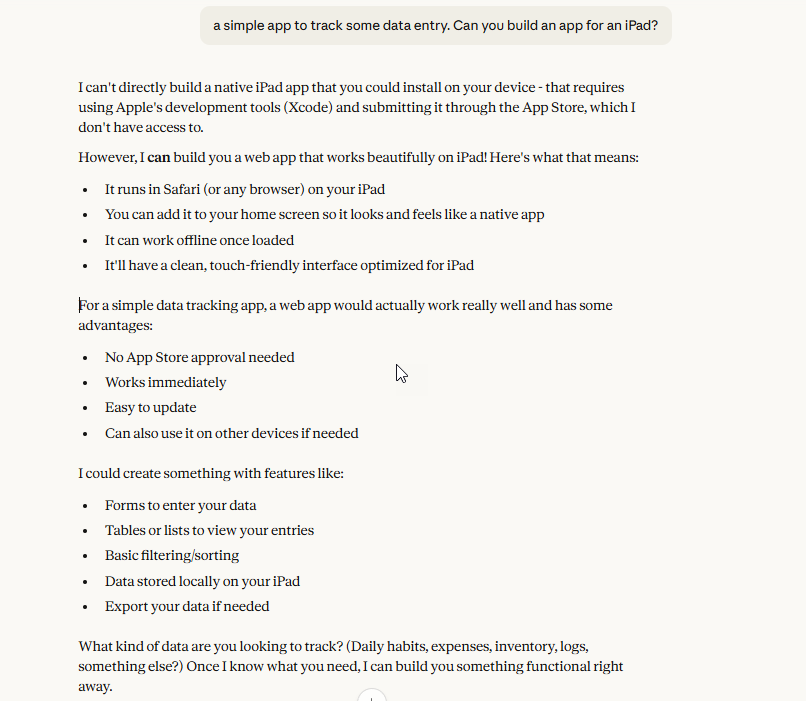
    a simple app to track some data entry. Can you build an app for an iPad?

    I was just looking for help in my thought process here and trying to scope the work. I’m sure Claude Code could knock this out, but I’m experimenting. This was Claude’s response.

    2026-01_0337

    That’s great news. I don’t need a native app, and in fact, that’s likely a lot of overhead registering on a store or playing the sideload game, sending updates slowly, etc. With cloud file sync, I could easily have this data available elsewhere anyway.

    This is the type of advice I’d get from some friends. Others would relish the chance to build an app and make this more complex. I’ve certainly seen some other Vb coaches on FB create complex systems.

    My answer:

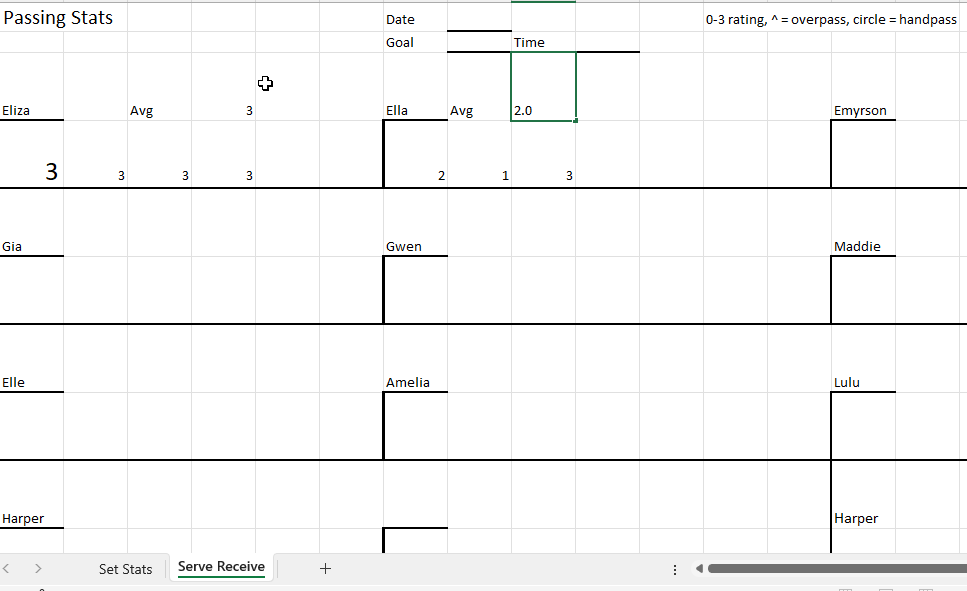
    volleyball stats. Display a list of players in a 4×3 grid, like the image. Each player’s name is customizable. A date, goal, and time can be entered. For each player, display 4 buttons: 0,1,2,3 which are used to rate a pass. There should be a real time calculation of the average pass score for a player (sum of items/ attempts). Save this to a text file with the datetime data entry was completed.

    I meant to upload the image below, but forgot. For context, I print this out and then as kids pass balls, I write 0, 1, 2, 3 for each pass. After we’re done (usually xx passes or time), I quickly compute an average. You can see below, Eliza gets a 3 and Ella gets a 2.

    2026-01_0334

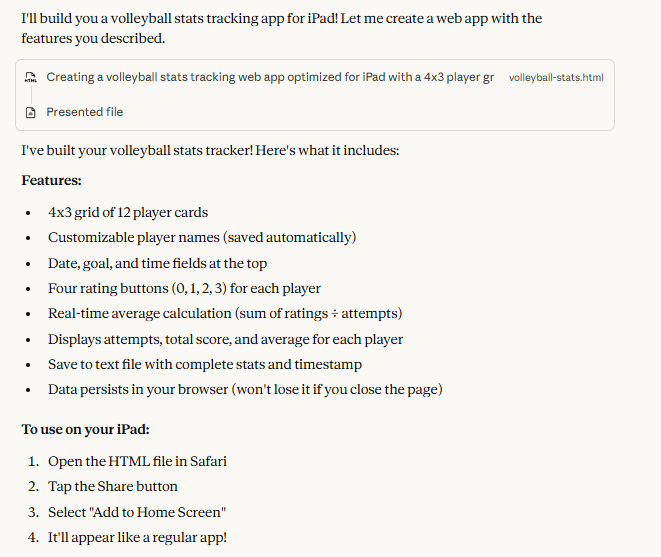
    That takes time, so I wondered what Claude would say. This is the response, which took about 5 minutes.

    2026-01_0338

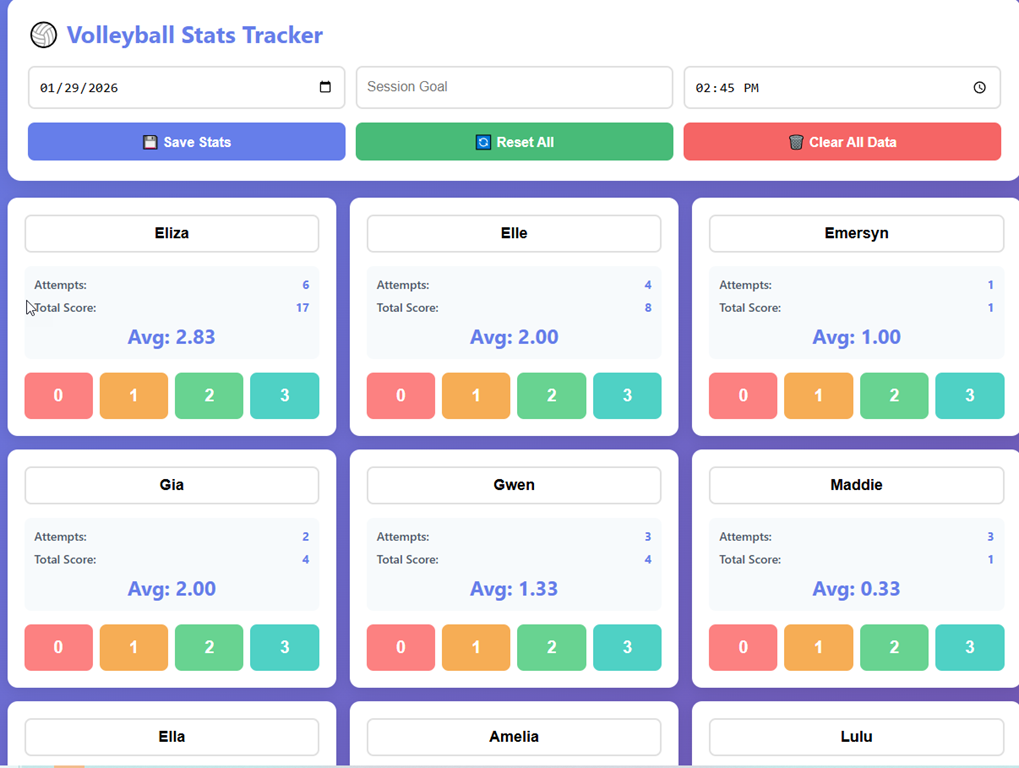
    I downloaded the file and opened it and saw this, or most of this. I updated the player names and they’re saved in the HTML.

    2026-01_0339

    I can click around and it logs attempts and calculates an average in real time. If I download the data, I get a text report of what happened.

    If you want to try it yourself, look in my repo: https://github.com/way0utwest/AIExperiments/tree/main/VolleyballPassingStats

    I asked for a few changes, and then I asked for a log of the session. That’s the readme in the repo.

    To me, this was something I’ve put off for a few years, not wanting to get caught up in a project like this when I could easily just use paper.

    Now I have a new toy that I’ll use at the next practice. Plus, I’ve amazed myself at how  easy this was.

    Be curious, try things, ask for help on a task or project you’ve put off. GenAI is amazing.

    Other AIs

    I tried this on a local Gemma3 model and it was very slow and produced a single entry box. to me, this wasn’t worth the time or effort.

    I tried this in Copilot (in VS Code) with the Sonnet model, and it wanted to make me an xCode app right away with a SwiftUI. I could get it to produce something like what I got below, but it wasn’t as helpful as Claude.

    Video Walkthrough

    You can see some of this live in this video.

  • Expensive CPUs

    There have been a lot of features added to the SQL Server platform over the years. Several of these features let us perform functions that are beyond what a database has traditionally been designed to handle. SQL Server has had the ability to send emails,  execute Python/R/etc. code, and in SQL Server 2025, we can call REST endpoints.

    Quite a few of these features (arguably) are more application-oriented than database-oriented. There’s nothing inherently wrong with having a server perform some of these functions, and there have been some very creative implementations using these features. I recently ran into one of these examples from Amy Abel, where she shows how to use the new REST endpoint feature to call an AI LLM to generate and send emails from your database server. That’s creative, and it’s reminiscent of the numerous examples from various experts over the years who demonstrate how these features can be used to accomplish a task.

    However, these are examples. They work amazingly well with one user running a limited workload. This reminds me of many of the examples I’ve seen using the AI vector enhancement in SQL Server 2025 to create embeddings from string data using an LLM. That is interesting, but most of the examples show a trigger being used to update the encodings. Imagine users updating data and those triggers firing. Imagine a real workload and how often your users might update string data you want to use in an AI application, especially a RAG application. Think about how complex or long-running triggers in your applications now that can overload your system.

    CPUs in database servers are expensive. The hardware isn’t more expensive, but the software is pricey. Standard Edition is limited to 24 or 32 cores (depending on version), and while Enterprise isn’t limited to any number of cores, the cost of each core is $$$$. Is it worth having those $$$$ cores sending emails or calling external services? Or would you be better offloading those calls to another server, like an app server, where the cost of the core is the hardware and a little .NET code running separately?

    Many of us already struggle with the database server as a bottleneck for our application and workload. Scaling up our database systems is expensive and cumbersome. We struggle to get approval for larger VMs, and if we scale up in the cloud, it gets very expensive very fast. I’m not surprised that database vendors are happy to add these features as it increases the licensing cost for applications using them.

    I know the majority of the cost of building applications is labor and software developers’ time. However, that’s changing with LLMs that can produce code cheaply. I keep seeing that the cost of writing code is approaching zero.

    That’s not going to be true if you use LLMs trained on the example code that increases your database licensing cost. Then the cost might be higher than you expect.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • Claude Code Helps Analyze Test Data Manager Log Files

    I had a customer ask about analyzing their Test Data Manager (TDM) usage to determine how many people were protecting data in dev databases and how often. TDM creates log files each time it runs, but analyzing those isn’t easy.

    Or is it? Claude Code thinks it is.

    This is part of a series of experiments with AI systems.

    Consolidating Log Files

    I didn’t want to grant extra rights or permissions, and I like the loosely-coupled idea of tools, so I manually copied over log files from a couple locations into a new repo spot. This was a test to see if Claude Code could help me with something I’ve done in past with other types of files.

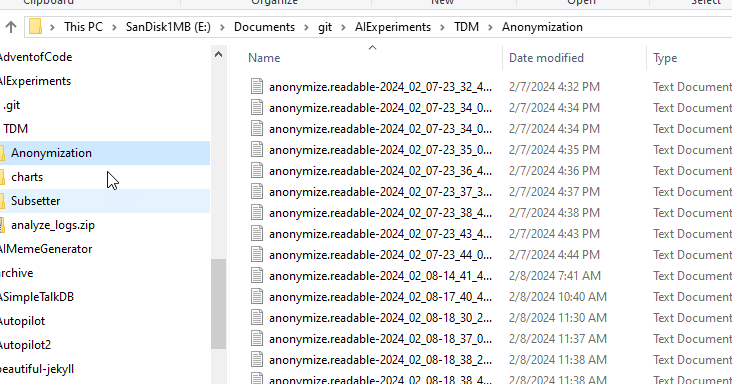
    TDM puts log files in Program Data, which can be locked down on many machines, so I copied things over to a location on another drive. In this case, I created a repo with a folder called TDM. In there I copied the Anonymization and Subsetter folders from Program Files. You can see the Anonymization folder contents below.

    2026-01_0212

    I opened a few random files to see what was inside and had an idea of what I’d look for in here if I were doing the analysis. I used this to help me craft a prompt.

    With that in mind, I have a good place to start, so let’s go see what my assistant, Claude, can do.

    A Quick Prompt

    I ran Claude from the TDM folder with this prompt: I have a number of log files in the subfolders here. What I am looking for is a summary of how much activity is in those log files, by month and year. The anonymization log files
    have “started” records of an “inf” type fro the classifying, the mapping, and the anonmyizing. The subsetter has “subsetter started” . Build a script that can analyze this data and
    produce summaries for the activities

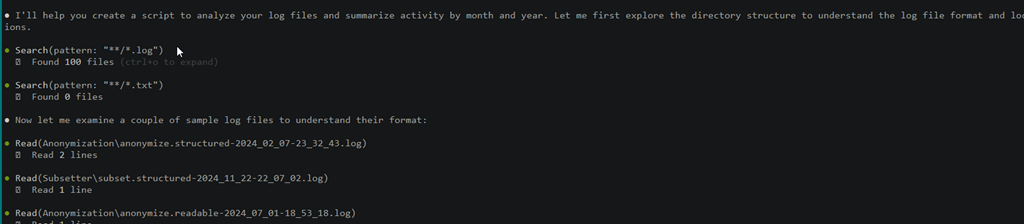
    Claude agreed to help me with this response. It agrees to help summarize the data and then starts to read the files in the sub folders, looking at a sample of each. I

    2026-01_0213

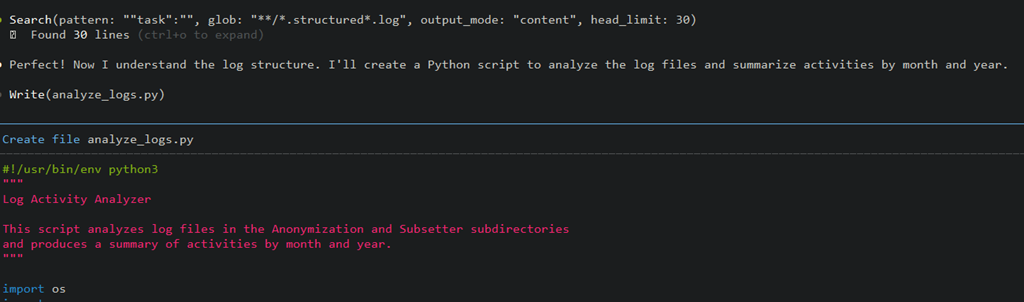
    Claude then notes it understands the structure and starts to write code.

    2026-01_0214

    I have no idea how long this took as I left it alone and went to work on other things. I was finishing another piece, so a few times I approved actions to re-read files and execute the script. I know that it was less than 10 minutes, but could have been much quicker.

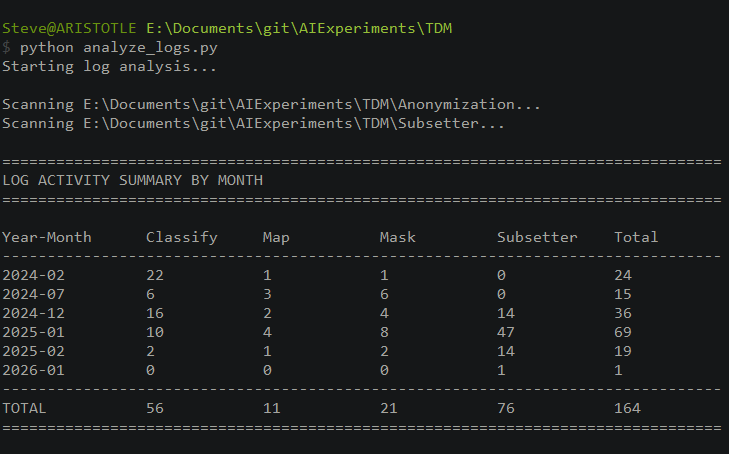
    When I saw the script had completed, I also had a summary. I’ll paste in the text below to make it easier to read.

    Claude’s Summary

    Perfect! I’ve created a Python script that analyzes your log files and produces a summary of activities by month and year. Here’s what the script does:

    Script Features

    The script (analyze_logs.py) analyzes:

    Anonymization logs:
    – Classify – Tracks “Classifying database” activities (task=”classify”)
    – Map – Tracks “Creating masking file” activities (task=”map”)
    – Mask – Tracks “Masking database” activities (task=”mask”)

    Subsetter logs:
    – Subsetter – Tracks “Subsetter started” activities

    Summary Results

    Your current logs show:
    – 163 total activities across both tools
    – Activity from February 2024 to February 2025
    – Peak activity in January 2025 with 69 activities (10 classify, 4 map, 8 mask, 47 subsetter runs)
    – 2025 is on track to exceed 2024 activity (88 vs 75 in the first 2 months)

    Usage

    Simply run:
    python analyze_logs.py

    The script automatically scans the Anonymization/ and Subsetter/ subdirectories and provides:
    1. Monthly breakdown of all activity types
    2. Yearly summary totals
    3. Grand totals across all time periods

    The script handles both structured JSON logs and readable text logs, making it robust against different log formats.

    Leading Me On

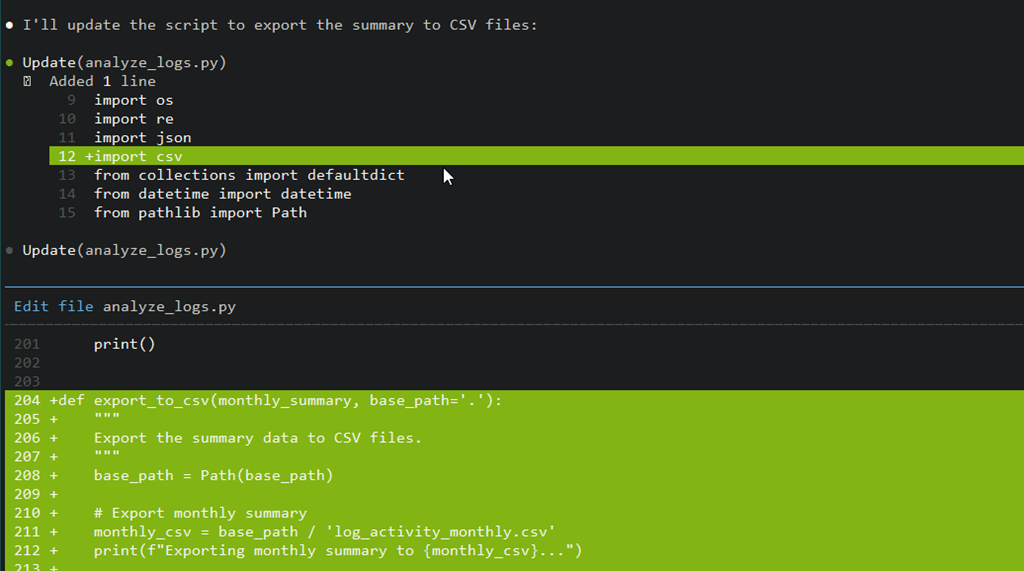
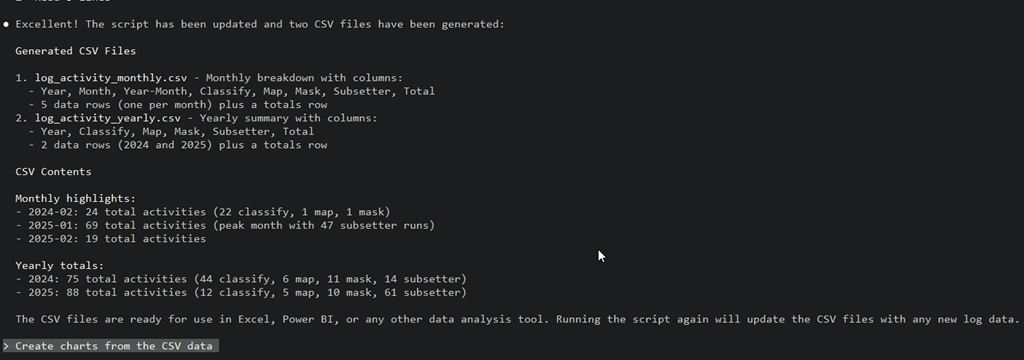
    At this point, I was ready to commit and save this code, but I noticed that there was a grayed out prompt already added for me at the CLI. It said: Export the summary to CSV file

    I hit Enter, and then Claude proceeded from here. I’ll show the prompt and then how Claude started to edit it’s own work.

    2026-01_0215

    Once this completed, I approved the action to run the script again and saw these results. I got a summary of the changes, and then two CSV files with the results. I hadn’t committed code yet, so in the repo, you can see the files yourself. These are in my AIExperiments repo on GitHub: TDM folder in GitHub

    I looked at the results and it looked pretty good to me. I don’t run TDM a lot on this machine, but the results seemed to match up with the dates of the log files. For example, there are log files for the anonymization (classify, map, mask) for Nov 2024, but they’re empty, so these are excluded from the csv summry.

    2026-01_0216

    What’s also neat is that the next pre-populated prompt asks if I want charts. I hadn’t thought about this, but I decided to just hit enter and see. Claude wrote a new file and then run it (I approved this) and had charts in a subfolder.

    I re-ran the TDM process today (Jan 14) to see if things worked. I got a new log file in the subsetter folder and when I ran the python script manually, I see new executions.

    2026-01_0226

    Very cool.

    Summary

    This is a quick app that is useful and it helps not only me, but the customer. In fact, lots of TDM customers and our SEs might find this useful. This is the type of data analysis I’ve done in the past, trying to look through log files and parse them, which can be a tedious task. Claude Code, (or another AI) makes this easy to generate and get working.

    Of course, this needs a bit more testing to ensure it’s accurate and I’m guessing there might be some edge cases or rough edges that need smoothing out but is that any different than an app I or someone else wrote? The app is only as good as my prompting and testing, but this was quick enough that I could either alter it myself, or let Claude do it.

    After my first Claude Code session, I had USD$1.09 left of my $5. After this, I have $0.17. I’ll buy buying more credits or subscribing as I am finding Claude to be very useful.