Tag: syndicated

  • Get Inspired – SQL Inspire 2011 New York

    Coming up next week is the SQL Inspire 2011 event in New York City. It’s an event with a number of SQL Server community speakers that are here to inspire you in your career, your life, and with SQL Server. The talks cover a variety of topics, and they look interesting. I am very excited to attend the event, and give my talk as well.

    The event is from SQL People, the brainchild of Andy Leonard and Brian Moran, designed to build a stronger community by having us inspire each other. This event is based on the TED events, which are inspirational and informative talks that look to explore new ideas in a variety of topic areas. I have loved watching many of the talks, and while I’m not sure I’m up to the same level of presenting as many of these people, I’m going to try.

    Please come if you are in New York on the 12th of November. It will be a lot of fun, and hopefully a very motivational event.

  • Document Your Day

    You should be documenting your day, your week, your month, on a regular basis. Take a few minutes when you accomplish something and make a blog entry. This is a great way for you to keep track of what you’ve accomplished during the year, and be ready to talk about it in an interview, or in a performance review.

    You don’t have to publically blog this. You can use Word, emacs, Live Writer, text files, whatever works, but, keep track of it. Read through it when you need it and summarize your accomplishments for the quarter or year. This is also something you consult every quarter when you touch your resume.

    And when you get ready for that review, read Kendra Little’s post on asking for a raise.

  • Buckets for Disaster Recovery

    Disaster recovery can be a huge project at any company. Considering the ways in which you build a plan that covers all the infrastructure, and it can quickly become a full time job for someone. The details, and the scope of the project can be overwhelming when you try to address your environment.

    There’s a way to make this easier: buckets. If you can group your systems into a few gross buckets that define those systems that have similar needs, you can make life simpler.

    In the past, I have typically built four buckets of systems for DR purposes, though I think you could go with three. These are the buckets I’ve had:

    • Critical Systems – high priority systems that typically must be running the majority of the business day. Note that you may have a 24 hour business day in which case downtime must be minimized to minutes.
    • Low priority – systems that we can function without for a day or two if we need to. Often development systems fall into this area.
    • Everything else – Medium levels of priority.
    • Not recovered – This is an optional level, but it’s almost always been a set of test systems, maybe some development systems that aren’t important enough to worry about.

    The fourth bucket, the “Not Recovered” bucket doesn’t mean you abandon those systems. In the event of an issue, you would make an attempt to recover them, but you might not spend time or resources practicing or preparing for the recovery effort.

    Bucketing your systems is the best way to easily manage your preparations for disaster, and also set some gross priorities. You might end up recovering systems within the bucket in different orders, depending on what happened, but this gives you an easy way to allocate resources, both in a disaster, and in preparation.

  • The Basics of Joins – Skill #4

    This series of blog posts are related to my presentation, The Top Ten Skills You Need, which is scheduled for a few deliveries in 2011.

    Databases are built to store data. That’s the primary purpose, and in SQL Server, we store data in a relational form. That means that often we have data spread across multiple tables. Why we do this is a discussion for another day, but suffice it to say that we often have structures like this:

    personcontact

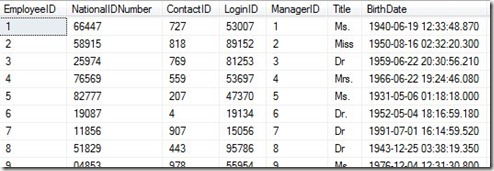
    Part of the person.contact table in AdventureWorks above and the HumanResource.Employee table below.
    employee

    One typical join task might be to get an employee’s name, or a list of employees and their names. Here we have a birthday in the Employee table, but we don’t have a name. That’s in the Person.Contact table. Essentially we want to match these up using basic, elementary school set theory.

    settheory

    In the diagram above, you can think of each letter as a row in a table. As an example, let’s assume that B in the orange circle represents the row in the employee table with a ContactID value of 4. The B in the pink circle would represent the row in the Contact table with a ContactID value of 4 as well.

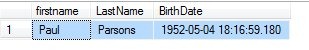
    When we join these to get the Employee name and birth date, we get:

    join2

    I used a join in my query to get that:

    SELECT 
      c.firstname
    , c.LastName
    , e.BirthDate
     FROM person.contact c
       INNER JOIN HumanResources.Employee e
         ON c.ContactID = e.ContactID
     WHERE c.ContactID = 4
     

    In this query I’ve included two tables in the FROM clause with the INNER JOIN key phrase between them, which specifies I only choose the matching rows. The match is made in the ON clause.

    I’ve also qualified this to only apply to the row with a ContactID of 4 in the WHERE clause.

    There’s a lot more you can do with joins, and you can include more than two tables, such as this query:

    SELECT 
      c.firstname
    , c.LastName
    , e.BirthDate
    , pa.AddressLine1
    , pa.AddressLine2
     FROM person.contact c
       INNER JOIN HumanResources.Employee e
         ON c.ContactID = e.ContactID
       INNER JOIN HumanResources.EmployeeAddress ea
         ON e.EmployeeID = ea.EmployeeID
       INNER JOIN person.Address pa
         ON ea.AddressID = pa.AddressID
     WHERE c.ContactID = 4
     

    I would recommend that you practice working with basic joins, based on the information that you commonly see queried in your application. Sooner or later someone will ask you for some data that isn’t available in the application and you will want to write a query to extract it for them.