Tag: syndicated

  • Why Two Devices

    I used to travel with two laptops, one as a backup, however lately I’ve switched to taking the iPad and a laptop. The iPad doesn’t double as a backup, but it does let me do things like take notes at events or conferences with an extremely long battery life. My laptop only gets 2-2.5 hours, and when you’re on the go for 10 hours, you need something else. I also use the iPad for demos of SQL Monitor, from Red Gate, using http://monitor.red-gate.com/ 

    However I’ve been tempted to get a real second machine, something that is truly a backup. I read Brent Ozar’s post on his MacBook Air, and it’s really tempting to get one of those, especially as I use VMware, which works agree both Mac and PCs.

    Seth Godin as another interesting argument for a second machine. Use one for pleasure, or distractions, and one for work. That’s not bad, but I kind of do that with my phone. I read on it and listen to music, as a break from the laptop (or sometimes in conjunction with it).

    I’m a practical guy, and don’t want to get (too many) gadgets for fun, especially laptops. I went through that last year, going from a Win 7 tablet to the iPad, which was a good move for me. At least my daughter thinks so.

    For now I think I’ll stick with just the iPad and my Lenovo. However when I look for a new laptop, I have to say that the MBP will be high on my list, just to try something new.
  • Five Lines of Code

    An interesting story on how a database speeds up by changing some application code. Worth the read for sure.

    I caught this from Andy Warren’s blog, and it shows why we need developers to think for themselves and ask relevant questions, not just meet the spec. If someone had asked if Accuweather needed micro-granularity for location earlier, they might never have had issues.

  • Setting a Unique Index on a Bit Field

    Can you set a unique index on a bit field? Well, you can, but you’d end up with a very short table of two (or three) rows. I defined this table:

    CREATE TABLE [dbo].[BitTest](
        [MyBit] [bit] NULL,
        [MyName] [varchar](50) NULL
    ) ON [PRIMARY]
    
    GO
    
    USE [db1]
    GO
    
    CREATE UNIQUE NONCLUSTERED INDEX [IX_BitTest] ON [dbo].[BitTest] 
    (
        [MyBit] ASC
    )WITH (PAD_INDEX  = OFF, STATISTICS_NORECOMPUTE  = OFF, SORT_IN_TEMPDB = OFF, IGNORE_DUP_KEY = OFF, DROP_EXISTING = OFF, ONLINE = OFF, ALLOW_ROW_LOCKS  = ON, ALLOW_PAGE_LOCKS  = ON) ON [PRIMARY]
    GO
    

    and then added some data

    INSERT BitTest SELECT 1, 'Test'
    INSERT BitTest SELECT 0, 'Test2'
    INSERT BitTest SELECT NULL, 'Test 3'
    
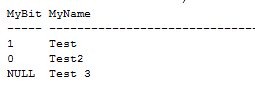
    SELECT * FROM BitTest

    This table has these rows:

    bittest2

    Adding another row:

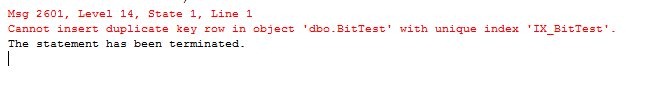
    INSERT BitTest SELECT 1, 'Test 4'
    

    gets you an error:

    bittest3

    However what about a compound index? What if I make the table larger and add more fields. Here’s a larger table:

    CREATE TABLE UniqueBit
    ( BureauID INT
    , CompanyID INT
    , DivisionID int
    , DefaultType BIT
    , ProductName VARCHAR(100)
    )
    GO
    INSERT Uniquebit SELECT 1, 1, 1, 1, 'Product 1'
    INSERT Uniquebit SELECT 2, 1, 1, 1, 'Product 2'
    INSERT Uniquebit SELECT 3, 1, 1, 1, 'Product 3'
    INSERT Uniquebit SELECT 4, 1, 1, 1, 'Product 4'
    INSERT Uniquebit SELECT 1, 2, 2, 1, 'Product 5'
    INSERT Uniquebit SELECT 1, 2, 3, 1, 'Product 6'
    INSERT Uniquebit SELECT 4, 1, 1, 0, 'Product 7'

    If I now add a unique index:

    CREATE UNIQUE NONCLUSTERED INDEX [IX_UniqueBit] ON [dbo].[UniqueBit] 
    (
        [BureauID] ASC,
        [CompanyID] ASC,
        [DefaultType] ASC,
        [DivisionID] ASC
    ) ON [PRIMARY]
    GO
    

    It works fine. I can add another unique row like this:

    INSERT Uniquebit SELECT 4, 2, 1, 0, 'Product 7'

    without an error. Adding in a non-unique row:

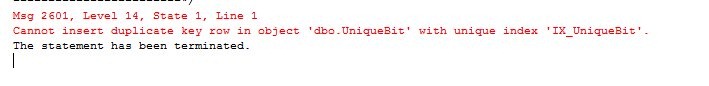
    INSERT Uniquebit SELECT 4, 1, 1, 0, 'Product 7'
    

    gives me an error:

    bittest4

    There’s nothing special about a bit column for a unique index. There are restrictions for bit fields in some ways that relate to indexing, but uniqueness is not one of them.

    This was inspired by this post (before the complete details from the OP): http://www.sqlservercentral.com/Forums/Topic1126794-149-1.aspx#bm1126850

  • Data Compression in SQL Server

    Do you know much about data compression? It seems that quite a few people I meet don’t really understand how it works, or what the benefits are. I heard about compression first hand from Sunil Agarwal a few years back at TechEd. I visited one of his sessions and then he was gracious enough to spend about 15-20 minutes with me afterwards answering more questions about additional details. At the time, I was just another schmuck in the audience, but Sunil was very pleasant and patient with me.

    I was lucky that day,but Sunil has a video where he explains some of the ways in which compression works for Microsoft customers.

    http://channel9.msdn.com/posts/SQL-Server-Data-Compression/player?w=512&h=288

    The summary is that data compression works in a few ways. One is, obviously, to save space. The second, however, is that fewer I/Os’s are required to move data onor off a disk, which can result in a performance increase. The SQL Server team tried to strike a balance in how they implemented compression to allow for both of these benefits. The tradeoff is that CPU is needed to compress or decompress data, so while more compression is possible, it can negatively impact performance.

    Compression is a cool feature, and consists of a few parts. You can read more about each of them if you are interested:

    The DBA has complete control over what is compressed, but it is also some work to analyze the space savings and then make a determination about whether or not it is worth you compressing your table. If the space savings is too small, you might end up negating any storage gains with additional CPU costs.

    How Do I Decide?

    There is a stored procedure (sp_estimate_data_compression_savings) that can be used on tables or indexes to help you determine what the savings are. Numerous scripts are available, like this one from Paul Neilsen – Whole Database – Data Compression Procs.

    There’s also one easy decision. Only Enterprise and Data Center editions of SQL Server support this feature, so if you aren’t running those, you don’t have to worry about this.

    Alternatives

    There are a couple other alternatives to implementing data compression.  If you want to get compression savings in other editions of SQL Server, my company, Red Gate Software, makes a product called SQL Storage Compress, which implements compression at the file level.

    This is based on Hyperbac technology and is completely transparent to SQL Server. We are working on some extensive case studies now and this is part of the SQL Server I/O Reliability Program, but this can help performance on your system by reducing I/O.

    If space is an issue in test, customer service, and development environments, you can use Virtual Restore to mount a backup file as a database that you can read, or write to. The writes occur in a sparse file, so your backup file is untouched. However you get a quicker “restore” that is transparent to SQL Server.

    As I mentioned, I work for Red Gate software, so take these as mentions of products my company builds and sells. I’ve heard great things about them, and use them in a few places for work at SQLServerCentral. I’d recommend you try them and see if they are a fit in your environment and have a good price/value ratio for your company.