Author: way0utwest

  • Create a BACPAC–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    One of the things that you might encounter at some point is the need to create a BACPAC. This is essentially a DACPAC with data included. There are times you might find a BACPAC more convenient than a full backup, especially if you work with Azure.

    This post shows how you can create a BACPPAC file (with the extension .bacpac) from SSMS.

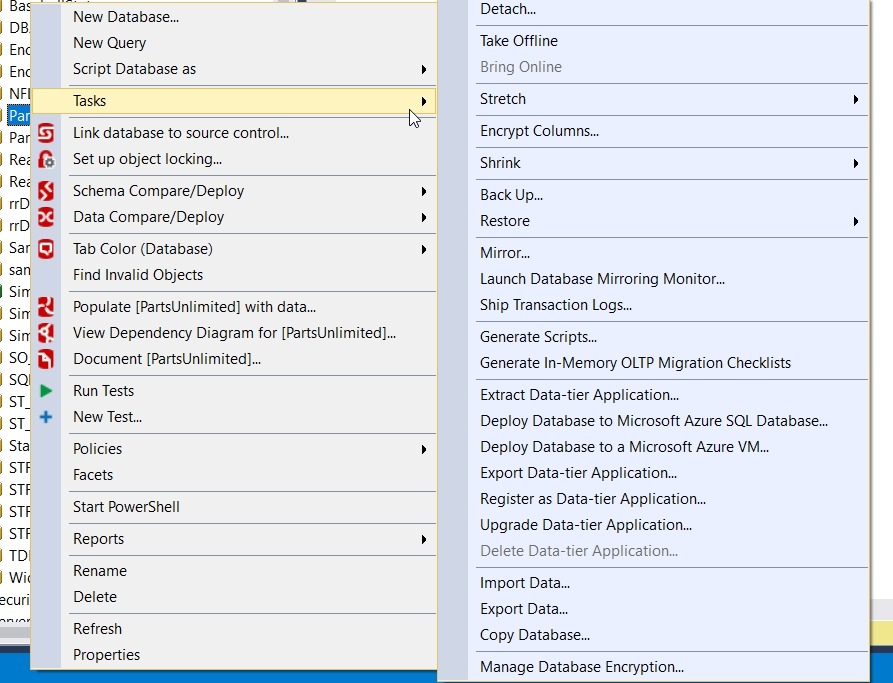
    I have a small database, the PartsUnlimited database, from the Microsoft PartsUnlimited demo application. I want to create a BACPAC from this, however, when I right click and select Tasks, there is no “Create BACPAC” option.

    2017-02-21 14_08_41-SQLQuery1.sql - dkranchlabdemo.database.windows.net.master (sjones (113)) - Micr

    That’s fine, because the “Data Tier Application” is the DAC, and an export includes the data, which creates the BAC part of the process. Let’s choose “Export Data-tier Application”. Once we do that, we get the expected summary wizard screen to start.

    2017-02-21 14_10_05-Export Data-tier Application 'PartsUnlimited'

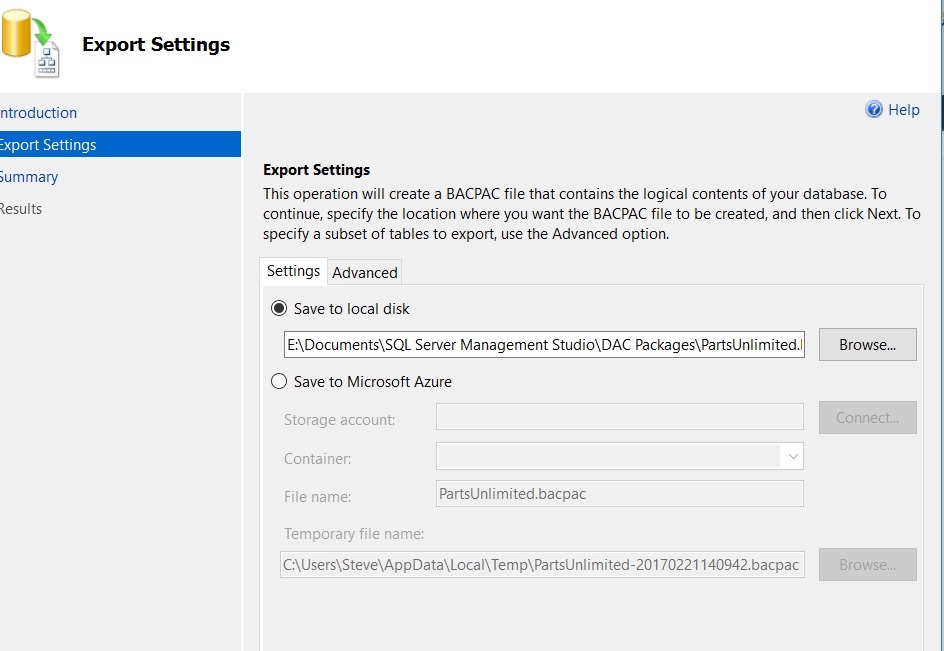
    I click next and immediately get prompted for a location in which to save the file. The will include all your data, so choose a location that has sufficient disk space. You have the option to also store this in Azure if needed.

    2017-02-21 14_10_43-SQLQuery1.sql - dkranchlabdemo.database.windows.net.master (sjones (113)) - Micr

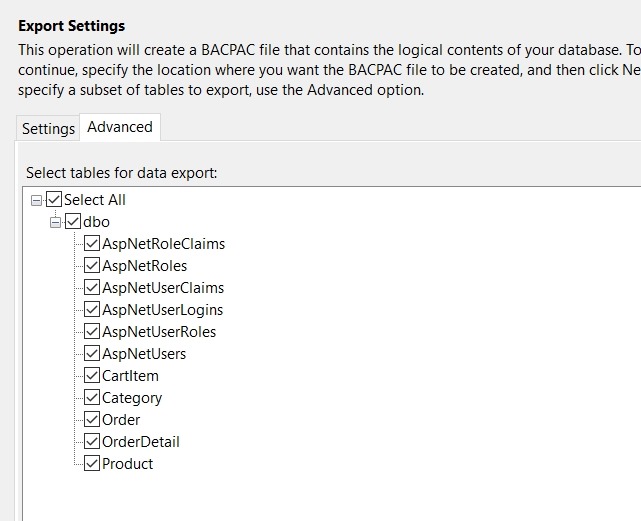
    Note the filename above is already filled out by default, but you can change this in the edit box. If you click the “Advanced” tab, you’ll get the chance to select only certain tables if that is required. You can see this dialog below.

    2017-02-21 14_10_50-Export Data-tier Application 'PartsUnlimited'

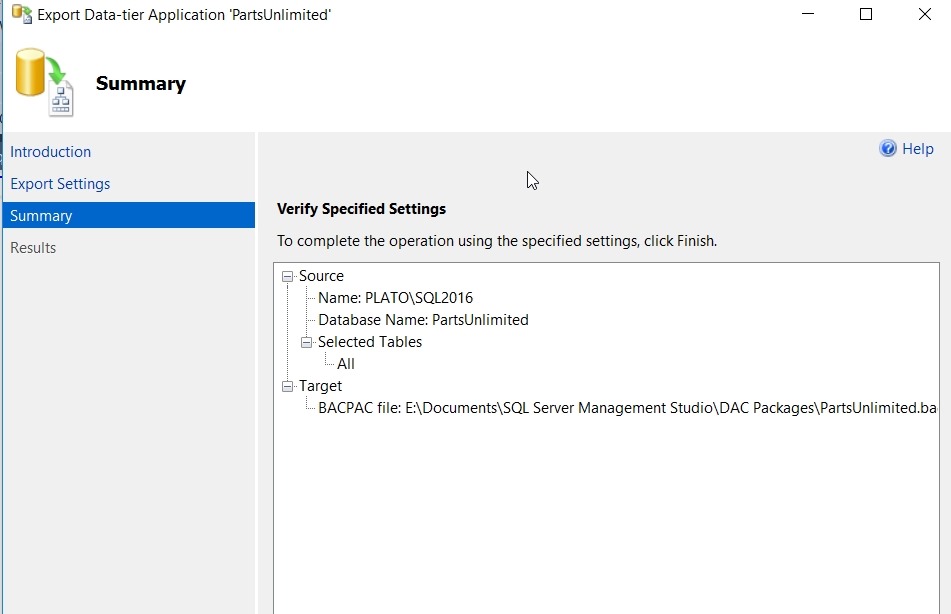
    Once you’ve chosen a location, you click next and get a summary page.

    2017-02-21 14_13_31-Export Data-tier Application 'PartsUnlimited'

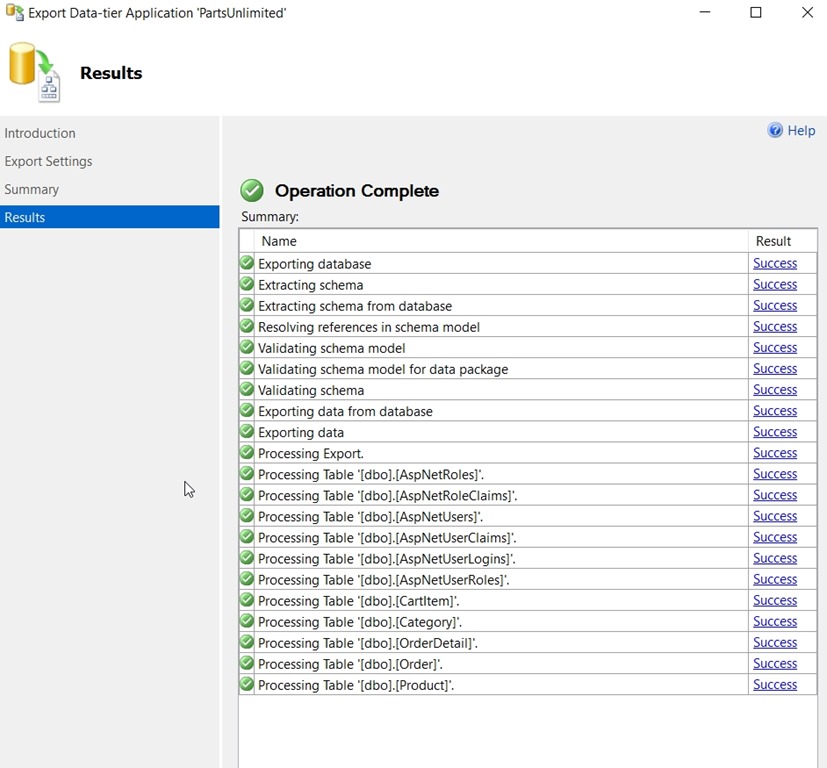
    Click finish, and the process starts. This runs very quickly, extracting the schema and then all the data, noting the results of each object.

    2017-02-21 14_13_38-Export Data-tier Application 'PartsUnlimited'

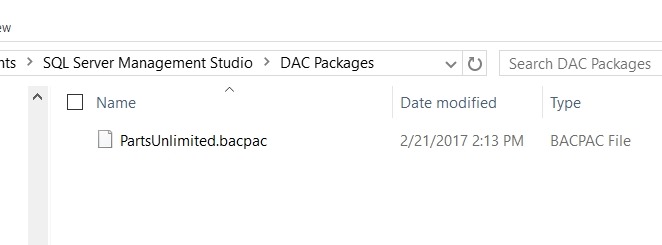
    That’s it. If I look in the location, I’ll see my BACPAC file.

    2017-02-21 14_15_11-DAC Packages

    I can copy this to another machine and import it to recreate a database. We’ll do that in another post.

    SQLNewBlogger

    A short, quick post. I’ve done this before, but I had to do this for a quick process and took 5 extra minutes to take screen shots, spending 5 minutes later writing this up.

  • The Livestream Product Launch

    SQL in the City Streamed in 2016 was a success, with lots of feedback that people enjoyed the sessions and format. With the release of SQL Clone, we’ve decided to do it again.

    The SQL Clone Product Launch Live Stream is coming in a couple weeks, on Mar 29, live from Cambridge, UK. I’ll be traveling there, along with Grant Fritchey, and we’ll both be helping broadcast all day, repeating sessions across many time zones.

    Join us and see if SQL Clone is right for you. Or download an eval and give it a try.

  • DevOps Isn’t Perfect

    I saw a post recently from Grant Fritchey, Help Me, Help You, Deliver DevOps. In it, Grant shows that DevOps isn’t making developers do everything, it isn’t just giving developers more responsibility, and it isn’t developers handling some of the operational staff responsibilities. It’s about getting development and operations to work together. Hence, DevOps, not DEVops, or Dev    ops.

    In the post, Grant also links to some fundamental failures from companies that supposedly have adopted DevOps processes. Companies like Gitlab and Amazon. There are plenty more examples, which certainly make some people question whether DevOps is better than other methods of building and deploying software.  How are the VSTS issues different from the Knight Capital debacle?

    In some sense, they aren’t. In many cases, we’ve had a software issue that affected customers. People were upset, services weren’t delivered, and it’s entirely possible that revenue was lost. However, one of the things that I think differentiates DevOps is that developers and operational staff can troubleshoot and determine a root cause much quicker. Since the entire commit, build, test, release pipeline is instrumented and documented, your staff can quickly determine what new items might have caused an issue. If it’s not a new item, they can also quickly determine if that’s the case.

    However, once you’ve placed your system in production, DevOps doesn’t ensure that your HA (High Availability) or DR (Disaster Recovery) preparations are adequate. Those are still the responsibility of your Ops staff, but by using DevOps, and storing configuration as code and provisioning your systems in all environments the same, hopefully you’ve taken advantage of this to actually ensure you have tested some HA or DR features in an environment outside of production.

    However, DevOps isn’t prescriptive advice. DevOps isn’t a particular process or a tool that you use or install. DevOps is about learning and improving over time. For different companies, this means you’ll be at a different stage in your DevOps maturity than other companies. Some have complete deployment processes, but limited instrumentation and monitoring in production. Some have tons of data and deploy code perfectly, but no HA. Some have great HA, but poor deployment processes.

    DevOps is about constant improvement and advancement to make your software development (Dev) and deployment (Dev and Ops) and monitoring/management (Ops) better over time. This might not prevent human error, or even code bugs, but DevOps should mean you make fewer mistakes, less often, and learn from them to avoid repeating those issues.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.7MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • T-SQL Tuesday #88 – WTF

    tsqltuesdayIt’s T-SQL Tuesday time again, and this is a good one. The host this month is Kennie Pontoppidan, who I had the pleasure of running with one morning in Copenhagen. His theme is The daily (database-related) WTF.

    You can read about T-SQL Tuesday at tsqltuesday.com and see all the archived invitations. Join in the fun by watching the site, or the #tsql2sday hashtag on Twitter. If you want to catch up on old invites, feel free.

    WTF

    I’m not sure if I have a great story, but I certainly have had a few “WTF” items in my career. Some of them caused by me, some by others, and often not a good thing.

    The one item that I’ll relate here goes back quite some years in history, but it was one that affected me for many years in my career. I do quite a bit of work with DevOps and software development these days, trying to help people build better software.

    Part of that is ensuring your code, including your database code, is in a version control system (VCS). I’ve worked in a variety of environments, using different source code control methods, and I have to relate a story that taught me how important it can be to manage code and track the versions in production.

    A long time ago I went to work for a small startup. The company had been in business for 5 or 6 years, and had a number of customers that depended on our service. However, our developers and admins were a mess. I was brought in to try and straighten out the the database and infrastructure side of our codebase.

    One of the first things I found was that all our stored procedures in the production server were encrypted. I wasn’t sure why, since we hosted our machines, but that wasn’t a big deal.

    Until it was.

    One day we had an issue on one of our SQL Server 2000 servers (we had two, supposedly identical). In troubleshooting and putting some sample data in both systems for a fake customer, we got different results. Hmmm, not what I wanted to see.

    I checked the VCS (SourceSafe at the time) and checked out the code. I then loaded my test data and … got a third, different result. Now I was concerned as this was a production bug that was delaying work for a customer.

    This was early in my tenure at the company, so I asked the other DBA for some information. He had been passed over in favor of me by management and wasn’t a great deal of help. He told me that he likely had the source code for server 1 on his machine.

    You might start to guess why this is a WTF post. Rather than get upset, I wanted to see the code, which he produced. His version was one one of the servers, but not the other. Where was that code? He thought it was on the lead developer’s machine, who conveniently, was on vacation. We checked, and it wasn’t in his checked out folder structure.

    What about our former developers, who had moved out of state? We still had their machines, which were supposedly going to be shipped to them so they could continue working for us. The checkout folder wasn’t right, but we found 2 other folder structures, copies of the source code tree, with different code. At this point, I just needed to fix the issue, and managed to find a copy of the stored procedure that matched my issue, built a correction, and deployed it to both servers. Unencrypted.

    Detective Time

    At this point, I paused some work that the DBAs were assigned. We spent a day or so pouring over all developer’s machines, finding 6 or 7 different copies of source code (plus our SourceSafe install). Multiple files were different, and we essentially had no idea what was running in production.

    Apparently our developers had decided that when they checked in code, they would leave it on their machines. If they wanted a branch, in essence, they’d copy this folder over, make changes, and sometimes copy things back, but mostly just assume they knew what was good, and leave the updates on disk, uncommitted to the VCS.

    I couldn’t come up with a rational reason for this. Back then, we didn’t have any sort of integration like SQL Source Control and we checked code in and out of the VCS manually. I had previously set all my machines to remove the code from my local disk, ensuring I’d go to the VCS to get code when I needed to change something. I suspected this was one way of creating ”job security” by a few developers and DBAs. Hint: it didn’t work with me.

    Solving the Issues

    This necessitated a complete reboot of our system. Together with a new lead developer (you can guess where the old one went), we paused development for 3-4 days. I found a routine to decrypt SQL Server 2000 stored procedures, and we all spent time decrypting the stored procedures from both instances and committing them back to a new tree in SourceSafe. If we had an discrepancies, then we had at least two developers examine the code, merge the differences and commit code.

    After a week of lost work, we had a clean source code tree of what was running in production, and both database servers synchronized. From there, we could start new development. Learning from the issues, I also would only deploy changes from the VCS (manually back then), which ensured the developers had an incentive to commit their changes and not just alter the database objects on the development server.

    Of course they still did, and we had numerous deployment issues. If only we’d had a few better tools back then for CI and CD in the database world.