Author: way0utwest

  • Is Rollback Feasible for Database Changes?

    One of the things I used to show people in SQL Compare was the ability to generate a quick rollback script by switching the source and target. We can generate a deployment script going from Dev to Production, switch the source and target, and then generate the rollback script, from Production to Dev. This was the automation of a manual process I used to go through, examining changes made in deployment scripts and producing the reversing changes for various schema items.

    Really the only object that causes us problems is the table. We can easily grab previous versions of views, functions, stored procedures and other code objects, applying them on top of our deployment without worrying about maintaining state. We can go back and forth with different versions of code. Certainly our applications might have issues, but the database itself works fine and deployment is quick.

    However, that’s not the case for tables. If I add a column to a table in a deployment, how do I remove it? Certainly I can drop the column, but what happens if there’s been a data transformation, or users have entered data? I might need to preserve the data that’s been added, which is a process I might not want to script. What if I split a column or refactor data to a new table? The movement of data back to it’s original spot, while preserving any changed data, is not a trivial task. Add up enough changes in a deployment and it wouldn’t be worth running any rollback scripts. A database restore might be more efficient.

    Recently I was discussing these issues with a developer, who remarked that they never built rollback scripts. It wasn’t a good use of time. If there were issues, developers or DBAs would need to make decisions about how to handle the issues. These days, as we’ve become better at architecting database applications, we might even decide to leave the actual table alone and use view or stored procedure change to effect a virtual rollback for the application, erasing the changed schema with code rather than actually returning the table schemas to their previous versions.

    As I see our organizations depending on databases to a larger and larger degree, requiring no more downtime than actually needed, I think that rollback scripts for tables might be a thing of the past. Certainly rolling back object code is still possible, with an understanding of the impact on both the database and application when old code is used. That’s definitely a decision that needs to be made on a deployment by deployment basis.

    My view is that whenever possible, both the application and database should try to be forward and backward compatible by one version to allow changes to be made to one or the other without breaking the system. That’s not always easy, but in many cases it is with a little forethought, practice, and awareness of the architecture techniques that allow this, it can be relatively easy. In some cases, especially with smaller databases or discrete, limited changes, rollback scripts might make sense. However, I think for most of us this is a software development pattern that’s not worth considering most of the time.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 4.4MB) podcast or subscribe to the feed at iTunes and Mevio .

  • PoSh Everywhere

    This week we had an announcement that PowerShell has been released as an open source project and is available on some Linux platforms as well as OSX. I was actually talking with someone else that had been informed prior to the MS announcement, and they told me to go to github.com/powershell/powershell. I first I thought I was getting some inside information. However this is a public site, obviously updated and released in time for the announcement, so no NDAs were harmed this week.
    I have an Ubuntu VM I use at times, and I decided to take a few minutes to try out PoSh on Ubuntu 16.04. Installation was easy, as are most things on Linux. Not quite as simple as Chocolatey, but close. This is certainly one of the ways that Linux is a bit easier to use than Windows. Or maybe we’re just more used to the command line in Linux. In any case, it’s a very simple process, which I documented in a blog. For those of you that use PoSh, this will be easy, and for those of you used to Linux and shell scripting, you’ll feel right at home.
     I wondered how much stuff would work, but my first few tests, grabbing some generic, non SQL Server, scripts worked fine. The .Net CORE project has already moved some of the namespaces and functionality over, and this means  that a lot of the management of your infrastructure systems is there. I don’t see the SQL Server libraries ported over (if I’m wrong, someone let me know), but there certainly are some other items, including Azure modules. I thought the demos in this Channel 9 webinar, while simple, were pretty impressive.
    Do most of us care about this? No, not really. If you’re a person that runs Windows on laptops and desktops, this doesn’t really matter to you. I run Linux for fun, but not for daily work and my use of these tools will likely be limited to testing. However, if I were to move to an Android or Linux machine in the future, it’s nice to know that I could run the same packages across various platforms without changing any code. That’s useful for collaboration with people that might want to work together on different platforms.
    This is where this makes the world easier. If you have friends running Macs, or using Linux, then you can share code. Or they can write PoSh scripts and share them with you. While I love virtualization, sometimes it’s a pain, and this is why I keep an installation of SQL Server on my host. It’s simpler and easier to work with in some situations. This is also why I look forward to a SQL Server developer edition on Linux (and hopefully OSX). It’s just a smoother world when the OS becomes a matter of choice, rather than a requirement to run some code.
  • PoSh on Ubuntu

    I heard about the PowerShell announcement recently where the platform is porting over to Linux and OSX. I think this is part of the SQL Server on Linux project, where I assume we’ll start to see the functionality that we have on Windows appear on Linux platforms. OSX is a surprise, but since more and more people run Macs, this makes sense. Hopefully we’ll see SQL Server Developer on OSX at some point.

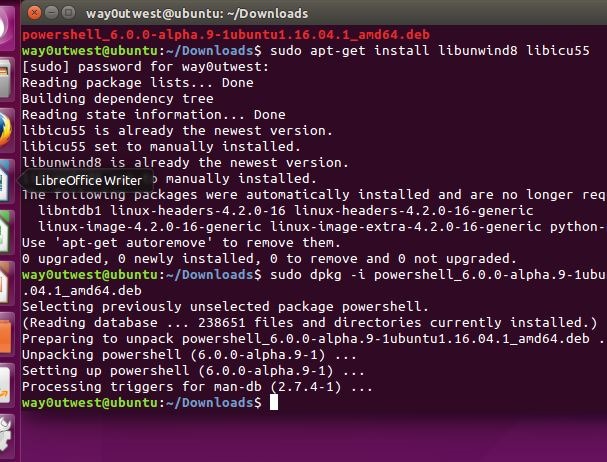
    I’ve got an Ubuntu VM, so I decided to see how well this works, so I picked the Ubuntu 16.04 package and found the instructions I ran on my VM. You can see how this worked in the image below.

    2016-08-18 12_37_14-Ubuntu 64-bit SQL Server - VMware Workstation

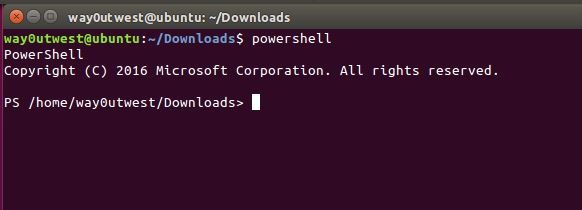
    Now that I’ve got the package downloaded, I can start PowerShell pretty simply:

    2016-08-18 12_38_51-Ubuntu 64-bit SQL Server - VMware Workstation

    What can I do? Well, let me grab a short PoSh script I have. This is from the Advent of Code, and it’s a .ps1 for me. Here it is interactively.

    2016-08-18 12_49_53-Ubuntu 64-bit SQL Server - VMware Workstation

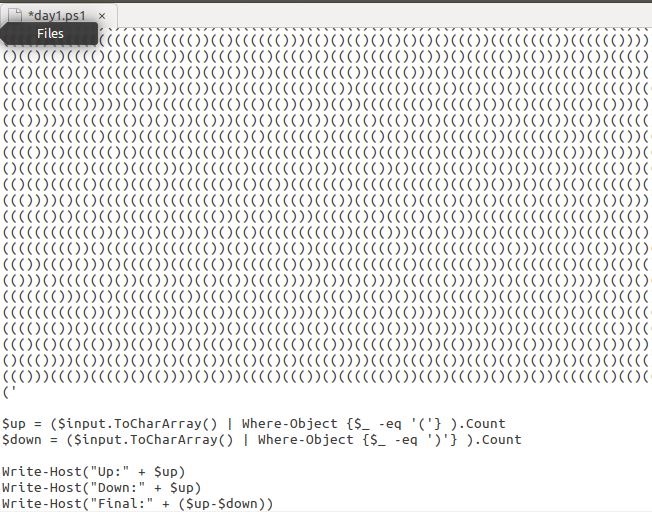
    If I make a .PS1, then I can paste in the original code:

    2016-08-18 12_51_09-Ubuntu 64-bit SQL Server - VMware Workstation

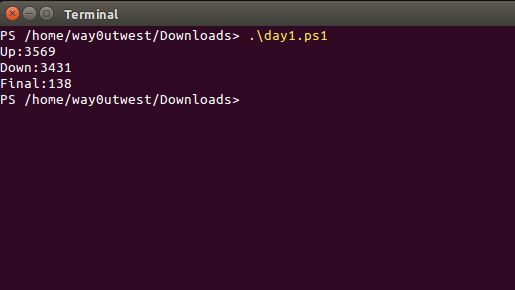
    and if I execute this:

    2016-08-19 11_07_01-Ubuntu 64-bit SQL Server - VMware Workstation

    That’s pretty cool.

    I haven’t explorer the extent of the PoSh support, and I don’t think there is SQL Server support yet for the SMO namespaces, but I’m sure it’s coming.

    If you’re a Linux person, or an OSX person, I’d encourage you to play a bit and see what you think of the port.

  • What’s Your Smoke Test?

    Many DBAs and operational staff regularly stress over software deployments to production systems. Even when the administrator has built and tested the deployment scripts, there is still a nagging fear that something will be missed, incurring downtime for systems. I think automation, building an ALM And DLM process, as well practicing deployments in other environments is the way to alleviate concerns, but that’s a discussion for another day.

    However, I had a question this week that is related to the deployment process. I’m curious, do you smoke test your production deployments?

    Perhaps the first question is do you know what a smoke test is? If you don’t, maybe you want to read a bit about smoke tests. If you know about smoke tests, do you have anything more than testing if a server or service is running?

    If you don’t, that’s fine. In fact, throughout most of my career our smoke tests consisted of checking that we could connect to a server or database. In fact, in most cases, we did this manually. We’d deploy some change or patch, then see if we could connect to the server. Sometimes a person would connect with an application, but not much more than logging in. Since many apps were fairly simple client-server applications, this was usually sufficient, but there were times we had problems with not all changes being deployed. A few times we didn’t realize this for days.

    If you deploy changes, there should be some small things that you check as an method of validating that your systems are working correctly. There may be initial checks that machines are actually running. If those checks fail, there’s no point in going further. However, if the basic connections work, perhaps you should have a few critical functions that can be called and ensure that basic functionality of the application is there. Or that your new changes actually are deployed. If you have complex, interconnected systems, maybe you want a few smoke tests that you can automate and quickly ensure everything is running as expected and communicating.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.0MB) podcast or subscribe to the feed at iTunes and Mevio