Author: way0utwest

  • Data Overload

    Data rich and information poor. I think that describes most of the companies I’ve worked for. It’s a theme in this piece from Forbes, noting that many companies use only a fraction of the data they have to make decisions. Certainly I think that many of us that work as data professionals might note that most queries access a portion of our data, often the newest data, with older data sitting on storage systems, constantly powered on, but rarely included in a report.

    Retrofitting archival processes into an existing application can be hard. Even more so when there is rarely queried data that clients want to be sure is still accessible somehow. The Stretch Database feature in SQL Server 2016 might help, but I bet it’s a long time before most of us have all our systems on SQL Server 2016 or later versions, let alone finding someone to pay for this feature.

    There are real costs to keeping this data around, first and foremost of which is the stress for us as developers and DBAs as we try to tune queries the must run against larger and larger data sets. Actually, I’m only somewhat kidding. Management and clients might not care about this, but having to work against larger and larger can be stressful for technical professionals.

    There are other, more concrete and measurable costs to keeping this data around. The cost of power and larger storage systems. With many companies keeping multiple copies of production systems around for different purposes, these can be noticeable costs. There’s also the time factor. If our systems run just 10% slower, that’s potentially 10% less business we can handle. Or maybe all that extra data means more annoyance and frustration from our customers due to slow systems.

    We are going to get more and more data in our systems. While much of this data may be useful, if we’re overloaded, we may not be able to take advantage of the information. We also might get erroneous results if we don’t recognize that data gets old, and the value we might have from a row today might not exist in a few years. We should also realize that at times we have lots of data that isn’t useful at all for our organization.

    I really would start thinking about the ways in which we can actually remove older data from our systems, with archival to cold systems, or even deletion if we’ve moved copies of data to other applications, such as data warehouse systems. Or maybe just deleting data we know isn’t going to provide any information. Above all, remember that warehouses will fill up at some point, unless you buy more and more (expensive) storage. Keeping all data accessible might not be the best decision for your organization.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.5MB) podcast or subscribe to the feed at iTunes and Mevio .
  • T-SQL Tuesday #81–Sharpening Skills

    This is an interesting month for T-SQL Tuesday. The challenge is from Jason Brimhall to Sharpen Something, and learn something new. However, his challenge isn’t just a simple “learn something.” Instead, he writes:

    “This month I am asking you to not only write a post but to do a little homework – first. In other words, plan to do something, carry out that plan, and then write about the experience.”

    I didn’t see the original invite, but I saw the reminder, and so had less than a week to actually try something. Fortunately I was starting something new, so I decided to incorporate that into my post.

    The Plan

    I have been doing a little work with auditing, as part of trying to better understand security around SQL Server. With that in mind, I’ve been meaning to do more Extended Events work. I’ve done a little, inspired by Erin Stellato, and as I read the invitation, I thought this would be a good time to tackle something. My plan:

    I know there are potential issues with the matching of events here, but this is an experiment, and the chance to learn.

    The Actions

    Last week my daughter had a volleyball tournament during the week. As a result, I was working remotely, in coffee shops and gym bleachers, trying to get work done. The day after starting this plan, my laptop started to die, with no good outlets nearby. At least not where I could see my daughter.

    So I started Erin’s course. While I saw pieces of a few sets, I also watched the first 3 modules in the course, and even made a few notes in Evernote of things to try. The next day I finished the course late in the afternoon.

    Part 1 done.

    Now on to actually practicing.  I downloaded the exercise files from the course and started to work through some of them. The first XE sessions are simple, but worth setting up to get a feel for the code. I could do things in the GUI, but I wanted to play with code a bit.

    I ran a few items, trying to remember how they worked, and I realize that I needed to review a few things.

    Testing Myself

    The challenge for myself is to create a new session that does event matching, but looking for those transactions started, but not ended. I decided to use the GUI to do this, mainly because I was pressed for time. It’s been a busy week, and weekend, so I didn’t have as much time to experiment as I’d like.

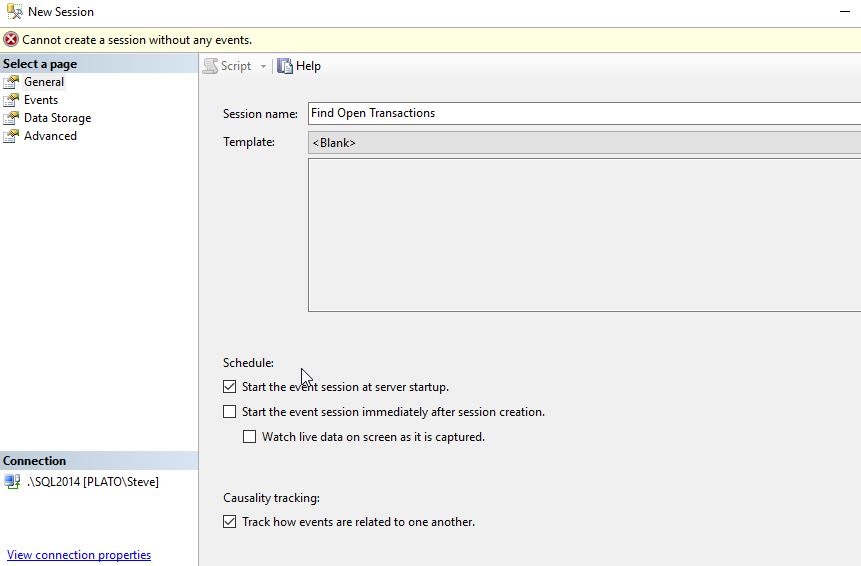
    I started with a new session:

     2016-08-08 16_46_23-SQLQuery8.sql - (local)_SQL2014.Sandbox (PLATO_Steve (66))_ - Microsoft SQL Serv

    I gave this a simple, descriptive name, and selected to start on server startup, and also to track causality. My understanding is that since I want to pair up events, I’ll need this. I might be wrong, as I’m certainly not an XE person, but let’s see.

    2016-08-08 16_46_55-New Session

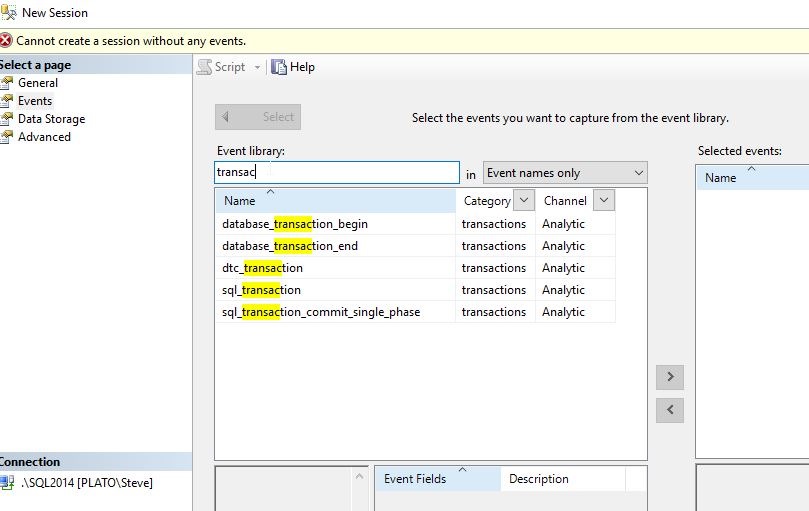
    Now we need events. Let’s use the Search, as Erin mentioned, to find those events with “transac” in them. This screen alone is worth leaving Profiler and Trace.

    2016-08-08 16_48_36-New Session

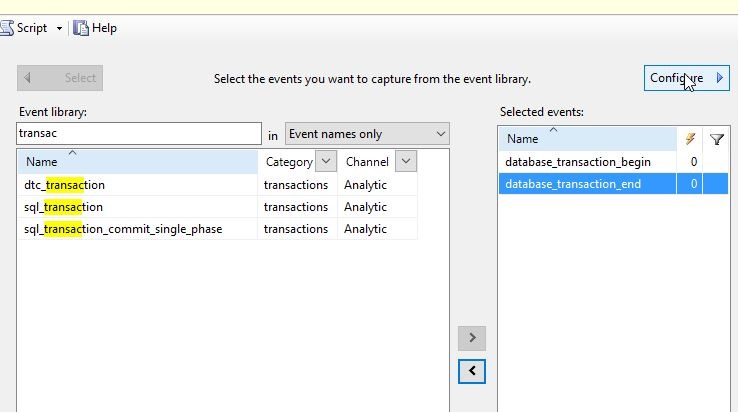
    As you can see below, I’ll add these events and then click “Configure” in the upper right.

    2016-08-08 16_49_44-New Session

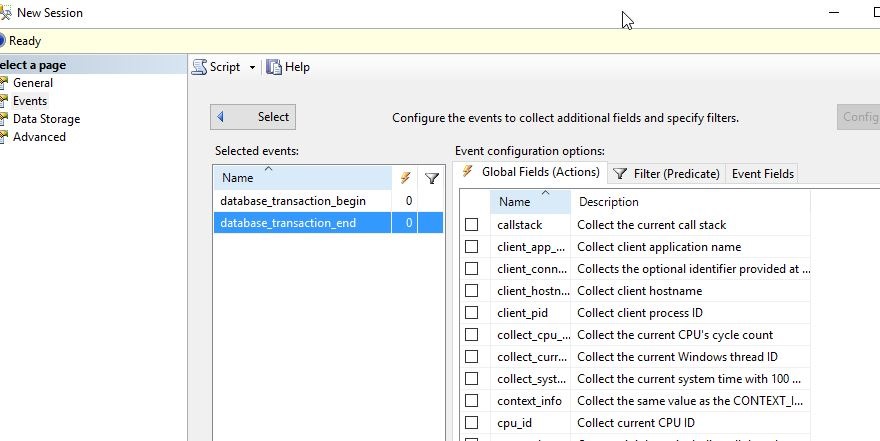
    This slides the pane over and I can see my Actions, Predicates, and Fields.

    2016-08-08 16_50_41-New Session

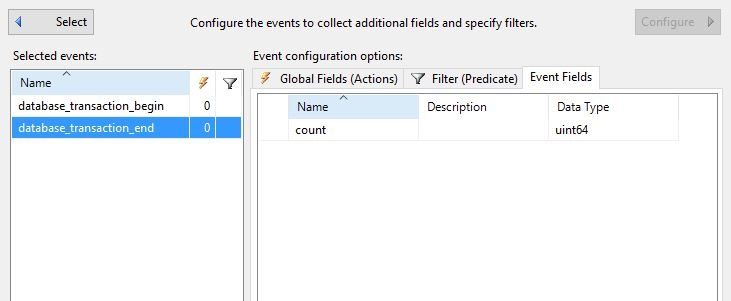
    As Erin did, I want to start with the Event Fields. Let’s see what’s available.

    2016-08-08 16_51_08-New Session

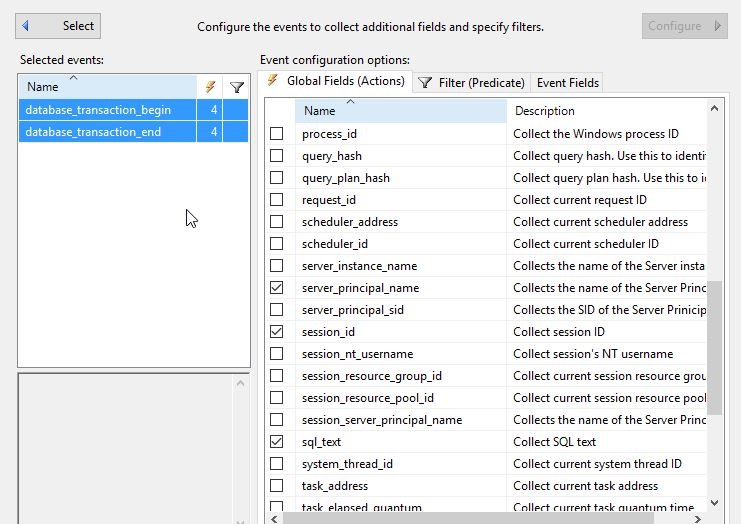
    Essentially nada. This won’t help. So let’s go to the Actions, which I know is something I want to avoid, and get a few fields. I’ll select both events and click a few items that seem useful.

    2016-08-08 16_51_46-New Session

    I’ll want to compare the events based on the session and database, to find those items that have a begin, but no end.

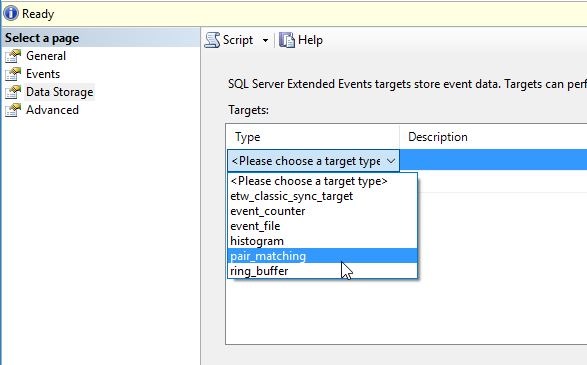
    Let’s now match. In the Data Storage pane, I’ll pick the pair matching target.

    2016-08-08 16_53_32-New Session

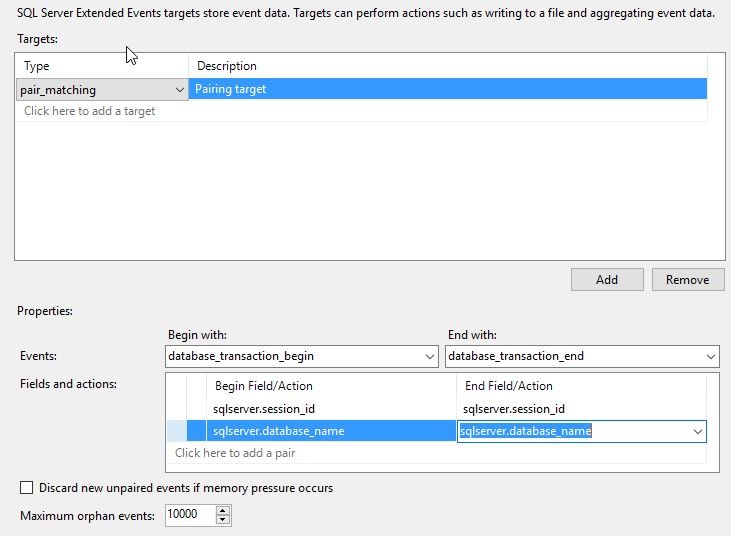
    Once I pick this target, I need to pick the events I use in my matching, along with the fields. I’ll do that here. I’m going to match the begin with the end on session and database. Session might be enough, but let’s go ahead and try to separate out those sessions that might do something silly in two databases.

    2016-08-08 16_54_25-New Session

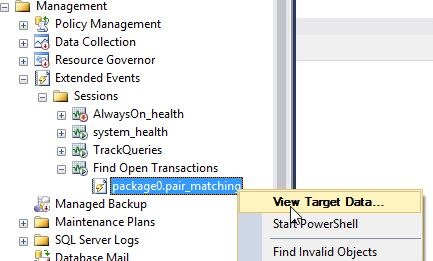
    That’s it for me. I’ll click OK and then start the session. Once I do that, I see the session and the target, which I can view data for.

    2016-08-08 16_55_53-SQLQuery8.sql - (local)_SQL2014.Sandbox (PLATO_Steve (66))_ - Microsoft SQL Serv

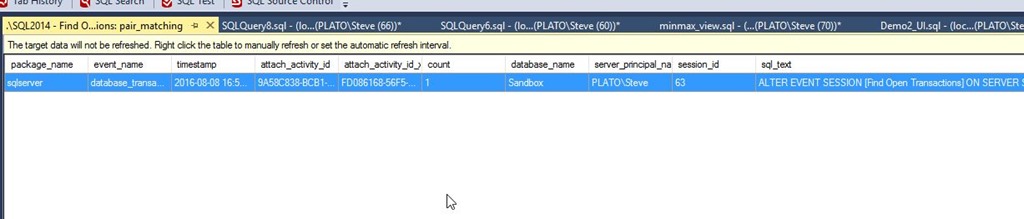
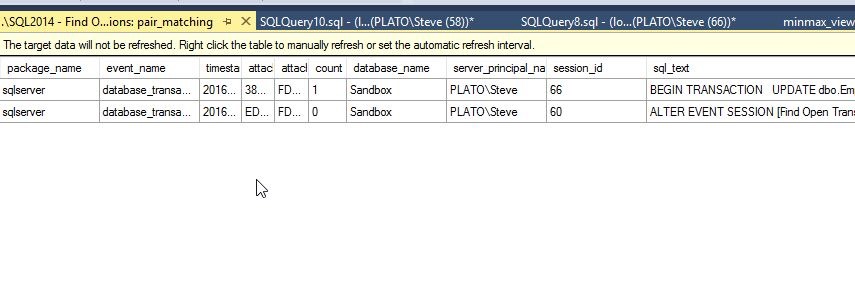
    I see the ALTER EVENT item, which I’m guessing is the start of a transaction inside SQL Server. Note this data isn’t refreshed by default, so I’ll need to right click and do that.

    2016-08-08 16_56_37-._SQL2014 - Find Open Transactions_ pair_matching - Microsoft SQL Server Managem

    Now let’s make a transaction. I’ll run this:

    2016-08-08 17_07_21-SQLQuery8.sql - (local)_SQL2014.Sandbox (PLATO_Steve (66))_ - Microsoft SQL Serv

    Once I do this, I have an open transaction. My session id is 60 for this transaction. If I refresh my data, I see the item.

    2016-08-08 17_09_31-._SQL2014 - Find Open Transactions_ pair_matching - Microsoft SQL Server Managem

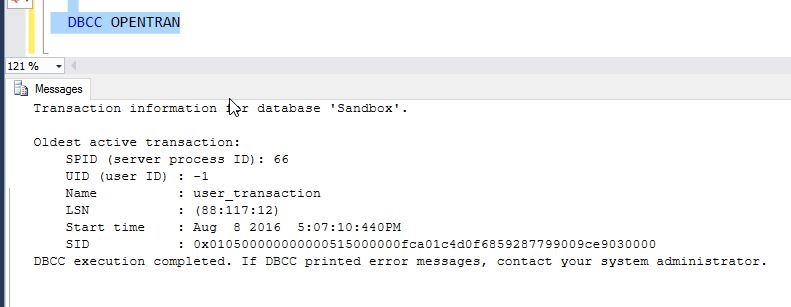
    I can also see the open transaction.

    2016-08-08 17_07_32-SQLQuery8.sql - (local)_SQL2014.Sandbox (PLATO_Steve (66))_ - Microsoft SQL Serv

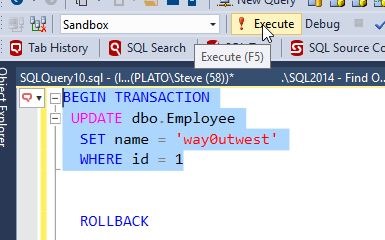
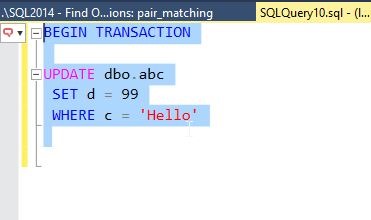
    Let’s try another one. I’ll start another new transaction, this time for session id = 58.

    2016-08-08 17_10_45-SQLQuery10.sql - (local)_SQL2014.Sandbox (PLATO_Steve (58))_ - Microsoft SQL Ser

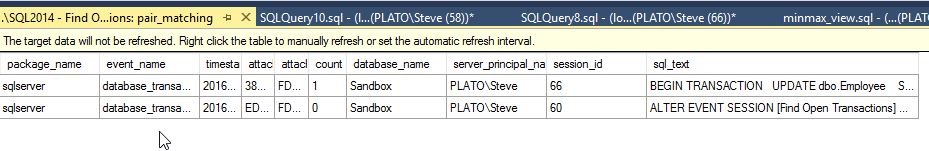
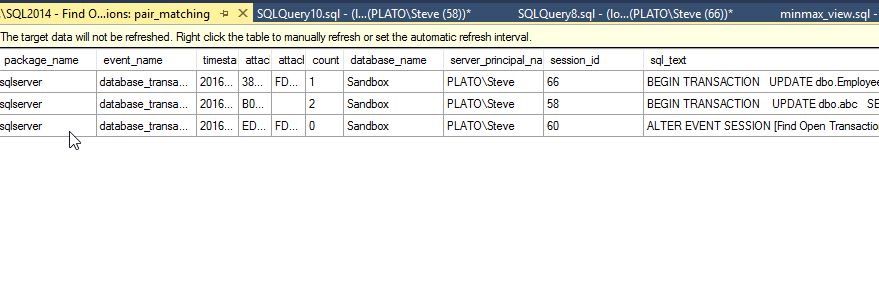
    Sure enough, I see another open transaction. 

    2016-08-08 17_11_13-._SQL2014 - Find Open Transactions_ pair_matching - Microsoft SQL Server Managem

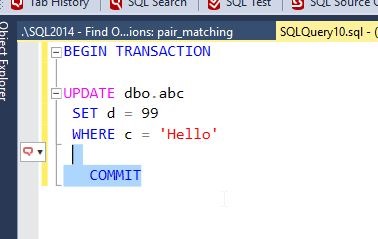
    Now let’s commit the second transaction, the UPDATE dbo.abc.

    2016-08-08 17_11_48-SQLQuery10.sql - (local)_SQL2014.Sandbox (PLATO_Steve (58))_ - Microsoft SQL Ser

    My transaction goes away from the pair match.

    2016-08-08 17_12_00-._SQL2014 - Find Open Transactions_ pair_matching - Microsoft SQL Server Managem

    The Results

    The third part of the invitation was to write this. I covered what I did, and some of what I learned. I’ll add a bit more here.

    I certainly was clumsy working with XE, and despite working my way through the course, I realize I have a lot of learning to do in order to become more familiar with how to use XE. While I got a basic session going, depending on when I started it and what I was experimenting with, I sometimes found myself with events that never went away, such as a commit or rollback with no corresponding opening transaction.

    This was a good challenge, and it forced me to work through a bit more than I might have done this past week, given a busy schedule. However, I’m glad it did, and I might challenge any of you writing about this in the future for your own T-SQL Tuesday #81 post to limit yourself to a week and force yourself to learn and try something.

  • SQL Saturday and the Alamo

    I’ll be traveling this week to SQL Saturday #550 in San Antonio. This is my first time traveling to this part of Texas and I’m looking forward to getting a few minutes to swing by The Alamo and see a piece of history. The Riverwalk is also on my list as a place to hopefully enjoy a margarita or two.

    This is a combination trip for me, going early to see Tim Mitchell’s pre-con on Building Better SSIS Packages. I don’t do a lot with SSIS, but training time can be hard to come by. I always learn things at one hour sessions, but I’m hoping to get a chance to do a little more in depth work with Tim on Friday. He’s a great teacher, and I’m always appreciative of software devleopment techniques that try to build reusable, scalable skills for developers.

    Saturday will be a great event, the first one in San Antonio. I will be delivering my Branding Yourself for a Dream Job talk at 9:45. However, around that, there’s quite a list of sessions covering all aspects of SQL Server. BI, Performance, HA, even Linux.

    If you can make the trip to San Antonio, come on down, learn some SQL Server, meet fellow data professionals, and get inspired to try something new in SQL Server the following week.

  • Making Complex Table Changes

    Tables are a problem for anyone trying to grow and modify software. Views, stored procedures, functions, all of these objects are easy to modify, but when we start to deal with actual data, where we need to maintain state, we start to have issues with concurrency, performance, and more. These challenges can really stress the developers and administrators that work on large tables.

    As an evangelist for Redgate Software, I talk with a lot of customers and potential customers about their database work. Almost all of the problems and difficulties they experience revolve around tables, especially as we seek to deploy changes with little to no downtime. In fact, one of the hardest problems Redgate has been trying to solve is how to make these changes easier for DBAs and developers. It’s hard, especially because the impact becomes greater as the table gets larger.

    I ran across a post from Michael J Swart that looked at ways to alter a large table while keeping the data available for querying. It’s the start of a nice series that examines a technique, looking at the pros and cons. This seems complex, but there isn’t any magic to altering tables and ensuring the system continues to run. There really are a limited number of ways to perform alterations to tables.

    These are hard changes, and need to take place across time, meaning you won’t get this all done in an hour, sitting at your desktop. Some of these changes might take hours, or even take place across days. Really complex changes that must synchronize with an application (or many), might actually sit in some limbo state where triggers keep data in sync for months.

    There are different ways to make these changes, but how do you test which one works best? How do you ensure the correct steps run in the right order? You want an automated process that can be repeated. If I need to restore and retry my idea, I won’t want to depend on humans to execute the correct steps in the correct order. That’s a recipe for disaster. Especially when repeat the deployment to production.

    As the changes you make to your systems become more complex, with multiple steps, and the repercussions for problems grow, I think it’s important that you have an automated process. A human might need to kick off parts, but really an entire batch of items should run automatically, in a reliable, repeatable fashion, without requiring a human to execute each step. This doesn’t mean some things are too difficult to completely automate, or that human’s aren’t involved (maybe for smoke test) but people should be involved as little as possible.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.8MB) podcast or subscribe to the feed at iTunes and Mevio .