Author: way0utwest

  • Stretch Pricing

    I have to admit that I was really excited about the Stretch Database feature in SQL Server 2016. This will automatically archive older data away from your database, but let the query optimizer go get the data if needed. That’s outstanding. That’s the type of archive solution I’ve struggled to implement in the past, finding the effort complex and requiring application change or active DBA management. Often I’ve found that only 10-20% of the data in my database was accessed often, and the rest relatively rarely. Maybe old data was queried every day, but still somewhat rarely compared to a small percentage of the data.

    Then the pricing for Stretch was released, and I think it’s definitely aimed at the Enterprise. If you stretch a sales database, say a 100GB database and want to move 60GB of that data away, you’re going to pay at least US$930/month for the compute at the lowest performance level. Regardless of whether anyone queries the data. If you want better performance, you can run up in roughly multiples of that amount ($1860, $2790, $3720, etc), however, that’s just for compute. If you add in storage, and you must, it’s a minor cost even 1TB, but still, having a $1k bill for access to archive data, especially when you might find people make the mistakes and do query cold(er) data might seem like a lot for a small or medium sized business (SMB). If you have to get better performance, you’ll pay more per month.

    I’m not the only one that doesn’t love the pricing of stretch. It seems to me that the pricing very much favors the Microsoft share price more than the value of my own business. Perhaps this makes more sense at an enterprise level where storage costs can be high, and separating out older data could result in savings. However for smaller companies, if you’re running a SQL Server, even a 1TB (or 10TB) database, is the addition of another 1TB of storage going to cost much? I’m not sure it does.

    Of course, there are other factors. Less data should mean much better performance from your local system. With some tuning of the feature, I would bet that plenty of people might be able to get 90% of their queries satisfied by on premise resources, when they have a substantial amount of older data stored in Azure. That’s not something I can easily do in my own archival system, or with the addition or more storage.

    What I’d really like to see is a stretch to another SQL Server feature added. I’m guessing we’ll see that, likely in SQL Server 20,18 as I don’t think this would be hard to implement. However since this looks like a cash cow for MS, I bet when we get stretch to an on premise SQL Server, this will be an Enterprise only feature, once again, ignoring SMB needs and desires. Maybe in 2020 or 2022 we’ll be able to stretch on premise at a reasonable cost.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • A Better (Free) Search in SSMS

    A few years back, Redgate Software released SQL Search. This was an internal project that became a free product we released. Free as in beer, so go get it.

    Why use SQL Search?

    There are a number of good reasons, which Ike Ellis of Crafting Bytes does a good job of highlighting in a short video. In short, SQL Search is much more robust in helping you track down objects.

    I’m sure plenty of you are like me. You think you know where most of the objects live in a database. I’ll use the SQLServerCentral database as an example. If I want to look in the forums for how to modify profiles, I know there’s an InstantASP_Users table. I can quickly go to the Object Explorer, hit Databases, go to SQLServerCentral_Forums, hit tables, and pick the table. I can get the designer, a list of columns, etc. This is a familiar way of working with databases.

    2016-06-13 11_49_33-Start

    However, I’d be lying if I said I knew all of the objects that referenced that table. Especially stored procedures. Even if I work with a database every day, and I have a great memory, I don’t always keep every reference in mind.

    I still follow that process (too often), but I’ve learned there’s a better way of working with a database.

    SQL Search.

    If I type “asp_user” in the search dialog, I get this:

    2016-06-13 12_01_32-Photos

    Now I can see lots of objects, including those in other databases. If I know I want tables, I can easily filter.

    2016-06-13 12_01_47-Photos

    However I don’t just get the names, I can get some details:

    2016-06-13 12_01_55-Movies & TV

    The more I move to search, the more I start to realize that the Object Explorer is quite slow, and inefficient. I’d be better served by just going to search right away. At least, a search that gives me plenty of useful information,

    So download SQL Search today and see how it can make development easier in large databases, and check out Ike’s video.

  • It’s 2016 RLS for T-SQL Tuesday #79

    tsqltuesdayIt’s T-SQL Tuesday time again. I missed last month, being busy with travel, though I should go ahead and write that post. Maybe that will be next week’s task.

    In this case, Michael J Swart is hosting this month’s blog party and he asks us to write about something to do with SQL Server 2016. Read the rules at his invitation.

    Row Level Security

    I’ve wanted this feature to be easy for a long time. In fact, I’ve implemented a similar system a few times in different applications, but it’s been a cumbersome feature to meet, plus each developer needs to understand how the system works for it to work well. Even in the case where we once used views to hide our RLS, it was a performance issue.

    Microsoft has made things easier with their Row Level Security feature. This was actually released in Azure in 2015, but it’s now available in SQL Server 2016 for every on premise installation as well.

    Essentially for each row, there is some data value that is checked to determine if a user has access. This doesn’t mean a join. This doesn’t mean you write a lot of code. The implementation is simple, and straightforward, and I like it.

    Security Predicate Functions

    The one piece of code you need is an inline table valued function (iTVF) that returns a 1 for the rows that a user should see. You need to have some way to match up a row with a user, and that can be tricky, but if you identify a row, even in another table, you can use it.

    For example, I have this table.

    CREATE TABLE OrderHeader
      (
        OrderID INT IDENTITY(1, 1)
                    PRIMARY KEY
      , Orderdate DATETIME2(3)
      , CustomerID INT
      , OrderTotal NUMERIC(12, 4)
      , OrderComplete TINYINT
      , SalesPersonID INT
      );
    GO

    There’s nothing in this table that really helps me identify a user that is logged into the database. However, I do have a mapping in my SalesPeople table.

    CREATE TABLE SalesPeople
      (
        SalesPersonID INT IDENTITY(1, 1)
                          PRIMARY KEY
      , SalesFirstName VARCHAR(200)
      , SalesLastName VARCHAR(200)
      , username VARCHAR(100)
      , IsManager BIT
      );

    Granted, this could mean some change of code, but perhaps you can somehow use a user name in tables to query AD or other directory and map this to a user name.

    Once I have that mapping, I’m going to create a function. My function will actually look at the SalesPeople table, and map the parameter passed into the function to the value in the table.

    CREATE FUNCTION dbo.RLS_SalesPerson_OrderCheck ( @salespersonid INT )
    RETURNS TABLE
        WITH SCHEMABINDING
    AS
    RETURN
        SELECT
                1 AS [RLS_SalesPerson_OrderCheck_Result]
            FROM
                dbo.SalesPeople sp
            WHERE
                (
                  @salespersonid = sp.SalesPersonID
                  OR sp.IsManager = 1
                )
                AND USER_NAME() = sp.username;
    go

    In the function, I look at the USER_NAME() function and compare that to a value in the table. This is in addition to checking the SalespersonID column.

    I can use a Security Policy to bind this function to my OrderHeader table as shown here:

    CREATE SECURITY POLICY dbo.RLS_SalesPeople_Orders_Policy
      ADD FILTER PREDICATE dbo.RLS_SalesPerson_OrderCheck(salespersonid)
      ON dbo.OrderHeader;

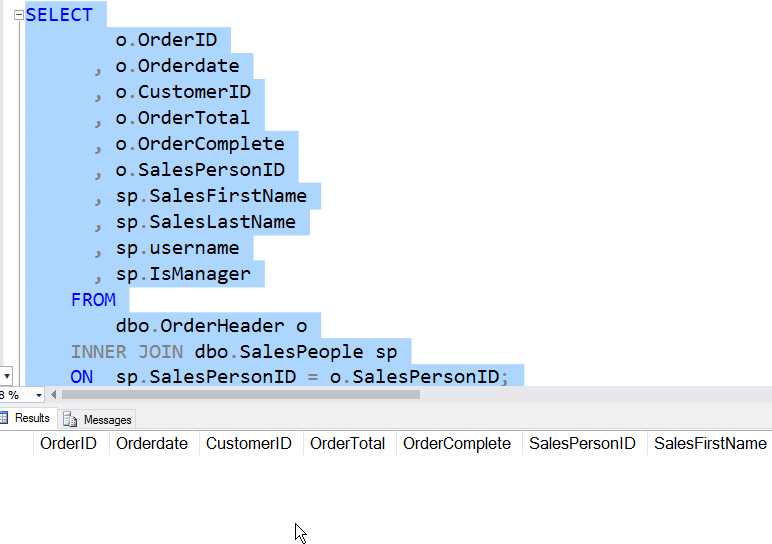
    This sets the function, passing in a column from the OrderHeader table, which is the column I want evaluated in the function.When I now query the OrderHeader table, I get this:

    2016-06-13 11_42_16-Photos

    There is data in the table. However, I don’t get rights by default, even as dbo. My USER_NAME() doesn’t match anything in the table, therefore no SalesPersonID matches. However, for other users, it works.

    2016-06-13 11_42_32-Photos

    There is a lot more to the RLS feature, but I think it’s pretty cool and it’s something that will be highly used in many applications moving forward, especially those multi-tenant systems.

    Go ahead, get the free Developer Edition and play around with RLS.

  • We Manage Algorithms

    “Every business is an algorithmic business.”

    That was a phrase that Microsoft’s Joseph Sirosh used in a keynote at SQL Nexus, talking about the future of software and data. Rather than managing data, many of us will move to manage algorithms, which will determine how data is interpreted, used, processed, and potentially returned to users as information. There are starting to be too many sources of data, too much data itself, being generated at too quick a rate, to the point where algorithms become more important than the actual data in examining, grading, interpreting, filtering, and more.

    This is exciting on one hand, with new opportunities for those that can develop, choose, write, tune, or enhance algorithms. I can easily see greater influence from both developers and DBAs as we work to better manage the floods of data. Especially with 50 billion sensors, IoT devices, and more that are predicted to be online in the 5 years. That’s potentially a tremendous amount of data being generated.

    On the other hand, this is a bit scary as separating good data from bad in the ocean of bits, and choosing helpful rather than hurtful algorithms might create lots of stress, and perhaps even fewer opportunities if few algortihms are reused. This also means we will need algorithms that can help us determine if data is actually good enough to use. After all, in the deluge, there will be bad data, that potentially needs to be excluded from queries. Will software developers become more important than DBAs as we end up with more unstructured data stores, data lakes, or other constructs that might require less administration?

    I’m not sure how things will change, but it will be an interesting world the next few years as we work with larger and larger, more diverse sets of data in our organizations.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.3MB) podcast or subscribe to the feed at iTunes and LibSyn.