Author: way0utwest

  • How Often Does Production Drift?

    One of the new products that Red Gate Software is working on is SQL Lighthouse, which is designed to track and alert you on “database drift“, which are the changes in your schema. I hadn’t really heard the concept in the past, though I’ve found there are a few people using the term to describe the changes being made to production that aren’t inline with the development project that created (and updates) the database.

    Vendors that sell products backed by a SQL Server database, like Microsoft Dynamics, often consider database drift to be a violation of their EULA. When a customer changes the database, even by just adding indexes, it causes them support costs, though arguably those costs are lower than if no indexes were ever added by enterprising DBAs.

    However this also happens in databases built by companies. It seems there’s no shortage of “quick fixes” in production, in addition to the “improvements” that DBAs and others seem to make to their live databases in order to solve some short term issue. I know there’s a need for this, and even seen recommendations to ensure production differs from development schemas. However I haven’t had many issues with this in the past and I’ve tried to prevent any drift.

    Maybe because I’m a controlling DBA, or maybe because I’ve been lucky. In either case, while I’ve had to implement hot fixes and changes in production, it’s been rare. Most of the time I’ve been able to backfill these changes in development (and test) environments, or delay the fix until it could be tested.

    However I’m sure there’s a need for a way to manage drift, and detect it as the number of databases you manage grows, so I’m excited by SQL Lighthouse and hope it helps DBAs avoid those late night phone calls by being aware of what’s changing in their systems.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.2MB) podcast or subscribe to the feed at iTunes and LibSyn.
  • Off

    I’m off for a few days. Actually, today and most of next week. I completed my achievement, getting all my vacation scheduled, and this one of those days. I also have most of next week off, so I’ll be taking time with family over the Thanksgiving holiday to relax a bit, and likely, work on my latest woodworking project.

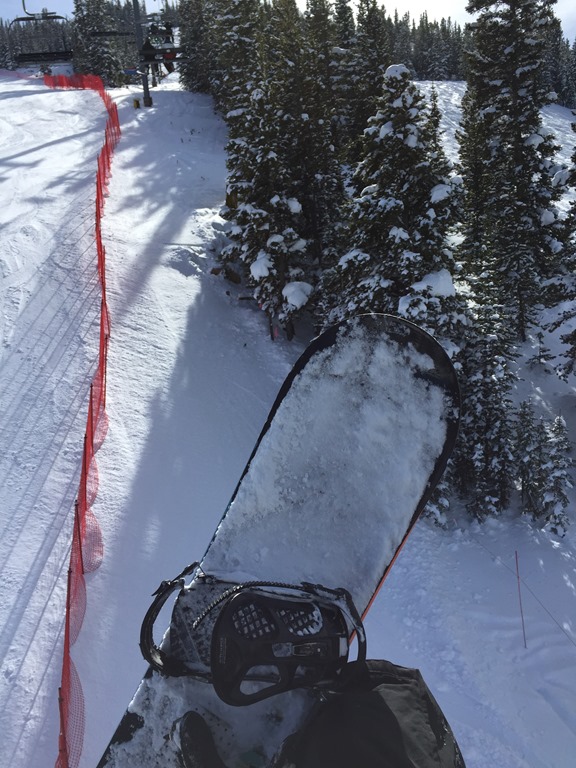
    The blog will be a bit hit and miss as I work around time off. Apart from next week, and the week of Christmas, I’ve mostly got some random days each week, 1-2, where I hope to have views like this:

    Photo Nov 18, 12 45 28 PM

  • Real World T-SQL Tricks

    I’ve been playing more with T-SQL this year, doing some testing and development in various places. I’ve been trying to improve my skills, and keeping up with the advancements the language has made in the last few versions. Like many of you, if I haven’t had the need for a particular feature, or the chance to implement it, I haven’t done much with it.

    I think that’s the case with many people, who may not catch all the changes in T-SQL with new versions, especially if you upgrade after a year or two and don’t often do more than refactor the existing code you have in production. In the spirit of improving skills, and also learning more about how others work in this profession, I want to ask you:

    Have you used any of these T-SQL items in production code?

    • APPLY
    • THROW
    • LAG/LEAD
    • a tally table
    • symmetric or asymmetric keys
    • TRY..CONVERT
    • CONCAT/FORMAT
    • IIF
    • SEQUENCE

    Some of these have been around for a long time, some are new in SQL Server 2012, but they are all improvements beyond the core T-SQL language that I see so many people posting and asking questions about.

    Let us know this week if you’ve used any of these constructs, and if you can, how they solve a problem that you struggled with in the past, or maybe how these new features have improved performance or sped up code development.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.0MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • Encryption in Colorado Springs – Encrypting in the Application?

    Last night was my annual presentation at the Colorado Springs SQL Server User Group. I try to make sure I get down there at least once a year, and it’s been only once a year for the last few years. Far too busy, and I’m sorry for that, but I am glad I get invited to go down.

    I presented The Encryption Primer, and there were a few interesting questions asked. Always good to see people debating and asking questions.

    One interesting one from a developer – If I can perform encryption in the application, why would I do use something like TDE or column level encryption?

    To me, I prefer to do encryption as close to the source as possible. If I can do the encryption in the application front end, I’d do it there. It reduces the chances of having the data accidentally disclosed. I don’t have to worry about having data read across the wire, or in a backup tape, or anywhere else.

    However that takes time and effort. Developers are expensive, and they have to write good, solid, secure code in the application. They also have to write this encryption code in every application that accesses the database (reports, ETL, etc.).

    Something like TDE is much easier to setup and use. Column level encryption, while still coding, is centralized.

    It’s a balance, and one you need to consider carefully and thoroughly. It also helps to debate and discuss the decisions about what you protect, why, and what it costs.