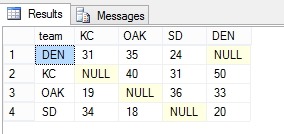
I’ve been working on some skills, trying to grow some of my T-SQL, and started to mess with the PIVOT operator. This is a T-SQL construct that helps you turn row data into column data. It’s part of the SELECT query, and comes about in the FROM clause. There is an article on MSDN to help you understand this.
Note: Performance of PIVOT can be challenging. Jeff Moden has a great piece on Cross Tabs and PIVOT. It is worth a read to understand the limitations and issues with PIVOT.
Setup
I’ve got some sample data I’ve put together. In this case, I have a set of data from the 2013 NFL season, with the scores for the Denver Broncos.
CREATE TABLE Scores
(
Team varchar(3)
, Opponent varchar(3)
, gamedate datetime
, TeamScore int
, Oppscore int
);
go

INSERT INTO scores (team, opponent, gamedate, teamscore, oppscore)
values
    ( 'DEN', 'BAL', '2013-9-5', 49, 27)
,   ( 'DEN', 'NYG', '2013-9-15', 41, 23)
,   ( 'DEN', 'OAK', '2013-9-23', 37, 21)
,   ( 'DEN', 'PHI', '2013-9-29', 52, 20)
,   ( 'DEN', 'DAL', '2013-10-6', 51, 48)
,   ( 'DEN', 'JAX', '2013-10-13', 35, 19)
,   ( 'DEN', 'IND', '2013-10-20', 33, 39)
,   ( 'DEN', 'WAS', '2013-10-27', 45, 21)
,   ( 'DEN', 'SD', '2013-11-10', 28, 20)
,   ( 'DEN', 'KC', '2013-11-17', 27, 17)
,   ( 'DEN', 'NE', '2013-11-24', 31, 34)
,   ( 'DEN', 'KC', '2013-12-1', 35, 28)
,   ( 'DEN', 'TEN', '2013-12-8', 51, 28)
,   ( 'DEN', 'SD', '2013-12-12', 20, 27)
,   ( 'DEN', 'HOU', '2013-12-22', 37, 13)
,   ( 'DEN', 'OAK', '2013-12-29', 34, 14)
;
go
The Problem
I want to get an average score for the Broncos for each of their opponents. They had 13 opponents in 16 games, with 3 teams being played twice. However, I want to see the data sideways, but I’m only going to show the scores for the opponents with multiple games. In this case, I know the teams are “KC”, “OAK’, and “SD”.
In other words, I want to see:
Team KC OAK SD
DEN X Y Z
I want the real averages for the games in question. I could include the other teams, but let’s leave this alone.
Note that in my results I’ve limited things to Denver. I forgot to include the WHERE clause when I rewrote this post, but I had limited the winning team to DEN.
The Query
There are a couple parts to the query. First, there’s the column list, in this case, it’s a SELECT *. We’ll fix this as I dislike the asterisk, but let’s leave that for now. That means we have:
select
    *
Now, we need a FROM clause. The first part of the FROM clause will be my source data. This is a normal select, in this case, we’ have:
select
          team
        , opponent
        , teamscore
        from scores
          results
We need to embed this in parenthesis, so that gives us this:
select
    *
  from
    ( select
          team
        , opponent
        , teamscore
        from scores
          results
    ) as rawdata
So far this is a normal query. Not it’s time to PIVOT things. First we add a PIVOT clause to the end of the statement. The outline looks like this (with our query):
select * from ( select team , opponent , teamscore from scores results ) as rawdata
PIVOT
( aggregate(col) for var in ([col1], [col2], [col3]
) as pivotalias
The PIVOT clause includes one (and only one) aggregate. You choose the aggregate and a column. In my example, I’ll be averaging the scores for the teamscore column.
The next part of the clause is a pivot column, on which we are looing for data. This column must be in the select list for the first part of the query. Next we have the “IN” clause, in which we list the various values that we are moving from rows to columns.
In this case, I’m looking to move the divisional opponents to columns rather than rows. I’m pivoting on the Opponent column and looking for the AFC West opponents. Those teams are OAK, SD, and KC. That makes my query look like:
select * from ( select team , opponent , teamscore from scores results ) as rawdata
pivot
( avg(teamscore) for [Opponent] in ( [KC], [OAK], [SD] )
) as pivotresults;
This will give me these results:
team KC OAK SD
DEN 31 35 24
I have the average scores for opponents as columns, not rows.
Technically, I should include DEN as an opponent so I can actually build a proper grid. If I do that, I get:
select
    *
  from
    ( select
          team
        , opponent
        , teamscore
        from
          scores results
    ) as rawdata
  pivot
   ( avg(teamscore) for [Opponent] in ( [KC], [OAK], [SD], [DEN] )
   ) as pivotresults;
And these results.
team KC OAK SD DEN
DEN 31 35 24 NULL
Note that this gives me a NULL. I can handle that with an ISNULL, COALESCE, etc.
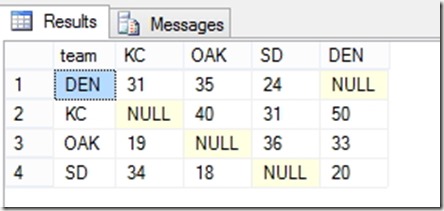
If I add more data for the other teams, then I’ll get this:
INSERT INTO scores (team, opponent, gamedate, teamscore, oppscore)
values
    ( 'KC', 'DEN', '2013-9-5', 49, 27)
,   ( 'KC', 'SD', '2013-11-24', 38, 41)
,   ( 'OAK', 'DEN', '2013-9-23', 21, 37)
,   ( 'KC', 'DEN', '2013-9-29', 52, 20)
,   ( 'KC', 'SD', '2013-12-29', 24, 27)
,   ( 'KC', 'OAK', '2013-10-13', 24, 7)
,   ( 'KC', 'OAK', '2013-12-15', 56, 31)
,   ( 'OAK', 'DEN', '2013-10-27', 45, 21)
,   ( 'OAK', 'SD', '2013-10-6', 27, 17)
,   ( 'OAK', 'SD', '2013-10-27', 45, 21)
,   ( 'OAK', 'KC', '2013-10-13', 7, 24)
,   ( 'OAK', 'KC', '2013-12-15', 31, 56)
,   ( 'SD', 'DEN', '2013-11-10', 20, 28)
,   ( 'SD', 'DEN', '2013-11-10', 20, 28)
,   ( 'SD', 'OAK', '2013-10-6', 17, 27)
,   ( 'SD', 'OAK', '2013-11-10', 20, 28)
,   ( 'SD', 'KC', '2013-11-24', 41, 38)
,   ( 'SD', 'KC', '2013-12-29', 27, 24)
;
go
And these results from the same query:
That’s pretty cool, though I’d argue that the data isn’t valuable for many people unless you’re trying to bet or analyze the performance of teams against each other.
As I mentioned at the top, this isn’t necessarily the best way to move data. Performance can be an issue, however there are people that find this to be an easier way to write code and understand what it’s doing.
I might argue that a cross tab can be just as easy to code and maintain, but you may feel the differently.