Author: way0utwest

  • Versions of Disaster

    Today’s editorial was originally released on Jan 13, 2009. It is being re-run as Steve is on vacation.

    I wrote about versioning of old software recently and how I had to restore an old version of SQL Server in response to a lawsuit. We had some challenges because the backup file that we had was from years before and we weren’t sure which version of SQL Server we needed. I forget how we finally determined which service pack was needed, perhaps we read master somehow to get a build.

    In any case, when you apply patches or change how SQL Server functions, you can change the way that code is executed or even the results that might be returned to an application. You would hope that code would break and error out rather than return different results than you expect.

    Since many of us patch servers when Service Packs come out, or when we find a hot fix we need, and we are constantly deploying and changing code, do we pay enough attention to the server version as we make these deployments? I started thinking about this after the last editorial and I think that we often take it for granted that we can easily recreate our environments.

    Consider what would happen in the event of a disaster. Suppose that one of your server instances, any particular instance, died and you had to go back to a backup of the database, would you know what version of SQL Server is needed? Do you know what version each of your instances is using right now?

    In some ways this makes me think that only installing RTM and Service Pack versions in your production environment is a good idea. It’s easier to track things if you keep all your instances within a very narrow band of versions, and the worst case would be attempting a restore on RTM, then SP1, then SP2, etc. until you hit the correct version. Imagine now if you had to work through the various builds on my build list.

    I used to think that I’d want to keep current on my patches. In one large environment, we were actually pretty good about deploying patches to hundreds of instances inside a month, so we always had a large percentage of our servers, and usually all the critical servers, at the same patch level. However if a disaster had occurred within the month, we wouldn’t necessarily have been sure of what versions were installed.

    I really don’t have a great recommendation on how to handle this other than build some automated system that tracks the current build number on a daily basis, perhaps even putting it in each database. At least then you’ll have it handy in the event of a disaster.

    Steve Jones


    The Voice of the DBA Podcasts

    Everyday Jones

    The podcast feeds are now available atsqlservercentral.mevio.comto get better bandwidth and maybe a little more exposure :). Comments are definitely appreciated and wanted, and you can get feeds from there.

    Overall RSS Feed:  or now on iTunes! 

    Today’s podcast features music by Everyday Jones. No relation, but I stumbled on to them and really like the music. Support this great duo at www.everydayjones.com.
  • Managing Data in a FileTable with T-SQL

    I wrote a post about creating a Filetable, which just covered the basics of how to build one. How do you work with the data in this table? In this post I’ll look at a few things you can do from the T-SQL side.

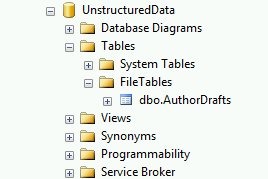
    From the last post, I had my author drafts Filetable. I can see this in the Object Explorer.

    filetable_c

    I can use the same “select data” feature from Object Explorer on a Filetable, just like any other table.

    filetable_e

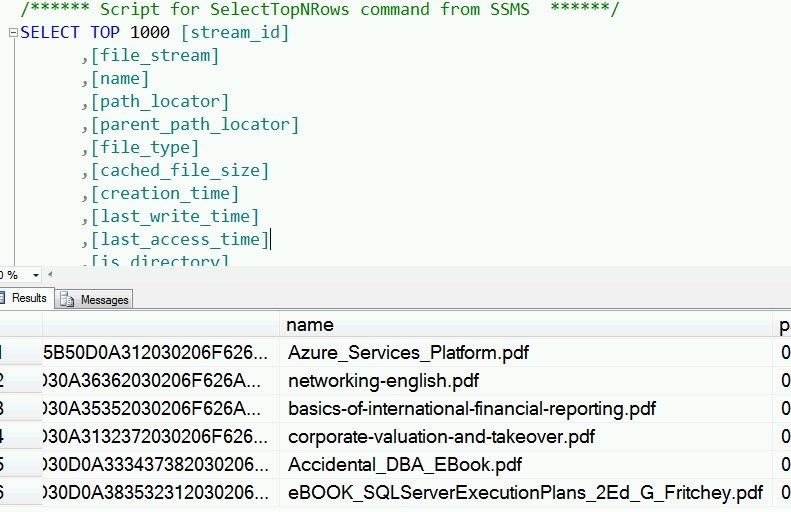
    I get the results, and as you see, I have a few rows in the table.

    filetable_f

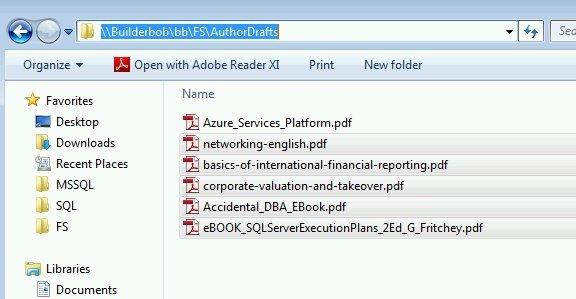
    These are actually the files I see in the share.

    filetable_d

    Inserting Data

    One of the advantages of Filetable is that you can use Explorer (and any tools that use the same Explorer APIs) to move data in and out of a table. However that doesn’t preclude you from using T-SQL.

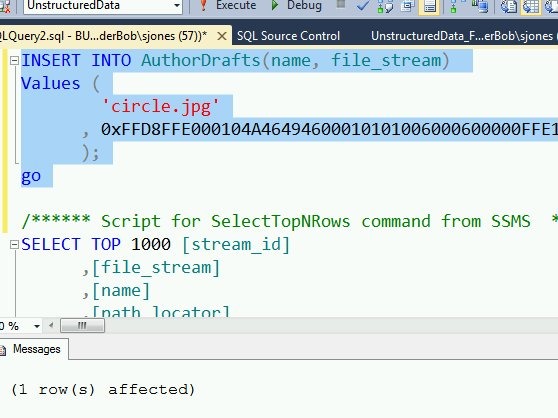
    I can use a script to insert data into the table, just as I might with Filestream.

    INSERT INTO AuthorDrafts(name, file_stream) Values ( 'circle.jpg' , 0xFFD8FFE000104A46494600010101006000600000FFE100684578696600004D4D002A000000080004011A0005000000010000003E011B0005000000010000004601280003000000010002000001310002000000120000004E00000000000000600000000100000060000000015061696E742E4E45542076332E352E313000FFDB0043000201010201010202020202020202030503030303030604040305070607070706070708090B0908080A0807070A0D0A0A0B0C0C0C0C07090E0F0D0C0E0B0C0C0CFFDB004301020202030303060303060C0807080C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0CFFC0001108000A000D03012200021101031101FFC4001F0000010501010101010100000000000000000102030405060708090A0BFFC400B5100002010303020403050504040000017D01020300041105122131410613516107227114328191A1082342B1C11552D1F02433627282090A161718191A25262728292A3435363738393A434445464748494A535455565758595A636465666768696A737475767778797A838485868788898A92939495969798999AA2A3A4A5A6A7A8A9AAB2B3B4B5B6B7B8B9BAC2C3C4C5C6C7C8C9CAD2D3D4D5D6D7D8D9DAE1E2E3E4E5E6E7E8E9EAF1F2F3F4F5F6F7F8F9FAFFC4001F0100030101010101010101010000000000000102030405060708090A0BFFC400B51100020102040403040705040400010277000102031104052131061241510761711322328108144291A1B1C109233352F0156272D10A162434E125F11718191A262728292A35363738393A434445464748494A535455565758595A636465666768696A737475767778797A82838485868788898A92939495969798999AA2A3A4A5A6A7A8A9AAB2B3B4B5B6B7B8B9BAC2C3C4C5C6C7C8C9CAD2D3D4D5D6D7D8D9DAE2E3E4E5E6E7E8E9EAF2F3F4F5F6F7F8F9FAFFDA000C03010002110311003F00E97FE0E87FF82CA7ED35FB04FED85E09F03FC2BD6A5F87BE1097408B5C4D523D2ADAF1BC41746795248CBDC4722F970848C18940399373E43478FD75FF00827CFC68F177ED17FB0FFC2AF1D78F3461A078C7C59E19B2D4F57B110B42B14F244199846DF346AFC384392A1C024E335E95E2EF87BE1FF880968BAF687A3EB6B612F9F6C2FECA3B916F27F7D3783B5BDC60D6C5007FFFD9 ); go


    As you can see, this command works fine:

    filetable_g

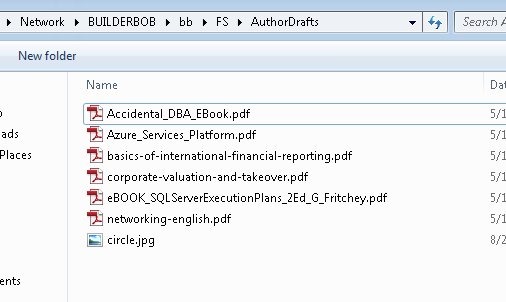
    If I then look at the share, I see my file:

    filetable_h

    Retrieving Data

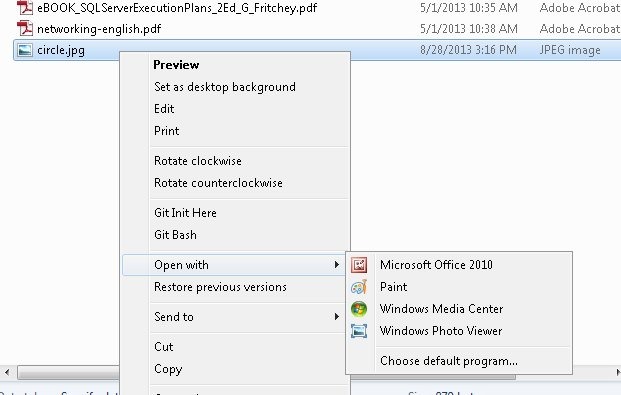
    As shown above, I can use SELECT queries to return data from a Filetable in T-SQL. However, I have a share as well, and I can cut, copy, paste, and open files from the share just as I would any other file in the file system.

    filetable_j


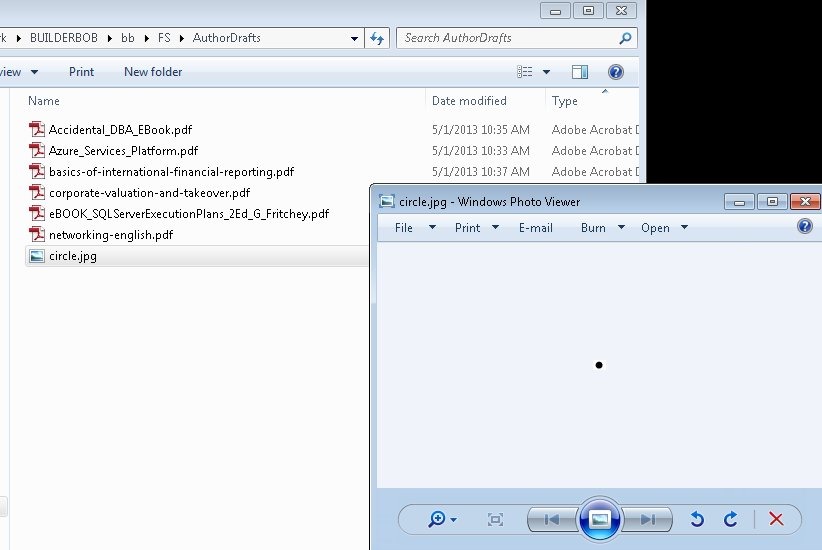
    If I open the file in Paint, I see my image:

    filetable_i

    Summary

    Working with files in a file table is easy, and while many people will use Explorer functions, you can use T-SQL as well to insert, or retrieve the data as you choose.

  • The Future of Knowledge Measurement

    This is part 3 of a 3 part series of thoughts on certification and Microsoft technologies.

    We’ll never be able to completely and accurately measure a person’s skills in technology. At least not in any cost- and time-effective way. Ultimately we want to come up with some way to weed through candidates and ensure they have a minimum aptitude for technology and some level of skill in the areas that are important to us. We want a way, with some level of confidence, to say that a person who has xx certification knows yy skills.

    In the Microsoft world we can be sure that our platforms and technologies will change at least every 2-3 years, with major or minor revisions to all parts of the product we use. We might see minor tool changes, but fundamental feature enhancements or vice versa.  However even when there are major changes, the revisions to the effective way we accomplish tasks doesn’t change much. It evolves, and I think that a core set of skills can be measured, and more importantly, scored.

    How we do that, I’m not sure. As Brent Ozar said, however, the experiment must go on. We, as an industry and group, should be finding ways to assess our community, and drive forward our profession. I’d like to think that we could build an open source framework that allows for the presentation of a situation, and the evaluation of a result. It could be a framework like tsqlt, which allows us to write tests that can be evaluated by a scoring system. By taking a script of some sort, and comparing it to a “question”, some automated measurement would be able to determine if the question was answered (or partially answered).

    Our community could easily build a bank of hundreds, if not thousands, of questions. Want to evaluate someone? Download 50 questions, drop someone in a room for an hour and see how much they get done. They might not finish, which would be a good test in and of itself. Run their answers through a scoring engine and get a report back. With tags, we could easily separate questions into a variety of packs that employers could use to test certain areas. Testing core skills, without too much worry about version specific items would allow questions to live for years. Heck, with the age of some SQL Server instances out here, I bet some companies still need SQL Server 2000 based tests.

    Ultimately I don’t think Microsoft will properly build and maintain a framework to evaluate candidates. They have too much incentive to cheat. They can fool lots of employers with easy to pass, paper diplomas and turn a profit with lots of easy certifications that sound good, but don’t really test skills. The future of measurement in technology will be like it is in many other fields, with independent bodies that provide a minimal level of educational skill for most individuals. It will consist of granular tests that measure skills, in real situations, not question and answer trivia. Some people will slip through, some will cheat, but it will work well enough when it falls out of the hands of vendors.

    Until that time, all you can do is prove your own skills, in person, through your publications, or with lots of good, valuable answers given to others.

    Steve Jones

    Video and Audio versions

    Today’s podcast features music by Everyday Jones. No relation, but I stumbled on to them and really like the music. Support this great duo at www.everydayjones.com.
    Follow Steve Jones on Twitter to find links and database related items and announcements.
    Steve Jones Windows Media Video ( 25.9MB) feed

    MP4 iPod Video ( 29.5MB) feed

    MP3 Audio ( 6.0MB) feed

    Feeds are available at iTunes and Mevio

    To submit an article, rant or editorial,
    log in to the Contribution Center

  • T-SQL Tuesday #46–The Rube Goldberg Machine

    tsqltuesdayIt’s T-SQL Tuesday time again. This is the monthly blog party where we all write on a topic. This month the topic is the Rube Goldberg Machine, as it might relate to SQL Server. You can read the invitation linked above from Rick Krueger and write your own post if you choose.

    Just be sure you post it on Tuesday, Sept 6, 2013.

    Catching the Cheaters

    A long, long time ago, in a county just to the west of here, I worked for a small company as a DBA. I had to support our production operations, as well as a team of 10-12 developers that were building our main company application. Since we were an ecommerce type company, this was an important application for the company.

    We were working in an high incremental way, probably similar to an Agile methodology, and deploying changes every week. However when I started the deployments weren’t smooth. Our developers were handling them, often bumbling them a bit, but able to fix things in an hour since they had done the development.

    Not a good separation of duties and it was becoming more of an issue as our boss wanted minutes of downtime, preferably single digits. I tracked down the main cause as a haphazard development style where changes were made to databases, instances, and IIS without much tracking going on. The IIS changes were easy: the developers had their rights removed from production and even test machines for configuration changes. However the database required a bit more work.

    As this was SQL Server 2000, we had limited ability to audit and manage rights. We also required our developers to have rights to the development machines in order to create test databases and work on importing data. We also wanted to ensure that developers moved quickly, but I needed a way to keep control of the instance.

    The first contraption I used was a simple one. I loaded the output of sp_configure into a table on the instance. I had created an administrative database that I used to track backups, and I added this information in there. I then created a job that would run sp_configure every day, compare the values to my table, and then alert me to changes. It would also update the table with the new, current values.

    This allowed me to catch various changes that developers were making when they tinkered with the server to “make it run faster”. I didn’t prevent changes, and if their changes worked, we’d deploy them to test (and eventually production), but this allowed us to document them and be aware.

    This worked well enough that I build a few more mousetraps. Catching schema changes is hard, as there isn’t good auditing in SQL Server 2000. However there is a “version” number for each object that is incremented when it’s changed. I built a similar audit/job system for our sysobjects table, but ran this every hour, catching changes. When I was alerted, which was more days than not, I’d email the team, track down the person changing things, and make a note for our current branch of work.

    This worked great in that development wasn’t slowed, but I was able to account for all development changes and slot them into the current, or future, development deployments. In a few months we reduced our deployment time from about an hour every Wed night to less than 5 minutes.

    Sometimes the mousetraps actually help the mice work better.