Category: Blog

  • The 2026 Redgate Summit in New York City

    We’re coming back to New York, which is exciting for me. I love NYC.

    The Redgate Summit 2026 – New York City comes back on May 5, 2026. You can register today and I’ll see you back in Manhattan the first week of May. Once again Bob Ward is giving the closing keynote, with me and fellow Redgater’s giving the opening one.

    We’ll have three tracks, but I’ll be hosting a session with one of our customers, so you can hear how and why Redgate Monitor helps them out and what it’s like to work with Redgate. We did this in Chicago, and there were some great questions from the audience.

    We’ve chosen customers who have had good experiences, but feel free to ask them anything about how Redgate Monitor works and how we are as a vendor. I’m certainly proud of how we partner with customers, so come get a first-hand view from a large financial services organization.

    New York City is such an amazing place, and we’ll have a drinks reception after, but there is lots to do. I’ll be bringing my wife and we’ll likely go see a Broadway or comedy show the night before. You should do the same.

    We also have a Redgate track and an AI one, so this is a great chance to see how Redgate views the world and how we’re approaching building software that helps you become more efficient inside your organization.

    Register for the Redgate Summit 2026 – New York City and I’ll see you in May.

  • Monday Monitor Tips: Intelligent Alert Thresholds

    At the recent Redgate Summit in Chicago, I demo’d (lightly) the ML based Alert thresholds in Redgate Monitor and decided to write a little about this.

    Video of this post below.

    This is part of a series of posts on Redgate Monitor. Click to see the other posts.

    Noisy Alerts

    When people used to setup Redgate Monitor in the 2015 timeframe (formerly SQL Monitor) they sometimes complained about the noisiness of the alerts. Just too many alerts were sent out.

    I felt this way about other products I’d used in the past, and our dev teams worked hard with support to enhance the produce and tune our defaults to make them less noisy. Many customers appreciate this, though a new install can take a little tuning to customize to what is helpful and actionable vs what is noise for each customer.

    A Better Way

    As the AI-LLM rise started in 2024, we started to work on different ways to use this tech in Monitor. One of our first ideas was an ML based alert that didn’t work on a set level to trigger, but rather would look at historical data and adjust the threshold for alerts. In this way you would

    We released this in v 14.0.37, so you need to be on that version or higher to use this. This is in a documentation page that describes how this work. Basically we take 14 days worth of history (the min required) and run that through a machine learning algorithm to decide what a predicted level should be. There is a pad added, and you can still set a min threshold and a duration.

    If the value exceeds the predicted value + pad, an alert is sent out.

    This is intended to reduce the amount of alerting from a system that might have a variable workload, but one that repeats and is predictable.

    Enabling Alerts

    This is available for the following alerts so far:

    • Processor (CPU) utilization
    • Server waits
    • DTU utilization
    • Query throughput

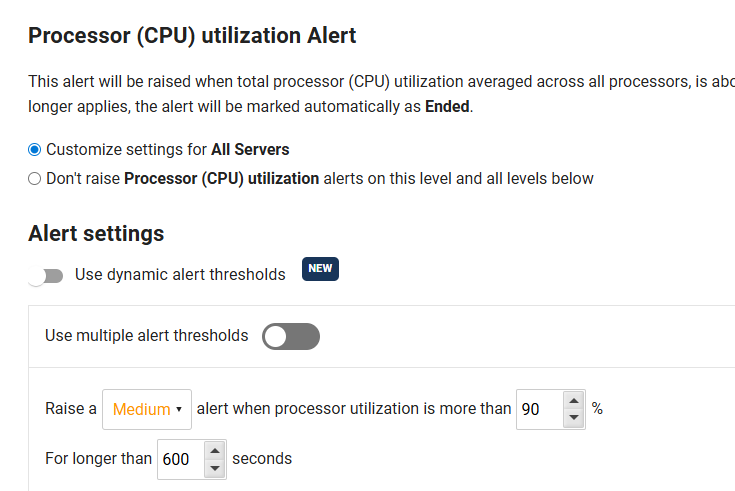
    If you go into the configuration for any of these alerts, you wil see a “dynamic alert” toggle that can be enabled. You can see this below where is says “Use dynamic alert thresholds”.

    2026-03_0120

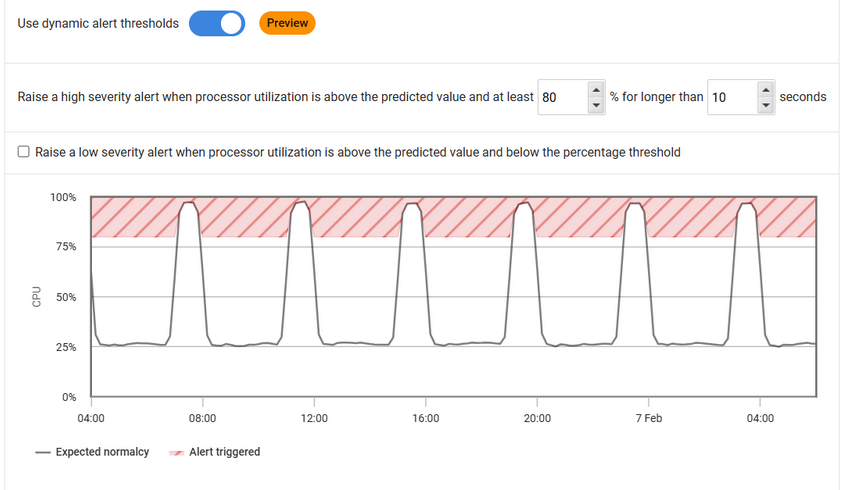
    When you do that, you can still set the levels, and as shown below (from the doc page), you get an idea of how the threshold works. The predicted values are shown as the line. If the line gets into the red areas, an alert is raised.

    2026-03_0121

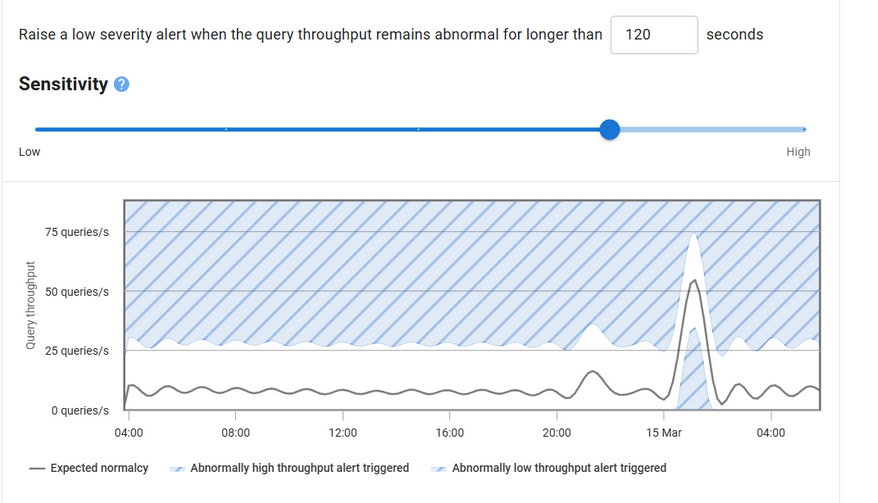
    The time limit works as shown for sensitivity. The value would have to get into the blue area, so you can see a pad around the predicted value alerts are not raised.

    2026-03_0122

    That’s it. Set the alert and if there is 14 days worth of data, each machine gets its own custom alert levels.

    Seeing the Expected Values

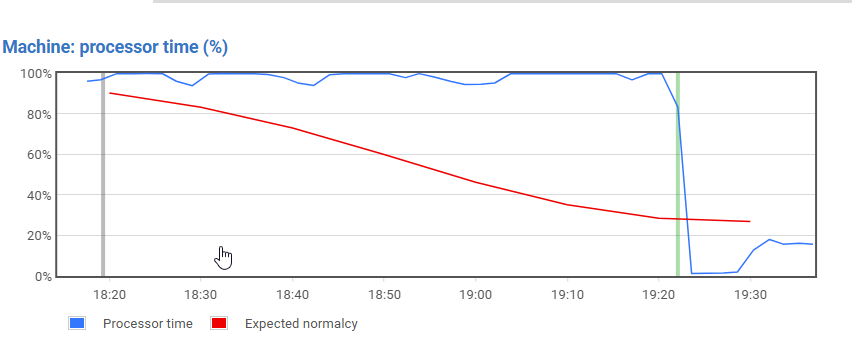
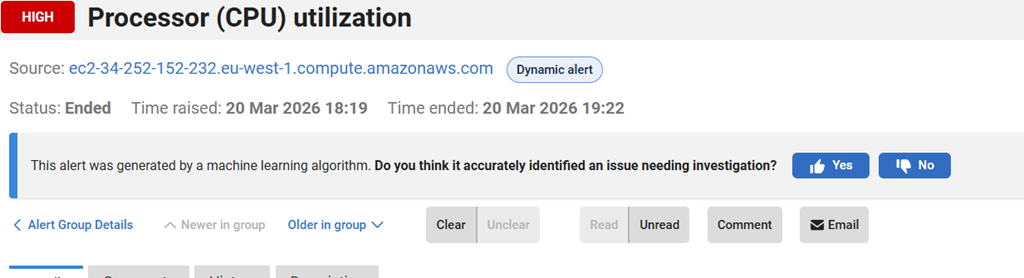
    When an alert fires, the alert includes the predicted values as well as the values recorded. You can see below in this alert that CPU was expected to decay, but hadn’t, so an alert is fired where the green line is shown.

    2026-03_0119

    At the top of the alert, you can see that this was generated by an ML process.

    2026-03_0118

    Summary

    This dynamic levels should reduce the amount of alerts you get from variable workloads, since the predictions are made based on each machine’s history. You can set some threshold and sensitivity over time, but the actual values used for alerts are predicted.

    There is also a feedback place in the alert so that you can let us know if this is helpful or not. We use feedback from you to help better tune our the ML works.

    If you have feedback in general, please let us know as we value your opinions and comments on how we shape the future of Redgate Monitor.

    Redgate Monitor is a world class monitoring solution for your database estate. Download a trial today and see how it can help you manage your estate more efficiently.

    Video Walk-through

    You can see me check this out in the video below.

  • A New Word: los vidados

    los vidados – n. the half-remembered acquaintances you knew years ago, who you might have forgotten completely if someone hadn’t happened to mention them again – friends of friends, people you once shared classes with, people you heard stories about, who you didn’t know well but who still made up the fabric of your intense little community – making you wonder who else might be out there somewhere, only just remembering that you exist.

    I have a lot of los vivados in my life. I’m old (late 50s), so high school and college were a long time ago. This is one thing I love about Facebook and Instagram is that I’ll get a memory, a glimpse of the past, of someone I knew, but not well. A post by someone closer leads me to the los vivados of my life.

    I had this recently at a Redgate event. Someone came up to me and the face was familiar, but I didn’t recognize them or their name. However, they reminded me we’d met years ago at an event and had a chat.

    I might be more memorable since I speak often, but I’m sure there are people how there who barely remember me, or remember something I’ve said/written, but don’t know the name.

    I think los vivados exist for all of us, mostly because of the faulty human memory.

    From the Dictionary of Obscure Sorrows

  • Finding and Updating Duplicate IDs: #SQLNewBlogger

    Finding duplicates was an interview question for me years ago, and I’ve never forgotten it. Recently I got asked how to easily do this and delete them, so I decided to write a couple of posts on the topic. This one looks at simple, single column IDs. The next one will look at more complex situations.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    A Simple Scenario

    Like many people, I like identity fields for primary keys. However, lots of people build tables like this:

    CREATE TABLE PurchaseOrder
    (
         poid INT IDENTITY(1, 1),
         purchaseordernumber VARCHAR(20),
         podate DATETIME,
         active INT
    )
    GO

    No nullability, and no PK constraint. People think an identity prevents duplicates. Run the query above and then the script below.

    INSERT INTO PurchaseOrder
    (
         purchaseordernumber,
         podate,
         active
    )
    VALUES
    ('PO-2023-00001', '2023-01-15 09:30:00', 1),
    ('PO-2023-00002', '2023-01-22 11:45:00', 1),
    ('PO-2023-00003', '2023-02-05 14:20:00', 1),
    ('PO-2023-00004', '2023-02-18 10:15:00', 0),
    ('PO-2023-00005', '2023-03-03 16:30:00', 1),
    ('PO-2023-00006', '2023-03-17 08:45:00', 1),
    ('PO-2023-00007', '2023-04-02 13:10:00', 0),
    ('PO-2023-00008', '2023-04-15 15:25:00', 1),
    ('PO-2023-00009', '2023-05-01 09:50:00', 1),
    ('PO-2023-00010', '2023-05-14 12:05:00', 1),
    ('PO-2023-00011', '2023-06-01 14:40:00', 0),
    ('PO-2023-00012', '2023-06-15 10:35:00', 1),
    ('PO-2023-00013', '2023-07-02 16:55:00', 1),
    ('PO-2023-00014', '2023-07-17 08:20:00', 0),
    ('PO-2023-00015', '2023-08-03 11:30:00', 1),
    ('PO-2023-00016', '2023-08-18 13:45:00', 1),
    ('PO-2023-00017', '2023-09-04 15:10:00', 1),
    ('PO-2023-00018', '2023-09-19 09:25:00', 0),
    ('PO-2023-00019', '2023-10-05 12:40:00', 1),
    ('PO-2023-00020', '2023-10-20 14:15:00', 1)
    GO
    SET IDENTITY_INSERT dbo.PurchaseOrder ON
    GO
    INSERT INTO PurchaseOrder
    ( poid,
         purchaseordernumber,
         podate,
         active
    )
    VALUES
    (19, 'PO-2023-00021', '2026-01-15 09:30:00', 1),
    (14, 'PO-2023-00022', '2026-01-22 11:45:00', 1)
    GO
    SET IDENTITY_INSERT dbo.PurchaseOrder OFF
    GO

    Now if we select all the rows from this table, we might think things are fine. After all, all the purchaseordernumber fields are unique.

    Checking Duplicates

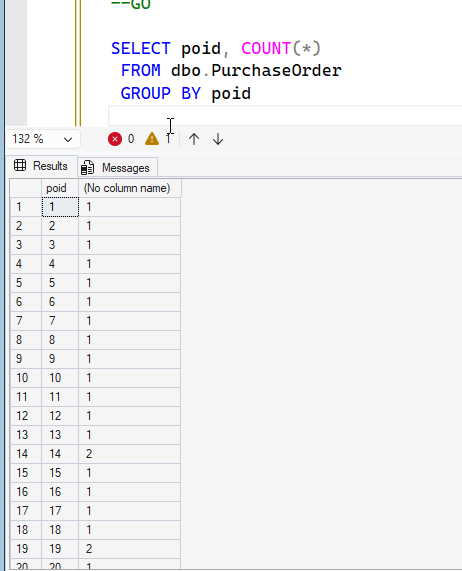
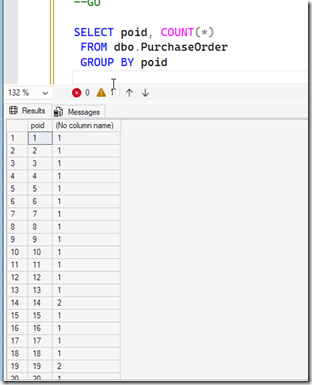
    I’ll run this query. Notice I use a GROUP BY on the poid to list these together with a count. In the image, we see some counts that are greater than 1, which indicates a duplicate. We are grouping, or putting all the rows with the same value together.
    2026-02_0139

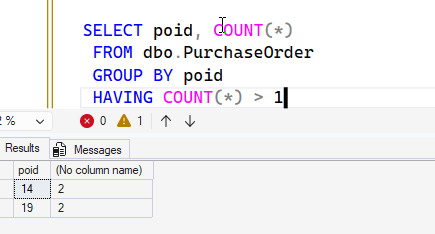
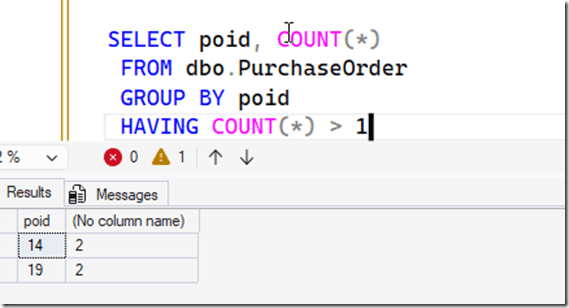
    I often will add a HAVING clause to this, which lets me filter the grouped items. When I do that, I just see two items.
    2026-02_0140

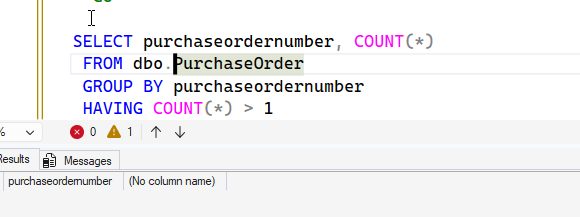
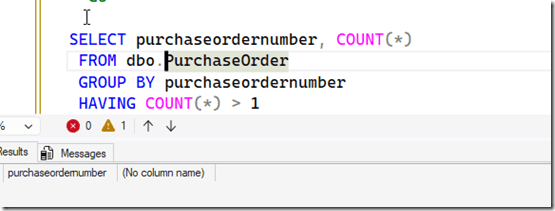
    Notice if I change this to purchaseordernumber, I don’t get duplicates. This is because those are unique.
    2026-02_0142

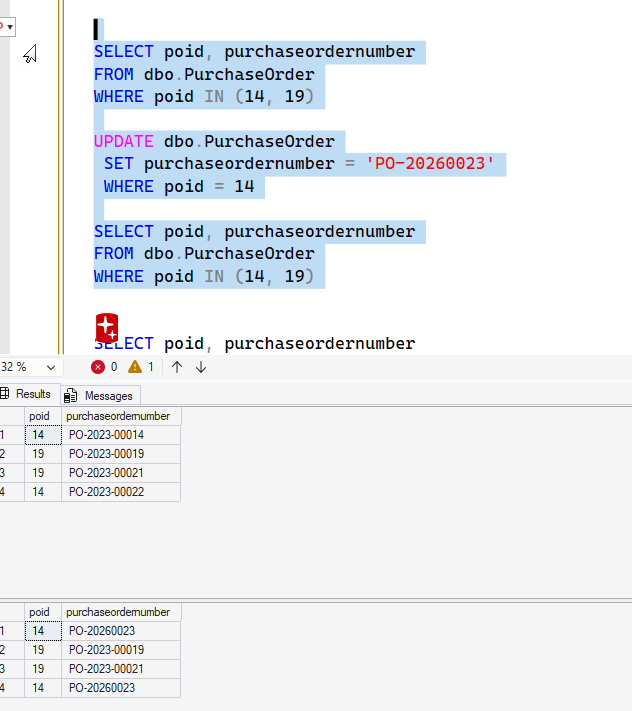
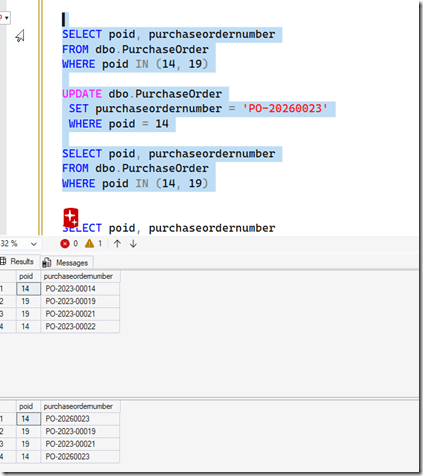
    However, a lot of people often build software that edits using the underlying key, so they can edit the PO number. Let’s do that. I’ll change the PO number for id 19. First we’ll get the current values, and then re-query.

    If we look below, we see separate purchase order numbers, but when we try to update one of them, we get two changed. Because we have duplicate hidden surrogate ID keys.
    2026-02_0143

    We want to fix this, so what can we do?

    What we want to do is find the duplicate 14s and 19s (and others) and change them.

    Fixing the Issue

    While trying to fix this, I realized that one can’t update an identity field. That actually makes the fix really, really simple.

    Since I want to give the rows new poid values, I need to find those rows which are duplicates and then re-insert them into the table. I also need a way to delete the old duplicate values as well.

    This can be tricky, as the purpose of an identity (usually) is to ensure there are not duplicate rows. It’s possible every field in the row is duplicate, which could be an issue. In this case, I’d likely just copy the data back in and delete all the “old” rows, which were the same.

    In my case, the purchaseordernumber is different, so we can use that with the date to decide which is a duplicate and which row we keep.

    SQL New Blogger

    This is a little longer post, and it somewhat got away from me, but this isn’t an easy thing to write about, nor is it short. Easy to mess this up.

    This post took me about 45 minutes to write. The code part wasn’t long, but I had to think about how to frame the issue with test code and explain that. SQL Prompt made the coding easy once I knew what I wanted. I built this over 3-4 days, working on it at 5-10 minutes at a time.

    That’s a great way to tackle complex topics.

    You could do this and impress an interviewer. Highlight this post in your resume/LinkedIn/etc.