Category: Blog

  • Accessing the Data API Builder MCP Server from VS Code

    I recently started playing with the MCP Server for SQL Server, which is a part of the Data API Builder (DAB). I’m not sure why there wasn’t a separate piece of technology used, but I do think the DAB server is very useful, and I wish more people used it. Adding MCP to it makes some sense, as the REST and GRAPHQL endpoints can be disabled.

    This post will look at a few things I did to get the MCP server working.

    A Default for New Projects

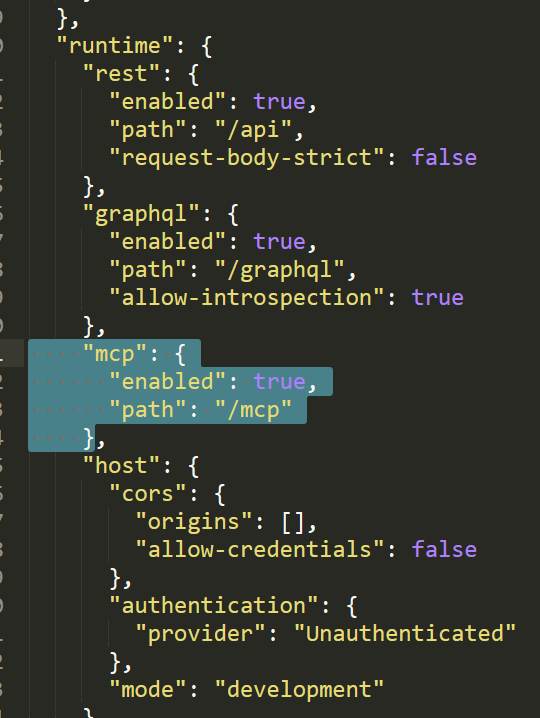
    By default, if you have v2.xx of the Data API Builder, when you create a new project (with dab init), you get this section in your json config file with the mcp entry.:

    "mcp": {
       "enabled": true,
       "path": "/mcp"
    }
    

    This is the enabling of the MCP server. In my files, this was added below the “rest” and “graphql” sections under the “runtime” key. You can see this in a larger view of the file.
    2026-08_0180

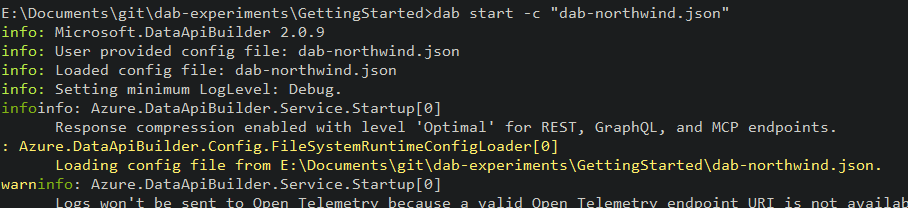
    Once you add this, the MCP server should start up with DAB. The only indication I see in the logs is this message that the endpoints are enabled.
    2026-08_0181

    Adding an MCP Server to VS Code

    My first experiment here was adding a server to VS Code. This isn’t a clear thing in the docs, to me, so I’ll tell you what worked for me. I already have some MCP servers in VS Code, so I really went through this process.

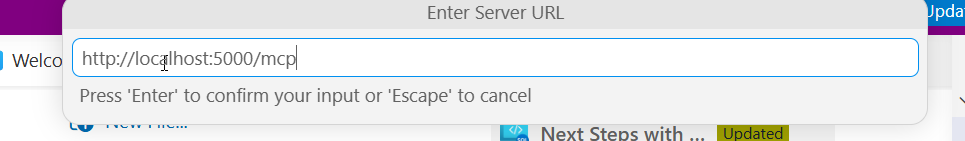
    First, this is an http MCP server, and the URL is the DAB URL  (for me: http://localhost:5000/mcp) that I’ll use to connect. I used the instructions in this VS Code article rather than the quickstart in the DAB docs.

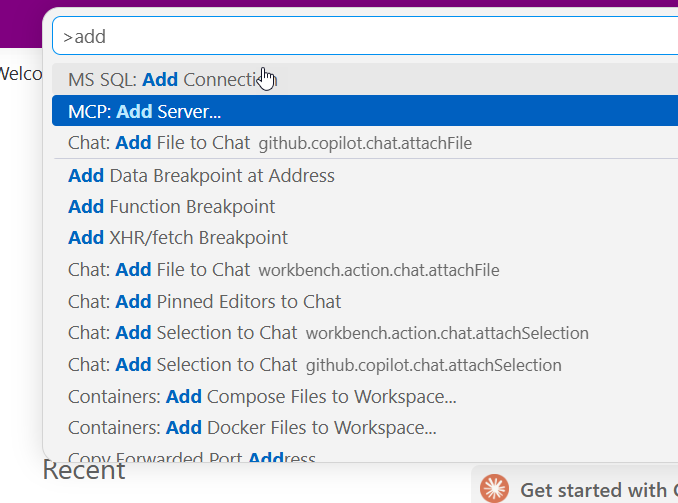
    In the VSCode command palette, I looked for the “MCP: Add Server” entry, as shown.
    2026-08_0182

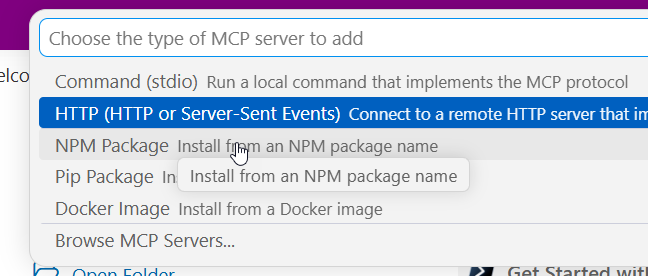
    I then picked the http option:

    2026-08_0183

    Next, I enter the UL. I’ve pasted mine in here.
    2026-08_0184

    Give this a name. This isn’t clear in docs, but this is the name that you’ll use when starting this MCP server. I chose dab-northwind-mcp, which lets me know this corresponds to my config file and it’s a dab server.
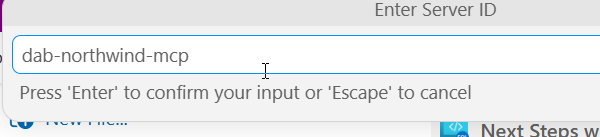
    2026-08_0185

    Next we decide where this is available. I usually choose workspace, but the setting depends on what you doing with this server. I tend to aim to keep things more tightly configured, so that if I need it elsewhere, I can learn how to adjust that, or add this as an item for another workspace.
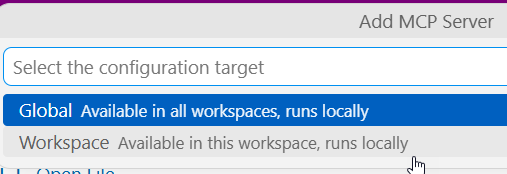
    2026-08_0186

    I then get my mcp.json file, which is the config file for the MCP servers in VS Code. These servers are a part of the “servers” key, as an sub-document below that. Each of these is a separate entry in JSOn. I essentially have two of the same here, the sql-northwind and dab-northwind-mcp point to the same server.
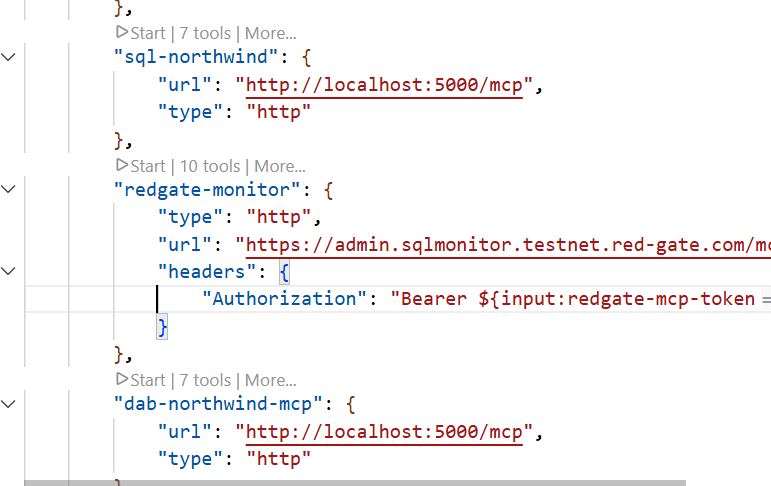
    2026-08_0187

    Starting the MCP Server

    If you look at the image above, there’s a “start” link that VS Code adds as an annotation to the entry. You can click that. For me, I usually go back to the command palette and get to the “MCP: List Servers” entry.
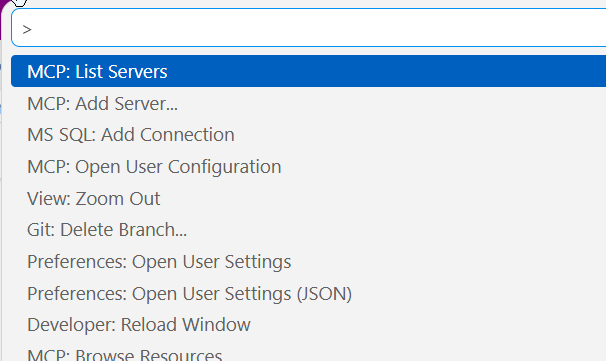
    2026-08_0188

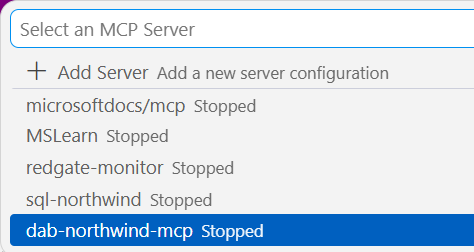
    Then I see a list of servers and I’ll select the one I want. In this case, that’s the dab-northwind-mcp one.
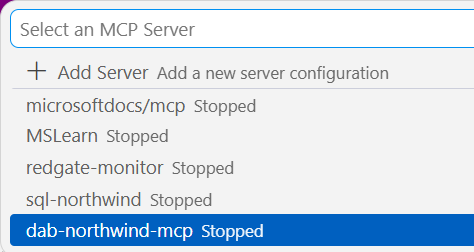
    2026-08_0189

    I see a few items. The configuration will open the mcp.json. It brings up output by default. I’ll pick “Start Server”
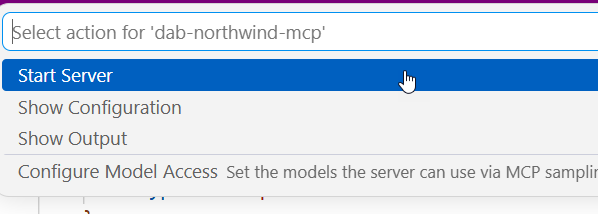
    2026-08_0190

    I can see in the output it starts. notice I have some errors, this is because the DAB server wasn’t running. I started it, and then went through the process above to get it restarted. You can see tools were discovered.
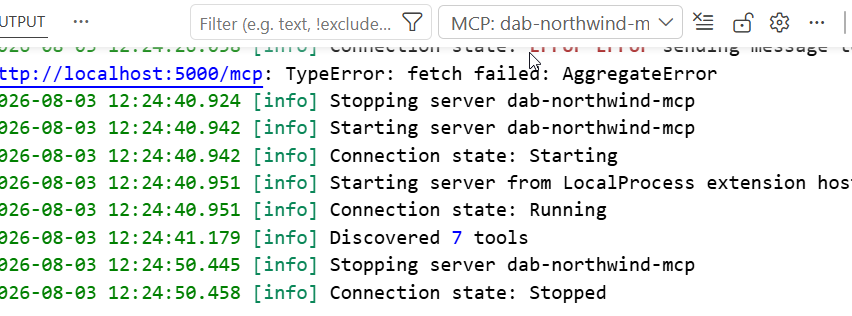
    2026-08_0191

    That’s it. The MCP server is active and running. I’ll do another post on how I can use this.


  • The Fringe Festival

    I was lucky enough to take a vacation a decade ago in Edinburgh with my wife. She came over to the UK with me for a quick trip. We had never been to Scotland together, so we trained up and stayed in Stirling. We walked around the area, visited the Wallace Monument and toured Edinburgh.  We hiked up Arthur’s Seat and piled stones on a sunny August afternoon.

    2026-07_0161

    We hadn’t planned it, but the Edinburgh Fringe Festival was going on at the time. We saw lots of street performers and wandered into a few comedy and music shows in random places. It was a fun time and we’ve always wanted to go back.

    We’re back this year. We trained up earlier today and are spending a few days here, taking in a few shows and unwinding from life. My wife has had a busy year with work and we’ve been aiming to get away every month and recharge a bit. This is our August trip after a few days in Napa in July.

    In the spirit of Amy Abel learning to recharge and detoxing, we’re getting away. I don’t know that we’ve avoiding technology, but we are avoiding the work things that create stress and take away from life.

    Make sure you take your vacation and get breaks away from the things that stress you out.

  • Why Use TRY_PARSE(): #SQLNewBlogger

    Someone asked why I would use TRY_PARSE after I posted a question at SQL Server Central: Getting the Average. Isn’t is slower?

    A fair question. This quick post looks at why.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    A Quick Setup

    The question above has the setup code, but what if I add another row? For example, I’ll run this .

    insert dbo.commission
    (
        salesperson
      , commission
    )
    values
    (‘Steve’, ‘A’)

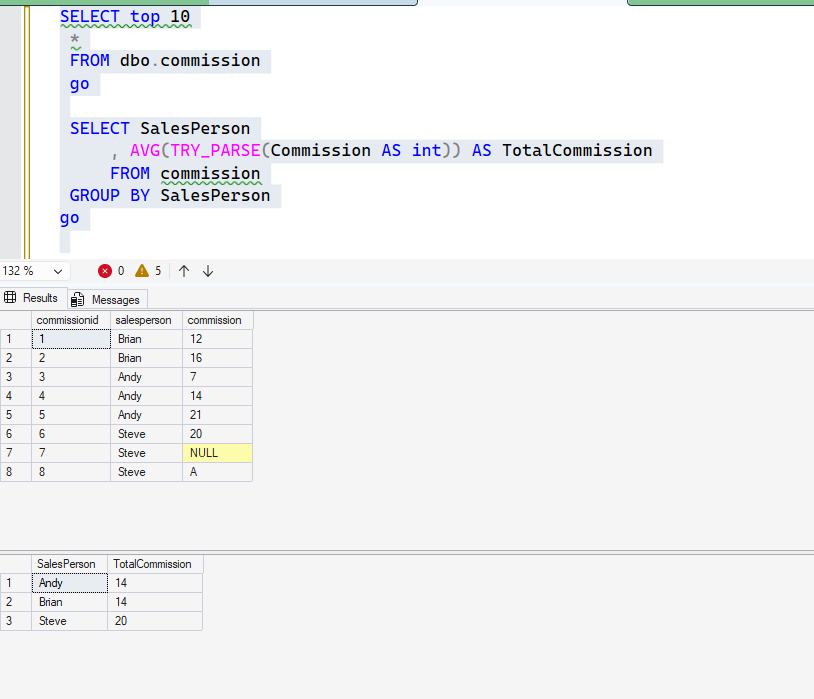
    Now, let’s look at the data and run the query from the question.

    2026-07_0371

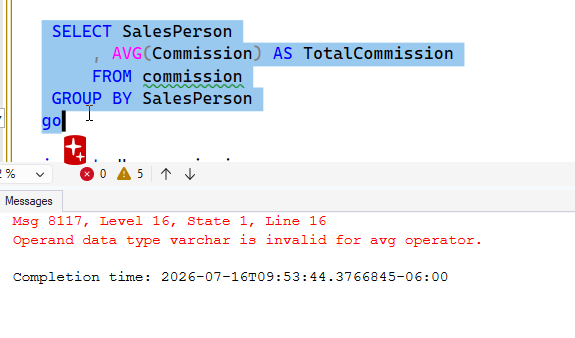
    This works. However, let’s remove the (slow) TRY_PARSE() from the aggregate.

    2026-07_0372

    Error. Why? I can’t convert “A” in the AVG to a number. It fails.

    You might think, I’ll never get bad data like this. But you might? A user might enter something you don’t expect. An AI might model this as a string, which is bad, but it happens. If it’s an EAV type table, or there are other data  items and you’re trying to extract the numbers from here, TRY_PARSE is helpful.

    SQLNewBlogger

    I wrote a post last week and this is a followup that really just took less than 5 minutes to setup and run. Plus I responded for the user in the post.

    This showcases me thinking about a question and situation and really gives an interviewer something to ask me. This lets them dive into my thought process and gives them confidence I don’t just write code without thinking.

    Add to your blog with short posts like this (or drop on LinkedIn).

  • T-SQL Tuesday #201: Temp Tables

    This month we have a new host, which I am grateful for. So many people have stopped blogging that it’s a challenge to keep this going. Jeff Taylor has an invite asking us about a core T-SQL topic that can affect the performance of your app and your server: temp tables.

    This is an interesting one for me, as I’ve changed my mind on these over the years, especially as Microsoft has made improvements to the SQL Server storage engine and query processor that have helped tempdb to perform better.

    They’ve also added things that can impact and load tempdb.

    If you want to host a T-SQL Tuesday, ping me. I’m always looking for new (or returning) hosts.

    My Answer

    My answer to Jeff’s question of temp tables as friend or foe is yes.

    They are friends.

    They are foes.

    Most things that we struggle with in database work are tradeoffs. We have to balance the demands. It’s why we say “it depends” so often because we have to find a way to do more of one thing, while accepting less of another.

    If I use temp tables in a query, I can potentially run a query to get a smaller data set that I can query with to get the results I need. I can reduce the memory grant, which might be required if the initial query scans a lot of data.

    Suppose I have a 100mm row table. If I am doing a complex join of this data on unindexed columns with multiple other tables, perhaps I want to do something like this (delivereddate might not be indexed):

    select c.customerid, o.orderid, o.delivereddate, oho.shipperid, o.salespersonid, ,qty, oh.price
    into #limitedorders
    from orderheader oh inner join orderdetail od on oh.orderid = oh.orderid
    where customerid = 12

    This can get me a filtered list of things, which I can then join this temp table with the customer, shipper, salesperson, and other tables, which will be a smaller, quicker join.

    However, a temp table can be a problem as well. If you have a query that does something like this:

    select *
    into #orderlist
    from orderheader oh inner join orderdetails od
    on oh.orderid  = od.orderid
    where oh.orderdate > dateadd(year, –10, getdate()

    And then you have some sort of query that aggregates across the years.

    select c.customername, sum(t.qty * t.price)
    from #orderlist t
    inner join customer c
    on t.customerid = c.customerid
    where customerid = 12

    I’ve done a lot of work in the first query to gather data, allocate space in tempdb, copy this over, use memory, etc. Then I am going a simple query to aggregate things, and filtering it. In this case, the developer likely followed a pattern of gather data, then sum it from other queries. It might have worked for them, but if I have 1mm orders a year, this will suck up resources.

    My Advice

    My advice is like Jeff’s. In general, try to work with a query to solve your problem. Use joins, beware of views, and make sure you’ve indexed well. Use CTEs to break down your problem, and don’t use temp tables.

    If you struggle to get a single query, or you have poor performance because of memory grants or other issues, then think about shrinking your dataset down using a temp table and indexed columns. Then join this to get other data that you need.