Category: Blog

  • Stop Copying Files from the Server – File Cache Bug

    I watched the Brent Ozar, PLF Scary SQL Surprises webcast and was surprised by him mentioning this bug: http://blogs.msdn.com/b/ntdebugging/archive/2009/02/06/microsoft-windows-dynamic-cache-service.aspx

    The blog references another blog and talks about the problems with x64 systems and the file caches. Too much file copy activity on your x64 server can severely crunch your memory, including your SQL Server memory.

    There’s an unsupported utility available from MS in the blog you can get, but I like Brent’s advice better.

    Don’t copy files on your production SQL Server.

    Use another machine to do the copy work for you, even if it’s slightly slower. That includes watching out for ETL work and any jobs on your system that might do the copies for you.

  • The Charles River – SQL in the City Boston

    headI once rowed in the Head of the Charles Regatta. I had the 3d seat, starboard, in a 4 man boat and it was quite exciting to come up to Boston and row down the famed Charles River. It was hard, and the river was rough, tossing waves in our boat at times, but it was a great experience. This year I won’t be rowing in the Charles, but I am looking forward to a chilly run along the Charles on Oct 7. I’ll get into Boston around 4:30pm, race to the hotel, and then have an evening run. Follow me on Twitter if you want to join me. I’ll probably do a couple miles that evening, and again around 6:30am on Monday.

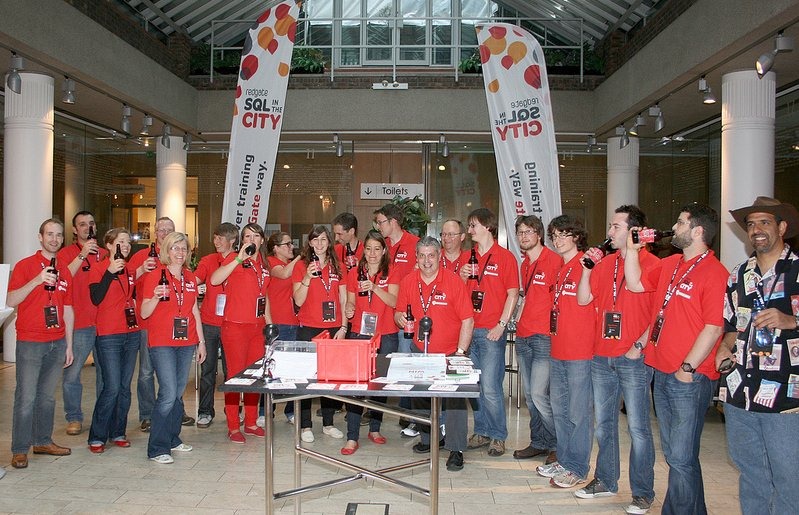
    The SQL in the City tour comes to Boston on Monday, Oct 8, 2012 with another great lineup of speakers. In addition to myself, g, and a number of our Red Gate developers, we have Adam Machanic (b | t) joining us to deliver a full day of free training to SQL Server professionals.

    Free. Just register and come down to the Joseph B. Martin Conference Center at the Harvard Medical School on Oct 8, 2012. It’s training The Red Gate Way at a great location, with fantastic material and plenty of refreshments. The staff is there to make sure you have a great day, as we do at every stop.

    staff

    booksWe’re looking to teach you a few things, give you tips and tricks for working with SQL Server, debate you, answer questions, and have an inspiring day. Stop any of us, and ask a question, pick up a book for your library, and maybe even win a prize as we sip a beverage at the end of the day.

    It’s a great time and I’m sure you’ll find it worth your time to come spend a day with us talking about SQL Server.

    Register today, and come shake my hand in Boston on Oct 8.

    This is part of my SQL in the City series, covering a few thoughts on the US tour.

  • Quick T-SQL Performance Comparison

    I’m not a T-SQL guru. When I have something that will run often, or I have performance concerns, I’ll ask someone like Jeff Moden or Wayne Sheffield to help me write a solution.

    However I have a few tricks to check things out quickly and determine what’s a better solution. Recently I ran across a thread asking for a solution to a problem that needed to sum data, but also pick values from a certain row. I posted a quick solution, and a few minutes later there were two others.

    I didn’t think mine was great, using a CTE and a subquery felt slightly inefficient, but was it really inefficient? I grabbed the third solution, which was similar to mine, and put both in SSMS. I then ran both pieces of code together, after clicking CTRL+M (include Actual Execution Plan).

    ; WITH MyCTE (acc_no, c_name, cnt)
    AS
    ( SELECT acc_no
           , c_name
           , COUNT(c_name)
       FROM #testing a
       GROUP BY acc_no
              , c_name  
    )
    SELECT 
      t.acc_no
    , c.c_name
    , number_sum = SUM( t.number) 
    , r_value_sum = SUM( t.R_Value) 
     FROM #TESTING t
       INNER JOIN mycte c
         ON t.acc_no = c.acc_no
     WHERE c.cnt = (SELECT MAX(d.cnt)
                     FROM MyCTE d
                     WHERE d.acc_no = c.acc_no
                   )
     GROUP BY t.acc_no
            , c.c_name
    ;
    
    with cte1 as (
    select acc_no,number,c_name,
           sum(R_Value) over(partition by acc_no) as R_Value,
           sum(time_spent) over(partition by acc_no) as time_spent,
           count(*) over(partition by acc_no,c_name) as cn
    from #TESTING),
    cte2 as (
    select acc_no,number,c_name,R_Value,time_spent,
           row_number() over(partition by acc_no order by cn desc,number desc) as rn
    from cte1)
    select acc_no,number,c_name,R_Value,time_spent
    from cte2
    where rn=1
    ;
    

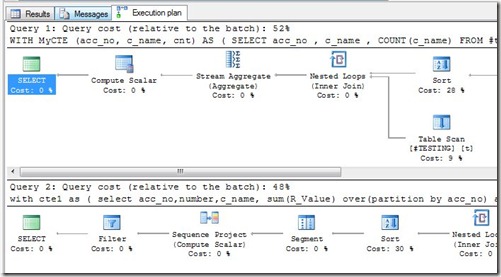
    With all this code, I ran it and got this in the execution plan window (the results were the same and correct).
    comapretsql

    If you look at the top of each section, where it says “Query 1” and “Query 2”, and then look to the right, you’ll see the relative percentage of cost of the batch. With two queries in this batch, but solution was only slightly worse than the other solution (52% to 48%). That quickly tells me these are similar solutions.

    Now this isn’t an end-all, be-all way to look at queries. This is limited data, and unindexed tables. You’d want to test this with a few loads, and examine the details more closely if you are trying to tune these queries, but as a quick check, this helps to decide if you should think about abandoning one solution quickly.

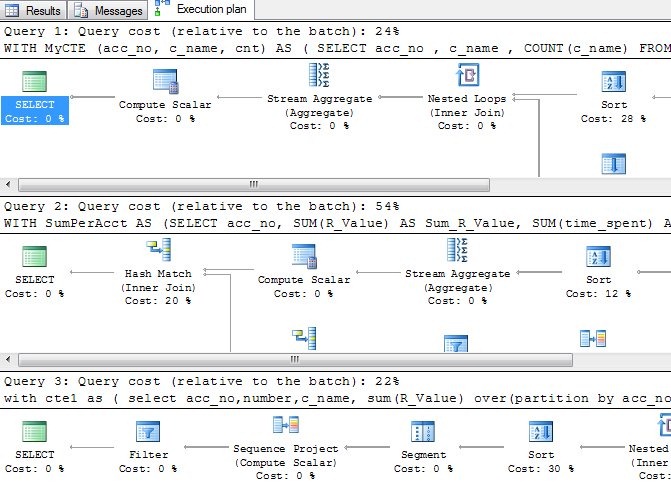
    When I ran all three solutions (mine first, the 48% one above last), I got this:
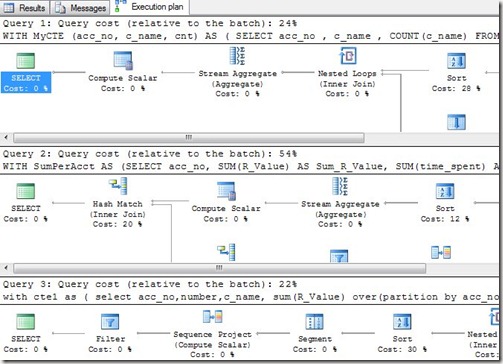
    comapretsql2

    The second solution is much worse, almost twice as bad here, so I’d give that up and look at both of the other solutions in more detail if I wanted the optimum solution.

    And probably ask Jeff or Wayne for their opinion in the SSC forums. Winking smile

  • Holiday

    Taking some of my own advice. I’m off today and tomorrow, as well as Monday for Labor Day. Across this 5 day weekend, I have a number of chores to tackle, including trying to build another horse shelter before winter.

    However I will look to recharge and relax a bit. No baseball, no kids sports, just a family weekend on the ranch.