Category: Editorial

  • Toggle Switches

    More toggle switches mean more decisions, but also more control. Are they worth it?
    More toggle switches mean more decisions, but also more control. Are they worth it?

    When SQL Server 7 was released, it was touted as a self-tuning, self optimizing database platform requiring much less attention from a DBA. The product had relatively few tuning options and limited information available about how it processed queries. DBAs were worried about losing their jobs, though as history has shown us, the concerns were overblown. There was plenty of work for DBAs then, and that has continued through the current SQL Server 2012 release.

    However the number of tuning options, and the wealth of information exposed by SQL Server to developers and administrators has grown tremendously over the years. We have DMVs and DMFs, many more tuning options, new hints, isolation levels, and more that enable the DBA to manage SQL Server fairly in a very granular way when they want to do so. From what I understand, there are still less options than other platforms have and often the best advice I seen given from various people is to write more efficient code and let SQL Server still determine the optimal plan for query execution.

    This week, I’m curious how you feel about the tuning and configuration options in SQL Server. The downside of the additional options in other platforms is that there are more choices to make, more DBA decisions, and more administrative overhead in regularly, and constantly tuning these systems.

    Do you want more toggle switches in SQL Server?

    I don’t mean two position switches, like the physical ones used on the Apollo command module, but rather just switches you can use in SQL Server. These could be database or instance level, sp_configure settings, they could be query hints, they could be session options. Do you want more options, or do you think we have a lot to work with already?

    Personally I like the idea that we can change behaviors, but I’d really prefer that the defaults were well set and somewhat self-tuning for most installations.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.

  • Zettabytes and Beyond

    Billions and billions of stars don't seem so large anymore.
    Billions and billions of stars don’t seem so large anymore.

    The old Carl Sagan quote about billions and billions of stars in the universe doesn’t seem so large anymore. In fact, a billion of anything, while a large number, seems immense only until we talk about the scale of data. How much data is there in the world? I’m not sure. As I was researching this for a new presentation, I’m not sure I can even conceive of the scale of data creation occurring in the world today, much less how much data we have.

    Think back 30 years ago, as computers were just starting to become household items. The high density floppy disk (not really very floppy) was a 1.44MB disk. At the time, this held what felt like lots of data in terms of text pages. However many songs we listen to today wouldn’t fit on this media. As we’ve progressed through CDs and DVDs to flash drives, we’ve grown the storage capacity of our hardware by unbelievable amounts. My phone has 64GB of storage, which is a level of growth so far removed from the Apollo guidance computer’s 2kb that comparisons don’t do it justice.

    We used to create data storage analogies by listing the number of books that would fit on the device. Today that’s meaningless. The 30,000 ebooks on Bookworm fit in 20GB. That’s a number of books that’s hard to conceive of. My local library branch has about 20,000 books, so I can somewhat grasp that scale, but not really. Two libraries worth of books is a level of words and knowledge that I’m not sure I appreciate. Trying to understand the amount of storage a library like the Vatican needs, is beyond comprehension.

    The grasp of how much digital data we create is even more mind boggling. I saw a talk recently that said 24 hours worth of digital video is being uploaded to YouTube every second. Every second. That’s an impressive statistic, but I’m not sure we can even comprehend what that means. An even more daunting statistic is that all the knowledge recorded from the Gutenberg printing press invention through the next 500 years totaled about 1 exabyte. At current rates, we create an exabyte of digital data in less than a month and that’s only going to increase. If you read some of the analogies in this report from EMC, they’re almost silly, and certainly not something most of us can relate to. I certainly can’t picture 75 billion iPads.

    These days the amount of data we are dealing with is growing faster than ever, and that means it’s a good time to be in the data business. From “Big Data” to data warehousing to the common OLTP databases we manage, there is no shortage of bits and bytes we will get the chance to manage. For pay.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.

  • Serious Storage

    This was our quarter million dollar server years ago.
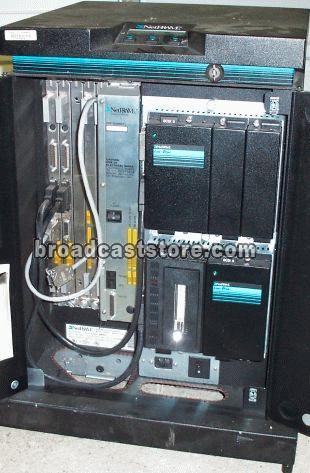
    This was our quarter million dollar server years ago.

    Years ago I worked for a company that had a Novell network. We had a multi-server environment with lots of users and were having issues with both space and users. We bought a Netframe server, packed with 350MB drives and a limited edition 1000 user version of Netware v3.11. This was also the time when I got to use my C-language experience, writing a login utility that would handle our user IDs above 250 on Netware since that was the limit for all of our other servers.

    That server, which cost something like $280,000 in 1991 was the biggest one on our network, with something like 8GB of storage. That seems like a pittance today, especially compared with the sale EMC just made. The Vatican is getting 2.8PB of storage from EMC for its library. EMC is also providing consulting services to digitize some of the historic manuscripts and documents that have been deteriorating from user and handling.  It’s an ambitious 9-year project, of which this is just the first 3 years.

    That’s a serious amount of storage, and while most of it will be used for raw, unstructured storage of images, some will have to house a database. There will be the equally critical part of cataloging and organizing the meta data about these documents into some type of database. I don’t know if this will be a relational or some other store, but without some database that keeps track of what each image represents and how to retrieve it, it’s entirely possible that these documents might get lost, in the same manner they may be lost in physical storage today.

    The scale of this project somewhat astounds me. Going from MB and GB to thinking about PB and EB is something many of us will deal with over the next decade as our organizations gather, store, and manage more and more data. Perhaps a few of us will get to work on some interesting projects like this one that look to preserve valuable knowledge from our past.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.

  • The Backup Process

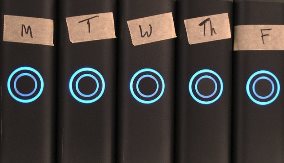
    This used to be my backup process. Five copies, one for each day of the week.
    This used to be my backup process. Five copies, one for each day of the week.

    I was reading Scott Hanselman’s post onThe Computer Backup Rule of Three, and I completely agree with him. If things are important, three copies are the minimum you should keep. I have had backups before, but I’ve found that when something breaks, like a tape drive or hard drive, I might not get to replace it right away. Usually this is procrastination, or as it’s more commonly known, laziness. During that window of opportunity, I’ve had Mr. Murphy strike. My inherent paranoia of having that second extra copy has saved me, both personally (at home) and professionally (at work).

    All too often I run into DBAs that seem to trust and assume their backups and processes are very reliable. After setting up a backup process, usually to disk, and testing it with a restore on another system, they assume it will work in the future. It should, but there is always the chance something will fail at some point in time. There’s the chance that some hardware failure or software reconfiguration will cause an issue with your process. There’s also the simple chance that your I/O system might introduce corruption into your backup files.

    If you aren’t regularly testing your processes, you can’t be sure they are working as they have in the past. The ideal environment would perform a restore of every backup file taken, every day, but that isn’t always possible. However restoring a random backup once every month or two will help you to ensure your backup, and restore, processes, have the best chance of succeeding when you actual need to perform them because of a disaster.

    This isn’t hard to script and automate, but it is something you need to do periodically. However even if you automate restores of all your databases, make sure you still practice your manual skills regularly. Automation might not work in a disaster situation, but those quarterly practice sessions restoring a database to a point in time with a tail log might just relax you when a crowd in your cube is asking if the database will be back up soon.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.