Tag: administration

  • The Dangers of Detach

    I ran across a twitter conversation about a post recently. The post talks about detaching or attaching databases in bulk.

    I agree that detaching databases in some cases is bad, but it’s not necessarily something I’d avoid. Detach is a good way to prep for upgrades, movement, etc. It may or may not be faster than backup/restore, depending on your environment, but it’s something to consider.

    However.

    If you are going to detach, there are a couple things I’d recommend. First, make sure you have a good backup. A backup is just that, a backup plan, a backup file, a way to recover when things go wrong. It isn’t your data, it’s a copy. A detached mdf is your data. Make sure you have a backup before detaching and messing with files.

    Second, never move files. Never, ever, ever, ever, move database files. Detach/attach is a valid way to move databases, but always copy the files.

  • Job Worries over Automation

    There was a report recently where the NSA noted that they are reducing the number of system administrators by 90%. If the report is true, that would certainly worry many of the people in the technology industry. However I’m not sure that the quote given in the article means what it looks like at first.
    Much of the technology reports that we see aren’t completely true since many of the reporters aren’t that familiar with the details of how computer technology works. In this case, however, we have a quote: “What we’re in the process of doing – not fast enough – is reducing our system administrators by about 90 percent,” It might be hard to interpret this remark in any way other than the NSA is looking to reduce the number of people, but if you read further, the piece notes that the NSA is concerned about contractors, not necessarily FTEs. I suspect that any reduction in contractors employed by other companies will be made up by increased internal headcount.
    However even if the NSA can reduce the number of people needed to administer their systems, I’d suspect that means that they had too many people to begin with. The various reports of this story all talk about automation being used increasingly to handle the load of system work, but the idea that automation replaces people is a myth. Automation usually results in less growth of people, but rarely a reduction in staff.
    I’ve heard the concerns over automation replacing technology workers for decades (literally) and I’ve yet to see it happen. We have more technology workers than ever before, and no sign of there being less in the future. Your department might change, you might hire less, but there will be lots of jobs in technology for the foreseeable future. In other departments that might not be the case, but I bet you we’ll have system administrators, DBAs, and developers for a long, long time in most companies that have them today.
    Steve Jones

    Video and Audio versions

    Today’s podcast features music by Everyday Jones. No relation, but I stumbled on to them and really like the music. Support this great duo at www.everydayjones.com.

    Follow Steve Jones on Twitter to find links and database related items and announcements.
    Steve Jones Windows Media Video ( 16.4MB) feed

    MP4 iPod Video ( 19.1MB) feed

    MP3 Audio ( 4.0MB) feed

    Feeds are available at iTunes and Mevio

    To submit an article, rant or editorial,
    log in to the Contribution Center

  • Versions of Disaster

    Today’s editorial was originally released on Jan 13, 2009. It is being re-run as Steve is on vacation.

    I wrote about versioning of old software recently and how I had to restore an old version of SQL Server in response to a lawsuit. We had some challenges because the backup file that we had was from years before and we weren’t sure which version of SQL Server we needed. I forget how we finally determined which service pack was needed, perhaps we read master somehow to get a build.

    In any case, when you apply patches or change how SQL Server functions, you can change the way that code is executed or even the results that might be returned to an application. You would hope that code would break and error out rather than return different results than you expect.

    Since many of us patch servers when Service Packs come out, or when we find a hot fix we need, and we are constantly deploying and changing code, do we pay enough attention to the server version as we make these deployments? I started thinking about this after the last editorial and I think that we often take it for granted that we can easily recreate our environments.

    Consider what would happen in the event of a disaster. Suppose that one of your server instances, any particular instance, died and you had to go back to a backup of the database, would you know what version of SQL Server is needed? Do you know what version each of your instances is using right now?

    In some ways this makes me think that only installing RTM and Service Pack versions in your production environment is a good idea. It’s easier to track things if you keep all your instances within a very narrow band of versions, and the worst case would be attempting a restore on RTM, then SP1, then SP2, etc. until you hit the correct version. Imagine now if you had to work through the various builds on my build list.

    I used to think that I’d want to keep current on my patches. In one large environment, we were actually pretty good about deploying patches to hundreds of instances inside a month, so we always had a large percentage of our servers, and usually all the critical servers, at the same patch level. However if a disaster had occurred within the month, we wouldn’t necessarily have been sure of what versions were installed.

    I really don’t have a great recommendation on how to handle this other than build some automated system that tracks the current build number on a daily basis, perhaps even putting it in each database. At least then you’ll have it handy in the event of a disaster.

    Steve Jones


    The Voice of the DBA Podcasts

    Everyday Jones

    The podcast feeds are now available atsqlservercentral.mevio.comto get better bandwidth and maybe a little more exposure :). Comments are definitely appreciated and wanted, and you can get feeds from there.

    Overall RSS Feed:  or now on iTunes! 

    Today’s podcast features music by Everyday Jones. No relation, but I stumbled on to them and really like the music. Support this great duo at www.everydayjones.com.

  • Managing Data in a FileTable with T-SQL

    I wrote a post about creating a Filetable, which just covered the basics of how to build one. How do you work with the data in this table? In this post I’ll look at a few things you can do from the T-SQL side.

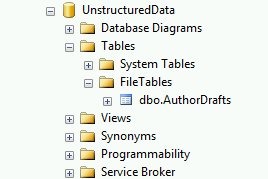
    From the last post, I had my author drafts Filetable. I can see this in the Object Explorer.

    filetable_c

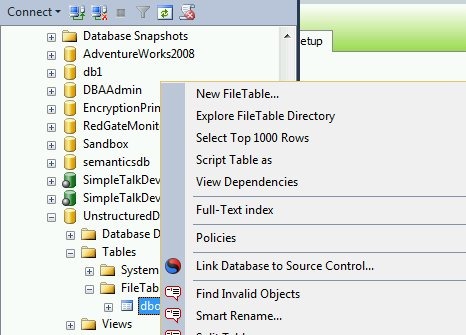
    I can use the same “select data” feature from Object Explorer on a Filetable, just like any other table.

    filetable_e

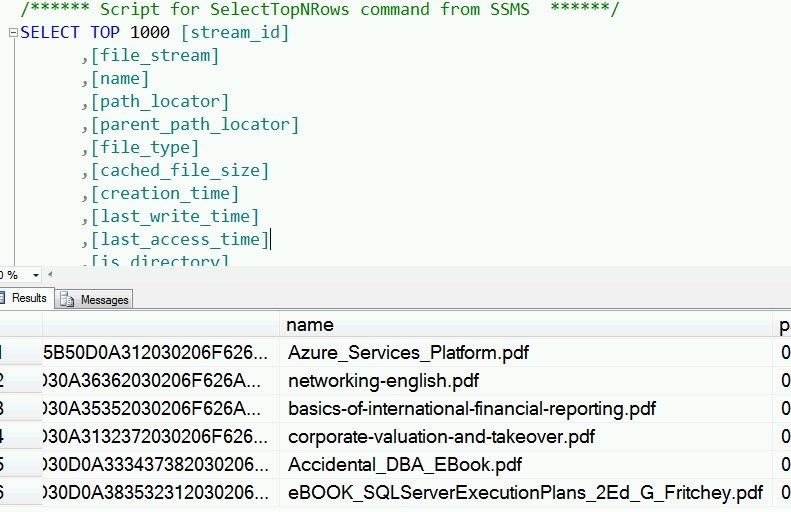
    I get the results, and as you see, I have a few rows in the table.

    filetable_f

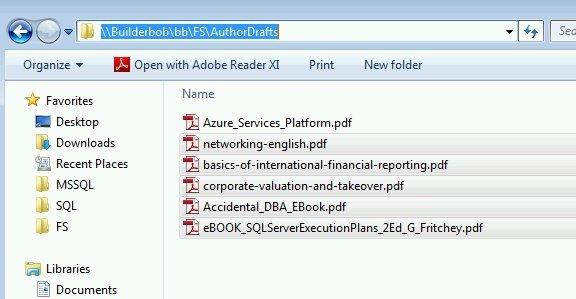
    These are actually the files I see in the share.

    filetable_d

    Inserting Data

    One of the advantages of Filetable is that you can use Explorer (and any tools that use the same Explorer APIs) to move data in and out of a table. However that doesn’t preclude you from using T-SQL.

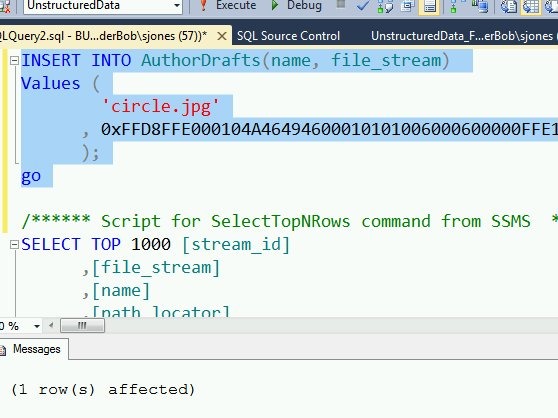
    I can use a script to insert data into the table, just as I might with Filestream.

    INSERT INTO AuthorDrafts(name, file_stream) Values ( 'circle.jpg' , 0xFFD8FFE000104A46494600010101006000600000FFE100684578696600004D4D002A000000080004011A0005000000010000003E011B0005000000010000004601280003000000010002000001310002000000120000004E00000000000000600000000100000060000000015061696E742E4E45542076332E352E313000FFDB0043000201010201010202020202020202030503030303030604040305070607070706070708090B0908080A0807070A0D0A0A0B0C0C0C0C07090E0F0D0C0E0B0C0C0CFFDB004301020202030303060303060C0807080C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0C0CFFC0001108000A000D03012200021101031101FFC4001F0000010501010101010100000000000000000102030405060708090A0BFFC400B5100002010303020403050504040000017D01020300041105122131410613516107227114328191A1082342B1C11552D1F02433627282090A161718191A25262728292A3435363738393A434445464748494A535455565758595A636465666768696A737475767778797A838485868788898A92939495969798999AA2A3A4A5A6A7A8A9AAB2B3B4B5B6B7B8B9BAC2C3C4C5C6C7C8C9CAD2D3D4D5D6D7D8D9DAE1E2E3E4E5E6E7E8E9EAF1F2F3F4F5F6F7F8F9FAFFC4001F0100030101010101010101010000000000000102030405060708090A0BFFC400B51100020102040403040705040400010277000102031104052131061241510761711322328108144291A1B1C109233352F0156272D10A162434E125F11718191A262728292A35363738393A434445464748494A535455565758595A636465666768696A737475767778797A82838485868788898A92939495969798999AA2A3A4A5A6A7A8A9AAB2B3B4B5B6B7B8B9BAC2C3C4C5C6C7C8C9CAD2D3D4D5D6D7D8D9DAE2E3E4E5E6E7E8E9EAF2F3F4F5F6F7F8F9FAFFDA000C03010002110311003F00E97FE0E87FF82CA7ED35FB04FED85E09F03FC2BD6A5F87BE1097408B5C4D523D2ADAF1BC41746795248CBDC4722F970848C18940399373E43478FD75FF00827CFC68F177ED17FB0FFC2AF1D78F3461A078C7C59E19B2D4F57B110B42B14F244199846DF346AFC384392A1C024E335E95E2EF87BE1FF880968BAF687A3EB6B612F9F6C2FECA3B916F27F7D3783B5BDC60D6C5007FFFD9 ); go


    As you can see, this command works fine:

    filetable_g

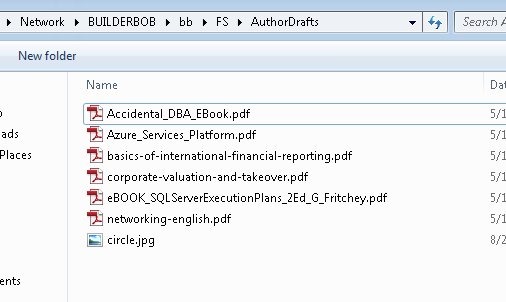
    If I then look at the share, I see my file:

    filetable_h

    Retrieving Data

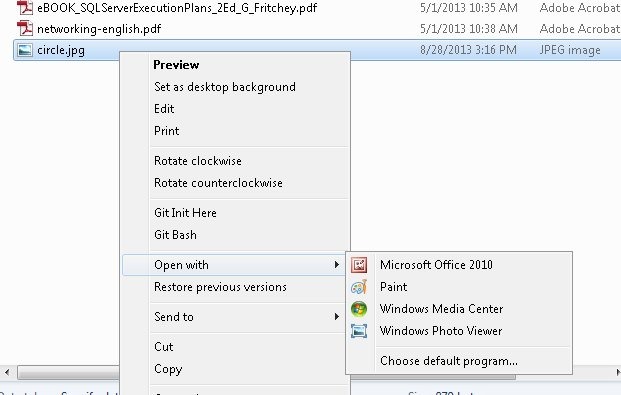
    As shown above, I can use SELECT queries to return data from a Filetable in T-SQL. However, I have a share as well, and I can cut, copy, paste, and open files from the share just as I would any other file in the file system.

    filetable_j


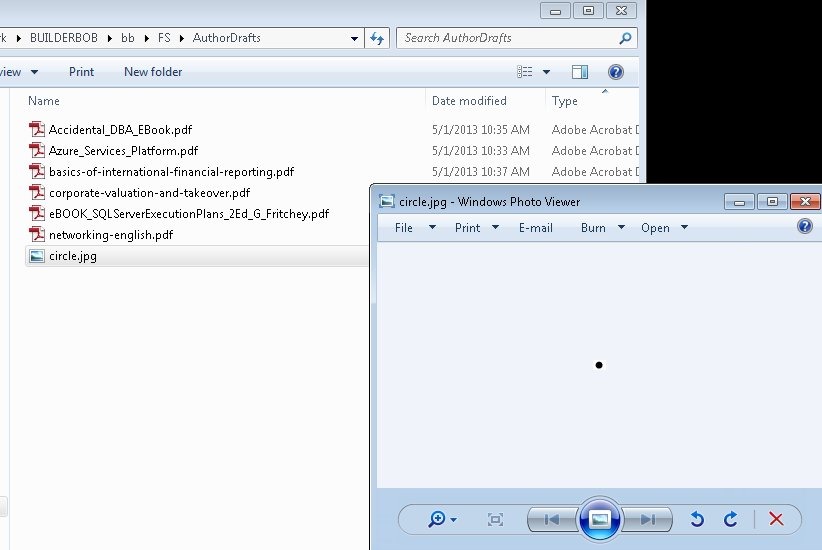
    If I open the file in Paint, I see my image:

    filetable_i

    Summary

    Working with files in a file table is easy, and while many people will use Explorer functions, you can use T-SQL as well to insert, or retrieve the data as you choose.