Tag: AI

  • Getting the SQL Server MCP Server Running

    If you’ve wanted a SQL Server MCP server for your databases, it’s available. The SQL MCP Server is a part of the Data API Builder (DAB). DAB is a wrapper that allows you to run a service over your databases that exposes REST, GRAPHQL, and now, MCP, in a way that lets you control it.

    I’ve written a bit about this here and at SQL Server Central, and this post looks at adding MCP access to your DAB setup.

    This is part of a series on the Data API Builder.

    Adding the MCP Endpoint

    I have a DAB setup already that runs well. I have a REST endpoint (here’s the REST view of Northwind.dbo.Customers).
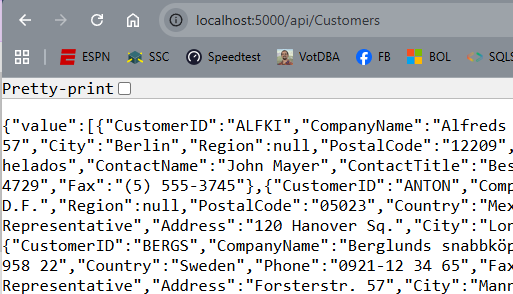
    2026-07_0304

    And here is the GRAPHQL endpoint.

    2026-07_0306

    If I look at my configuration file that drives the service, I see this:
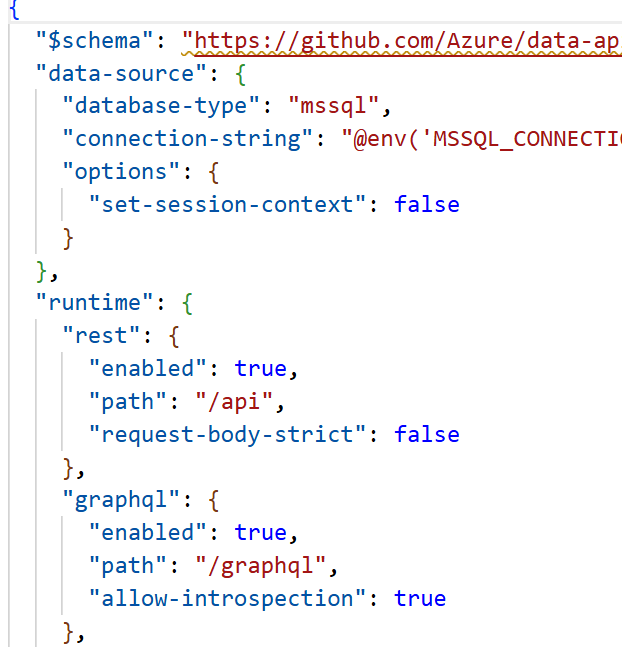
    2026-07_0307

    What about MCP? It’s easy to add.

    The MCP Service

    The MCP capability was added in v1.7 of DAB, but the current version if over 2.0 (2.0.9 as of Jun 30, 2026). There have been bug fixes and capabilities, so I’d recommend upgrading.

    Second, this is enabled by default for new DAB configs, but if you have an existing config, you need to add a JSON key/value in your file. This is the runtime configuration, but by default all the tools are available. Here is my new config file (which I regenerated from my old VCS items). You can see the new MCP section between the graphql and the host keys.
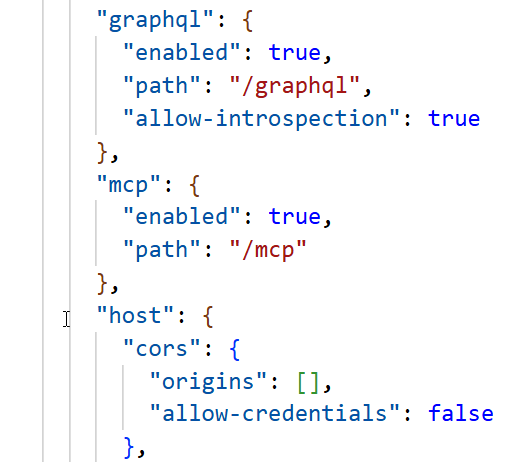
    2026-07_0308

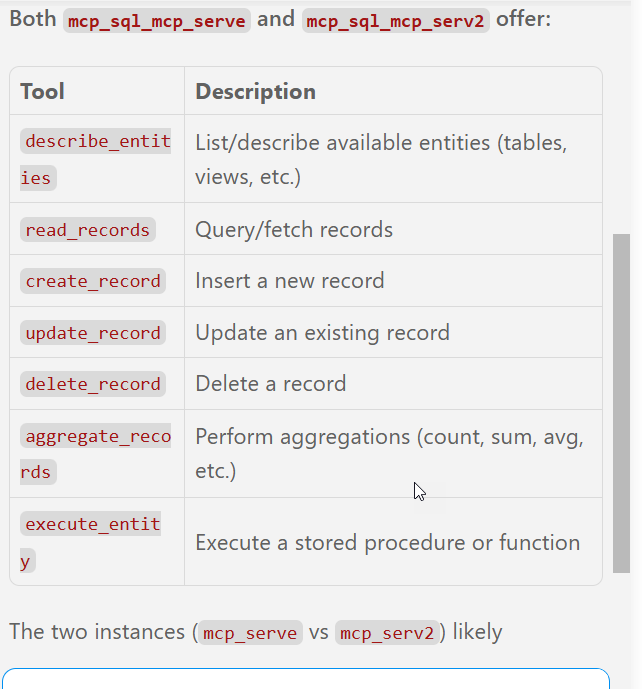
    In the docs, you can add a dml-tools key and enable or disable individual tools. The DML tools available are:

    • describe_entities – Discovers available entities and operations
    • create_record – Inserts new rows
    • read_records – Queries tables and views
    • update_record – Modifies existing rows
    • delete_record – Removes rows
    • execute_entity – Runs stored procedures
    • aggregate_records – Performs aggregation queries (new in v2.0)

    Since this entry is in my configuration, I’ll start the DAB server and query it.

    Querying the MCP Server

    I need an agent to do this. The easiest one for me is the Copilot Agent in VS Code. I configured the MCP server (another post coming on this) and then sent a query. You can see the agent accessing the server and looking for the tools. Seven were found.
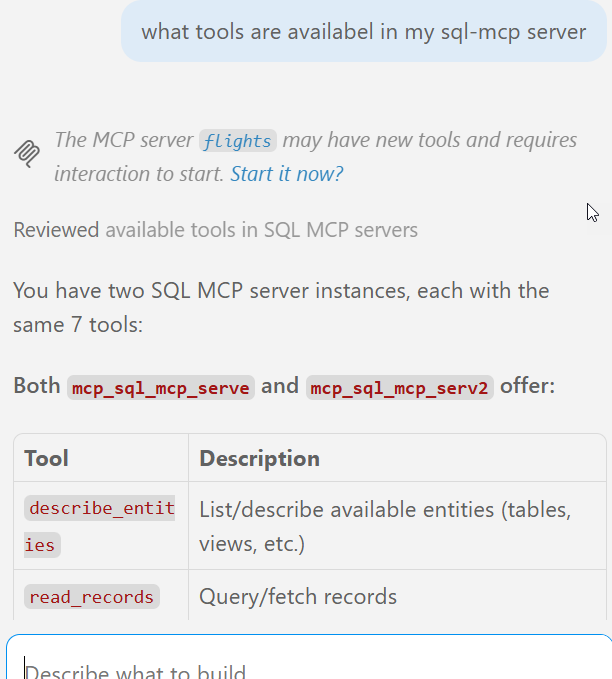
    2026-07_0309

    Here is the rest of the entry, with the descriptions of the tools.
    2026-07_0310

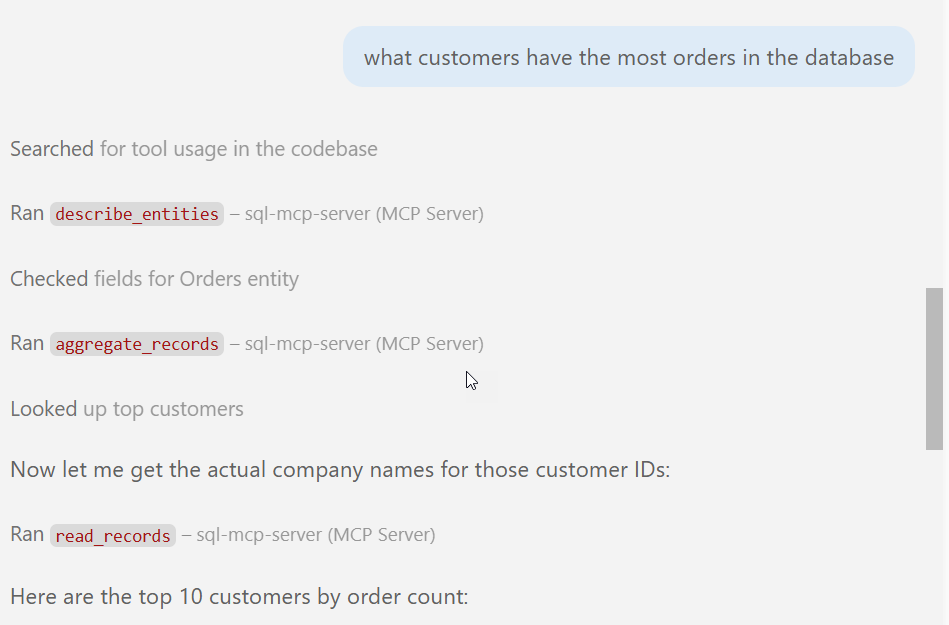
    The power in the MCP server is I can ask my agent to use the tools to do work. I don’t need to be that specific. In the query below, I’ll just ask for data. In this case, the customers with the most orders:
    2026-07_0311

    At each of the “ran” stages, the agent asked for permission. I granted it, allowing the agent to run code. It went through metadata in the db and then returned the data. Below the image above, I had the results returned. You can see that here.
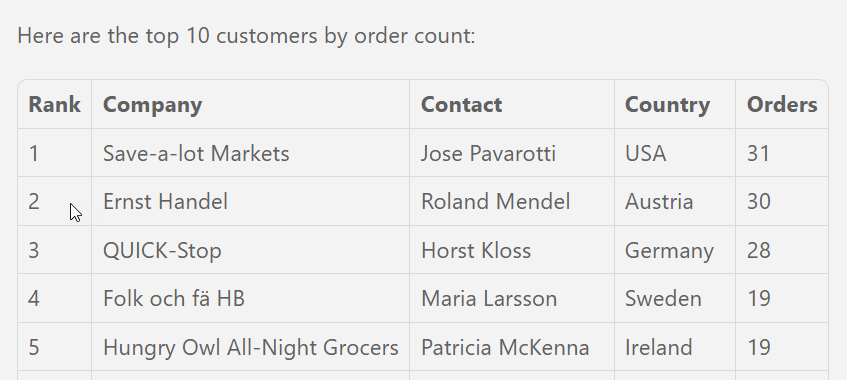
    2026-07_0312

    This matches what I get from SQL if I run a query. Below is the query I ran directly.
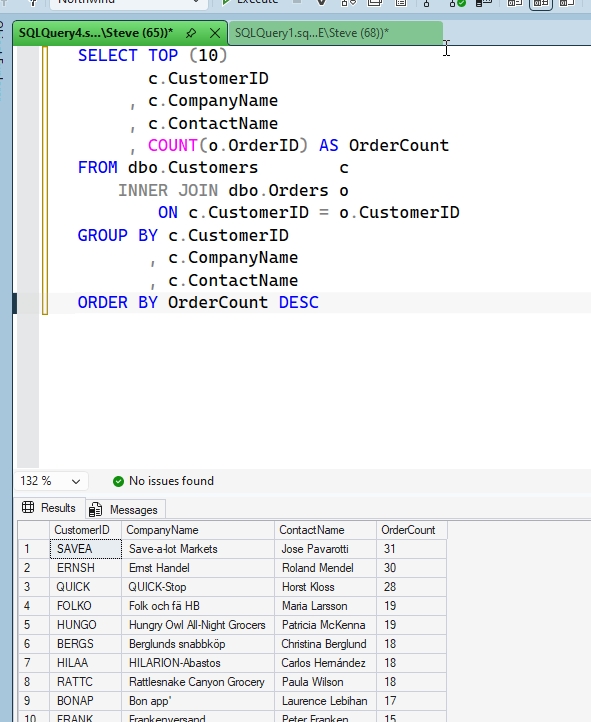
    2026-07_0313

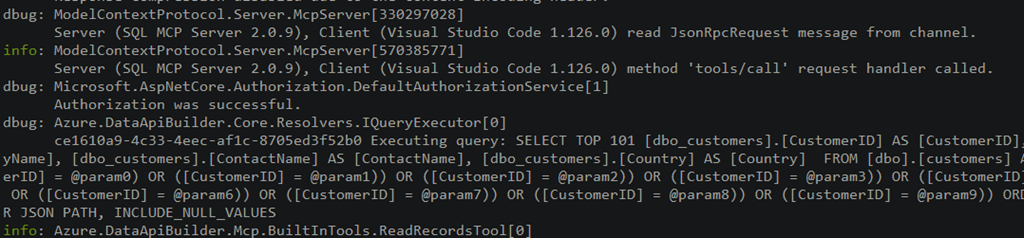
    If I look at the DAB log, I see the mcp server being accessed.
    2026-07_0314

    This is a very quick look at the MCP server working in SQL Server. It’s another great reason to use DAB. That already makes building CRUD applications easier, and now you get MCP access as well.
  • Another Model, More Data Loss

    This past week I saw an article on eWeek that the newest OpenAI GPT-5.6 (Sol) model has deleted local files and live data. Files I’m less worried about, but data concerns me. There are lots of file backups, and certainly version control should be enabled for any developer tasks on which an AI works. However, data is harder, since it can change quickly, especially in live environments.

    There are different reports, some of which seem like more human error issues than the model’s, but we should account for human error when we use models. In one report, a model had access to a live production database and cleared tables for integration tests. Database testing is hard, as I’ve learned over the years. Many developers don’t think about how testing works with live data and how it is different from mocks and stubs. It is different, and if you use a lot of testing frameworks on live databases, you run the risk of there being issues. You could have data loss, and almost certainly will have some level of downtime disruption.

    This is a great reason why adding AI coding to database tasks needs governance around what is allowed. It is easy to have success with AI-assisted work and forget that these models can make mistakes. And if you trust them with too much, like you might be tempted with an impressive but junior DBA, you might get burned. These automated tools can get hyper-focused on a certain task, and not consider the ramifications of their actions. The article notes an agent ran “rm -rf” on a dev machine. That’s similar to what happened with Toy Story 2, where a human made the mistake. Both that person and this GPT-5.6 model weren’t thinking widely enough about what tasks they were managing.

    The article notes that this model can be overly persistent and assume actions are permitted unless explicitly prohibited. Not unlike a lot of humans who assume if someone has given them rights, they can do the task. OpenAI noted in an internal case that a user approved the removal of three VMs. When the coding agent didn’t find these, it looked for other machines and chose three other VMs. Crazy, but I’ve seen humans do this in the past.

    I don’t think these models are getting closer to Artificial General Intelligence (AGI) or that they are anywhere close to sentience. However, as they become more capable and handle more complex predictive actions, they are also likely to do the same stupid things humans do by not considering all the possible consequences of their actions. After all, we have plenty of data where humans haven’t considered the effects of their actions, and that data is in the AI model training set.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • AI Experiments: Claude Solved a DAB Issue

    I’m sure many of you are using AI regularly, perhaps chatting, perhaps using some sort of agent. I’m doing the same, but in this case, I had it tackle an issue that’s been inconsistent for me with the Data API Builder and it solved it. Something I’ve struggled to do with docs and Google.

    This is part of a series of experiments with AI systems.

    The Scenario

    I’ve been doing some work with the Data API Builder, letting it provide me access to data through REST and GraphQL. Lately, it added MCP as well, and I’ve been updating a talk as well as experimenting with this.

    However, I’ve struggled to get Stored Procedures to work. They have sometimes worked, sometimes not, and I’ve not quite figured out why. Now that I know, I feel a bit silly, but recently I decided to let Claude help me solve this.

    I typically use Northwind, and the DAB docs have been a little light. They have exmaples, and I’ve gotten these to work, but when I’ve moved to more standard Northwind things, this hasn’t always worked.

    I should have seen a pattern, but it’s a lot of data, docs, and different places I’ve seen searches. This felt like a place an LLM might see something I didn’t see. It’s also a way to speed up work when I’m busy and not focused on this problem for hours at a time.

    Using Claude for Help

    This felt like a “chat” thing, so I picked the chat item in Claude desktop and gave it context: my dab call the error, the fact the proc executes in the correct security context. I got this back. Claude response in Italics.

    Ugh. Me see problem. Flag wrong. No shaman flag call “–parameters.name” exist. Fake flag. DAB no understand.

    Real flag call –source.params. Fix like this:

    Note: I’ve set Claude to talk like a caveman for now, which reduces output.

    I pasted in the doc page, and then got this:

    2026-07_0275

    The more interesting part of the response was Claude noting that sp_describe_first_result_set is called and needs a good response. I hadn’t thought about this, so I decided to run it. I have the response to claude and it evaluated this as correct.

    It next suggested adding dev mode (already on, it didn’t have my whole config) and turning the log level up. That’s a good idea. It also asked me for the section of the config file to be sure the proc was in there correctly.

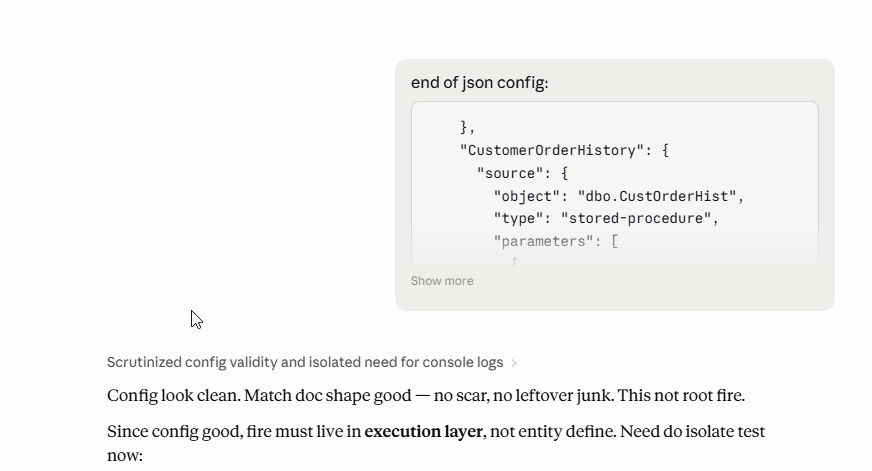
    I did all those things. It verified my config blocked was correct.

    2026-07_0277

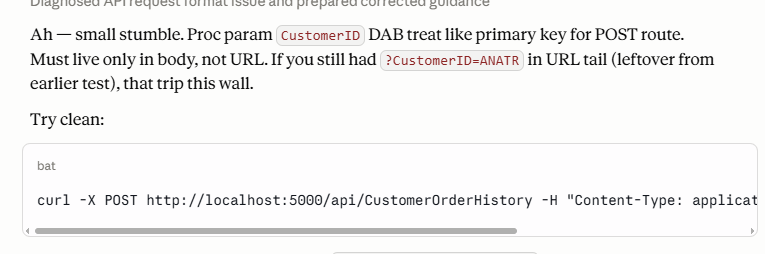
    Claude then asked me to try both the REST and GRAPHQL APIs and gave me the code for those. I pasted the error in and it suggested that I might have an issue with the URL code I used in Bruno. Maybe, but worth a try. It gave me the CURL command.

    2026-07_0278

    The Solution

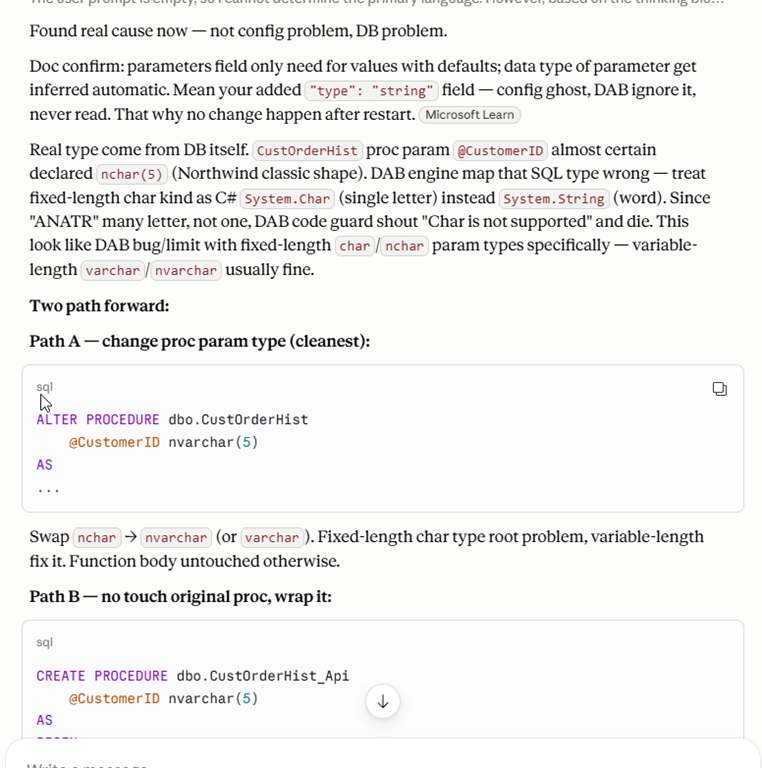
    It was at this point that I started to realize the issue. The proc that wasn’t working used an NCHAR() as a parameter. The DAB call expects string. It gave me this response and an example of the code for my config file.

    CustOrderHist proc expect nchar(5) param, but DAB parameter type system only know few kind: string, number, boolean, etc — no raw “char” concept. Missing "type" field make DAB fall back some default guess (maybe try char/byte path), boom, exception.

    Add "type": "string", restart engine (dab start again — config file, not hot reload), fire query/POST again. String type push CustomerID as varchar/nvarchar-like, proc side (nchar) accept fine via implicit convert.

    I changed things and tried it, but it wasn’t working. We upped the debug level and I pasted in results, which are annoying to go through. DAB doesn’t include a timestamp (I opened an issue) so I had to sort through the output to find the log items.

    I pasted in the logs and then Claude found the issue. It explained things, which I don’t care about since this is an API thing. However, it gave me a couple of choices for fixes. I changed the parameter in the proc, which isn’t a tiny change, but it’s also not a big change.

    2026-07_0279

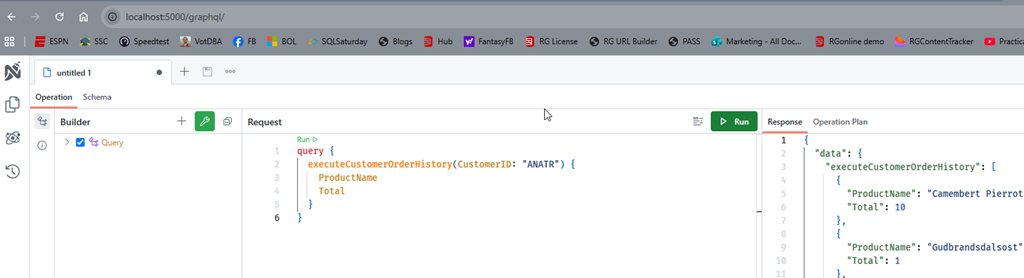
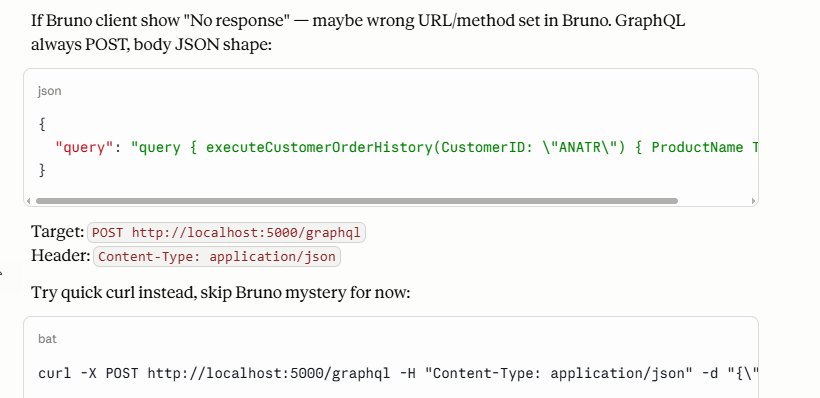
    It didn’t work at first, but when I pasted in my query, it recognized that BRUNO might be an issue.  The response explains this and says to try CURL. I did, but I also realized that my GraphQL command was a GET, not a POST.

    2026-07_0280

    This worked, and I tried a few more stored procedures to verify I had an idea of what to do.

    Summary

    There wasn’t anything amazing that Claude did here, but I approached this as if I were struggling with a problem and asked a colleague. I was a little shorter than I might be in Slack messaging or email, but I was really dumping some results on a co-worker and letting them sift through things.

    What was most amazing was that I had a few other things happening at this moment and I’d focus on this for an experiment and then let Claude examine logs while I went to try something else, edited my GraphQL queries or even answered an email. I solved the problem with help, but wasn’t spending a lot of focused time because I had an assistant.

    This is something I do more and more. Let me assistant do something and come back. I’ve struggled with this problem for months since I didn’t have a lot of continuous hours to spend digging through logs and docs. Not sure I’ve even seen this particular solution come up in my Google searches, but certainly Claude made it easier than it has been previously.

  • Day of Data Baton Rouge Slides and Code

    Thanks to everyone for attending my talk today at Day of data Baton Rouge 2026 (formerly SQL Saturday Baton Rouge).

    The slides are here: Building an API with DAB – Baton Rouge

    The repo for the code and demos is here: DAB-Experiments

    Use the Getting Started folder for the setup and demos as batch files. This is for SQL Server with a user set as JoeUser. Change this in the .env file if you want to alter this. I use Northwind, with a few additions in the .sql files.

    Apologies, it’s not completely organized as I am still working on the flow and structure. feel free to reach out with questions.