Tag: career

  • The Poor Soul

    This editorial was originally published on May 11, 2011. It is being re-run as Steve is away at SQL in the City.

    I recently had someone post this after I made a comment about someone taking responsibility for their database server.

    “So Steve, what would you recommend then for those poor souls?  As being one of them it drives me nuts to constantly be told I can’t get more training as it’s not my true job position yet I’m responsible for making the databases work. “

    I’ve been in this spot a few times, in and out of IT. I’ve been tossed into cooking or bartending jobs without training and had to learn quickly how to do the job, and I’ve had the same thing happen in IT. In a few cases the companies knew it was a bad situation and they eventually got me training, in others they didn’t. Here’s the advice I have for you.

    Ultimately you are responsible for the job. Tough love, but you’re being paid for that job, so you are responsible.  That means you have to learn how the technology in your environment works and how to solve the problems you have.

    First, get your resume up to date. Make sure it is ready for submission, and you are prepared to get fired every week.  Keep an eye on the job market and save some extra money, because to me, the financial security for my family comes first.

    Second, learn to restore data and then make sure you have backups in place. This is secondary because if you have a failure quick, you want to be ready to get a new job. But ultimately no matter what breaks or doesn’t work, getting data back first is crucial.

    As you go through all of this, you might be fighting fires. So while you practice restores or document the environment, you might be trying to fix things and asking questions of others, but invest the time to get yourself into a solid position.

    I’d also talk to my boss regularly. Every time I found a place I didn’t know something, I’d make a note and let my boss know this is a hole. Maybe I can learn it, maybe I can’t, but I could use help. That might be the best ROI for conferences. Go, make friends, get contacts that can fill your knowledge holes. Or find consultants you can call.

    Steve Jones

  • Choosing Your Tasks

    This editorial was originally published on May 13, 2011. It is being re-run as Steve is out of town.

    I have been working for SQLServerCentral for nearly a decade. I started in 2002 and in that time I have had to define my own job most of the time. Early on Andy and Brian had a list of things they thought I should be doing, and there were certain things to get done each week, but it was a general list.

    This Friday I thought this was a topic for a good poll. Answer this question:

    What percentage of your time is self-directed?

    By self-directed I mean the tasks that you choose to do because you think they need to be done for some reason. This is opposed to the specific tasks that someone assigns you and gives you some deadline for finishing. If someone asks you to “tune the server”, I don’t consider that a specific task, and you would have to pick items to work on, and determine how much time you spend on them, that’s a self-directed task.

    Do you have a good amount of self-directed time? When I used to manage a series of production servers, I usually had at least half my time as self-directed time. I could look at poor running queries, contact groups with proactive ideas for improving performance or preventing problems. I even had time to schedule DR testing. That took a lot of investment over time. I had to understand each system, set up monitoring and standards, build in data capture and analysis routines, and of course, plenty of alerting mechanisms.

    I think that a great production DBA will have a lot of self-directed time after 6-12 months on the job. A development DBA, however, will likely be constantly responding to code requests and enhancements, which is one reason I prefer the former job.

    Steve Jones

  • Are you a Data Scientist?

    It seems that there’s no shortage of re-branding attempts being made in all industries and by all types of people. I still remember when most of us were called computer programmers instead of developers. Not many people writing C# or Java code would want to be called “programmers” today.

    One of the latest fads is the call for more data scientists to work on big data, another equally, poorly defined term. However it seems that he definition of what a data scientist is has been so ill defined that almost anyone that can write a query using aggregates might define themselves as a data scientist.

    A good thing if you are looking for a job. Many of you might find opportunities (and raises) if you convince a hiring manager that you are a data scientist. However I’d be wary of living on just the new brand without growing your skills. If your company comes to expect more, especially with regards to advanced statistical analysis, you might find yourself in a bind.

    I ran across a piece that looks at the skills that a data scientist might actually need. I don’t know how many managers might understand the difference between simple discrete rules engines and more subtle, complex, multi variable, adaptive algorithms, but there can be a big difference in how well the system actually performs for your company.

    No matter what you choose for your carer, I’d certainly encourage you to continue to learn more about how to work with data. Whether you want to learn more about statistics, pick up R, or improve your visualization skills. Keep Learning. Keep your brain active and work to improve before you find yourself without a job and in need of training. Every little bit you learn helps and the practice of continuous improvement builds a habit that will serve you well over time.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.7MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • Exercism

    I’ve been looking to work on my programming skills a bit and try some new languages. I’d like to grow my career in a few different ways, as well as investigate where some of the new languages and platforms might be useful for data analysis. As I’ve talked to some developers and been looking around, someone recommended Exercism.io.

    Exercism.io is a site that allows you to practice coding exercises and get feedback from others. When you visit the site, it’s an interesting look, and invites you to log in through GitHub. If you’re not a member of GitHub, and you’re a developer, you probably are making some sort of mistake.

    2015-09-14 11_36_06-exercism.io

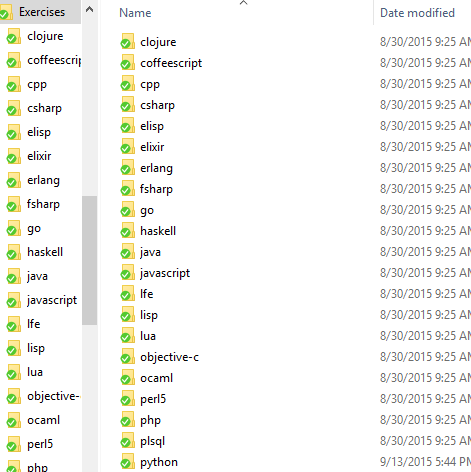
    Once you log in, you really need to download the command line client and execute it. Once you do, you can configure it to connect and download exercises. Each of these is placed in a folder, as shown:

    2015-09-14 12_41_27-Exercises

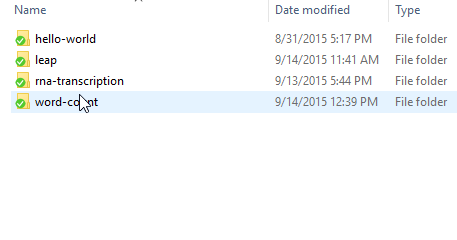
    For each of these languages, you get an exercise that you need to complete in that language. I’ve been playing with Python, and I had a first exercise of hello-world. In the python folder, were my exercises (you can see I’ve moved on).

    2015-09-14 12_41_38-python

    The hello-world folder had a read me and a test file (it’s since gotten my program in there). The Readme has instructions and the test file is a set of tests that can be executed to check your program.

    2015-09-14 12_46_15-hello-world

    When you pass the tests, you submit your solution from the command line client. The submissions appear on the website and people can comment on your code. I am in no way commenting on any else’s Python code at this point, but I did get a comment on my leap year calculation.

    2015-09-14 12_46_26-exercism.io

    I looked over the comment and then changed some code. I had to futz with the command line to get this to resubmit, but as you can see, I ended up getting a second iteration in there. No comments on that one, but we’ll see.

    It’s an interesting idea to share code and get comments. I think mostly this is a way to formally practice some exercises and get comments from experienced users, but the volume means that potentially you won’t get comments on your solutions. I know many of the SQL users may, or may not, comment on solutions.

    I think this is interesting, and I’m tempted to try to do something like this for SQLServerCentral. The hard part of putting together enough questions that others can practice in an organized fashion.