Tag: career

  • Choosing Your Tasks

    This editorial was originally published on May 13, 2011. It is being re-run as Steve is out of town.

    I have been working for SQLServerCentral for nearly a decade. I started in 2002 and in that time I have had to define my own job most of the time. Early on Andy and Brian had a list of things they thought I should be doing, and there were certain things to get done each week, but it was a general list.

    This Friday I thought this was a topic for a good poll. Answer this question:

    What percentage of your time is self-directed?

    By self-directed I mean the tasks that you choose to do because you think they need to be done for some reason. This is opposed to the specific tasks that someone assigns you and gives you some deadline for finishing. If someone asks you to “tune the server”, I don’t consider that a specific task, and you would have to pick items to work on, and determine how much time you spend on them, that’s a self-directed task.

    Do you have a good amount of self-directed time? When I used to manage a series of production servers, I usually had at least half my time as self-directed time. I could look at poor running queries, contact groups with proactive ideas for improving performance or preventing problems. I even had time to schedule DR testing. That took a lot of investment over time. I had to understand each system, set up monitoring and standards, build in data capture and analysis routines, and of course, plenty of alerting mechanisms.

    I think that a great production DBA will have a lot of self-directed time after 6-12 months on the job. A development DBA, however, will likely be constantly responding to code requests and enhancements, which is one reason I prefer the former job.

    Steve Jones

  • Are you a Data Scientist?

    It seems that there’s no shortage of re-branding attempts being made in all industries and by all types of people. I still remember when most of us were called computer programmers instead of developers. Not many people writing C# or Java code would want to be called “programmers” today.

    One of the latest fads is the call for more data scientists to work on big data, another equally, poorly defined term. However it seems that he definition of what a data scientist is has been so ill defined that almost anyone that can write a query using aggregates might define themselves as a data scientist.

    A good thing if you are looking for a job. Many of you might find opportunities (and raises) if you convince a hiring manager that you are a data scientist. However I’d be wary of living on just the new brand without growing your skills. If your company comes to expect more, especially with regards to advanced statistical analysis, you might find yourself in a bind.

    I ran across a piece that looks at the skills that a data scientist might actually need. I don’t know how many managers might understand the difference between simple discrete rules engines and more subtle, complex, multi variable, adaptive algorithms, but there can be a big difference in how well the system actually performs for your company.

    No matter what you choose for your carer, I’d certainly encourage you to continue to learn more about how to work with data. Whether you want to learn more about statistics, pick up R, or improve your visualization skills. Keep Learning. Keep your brain active and work to improve before you find yourself without a job and in need of training. Every little bit you learn helps and the practice of continuous improvement builds a habit that will serve you well over time.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.7MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • Exercism

    I’ve been looking to work on my programming skills a bit and try some new languages. I’d like to grow my career in a few different ways, as well as investigate where some of the new languages and platforms might be useful for data analysis. As I’ve talked to some developers and been looking around, someone recommended Exercism.io.

    Exercism.io is a site that allows you to practice coding exercises and get feedback from others. When you visit the site, it’s an interesting look, and invites you to log in through GitHub. If you’re not a member of GitHub, and you’re a developer, you probably are making some sort of mistake.

    2015-09-14 11_36_06-exercism.io

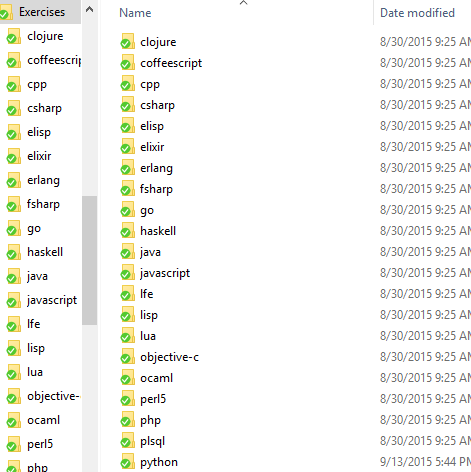
    Once you log in, you really need to download the command line client and execute it. Once you do, you can configure it to connect and download exercises. Each of these is placed in a folder, as shown:

    2015-09-14 12_41_27-Exercises

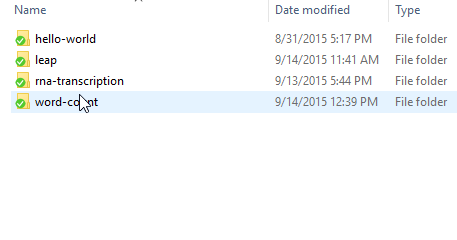
    For each of these languages, you get an exercise that you need to complete in that language. I’ve been playing with Python, and I had a first exercise of hello-world. In the python folder, were my exercises (you can see I’ve moved on).

    2015-09-14 12_41_38-python

    The hello-world folder had a read me and a test file (it’s since gotten my program in there). The Readme has instructions and the test file is a set of tests that can be executed to check your program.

    2015-09-14 12_46_15-hello-world

    When you pass the tests, you submit your solution from the command line client. The submissions appear on the website and people can comment on your code. I am in no way commenting on any else’s Python code at this point, but I did get a comment on my leap year calculation.

    2015-09-14 12_46_26-exercism.io

    I looked over the comment and then changed some code. I had to futz with the command line to get this to resubmit, but as you can see, I ended up getting a second iteration in there. No comments on that one, but we’ll see.

    It’s an interesting idea to share code and get comments. I think mostly this is a way to formally practice some exercises and get comments from experienced users, but the volume means that potentially you won’t get comments on your solutions. I know many of the SQL users may, or may not, comment on solutions.

    I think this is interesting, and I’m tempted to try to do something like this for SQLServerCentral. The hard part of putting together enough questions that others can practice in an organized fashion.

  • Data Sprawl

    When I was starting in the computer industry, it seemed that we had many choices for platforms, but once we had decided on a direction, the companies I worked for standardized on those systems. It seemed that there was less interoperability between vendors, or even subsets of products from those vendors.

    That’s changed and these days I see products from different hardware vendors, different OSes, different development languages, even different database platforms being co-mingled and mixed throughout all sizes of companies. I see developers moving from Windows to OSX to Unix without a blink and data professionals going from SQL Server to MySQL to Hadoop easily.

    Well, maybe not easily. Certainly there are challenges in learning how MySQL operates differently from SQL Server, which is a long way from the import and processing of data in NoSQL systems. However I do see some SQL Server professionals rising to the challenge and learning to work with these disparate technologies.

    It seems to me that many of us in the future will need to develop multiple skill sets with different technologies just to be effective. Many of our companies will continue to deal with more data sprawl as not only will data be stored in RDBMSs and Excel, but we’ll get cloud services, NoSQL systems, and more that contain sets of data our organizations want to combine together.

    We have seen XML and Hadoop integration in the SQL Server platform, with both R and JSON coming in SQL Server 2016. While I don’t know that any of these will come to dominate data analysis, I do think that it will behoove data professionals to be sure they keep their ability to learn sharp by experimenting with new technologies and growing their skills. Your company might not use Hadoop (or any new tech), but if you don’t learn about it, you won’t know if it meets a need you have.

    However, even if you don’t decide to use the technology, the effort spent learning about it will not be wasted. Your brain will be more flexible, and you’ll have less anxiety if you’re asked to take a look at a new technology, maybe graph databases, something that is probably wildly different from anything you’ve ever used.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.6MB) podcast or subscribe to the feed at iTunes and LibSyn. feed