Tag: Flyway

  • The Four Different Types of Flyway Files

    This is documented, somewhat, but I wanted to put this down for myself, as the I don’t love the docs and they are hard to sort through.

    Flyway is open source software owned and maintained by Redgate, my employer. There are also paid versions with additional features.

    The Main Files

    There are essentially 4 different types of files you can use for scripts in Flyway. These are:

    • versioned scripts
    • repeatable scripts
    • baseline scripts
    • undo scripts

    I’ll discuss each of these in light detail below. This isn’t intended to replace the documentation, but give a short explanation of each.

    For each type of file, there is a naming standard, which is the same for all. Essentially, there is are four parts. As an example, I’ll use V8.2__add_new_table.sql to explain this. The four parts are:

    • The prefix for the type of script, in this case, a V script.
    • The version. for my example this is 8.2.
    • The separator, always two underscores
    • The description, add_new_table, in my case.
    • The suffix, which is an extension

    Versioned Scripts

    These are the V scripts, which are named with a V to start. These are scripts which are run once on each target, and intended to be those that change the schema. The “V” is the default, but this can be configured. I wouldn’t change this.

    These are typically the CREATE or ALTER scripts that you run to change objects. You can have as much SQL code in here as you’d like. Think of these as a SQL Compare deploy script. One or my objects changes.

    The run once is nice because once you’ve deployed these, you don’t want to run them again. If you write idempotent scripts, you wouldn’t care but most people don’t do that well.

    Repeatable Migrations

    These are used less in the current Redgate paradigm, but these are repeatable scripts. They are designed to run every time you run “flyway migrate”. Again, the default is an “R” script, but this is configurable. Again, don’t change this.

    These scripts don’t have versions because they execute over and over. This could be used for creating or recreating programmable code objects, like view/procedures/functions/packages. They could also be used for places you need to ensure data is always there or has certain values.

    These scripts run after the migrate scripts, so be aware of that.

    Baseline Scripts

    By default, baseline scripts are “B” scripts. This can be changed. These scripts have a database version that you want to start with for some purpose. Like a new development effort or new deployment project.

    These are run for new environments only, and usually contain all the base objects you might need. If you start a Flyway project on a database that has objects, put all the code to recreate this state (CREATE objects and add data) in a baseline script.

    Undo Scripts

    The undo scripts are the “U” scripts. This can be changed, and these should have a version that matches a versioned script. We can run one of these scripts corresponding to those versions to “undo” changes. Since you can’t really undo anything in the database world, these should include code that reverses the action of the V script.

    Be careful with these, especially if you run these more than a few minutes after the V script. Flyway isn’t checking that you won’t lose data.

    I’d only use these after extensive testing in a pipeline and then only if my deployment broke immediately. These are good for putting in a previous version of a view/proc/function and quickly rolling back.

  • Flyway with Multiple Folders

    A customer asked about how they could organize their migration scripts in different ways to manage them and worried about it being complex. I decided to test a few things. This post looks at using multiple folders for scripts.

    Setup

    Flyway is controlled by a number of options. These can be in a configuration file or they can be passed into the command line. I’m lazy, and I like things self-contained, so I tend to drop things into the flyway.conf file and specify this in the command line.

    I’m also lazy about command lines, so I created a fw.cmd file with this in it:

    flyway migrate -configFiles=”./flyway.conf”

    Then I set up a few folders on my system. These were subfolders in a repo called SQL1, SQL2, SQL2. I know, I’m not creative. Here are the folders I set up. SQL1 has 3 scripts, each containing a CREATE TABLE statement. In this case, I am creating Table01, Table03, and Table04.

    2023-05-18 12_28_18-sql1

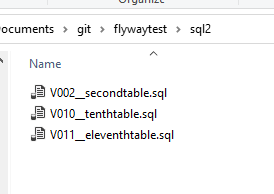
    I do something similar in SQL2, with table Table02, Table10, and Table11.

    2023-05-18 12_28_22-sql2

    SQL3 gets the 5th and 6th tables.

    2023-05-18 12_28_25-sql3

    I did this to check order of operations, as well as using multiple folders. For reference, each file looks similar to this, with numbers changed:

    2023-05-18 13_04_21-V010__tenthtable.sql - ARISTOTLE.foldertest (ARISTOTLE_Steve (60))_ - Microsoft

    I then edited my flyway.conf file. You can name this differently, you just need to pass the appropriate file to flyway when you execute it. By default, flyway.conf is looked for. I changed the variable for flyway.locations to be a comma separated list. In my case, I entered this:

    flyway.locations=filesystem:sql1, filesystem:sql2, filesystem:sql3

    Make sure you uncomment the # from the line.

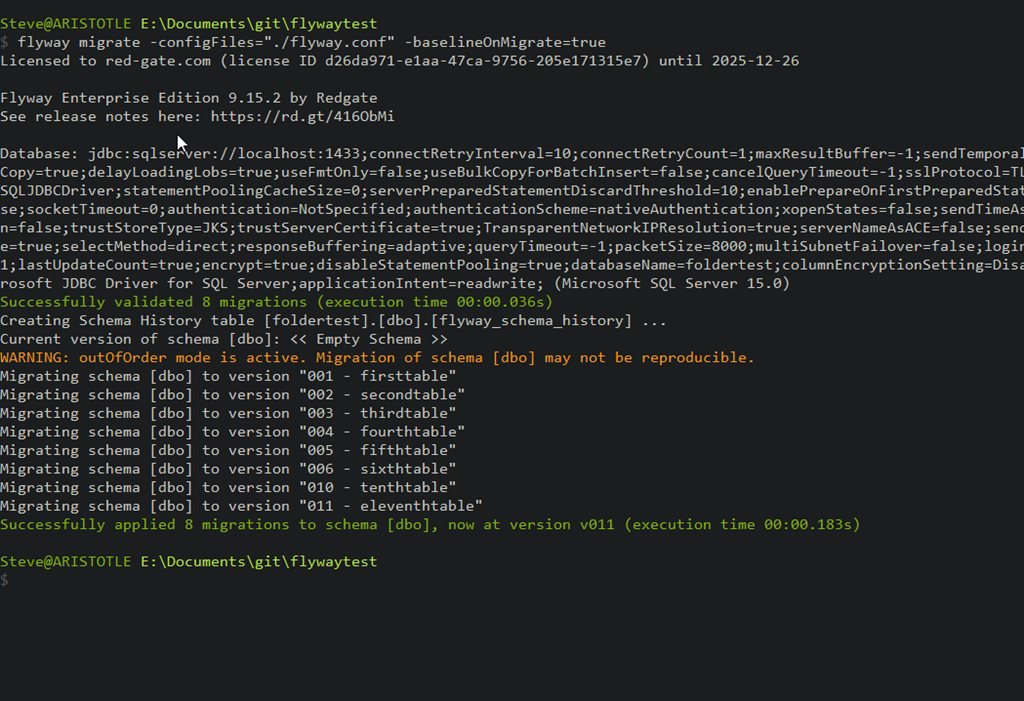
    Once this was done, I created an empty database, called foldertest. I then ran my fw command and saw this:

    2023-05-18 12_30_45-cmd

    Success, with all my tables created.

    Flyway is set up to search the locations path and load the files and execute them. You can organize your scripts into different subfolders if you want to, and flyway will sort out the ordering, if you’ve named them correctly.

  • Flyway Desktop PoC–Adding a Shadow and Baseline Script

    In the last post, I created a baseline marker for Flyway in each database. This set the version in the dev and QA databases to v1. However, I also need a baseline script, at least the tool asks for one, so this is the process if you have objects in your production or other downstream databases.

    I’ll do this for SQL Server and then PostgreSQL.

    Why do this?

    The main reason to create a baseline script is to note which objects already exist in production. For these objects, I don’t want to track these are changes in their current form.

    For example, if I already have a CountryCodes table in production, when I create a project, I want to tell Flyway Desktop that this table exists in production, so if the dev version matches, don’t add this to scripts. If it doesn’t, then I’ve done something in development and need an ALTER script deployed to prod.

    What was the Other Baseline?

    The first baseline in this post, is a version marker. I hate that this is the case, but both Flyway (pre-Redgate) and Flyway Desktop (evolved from SQL Change Automation), had the concept of a baseline, but these were somewhat different things.

    Flyway Baseline – The initial version of the database. Don’t deploy any scripts that are <= to this version.

    Flyway Desktop Baseline – A script that has the structure and code of all objects that exist in the target database(s).

    We can create a baseline script for Flyway, which looks for a B script, but the baseline command expects that you create this script manually. This is used to populate a new database with the baseline migration script prior to running all other scripts.

    Setting up the Baseline Script

    Flyway Desktop makes it easy to create a baseline script, and in fact, prompts you to do so.

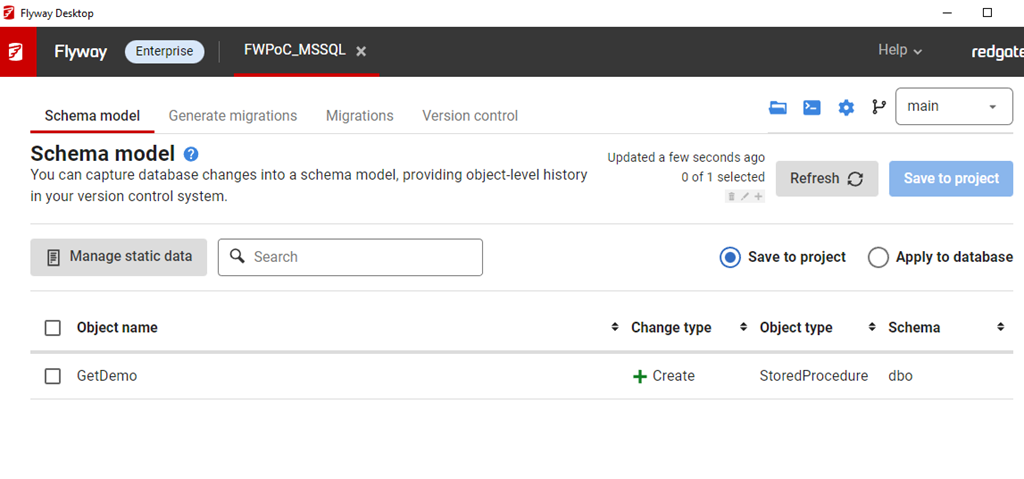
    In my project, if I go to the Schema Model (first) tab, I see there is an object in Development. This was the table I created when I set up the database. The goal is to get this table to other environments.

    2023-04-04 16_10_58-Flyway Desktop

    This table doesn’t exist in QA. I do have the flyway_schema_history table, which was the result of the baseline command.

    2023-04-04 16_15_58-SQLQuery4.sql - ARISTOTLE_SQL2022.FWPoc_1_Dev (ARISTOTLE_Steve (77))_ - Microsof

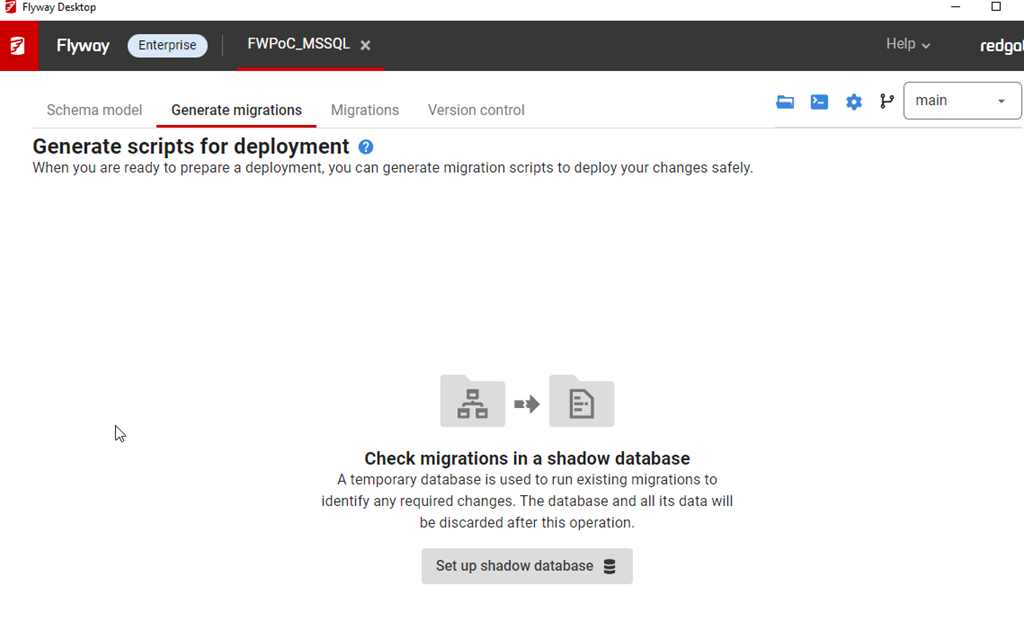
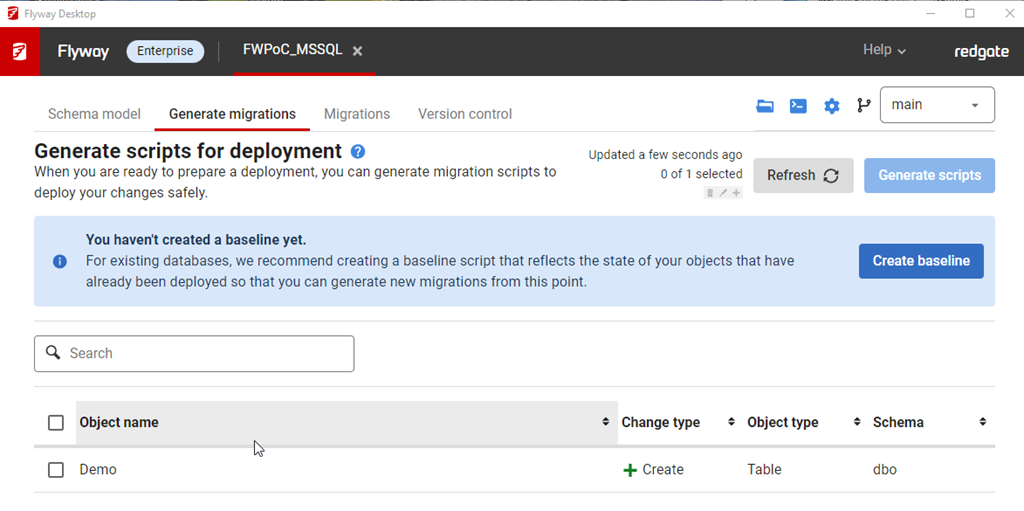
    If I go to the Generate Migrations (second) tab, I see this. The first thing that the tool wants is a Shadow database.

    2023-04-04 16_12_55-Flyway Desktop

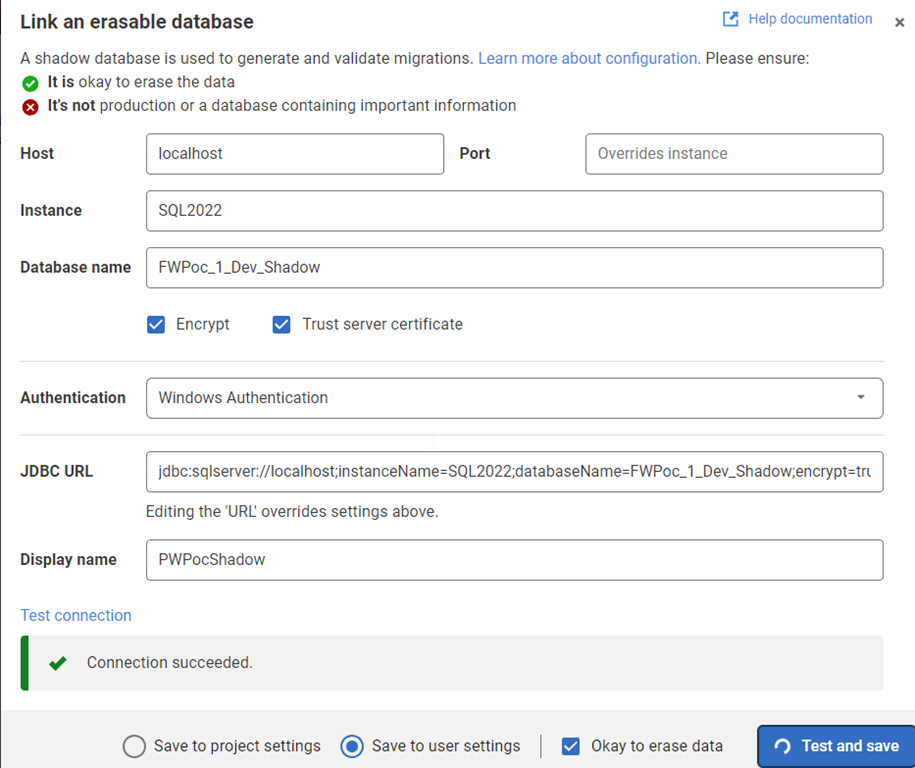
    The shadow is essentially a development V-1 (v minus one) version. This is where I test all migrations, compare the state with development, and then determine what’s changed. This is just a regular database, but I create this outside of Flyway Desktop. For me, I created a database (FWPoc_1_Dev_Shadow) and then clicked Set up shadow database to get this dialog. You can name this anything.

    I enter details, and test the connection before saving this. In general, this ought to be saved to my user settings as I’ll have my own shadow different from other developers. I DO NEED to click the “ok to erase data” box.

    2023-04-04 16_14_09-Flyway Desktop

    Once this is done, I now see another prompt on the Generate Migrations tab. Now I need a baseline script. I don’t have anything, but I will click the button.

    2023-04-04 16_14_28-Flyway Desktop

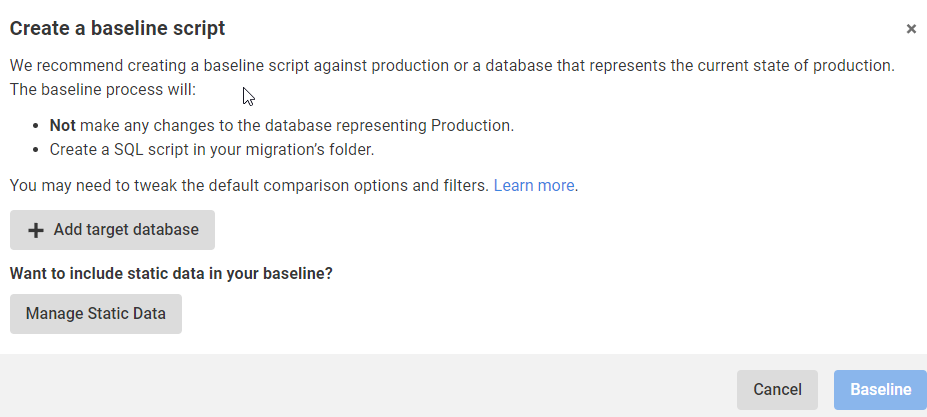
    This gives me a dialog to pick a target database. This target is used to get the initial set of objects to populate in the baseline script. You can use production or a copy (recommended) as the target database.

    2023-04-04 16_14_41-Flyway Desktop

    My QA is the same as prod, so I add that with the proper connection string and then I see the target here for the Baseline. I am ignoring static (or lookup/reference data for now). I’ll click the Baseline button.

    2023-04-04 16_15_25-Flyway Desktop

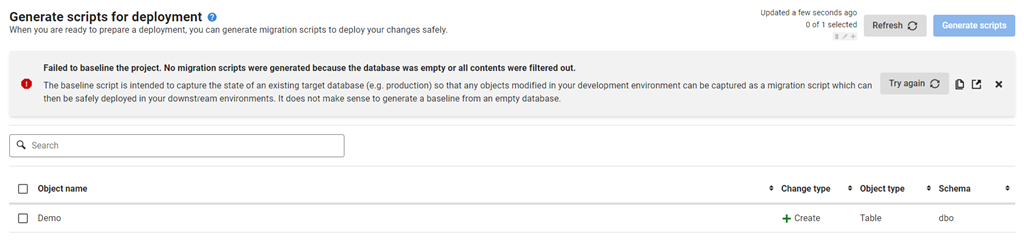
    This runs and … nothing.

    Which makes sense, as there is nothing in my target database. I actually get an error after this, which tells me that it doesn’t make sense to baseline an empty database.

    2023-04-10 12_38_51-Flyway Desktop

    I wish that were surfaced earlier. In any case, if I close this, I get the same image above, saying I don’t have a baseline. For now, I’ll ignore that.

    Summary

    Not much happened in this post. I added a shadow database, which I’ll use to generate scripts. I tried to baseline, but that errored, as it should. I really don’t need a baseline, so I’ll come back to this later in another format.

    For now, I’ve advanced the SQL Server project. I’ll actually repeat these steps for the PostgreSQL one, but it’s really creating a new database for the shadow and setting a connections string. Everything else looks the same.

    The next post will actually generate a script and deploy this to QA.

  • The Baseline for Flyway

    In my previous post, I set up the Flyway Desktop projects for SQL Server and PostgreSQL. I also added a table to each platform for development. In this post, I’ll look at how I let Flyway know what already exists in my system with a baseline.

    This is part of a series of working through Flyway and Flyway desktop to demo database changes. Disclosure: I work for Redgate Software

    Baseline v Flyway Baseline

    I find these terms to be slightly confusing, especially when I look at Flyway vs. Flyway Desktop. In Flyway, there is a “baseline” verb, which you can run at the CLI. This will mark the state of your database at a level and adds the flyway_schema_history table to the schema in which you are working. This baseline causes Flyway to ignore all migrations up to the baseline level.

    In my testing, when I run this on my database, it defaults to V1 for the first migration script. That’s usually fine, but as I wrote, this can cause issues.

    There is also the concept of a baseline migration, which is a Bxx script, and this contains the definitions of all the objects that already exist in your target databases. This ensures that as FW and FWD track and deploy changes, they don’t try to redeploy those migrations that are at a level lower than the baseline numbering (the xx).

    Creating a Baseline

    My development database for SQL Server looks like this:

    2023-01-25 14_27_21-Window

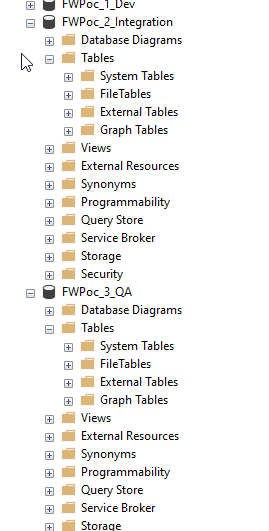
    There is an object in here, but it’s not in any other environment. Both Integration and QA (and the others) have no objects.

    2023-01-25 14_27_43-Window

    In this case, I don’t need a baseline script, because I want this table to deploy to the downstream databases.

    I do, however, need a baseline. I need the baseline marker in my databases to note that we have a base version. This will give me a starting point, but also ensure that FWD creates migrations that are numbered higher than my baseline.

    I’ll add this in two ways. One with Flyway Desktop and one with the Flyway CLI.

    The Flyway Baseline

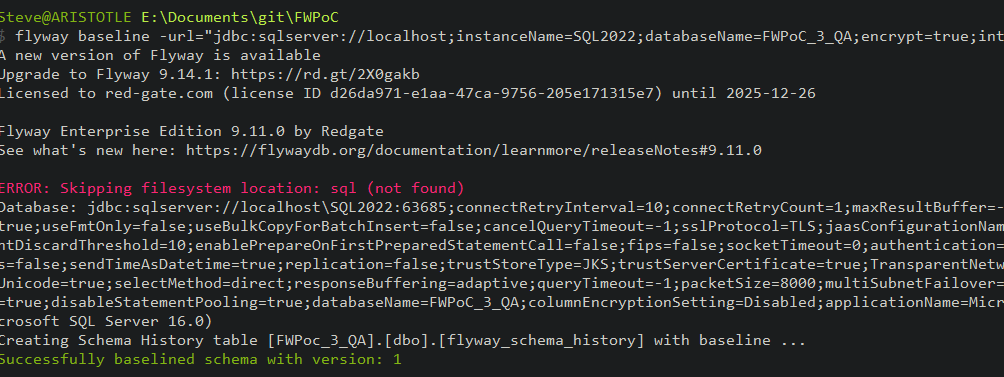
    For SQL Server, I don’t need to worry about any objects in downstream databases, so I’m just going to run the Flyway CLI. From a command line, I’ll run this code:

    flyway baseline -url="jdbc:sqlserver://localhost;instanceName=SQL2022;databaseName=FWPoC_1_Dev;encrypt=true;integratedSecurity=true;trustServerCertificate=true"

    This is run from my project location, though I’m passing in the connection string from Flyway Desktop as I don’t have a flyway.conf file configured for this project. Things work from the FWD gui, but not the CLI.

    This works, and I see these results. Note the flyway schema history table is created at the bottom, and the version of the database is set to 1.

    2023-02-08 08_55_37-cmd

    Now when I run Flyway info with that URL, I get this. There is an entry in the version tracking for this table:

    2023-02-08 08_56_03-cmd

    I can also see this table in my Object Explorer:

    2023-02-08 08_54_54-SQLQuery9.sql - ARISTOTLE_SQL2022.FWPoc_3_QA (ARISTOTLE_Steve (88)) - Microsoft

    Flyway Desktop and PostgreSQL

    I’m going to use FWD for my PostgreSQL project. This will do some of the work for me and give me the option for a baseline script.

    Note: I set up a shadow database first.

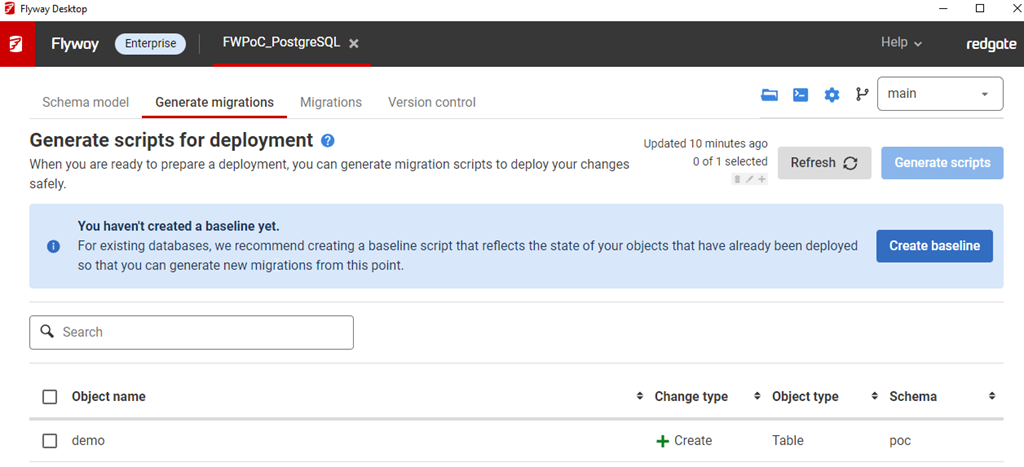
    2023-01-25 14_45_24-Window

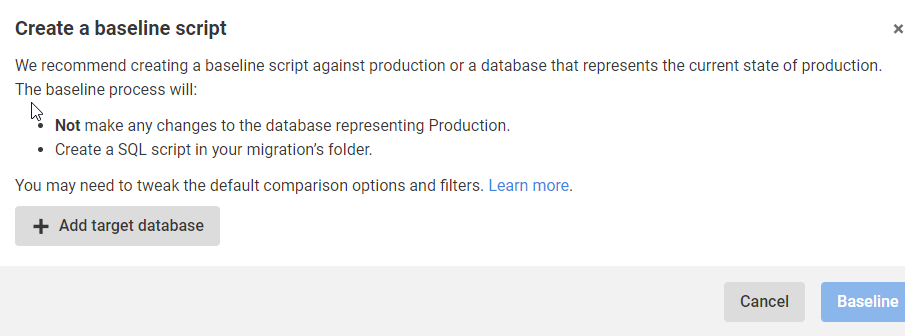
    I click “Create baseline” and this asks me for a target. After all, I’m trying to ensure I don’t deploy anything to prod that’s already there.

    2023-01-25 14_45_34-Window

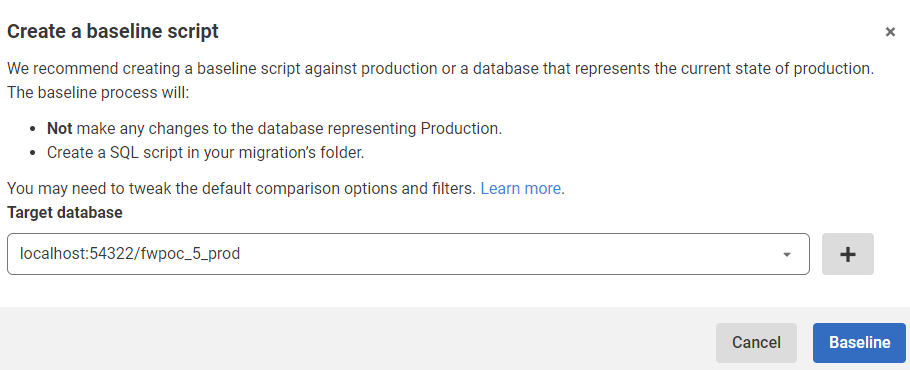
    When I click Add target database, I get a connection dialog. I fill this in with the credentials for prod. This returns me to this screen below, where I see my prod database, which is at this port with this name.

    2023-01-25 14_48_12-Window

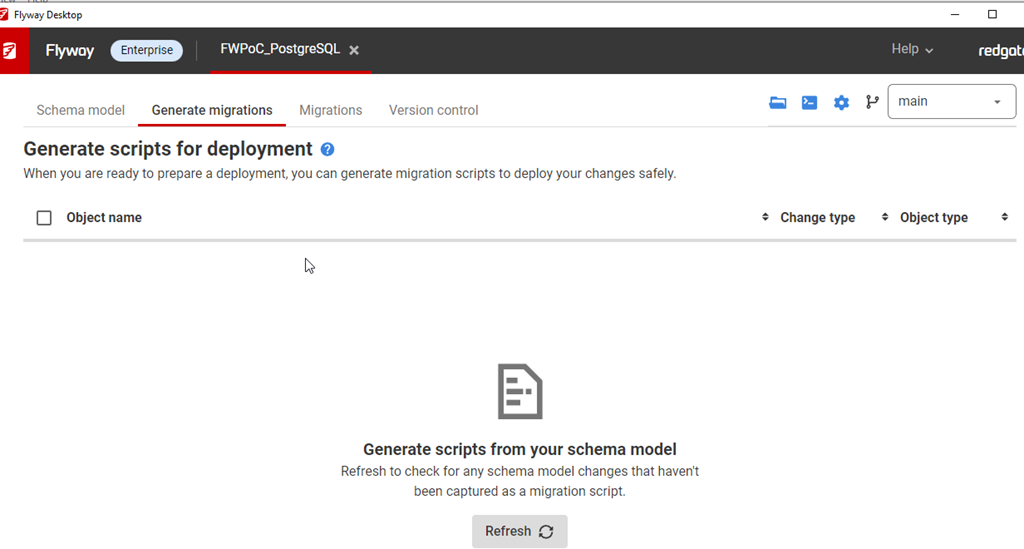
    I click Baseline and it goes to work. There’s nothing there, so this returns back to the blank, Generate Migrations tab.

    2023-01-25 14_49_02-Window

    However, there is no baseline or schema tracking table. I didn’t have a poc schema, so perhaps that’s an issue, but that’s OK. We can fix this.

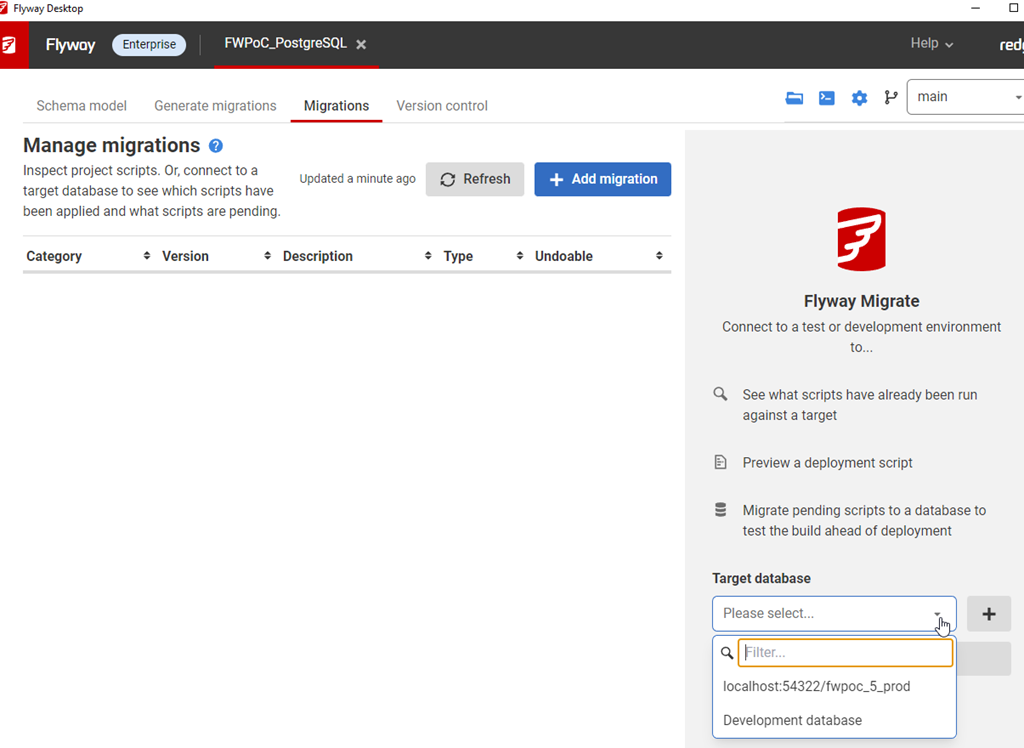
    In the Migrations tab, I see this:

    2023-01-25 15_10_52-Window

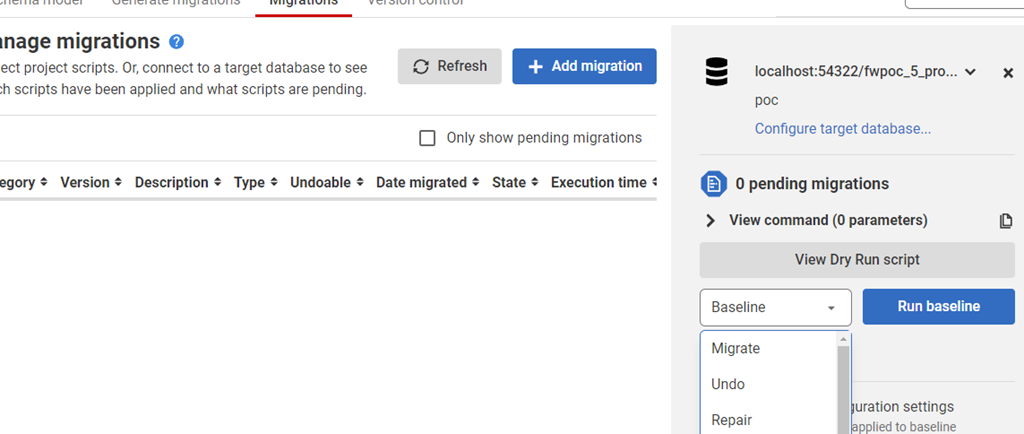
    That configures this tab to look at (and work with) this database.

    2023-01-25 15_10_44-Window

    In general, I know we won’t be able to see production, but this is a PoC. However, this is something that I, in general, don’t want to do. I want to work with dev/test environments, so let’s do that.

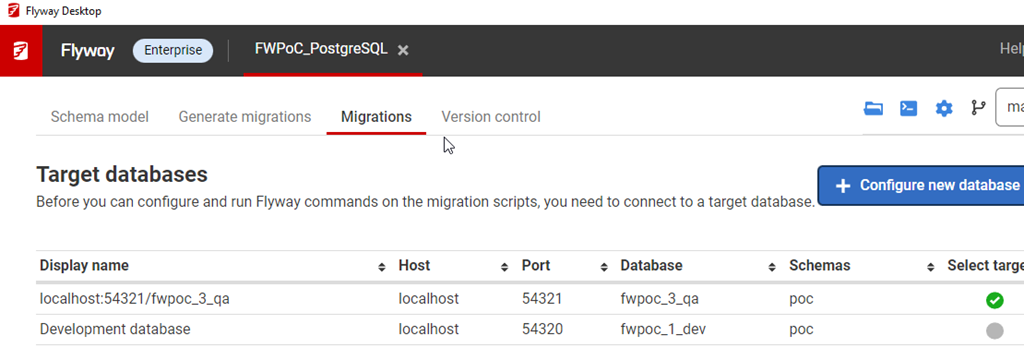
    I’ll configure my QA environment. I click “configure target database” and I get this screen. These are all the databases for my project. Here I’m going to click “delete” for production and then I’m going to click the Add and configure my QA database. Once I do that, I’ll see this:

    2023-01-25 15_14_52-Window

    Baseline added for PostgreSQL.

    2023-02-08 08_54_02-● SQLQuery_2 - localhost.postgres (postgres) - DBAScripts - Azure Data Studio

    Success.