Tag: Redgate

  • Using Data Masker on Chinese Surnames

    A customer had a question recently on masking Chinese characters. I thought that was interesting, so decided to test this out. This is a short post on using SQL Data Masker to accomplish this task, but I’ll a longer one on the Redgate Product Learning site.

    Setting Up A Table

    The first thing here was to get some test data. I was looking for Chinese names, since that was the request. I found this page on the most popular Chinese surnames. With that in mind, I build a small table and a few insert statements with this code. I only used the names Chén, Yáng, Zhào, Huáng, Zhōu, Wú, and one Western name for the demo

     CREATE TABLE dbo.CustomerFromChina
    ( customerid INT NOT NULL CONSTRAINT CustomerFromChinaPK PRIMARY KEY ,
       customersurname nvarchar(100)
    )
    GO
    INSERT dbo.CustomerFromChina
       (customerid, customersurname)
    VALUES
       (1, N'陈'),
       (2, N'杨'),
       (3, N'赵'),
       (4, N'黄'),
       (5, N'周'),
       (6, N'吴'),
       (7, N'Joe')
    GO

    I ran this and saw the results I needed.
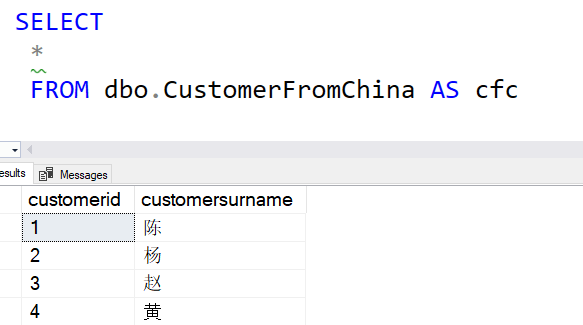
    query results with Chinese surnames

    Creating a New Data Set

    SQL Data Masker ships with a number of masking sets, but you can add your own. There is a process, but essentially you create a text file with the data in it and the udef extension.

    The masking sets are in Program Files below the Redgate folder. This is an administative folder, so you need to have admin rights to make a new file. I did that and opened my file in VSCode, which defaults to UTF-8 format. Since I want to use Chinese characters, I need to use a text file that supports unicode.

    I entered four names into my test file and saved it. You can see the entries here.
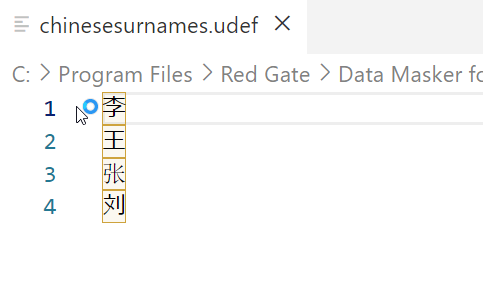
    2023-05-26 12_29_02-chinesesurnames.udef - Visual Studio Code

    I made the file name, chinesesurnames.udef. Make sure that this doesn’t have the .txt extension at the end.

    Setting The Masking Set

    I opened SQL Data Masker and created a new masking set. I connected this to my database and then went to the Misc. Setup tab. I didn’t see my set (I had this open), so I clicked “Refresh” at the lower left. This brought the data set into the list view. As you can see, I should have capitalized the file name.
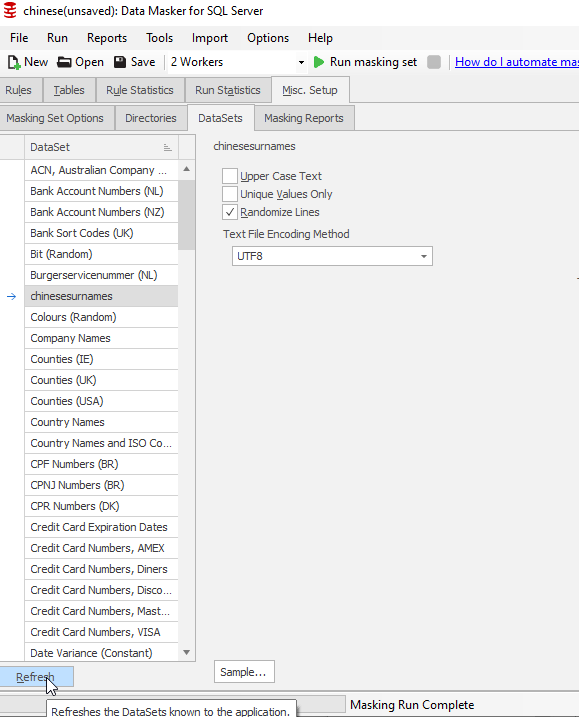
    2023-05-26 12_30_25-chinese(unsaved)_ Data Masker for SQL Server.

    If I clicked “Sample” at the bottom, I see my data:
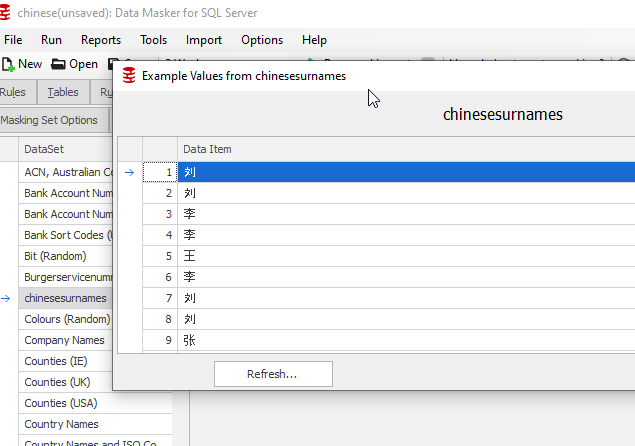
    2023-05-26 12_31_34-chinese(unsaved)_ Data Masker for SQL Server

    Note that the sample window shows a bunch of rows, but they are repeating the same four values.

    Next, I added a new Substitution rule. I picked the CustomerFromChina table and the ChineseSurname column. I also selected my custom data set. This is noted on the right of the image below.
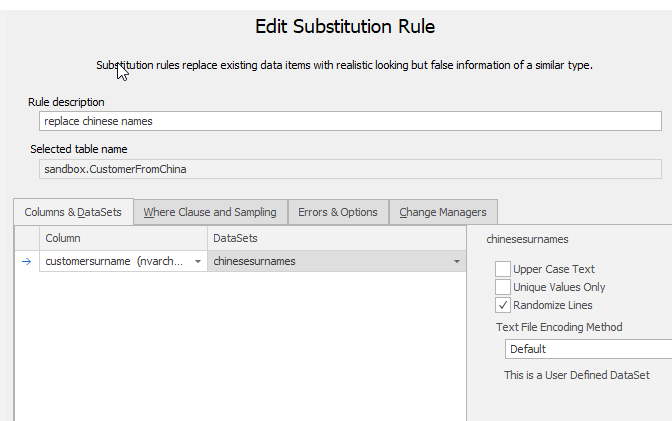
    2023-05-26 12_32_22-Edit Substitution Rule

    I saved this masking set and I was ready to test.

    Testing

    I first connected to the database and ran the query above in one window. Then I opened a vertical tab set, which moved this window to the right.

    Next, I ran the masking set, which was quick on 7 rows of data. I then opened a new query window on the left side of SSMS and ran the same query  I’d run on the right. You can see the results below:
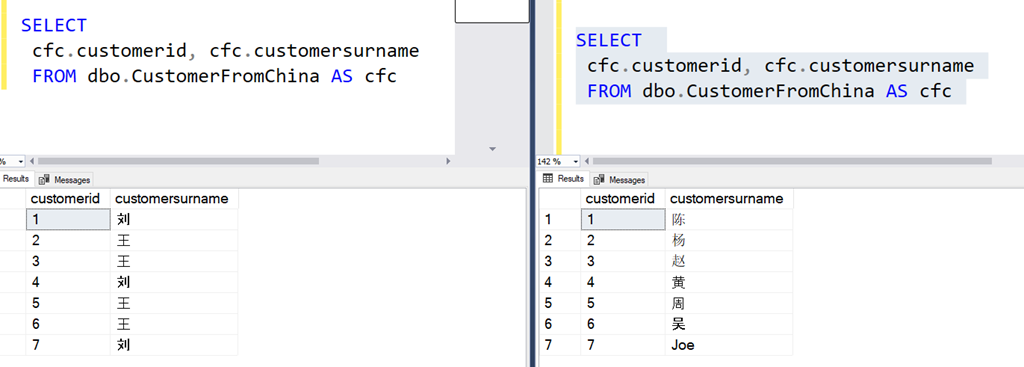
    2023-05-26 12_36_26-SQLQuery1.sql - ARISTOTLE.sandbox (ARISTOTLE_Steve (57))_ - Microsoft SQL Server

    In the image, the right has the original data. CustomerID 1 is Chén on the right, but on the left, this is now Liú. The others are also changed, with Joe also being masked to Liú.

    This worked.

    You can do the same thing with custom masking sets, in any Unicode format or language.

    SQL Data Masker is a great product for managing a set of update scripts that will remote PII data from a database. It is clunky, but it works well for building and updating a project across time and with a team. Way better than T-SQL scripts.

    Give it a try today.
  • Leveling Up for Sales and Marketing

    I’m heading to Austin today for Redgate’s internal Level Up conference. This is designed to help employees improve their skills in some way. The original ones focused on technology skills, but they have grown to include other business skills. A nice writeup from 2019 is here.

    This has traditionally been in Cambridge, UK, but last year we had an event in Austin. I couldn’t attend because of other commitments, and have actually never been to Level Up. Fortunately for me, there are actually a few events this year:

    • Level Up Sales and Marketing, US – May 2023, Austin
    • Level Up Sales and Marketing, UK – June 2023, Cambridge
    • Level Up Technical, UK – July, Cambridge

    This year, I’ll get to attend the first two, though not likely the third. I’d like to hit the technical talks, but I also have a lot of other trips and travel, so I have to pick and choose.

    I’m not speaking here. I speak a lot, and this is a chance for others to share their knowledge. I have offered to mentor and support others, and I ran a presentations tips and tricks session recently. Actually, I may do that in a few other places and record it.

    Having an internal conference isn’t cheap or easy, but it is a neat way to build bonds in the company and tailor training to what you need. I’ve been asked to speak at a few other companies’ conferences, and I’ve always enjoyed it.

  • Exporting SQL Data Compare Results to Excel

    I had someone ask recently about getting SQL Data Compare results in Excel. It’s easy to do and this post looks at the process.

    Exporting a Comparison

    I won’t go into the details of making a comparison. I have another post that looks at this with joins, but the tool is fairly intuitive (ingeniously simple) to use.

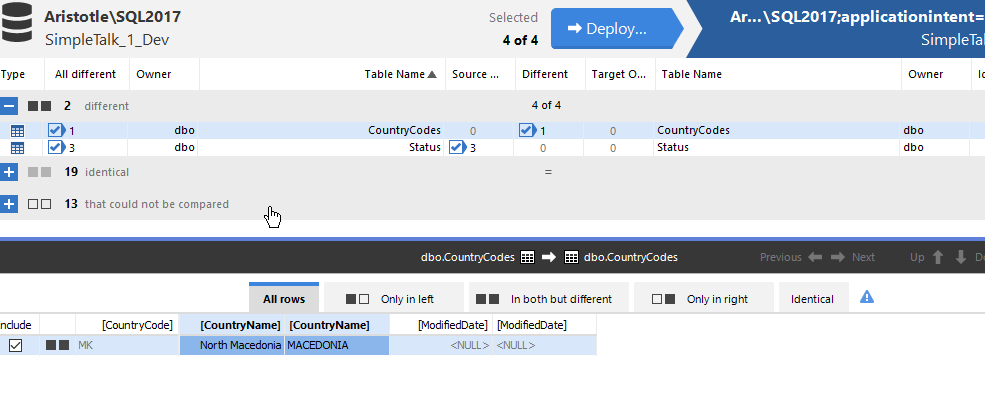
    Once you have a comparison, you should see something like this image. Here I have two tables that are different (I selected all tables). The first, dbo.CountryCodes, has a difference in a row, different values in the name.

    2023-04-14 13_47_56-SQL Data Compare - E__Documents_SQL Data Compare_SharedProjects_(local)_SQL2017.

    The second, dbo.Status, has some rows in the source (left) that are not in the target.

    2023-04-14 13_48_02-SQL Data Compare - E__Documents_SQL Data Compare_SharedProjects_(local)_SQL2017.

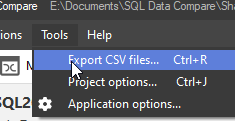
    To export these results, I use the Tools menu. There is an option you can see below:

    2023-04-14 13_48_08-

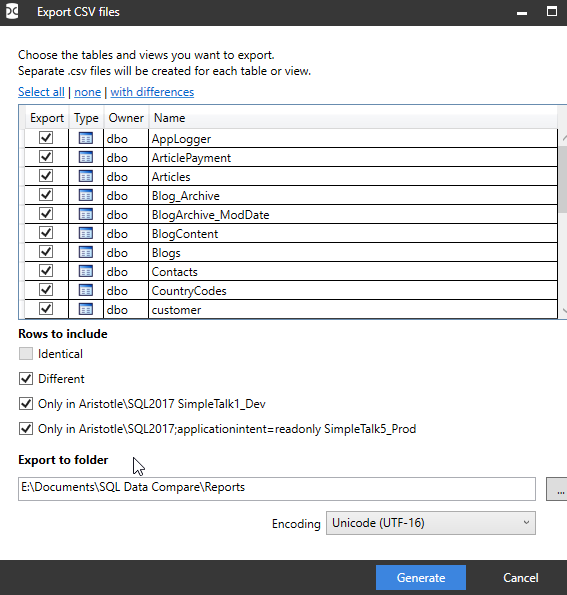
    Once I pick this, I get a dialog with options. I can pick certain tables, or all. The defaults are all tables, and only show differences. Note the identical button is not selected.

    2023-04-14 13_48_17-Export CSV files

    If I open the folder in the dialog above (after clicking Generate), I see my files. There are separate files for each table and one with a summary.

    2023-04-14 13_48_24-Reports

    If I double click the dbo.CountryCodes.csv file, Excel opens, but not the way I like it. I see this:

    2023-04-14 13_58_46-dbo.CountryCodes.csv - Excel

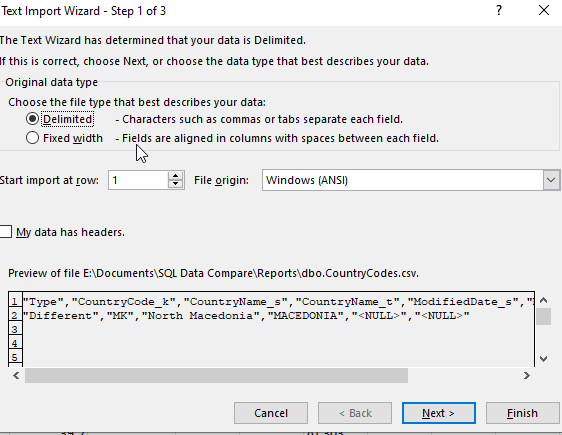
    However, if I File | Open the file, I get the wizard for delimited files.

    2023-04-14 13_59_00-Expenses 2023.xlsx - Excel

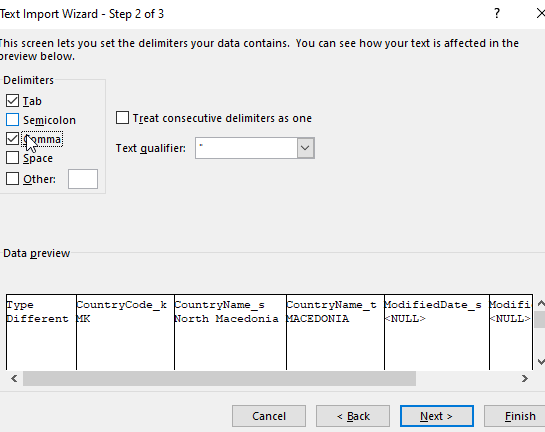
    When I go to the second page and click “comma” as the delimiter, I see a better preview.

    2023-04-14 13_59_05-Text Import Wizard - Step 2 of 3

    I can finish this and I see my data. In this case, the first column lets me know this is changed data that has the same row with the same PK in both databases.

    2023-04-14 13_59_22-dbo.CountryCodes.csv - Excel

    Similarly, I get open the Status table file and see this. Here the first column lets me know this data is only in the first database, the source or left database, that I set in my SQL Data Compare project.

    2023-04-14 13_59_50-dbo.Status.csv - Excel

    The summary also needs the same open process and this shows me all tables, with lots of zeros. However, for my two tables, you can see there is 1 row noted in the Different column for CountryCodes and 3 rows only in the source (SimpleTalk_1_Dev) database.

    2023-04-14 14_00_35-Results Summary.csv - Excel

    I can then save these in Excel format if I like and send them around to colleagues.

    Summary

    You’ve seen how you can review SQL Data Compare results in Excel. I don’t know if your Excel will open the CSV with values in separate columns, or if you need to perform a File | Open as I did.

    This is useful for sending to a business user that might need to make decisions about what data needs to be synched where. The hardest part here is explaining the _s and _t names for source and target.

    SQL Data Compare is very handy for single GB data sets to compare. I wouldn’t recommend this for > 10GB, but under that, with good hardware, you should have success comparing tables or views.

    If you’ve never tried it, download an evaluation today.

  • Flyway Desktop PoC–Adding a Shadow and Baseline Script

    In the last post, I created a baseline marker for Flyway in each database. This set the version in the dev and QA databases to v1. However, I also need a baseline script, at least the tool asks for one, so this is the process if you have objects in your production or other downstream databases.

    I’ll do this for SQL Server and then PostgreSQL.

    Why do this?

    The main reason to create a baseline script is to note which objects already exist in production. For these objects, I don’t want to track these are changes in their current form.

    For example, if I already have a CountryCodes table in production, when I create a project, I want to tell Flyway Desktop that this table exists in production, so if the dev version matches, don’t add this to scripts. If it doesn’t, then I’ve done something in development and need an ALTER script deployed to prod.

    What was the Other Baseline?

    The first baseline in this post, is a version marker. I hate that this is the case, but both Flyway (pre-Redgate) and Flyway Desktop (evolved from SQL Change Automation), had the concept of a baseline, but these were somewhat different things.

    Flyway Baseline – The initial version of the database. Don’t deploy any scripts that are <= to this version.

    Flyway Desktop Baseline – A script that has the structure and code of all objects that exist in the target database(s).

    We can create a baseline script for Flyway, which looks for a B script, but the baseline command expects that you create this script manually. This is used to populate a new database with the baseline migration script prior to running all other scripts.

    Setting up the Baseline Script

    Flyway Desktop makes it easy to create a baseline script, and in fact, prompts you to do so.

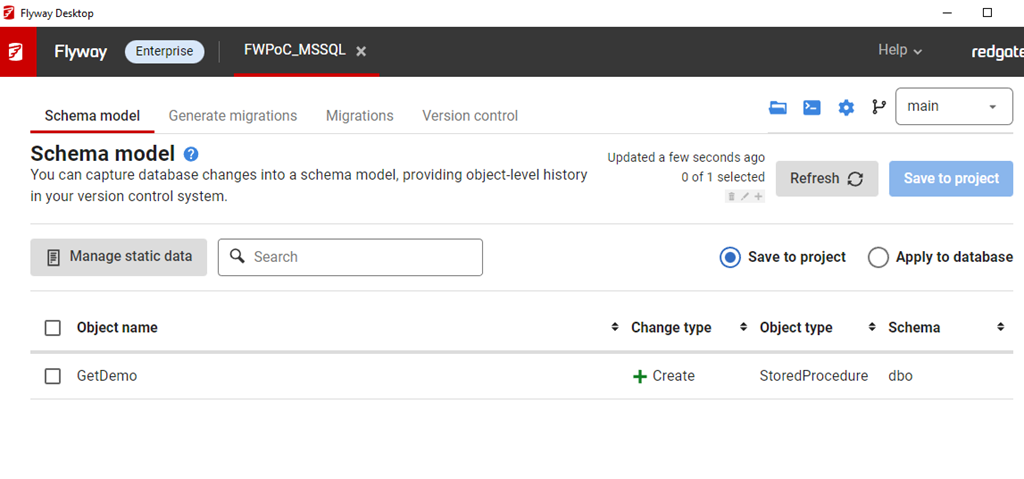
    In my project, if I go to the Schema Model (first) tab, I see there is an object in Development. This was the table I created when I set up the database. The goal is to get this table to other environments.

    2023-04-04 16_10_58-Flyway Desktop

    This table doesn’t exist in QA. I do have the flyway_schema_history table, which was the result of the baseline command.

    2023-04-04 16_15_58-SQLQuery4.sql - ARISTOTLE_SQL2022.FWPoc_1_Dev (ARISTOTLE_Steve (77))_ - Microsof

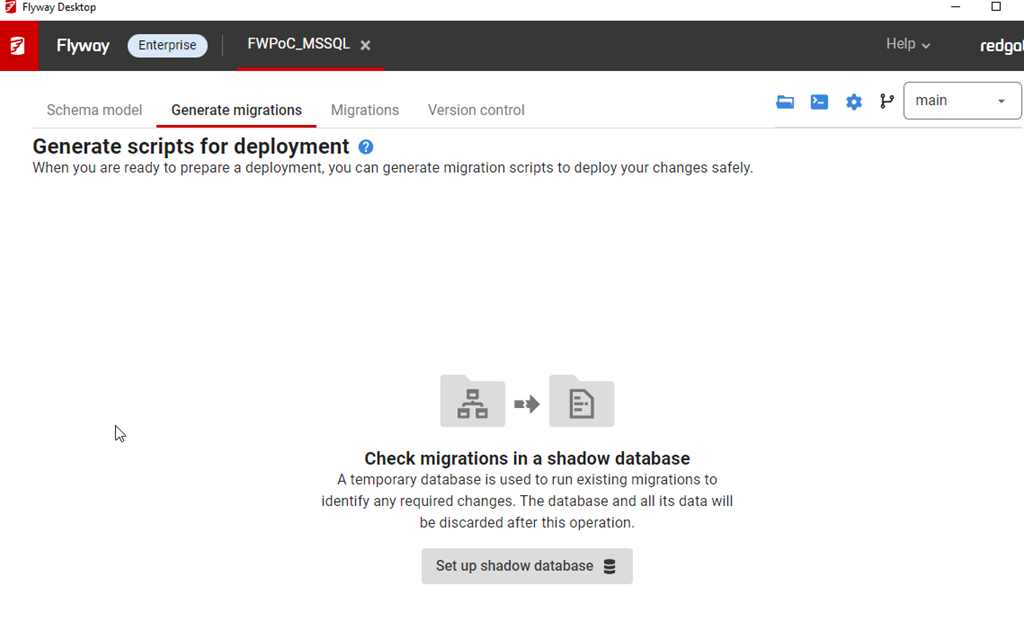
    If I go to the Generate Migrations (second) tab, I see this. The first thing that the tool wants is a Shadow database.

    2023-04-04 16_12_55-Flyway Desktop

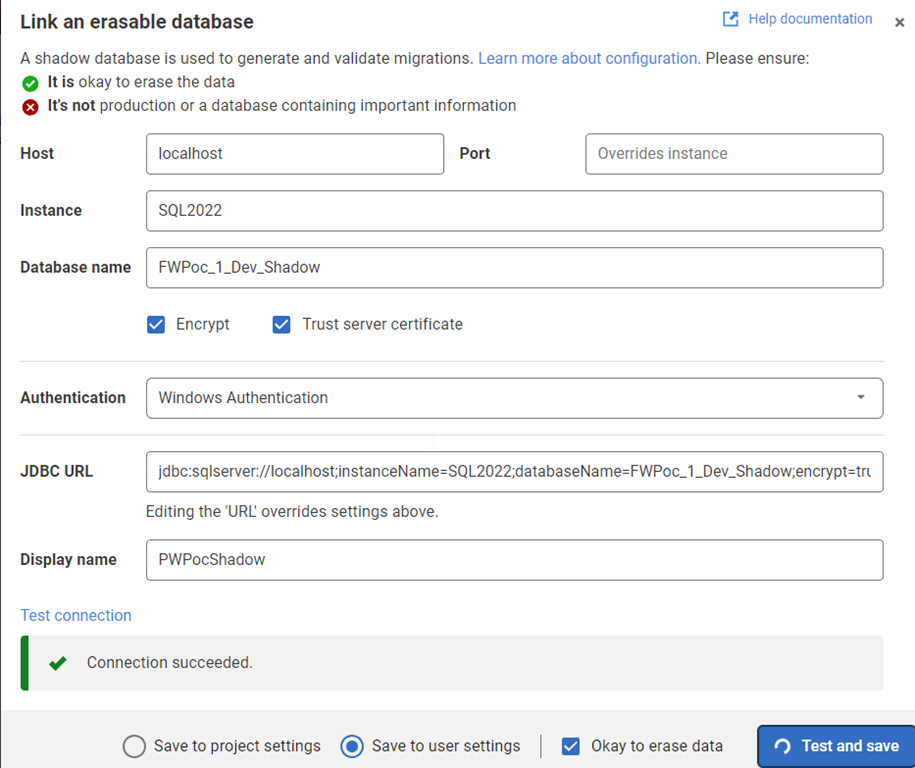
    The shadow is essentially a development V-1 (v minus one) version. This is where I test all migrations, compare the state with development, and then determine what’s changed. This is just a regular database, but I create this outside of Flyway Desktop. For me, I created a database (FWPoc_1_Dev_Shadow) and then clicked Set up shadow database to get this dialog. You can name this anything.

    I enter details, and test the connection before saving this. In general, this ought to be saved to my user settings as I’ll have my own shadow different from other developers. I DO NEED to click the “ok to erase data” box.

    2023-04-04 16_14_09-Flyway Desktop

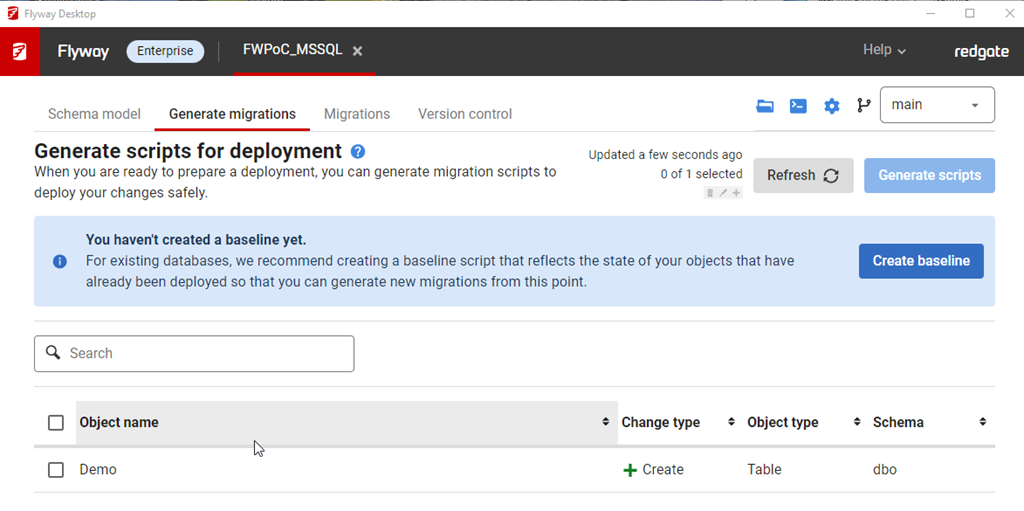
    Once this is done, I now see another prompt on the Generate Migrations tab. Now I need a baseline script. I don’t have anything, but I will click the button.

    2023-04-04 16_14_28-Flyway Desktop

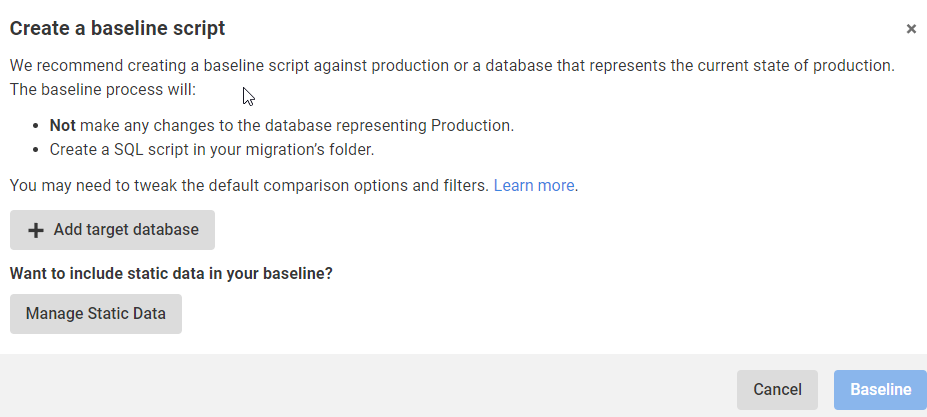
    This gives me a dialog to pick a target database. This target is used to get the initial set of objects to populate in the baseline script. You can use production or a copy (recommended) as the target database.

    2023-04-04 16_14_41-Flyway Desktop

    My QA is the same as prod, so I add that with the proper connection string and then I see the target here for the Baseline. I am ignoring static (or lookup/reference data for now). I’ll click the Baseline button.

    2023-04-04 16_15_25-Flyway Desktop

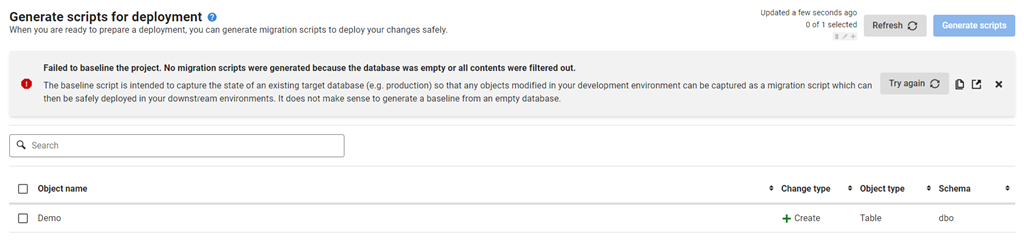
    This runs and … nothing.

    Which makes sense, as there is nothing in my target database. I actually get an error after this, which tells me that it doesn’t make sense to baseline an empty database.

    2023-04-10 12_38_51-Flyway Desktop

    I wish that were surfaced earlier. In any case, if I close this, I get the same image above, saying I don’t have a baseline. For now, I’ll ignore that.

    Summary

    Not much happened in this post. I added a shadow database, which I’ll use to generate scripts. I tried to baseline, but that errored, as it should. I really don’t need a baseline, so I’ll come back to this later in another format.

    For now, I’ve advanced the SQL Server project. I’ll actually repeat these steps for the PostgreSQL one, but it’s really creating a new database for the shadow and setting a connections string. Everything else looks the same.

    The next post will actually generate a script and deploy this to QA.