Tag: software development

  • Using AI for Git Hooks

    Recently I had someone internally ask about whether SQL Source Control supports Git Hooks. Since it was after UK work hours, I decided to run a quick test. One problem, I haven’t setup a Git hook in a few years.

    Could AI help me? See what I did.

    This is part of a series of experiments with AI systems.

    Asking for Help

    Claude is my go-to AI. I don’t have a good reason why I don’t lean on Copilot or ChatGPT or anything else, but I’ve become more comfortable with how Claude works and responds to me. When I have something that doesn’t have any PII or other sensitive requests, I tend to start with the free Claude site.

    Here was my prompt: what is an example of a git precommit hook

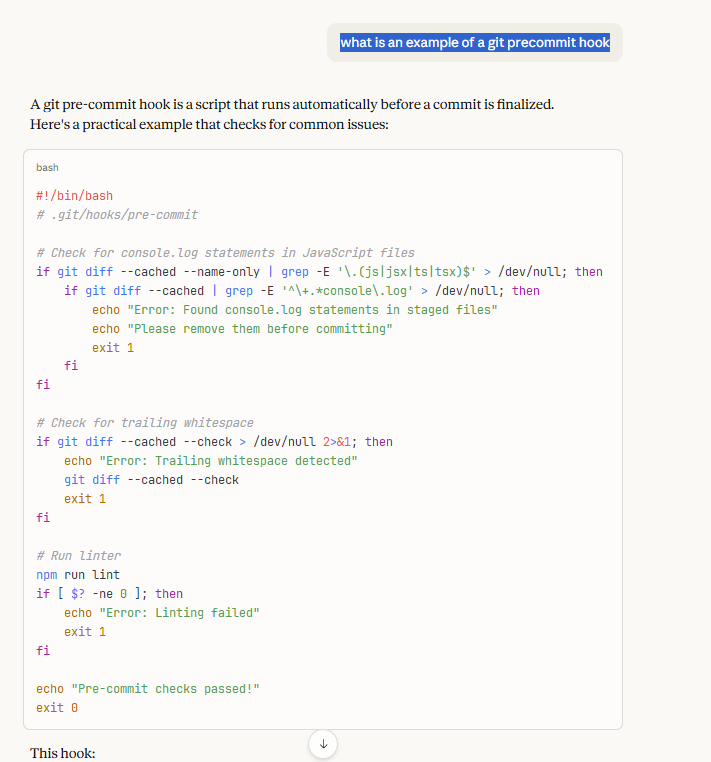
    Simple, easy, no punctuation or big setup. I just needed something. I got some code:
    2026-01_0150

    and an explanation. Here’s the’s the text of the explanation (italics from me):

    This hook:

    1. Prevents commits with console.log statements

    2. Catches trailing whitespace

    3. Runs your linter

    To set it up, save this as .git/hooks/pre-commit and make it executable with chmod +x .git/hooks/pre-commit.

    If the hook exits with a non-zero status (like exit 1), the commit is aborted. You can bypass hooks temporarily with git commit --no-verify if needed.

    Many teams use tools like Husky to manage hooks in a project, making them easier to share across the team since .git/hooks isn’t version-controlled by default.

    This shows some bash, which I don’t think runs natively in Windows. That makes sense as a lot of coders are likely using Linux/MacOS for complex stuff and the default training for Claude likely assumes that. I asked about Windows and got two options: Node.js and Husky. Since I don’t like to install things, I went with Node. Here’s the next question I asked.
    2026-01_0151

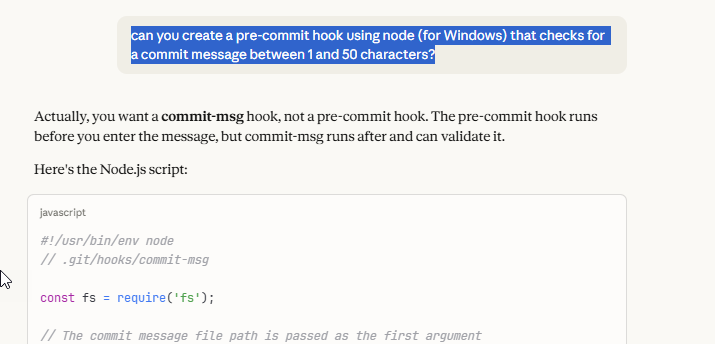
    I didn’t want to lint or worry about whitespace, since I’m depending on SQL Source Control to create the files, so I asked a different question: can you create a pre-commit hook using node (for Windows) that checks for a commit message between 1 and 50 characters?

    The response is good. I didn’t want this, and reading this, I realize Claude is right. I wasn’t quite thinking through the process here. I also didn’t want the code for a commit-msg hook, so I ignored the code.
    2026-01_0152

    I could see that I was getting generic hooks, mostly for other code, so I rephrased a prompt: I want a sample pre-commit hook for .sql files to test something, what is a good example

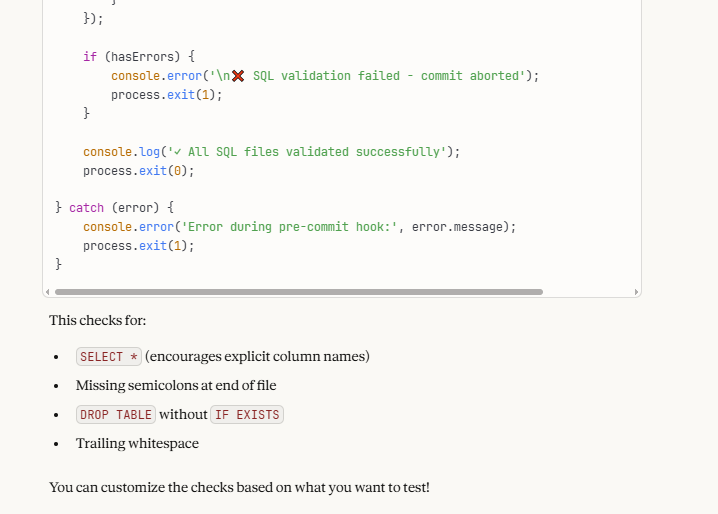
    The response was a practical hook for SQL files. The code had a couple of messages printing our errors when I failed things, and the code here isn’t important, but here was the explanation. The bottom of the code is shown, and then the list of things that are checked.
    2026-01_0153

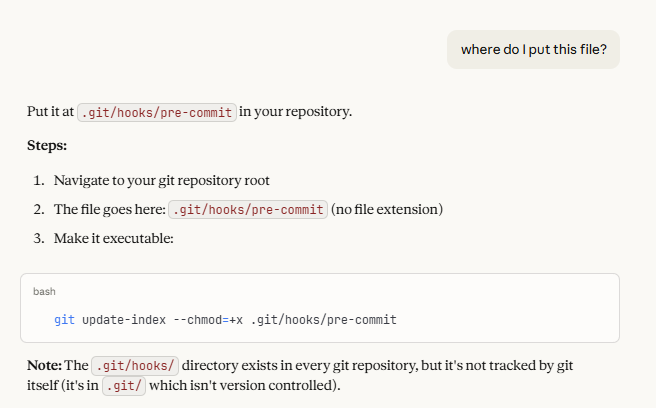
    At the top there is a comment about the hook, and since I’d done this a few years ago, I thought I know what to do, but I asked. I mean, why not ask the AI for more help? I liked that it noted not only do I need to add this to my .git folder, but I need to track this if I want to share it. That’s important. I do want other team member, or in this case, me on another machine, to have this hook.
    2026-01_0154

    Testing the Hook

    I then went to SQL Source Control and made a change. In this case, I added a file that I knew would fail the check. Here’s my code:

    ALTER PROCEDURE dbo.GetAllCustomers
    AS
    SELECT * FROM dbo.customer

    I could see this code change in the SQL Source Control GUI, but no error. I thought this might be staged, and I somewhat assumed the hook would fire on staging, so I asked.

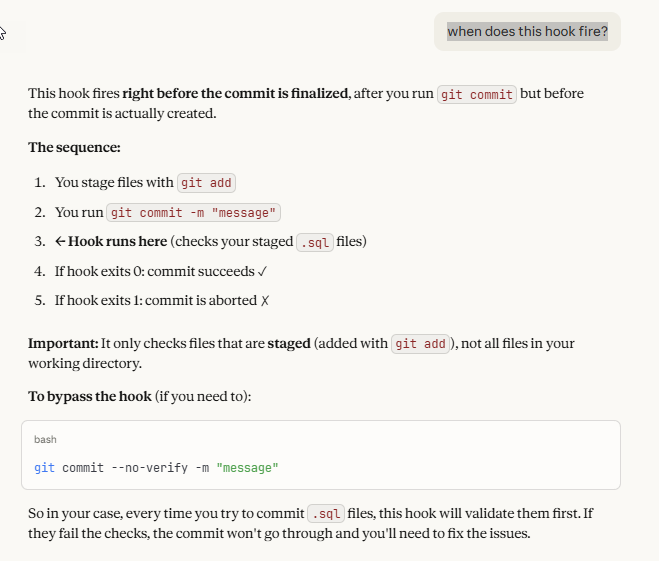
    My new prompt: when does this hook fire?

    The response let me know that I had to commit this to get the hook to fire. It runs on the commit command, as before the commit succeeds. That’s good to know. Thanks, Claude, for helping me learn something.
    2026-01_0157

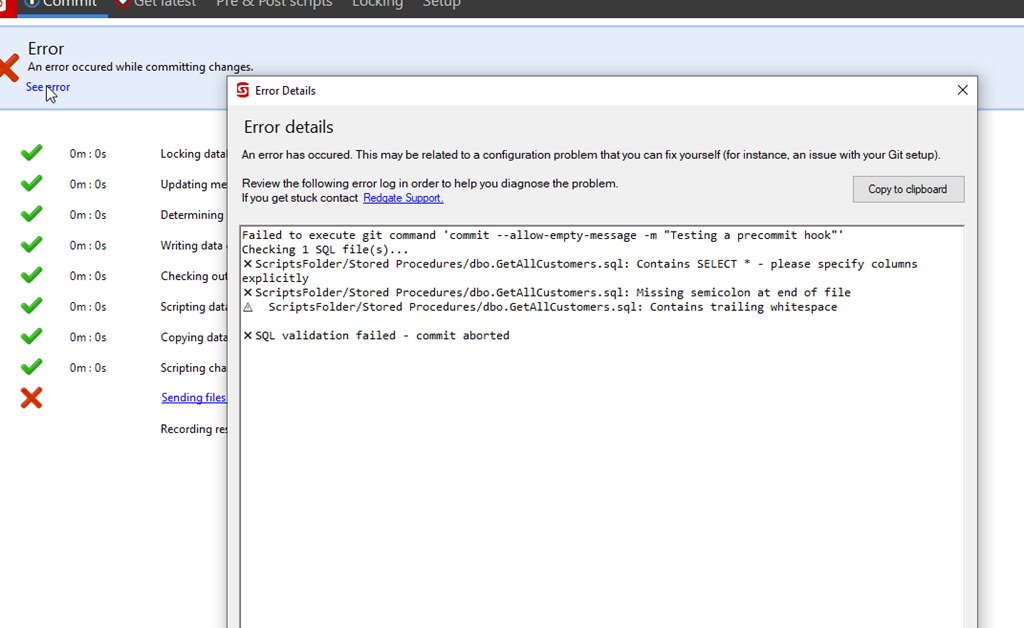
    In checking from the CLI, I realized that SQL Source Control at this point hasn’t staged the file. It also hasn’t written the file, so there’s nothing to stage. One of the downsides (one fo the few) of SQL Source Control is very limited git configuration. The write, stage, and commit happen at once.

    I tested this and sure enough, I got a failure when I tried to commit. The hook fired and saw my SELECT *, and my lack of a semi-colon.
    2026-01_0146

    I tested this further by fixing these elements individually, and I could correct the SELECT *, but I couldn’t fix the semi-colon. I realized with testing that when SQL Source Control writes the file, it always includes a “GO” at the end. So my hook doesn’t work.

    Asking for Modification

    I decided to see if Claude would fix this, as I wasn’t sure what to change myself. I’m not a Node nor RegEx person, and I’d be googling a bunch to figure this out (or find someone else’s code). Instead I tried this: can you adjust this hook to ignore the missing semi-colon if the file ends with a GO, or check for a semi-colon before the GO

    The response was interesting. The explanation said this:

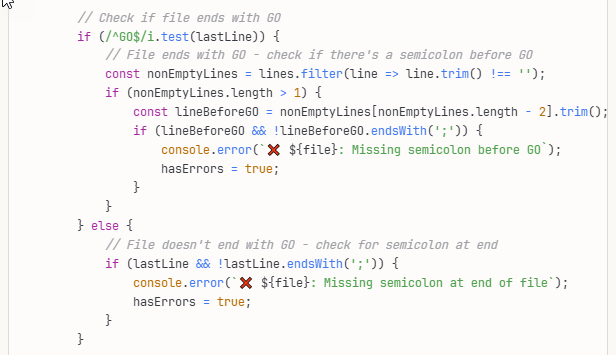
    Now it handles both cases:

    • File ends with GO: Checks that the line before GO has a semicolon

    • File doesn’t end with GO: Checks that the last line has a semicolon

    The relevant code is here:
    2026-01_0158

    I can read this and it makes some sense, but I would have struggled a bit to get this done in a reasonable time. Instead, it was seconds for Claude to produce this.

    When I re-tested, this passed the SQL Source Control GUI and I had a working git hook looking for a couple of simple silly mistakes I might code.

    Summary

    This is an area that I have a little experience, but not a lot. I’m a junior dev when it comes to Git, and Claude is definitely more skilled. However, I have to know what to ask to get a result and I thought the answers and explanations were good in helping me setup this test in a few minutes rather than the better part of an hour (or longer) if I were searching and trying to assemble code.

    This is one of those areas where AI was very useful to me. It built a fairly trivial coding item I needed, it helped explain things when I had questions, and it was helpful in adjusting code quickly when I realized I needed something else.

    Imagine asking a colleague this, realizing you’d asked the wrong thing, and then asking them again for new code. How slow, and annoying, would this be for both of you? AI is a game changer here, for things that are too simple to work with a colleague on, yet complex enough that you’d waste a decent chunk of time googling.

    That time savings went into me testing the code and testing SQL Source Control. I verified that SQL Source Control can work with git hooks in minutes.

  • Done is Better than Good

    Mary Spender is a musician in the UK who I follow and hope to see live one day. She works hard producing content about music, that business, and, of course, songs. Recently she had a little essay on Instagram where talked about creative time and focus. In it she referenced Elizabeth Gilbert saying “done is better than good.”

    My initial reaction was “that’s right.”

    Then I thought about software, and poor queries impacting database performance, and thought, “No, that’s not right.” My next reaction was to think maybe it’s “done is better than great”. I do see plenty of engineers trying to build great software. Code that would impress their peers or their former professors. Or maybe their future self.

    Then I thought, no, Elizabeth is right. If things don’t get done, then what’s the point?

    At the same time, I think that “done” and “good” (or great) aren’t mutually exclusive. We can get things done and make them great, which is something to strive for. We can also get good things done.

    Sometimes.

    Sometimes we don’t have that luxury of time, for various reasons. If I had to make a trade, I push for good (or quality) as much as possible if the delay isn’t substantial. If it is, then done is likely the choice I’d make. I do try to return and refactor, improve, etc. to raise the quality over time, but I recognize that sometimes getting something done is important. Certainly, on the ranch, I need to fix things to get by, with the aim of doing a better job later. I have mixed success at returning to improve a patch with a better fix later, but so far, that’s worked well. I’d say the same thing has happened while building software or managing systems, with enough success to be comfortable with my choices.

    What about you? What choices have you had to make about being done over delivering something that’s good? Or maybe great.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • Poor Name Choice

    I wrote recently about some work with Redgate Clone, and one of the things I did was start up a blank container instance of SQL Server from the image named empty-sql-current. This image contains SQL Server 2019. Clearly, “current” was a poor choice.

    I see this often in various places, where someone will reference “current”, “new”, “latest”, or some other term that denotes the most recent changes. If everyone reading the reference is doing so with knowledge of the past and at a time close to publication, this works fine. However, a year later, does this make sense? At the same time, I do like consistent names that might be used in scripts. If I always want developers pulling the latest item, I might use latest. However, if versions are important, than “latest” or “current” might not be the best choice. Much of the time, I tend to try and get a version or some other specific indicator in a name.

    It’s like seeing the words “the fastest SQL Server ever” (or pick your technology) in a release announcement. At that time, it might be the fastest SQL Server release, but when the next version is released (hopefully) that won’t be true.

    As I’ve matured, I aim to build things that last for the future, thinking beyond what the world looks like right now. This includes architecture decisions and more, but it also includes naming. Reference specific versions, times, etc., with the idea that I want to convey some information with the name. I even name my containers with the port I use because it makes it really easy to see which database container is running on 1433 and which is 41433.

    The other consideration for naming, for me, is to include data in the name that I will use for searching or sorting. Perhaps means using good date practices, like 2025-05-01 and 2025-10-03 to ensure my files sort correctly. That might be very important for things like backup files. Maybe it’s using something like “Customer_Copy_Delete_After_Year_Close” for a copy of data that might be relevant through our current financial cycle.

    I often do like using names that come to mind first, as this can help me find things, but I also have learned to be more explicit when using names as a way to convey information. With modern computing and support for large names, it sometimes pays to be descriptive.

    The only thing I try to avoid is spaces. For the most part, file explorers and web servers handle spaces, but sometimes things break, so I’ve learned to avoid spaces where possible.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • The Technical Debt Anchor

    I ran across an article on the 7 types of tech debt that can cripple your business, which is a great title. It certainly is one that might scare a lot of CTOs/CIOs/tech management. I am sure that much of the IT management gets concerned on a regular basis with how quickly their staff can evolve their software to meet new business needs.

    The first two items have to do with data, which is understandable. Data is the core of how many organizations operate and move forward, and if you don’t have the ability to easily work with data in a flexible way, you can struggle. Many of us technical people know this, but I find many non-data-professional staffers don’t get this and are often unwilling to work at improving the situation. They things to just be magically better without changing how they do their jobs.

    Many of us data professionals know that data quality is crucial. Many others assume we have quality data. Both of us need to understand that some of our data is suspect, but most of us is pretty good. Don’t get drawn into a black/white argument that our data is amazing or horrible. No matter what we do, there will be errors, so account for that. At the same time, do some testing, some evaluation, and double-check yourself.

    We also need to ensure some level of performance from our data stores (databases, data lakes, etc.). Too often we see queries start to slow down and blame the DBAs. We ask them for better performance without being willing to press on developers (or vendors) to improve the performance of their code. Don’t just expect to build bigger machines, make sure you train staff to write better queries and help DBAs learn how to better index systems. We’re a team, so let’s work as a team on our performance issues.

    There are a few AI-related items and a couple of DevOps items as well. All tech debt is a problem; it just depends on how much you have as to how big a problem it is for your systems. However, the seventh item is cultural debt. AI is part of this, as staff can have job-threatening views of AI, but that’s really a lack of trust. Management has to build trust with staff and ensure they are cared for if management expects staff to be accountable for code. Workers have to drive themselves forward, as a part of the technology revolution is that change is a given. Don’t expect to do the same job you’ve done for years. Learn to use new tools and learn to use them effectively in your position.

    At the same time, management has to value employees and be clear about what’s expected or workers. Be fair with employees and value their efforts. Working together is what will drive your organization forward.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.