Tag: T-SQL

  • Don’t Fight with AI

    I was recently trying to handle a simple task with a few AI tools to see how well things worked. I realized that AI isn’t great for everything and there are times you need your judgment to stop fighting AI and use other tools.

    Tl;dr choose the shortest path and know your tools. In this case, just copy paste a script and results (see the bottom).

    This is part of a series of experiments with AI systems.

    The Scenario

    I have a table with some data. I wanted to duplicate this table DDL and DML for another system. Here’s my table:
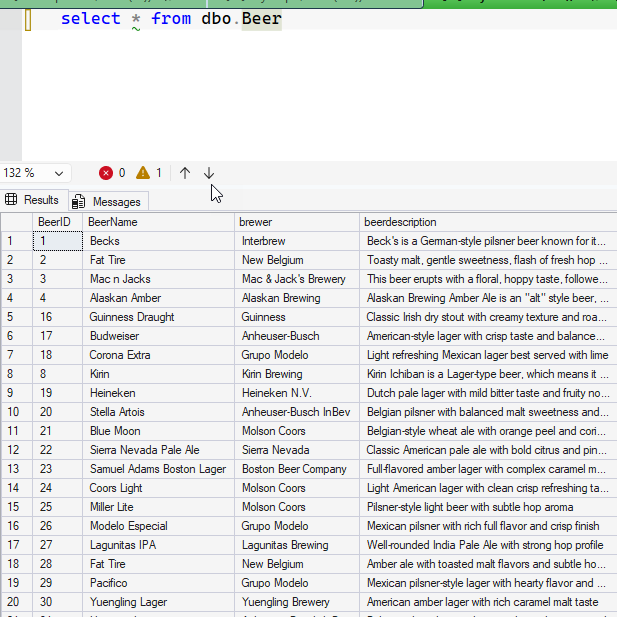
    2026-07_0152

    Simple thing, right? Lots of possible ways to do this, but understand, this wasn’t the task. I was doing something else, with another goal.

    This task was just in my way.

    First Try – Prompt AI

    I use SQL Prompt all the time, so I thought, hey, AI, script this.
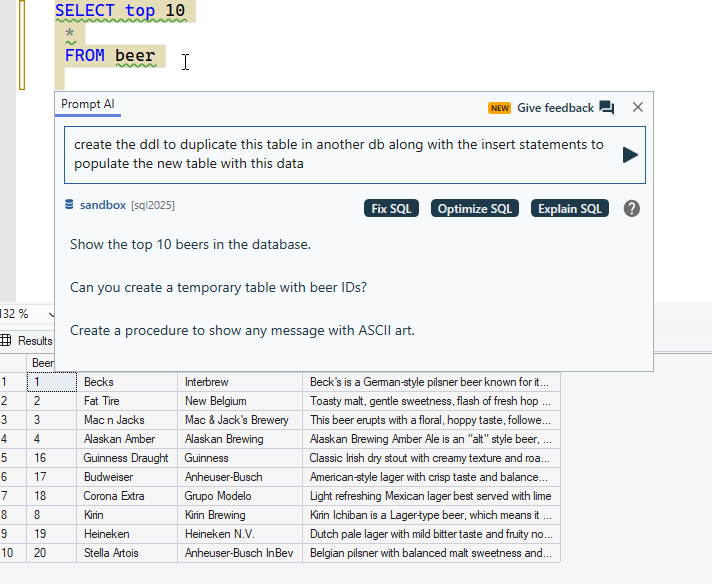
    2026-07_0135

    Well, not quite what I wanted. This works cross database, or if I make a new table name by editing the script in two places. But not ideal.
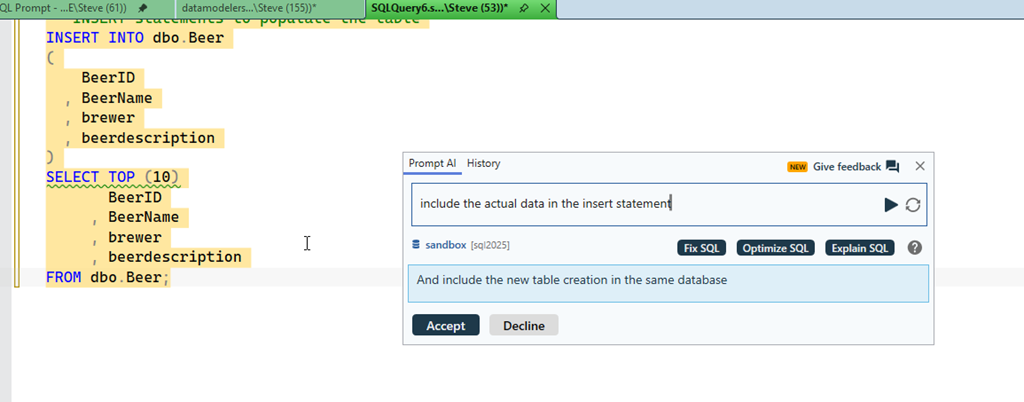
    2026-07_0136

    OK, I asked for the data, and this works. A bit. I only get 10 rows. To be fair, the original select I started with was top 10.
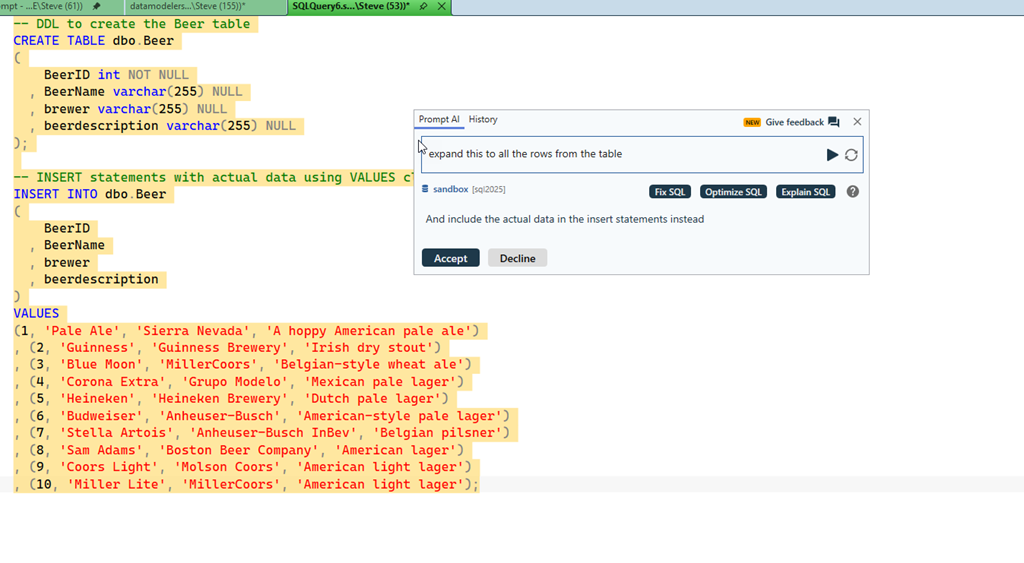
    2026-07_0142

    I then ask for the other data, and I go backwards. I don’t know why a model would go in this way. This reminds me of working with a junior person half listening to me.

    2026-07_0140

    Grrrr.

    Claude CoWork

    This seems like a cowork task. I’m not saying this is the best thing, and since I didn’t have a repo, I decided this over code. In any case, I asked for a task. Quickly Claude gave me options for 1) PoSh, 2)T-SQL, 3) something else. I picked 2 and it took about 4 minutes or so, but I got this script.

    2026-07_0146

    I had to open in VSCode, connect to SQL, and then it didn’t work:

    2026-07_0147

    Paste back into Claude, get a quick fix, maybe 15s.
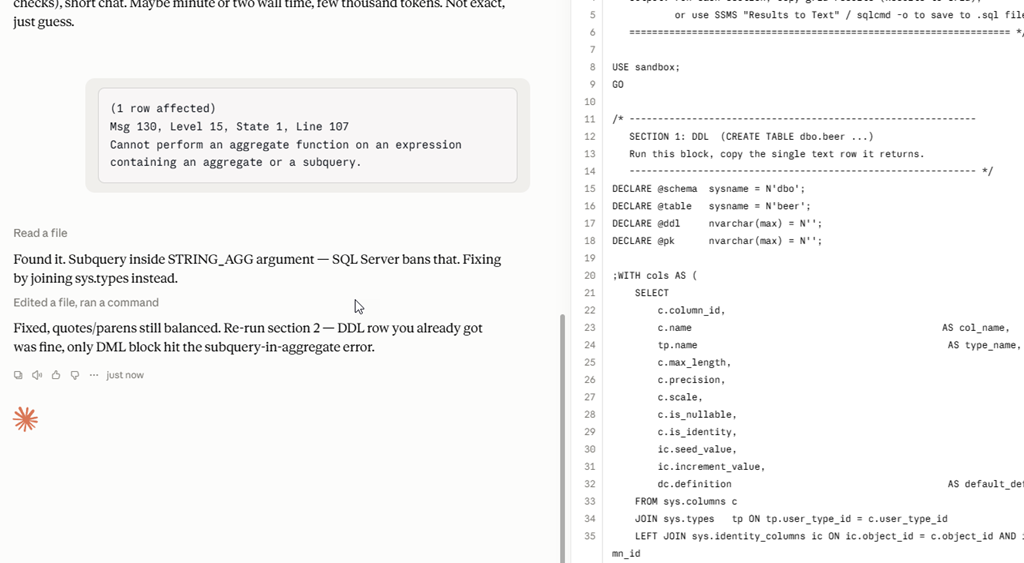
    2026-07_0148

    Copy/paste the script, which runs. Certainly I could have put this back in SSMS, but I’m not sure that’s easier/harder.

    2026-07_0149

    I copy the results, which is fairly easy here.
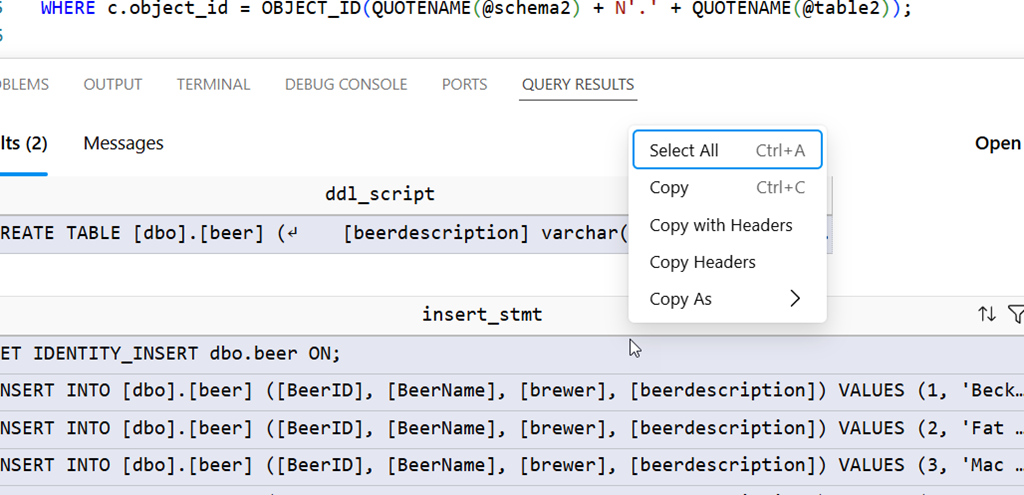
    2026-07_0150

    I have the script I need and can move on:

    2026-07_0151

    Redgate Assistant

    We’ve added a new Redgate Assistant panel to SQL Prompt. I tried this next, and got a few results. The DDL was first, which I could copy/paste into my new query window.

    The second was a script I pasted in and ran, which gave me insert statements. Taking these results gives me about what I have above from the Claude script.

    2026-07_0145

    This was significantly faster. From prompt to result was in the 10s range and then I could get the results in a few more seconds. That’s quick, and I didn’t lose my thought context.

    The Best Way – SQL Prompt

    I’m experimenting with, and it’s been a tool I reach for often, but as I was annoyed by Claude taking so long, I realized the best way was actually this. Run the query in SQL Prompt that’s at the top. Then select all the data in the results by clicking the top left box and right click. Select “script as insert”.

    2026-07_0153

    I can then easily search/replace or edit the name of the table.
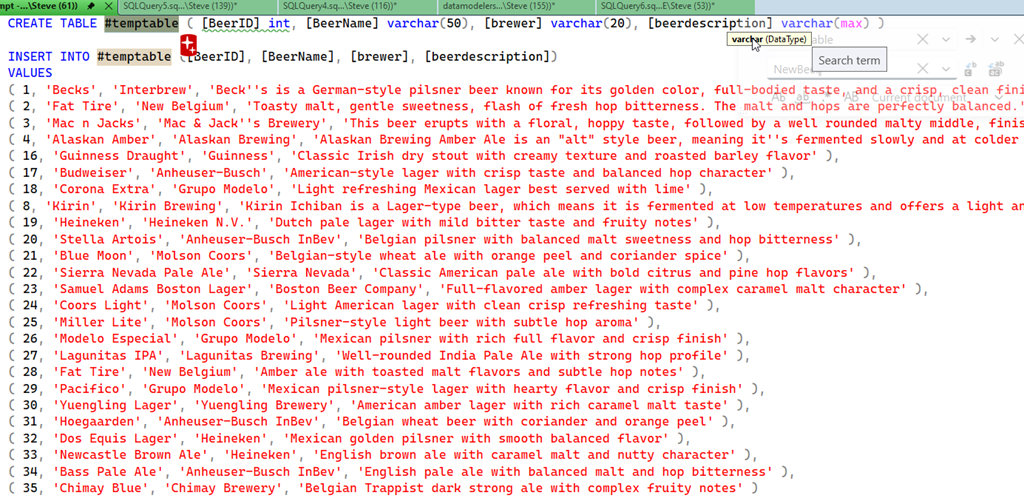
    2026-07_0154

    Doing this, once I thought about it, was about 5 seconds of effort, no context switch. Just grab this, change the name and go on with my other work on another connection.

    Use All the Tools

    I do think AI is a great tool for me. I also think it can cause me to spend more time and effort (and sometimes $$$) on simple tasks. While I’m all for experimenting, I also want to be efficient and effective.

    Fortunately, I’m somewhat paid to try different things and report on them.

    In this case, the KISS solution is best. Use Prompt what what it does best, work with your schema, code, and (lightly) data. I know I could use an MCP server, or Claude Code at al with more guidance, or something else, but those start to feel like using AI for the sake of AI and burning tokens when there are better tools.

    Not everything is better with AI. The people who succeed and prosper in this crazy AI world will embrace it when it’s most helpful and ignore it when it’s not very useful.
  • TRY_PARSE Limitations: #SQLNewBlogger

    I got a notification from a question I’d posted at SQL Server Central: Getting the Average. A user had posted their repro didn’t work, with no real comment. As a SQLNewBlogger FYI, that type of post shows poor communication and a lack of communication. I see that a lot and it’s a challenge in the modern world.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    A Quick Setup

    This was what the user posted:

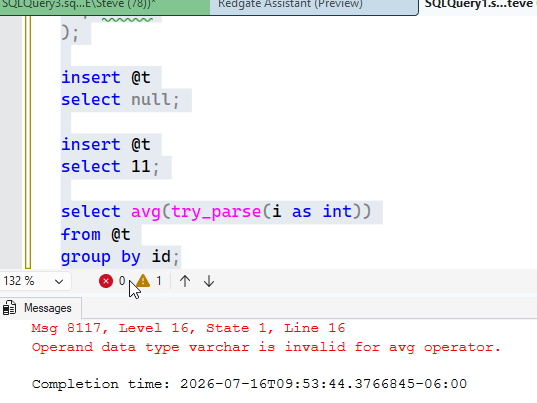
    declare @t table ( id int identity , i int ); insert @t select null; insert @t select 11; select avg(try_parse(i as int)) from @t group by id;

    This does return an error, as you can see below.

    2026-07_0373

    Why?

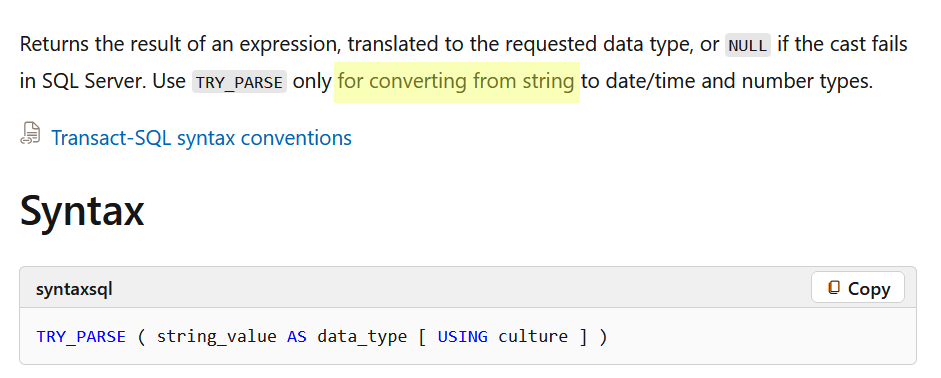
    Well, the TRY_PARSE() docs give part of an explanation. I highlighted this in Yellow, but the relevant text says “only for converting strings”.

    2026-07_0374

    Shouldn’t an int convert to a string? No, the precedence rules have int higher than char types. We convert lower to higher, not higher to lower.

    SQLNewBlogger

    I noticed something, thought for a second why this wouldn’t work, and then checked the docs. I decided to write this up and it was a 5-10 minute post for me. Easy to do and showcasing knowledge.

    It helps me remember, might teach someone something, and gives an interviewer something to ask me. Add to your blog with short posts like this (or drop on LinkedIn).

  • Capturing My Own Metrics: #SQLNewBlogger

    A customer was trying to compare two tables and capture a state as a performance metric. In this case, they were wanting to use Redgate Monitor and custom metrics, but since the tables were in a Memory-Optimized table, they couldn’t as Redgate Monitor runs inside a transaction.

    Note, there are workarounds, but they’re clunky.

    Fortunately, I had a quick solution, which involved SQL Server User Settable Objects. This post looks at how this works.

    The Scenario

    Let’s take the transaction out of the equation by using my own metric. SQL Server includes a few procedures that fall into a pattern. They are named with numerics as shown:

    • sp_user_counter1
    • sp_user_counter2
    • sp_user_counter3
    • …
    • sp_user_counter10

    Each of these corresponds to a value that is captured in a perfmon counter. The counters are in the objects called “SQLServer:User Settable”. The counter name is “query” and the instance is “User Counter n” where n is the number corresponding to the stored procedure.

    By default, these are 0, and you can see them here:

    2026-06_0191

    You can also see them in Perfmon

    2026-06_0192

    I’ll stick with SQL Server.

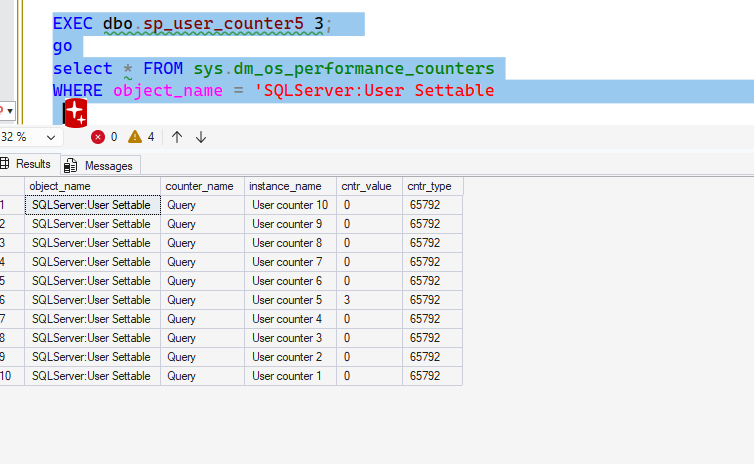
    If I want to alter a value, I call the appropriate procedure. I can do something like call the proc for 5 and set a value. I’ll then query the counters from T-SQL. You can see this below as the value for counter 5 is set to 3.

    2026-06_0193

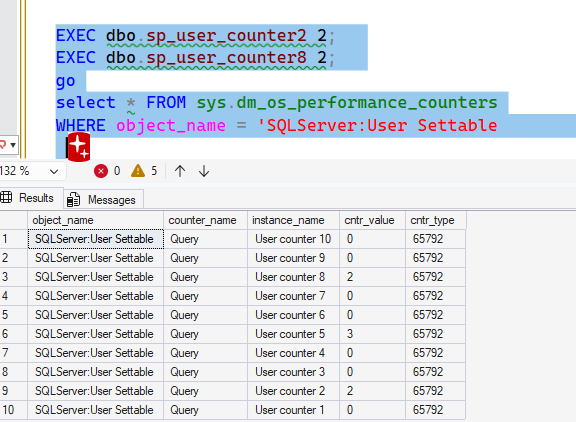
    This value remains set. I’ll set counters 2 and 8 to 2, and then query again. Note that 5 is still set.

    2026-06_0194

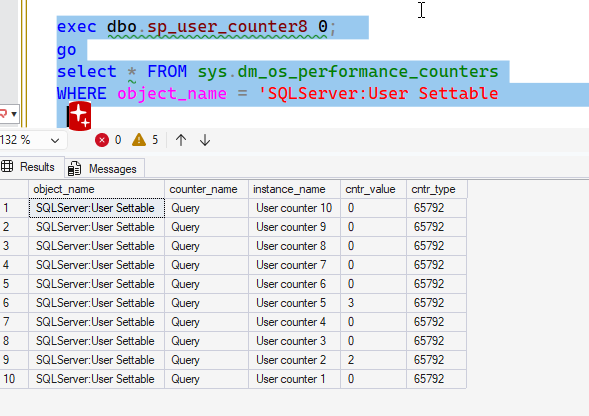
    If I want the value set to 0, I need to set it. I’ll do that for counter 8.

    2026-06_0195

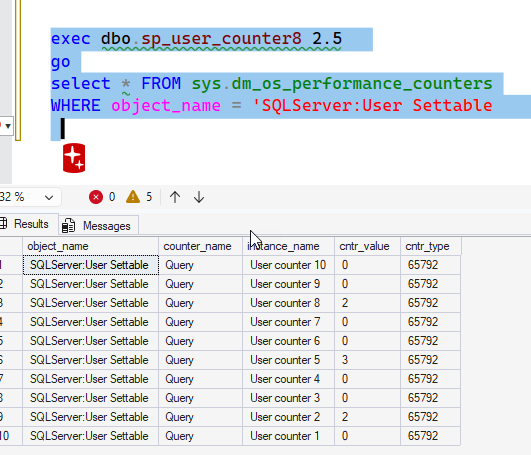
    These are metrics, so I need to pick an integer. I can’t set a decimal (or other type) and have it work. If the implicit conversion works, it works, but the value is a decimal.

    2026-06_0196

    If I make this a string, it fails with an error as ‘2.5’ doesn’t convert to an int. Same for a date. Using an int, like ‘5’, works.

    Solving the Issue

    In this case, for the customer, we solved the issue with a proc that performed their query The result of this query (and int) is sent to a counter value like this:

    CREATE or alter proc My_Checker AS BEGIN declare @i int select @i = count(*) from dbo.Customer a INNER JOIN dbo.Candidates b on a.CustomerName = b.PersonName select @i = @i + 1 EXEC dbo.sp_user_counter1 @1; END

    This can run from an Agent job on their schedule, updating the counter as appropriate.

    For their alerting, they can query this metric and set the boundaries that matter to them. In this case, whenever this is greater than 0, they want an alert.

    The user settable values aren’t that useful, especially as there are 10, but I’ve used them in a few places when I wanted to get instrumentation for an application. This allows me to easily capture values and watch them from any monitoring system.

    Worth knowing about and using if you need random things captured.

    SQL New Blogger

    This post took me around 15 minutes to write, though I spent about 10 minutes mocking this for our customer based on their system and then stripping out a few items that are specific to them.

    This is a post that shows how I can use features of SQL Server to solve a problem, which is something every employer wants. An AI would make this code easier, but I have to know to guide an AI in this direction and evalaute if this works. I’d certainly need to check if other apps were using these counters, which isn’t something an AI might think to do, especially as there could be lots of repos to scan.

    You can write something like this, showing how you’re use this features. Bonus points if you use an AI to help you (and disclose how).

  • T-SQL Tuesday #200: When I Look at a Query …

    This month is a milestone for T-SQL Tuesday. It’s number 200, which doesn’t sound big, but this is a monthly party (started by Adam Machanic). We have 12 blog party events a year. 200 means this has been running for almost 17 years (16 years and 8 months).

    I don’t care who you are, that’s impressive. Think about where you were, what you were doing, and what was happening in 2009.

    I haven’t been running it that long, but I am glad I took it over from Adam and have kept it going. Thanks to everyone who writes and reads the posts and especially the hosts.

    I tried to get Adam to host, but he declined. Fortunately Brent Ozar stepped up with a great initiation. My response below.

    At First Glance

    There are two things that immediately stand out to me when I see a query and create concern.

    1. cross joins
    2. functions in the where/on clause

    While there are other things I might see, these two stand out and usually I can guess there will be issues.

    For cross joins, I don’t see this as much when people use SQL Prompt or some other helper because they tend to use inner/left outer/right outer explicitly, or cross join. If you explicitly use a cross join, I might ask why, but these clauses require an ON clause, which means you’re deciding to join tables.

    Where I see people using old style joins, like this:

    select *
    
    from a, b
    
    where a.id > 23 and b.saledate > current_date
    
    or (a.id is null and b.saledate is null)

    I get worried. This happens in Oracle, and PostgreSQ, and it’s easy to forget to join a and b, especially when there are multiple tables. Usually cross joins happen with legacy join conditions.

    The other area is using functions in the WHERE clause. A common example is

    select *
    
    from customer
    
    where upper(customername) = ‘Steve’

    This function in the WHERE clause ruins the ability to see the data. The index is something like (‘Adam’, ‘bill’, ‘Steve’, ‘WILLIAM’). This can’t be used when the UPPER is applied. This often results in more reads, more scans than a system might otherwise take.

    There are plenty of other issues that can indicate performance issues, but these two are the ones I’ve often run into and the ones that would have helped 2004 Steve write and review better code.