Author: way0utwest

  • The Downsides of AI

    I remember reading about AI as a college student, and I always wondered if we’d get computing algorithms that might actually make better decisions than informed humans. As my tech career grew, I saw the advancement in systems, like Deep Blue, that showed we could build better systems that might beat humans at their own games. The recent success of AlphaGo makes me wonder what the next challenge will be?

    Certainly machine learning (ML) and AI-like systems are becoming quite popular in business these days. More and more companies are trying to find ways to use these computer science tools to improve their organizations capabilities. Whether these techniques will continue to be popular remains to be seen, but in the short term, all the efforts of companies like Microsoft and Amazon will get many companies to try to build intelligent systems.

    There is a lot of data being used to fuel these AI and ML applications, so it’s a natural fit that many data professionals will want to be involved. It’s a complex area, where lots of data is used to conduct lots and lots of experiments. That type of work my not suit many of you, but give it a try on one of these platforms and see what you think. Perhaps this is work you will enjoy. However, even if you enjoy the work and become good at it, there’s potentially some issue that may impact the use of these systems.

    We don’t know how most of the applications actually work. That’s because we haven’t programmed them. In some sense, many of these systems learn from data, and with a little guidance, but there isn’t necessarily a debug log that might explain all the actions. That is perhaps the dark secret of AI. We don’t really understand what’s going on.

    The article linked above looks at autonomous cars, which a number of companies are researching and building. One of the issues with the complex system(s) that runs the car is that we don’t necessarily know how it works. This might not bother technical people, but it certainly does bother many people. When there is a problem, and there will be a problem since there are always failures, how do we determine what went wrong and make it better? Add more data and retrain the system? I’m not sure that is a solution that most people will accept.

    Ultimately I think some of the research and work on AI needs to focus on allowing the model to output a set of data on what data is being weighed and the impact on the flow of information that leads to a decision. I know this is a tremendous amount of data, but it is probably the type of analysis that is needed for accountability in these systems. After all, it’s not just cars where this matters. Imagine that your have an AI system that cuts off all AC in the summer, or decides not to order enough resources for a busy time period. How do we explain to management that “the system just decided” on that course of action? I really think we need better tools for analyzing these models.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 4.1MB) podcast or subscribe to the feed at iTunes and Libsyn.
  • Use More Pull Requests

    I noticed a short while back that Books Online is on github. You can fork the code and make corrections to pages and then submit a pull request. This is the model that many OSS projects use, including the amazing DBATools project. That one I really like, and if I was better at PowerShell, I’d contribute. If you’re a PoSh whiz, I’d urge you to contribute.

    A few years ago I saw a lot of complaints about the SQL Saturday site, and over the years I’ve also seen a number of complaints about the Pass Summit sites, and the registration process. At one point there was a debate over whether PASS should build a registration system or continue to pay for the service. To me, this was a perfect place to start a project, maybe with a few volunteers, and then crowdsource enhancements and improvements. Get help from the members of this technical community, after all, this is the way most of us make a living.

    If Microsoft can get help from outside, I’d expect other organizations could as well. Certainly PASS has limited resources, and this is a great way to perhaps get new ideas, innovate, and grow their system. There will be some friction and loss in reviewing changes, but I’d expect that the overall gain would come from the greater number of people contributing to the software.

    We’ve kicked this around for SQLServerCentral and Database Weekly, and I am hoping to start getting help in enhancing my own site from its community at some point. There are certainly challenges and difficulties in integrating code from lots of sources. DevOps makes this easier, with more automation to evaluate and test code before a human needs to review it. However, DevOps has its own challenges, with extending the culture and process to others, and finding those individuals that want to contribute and buy into the philosophy, not to mention maintaining code quality and standards. However, I hope that you consider using pull requests and getting help from others in your own organization or project.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.0MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Back from the DPS 2017

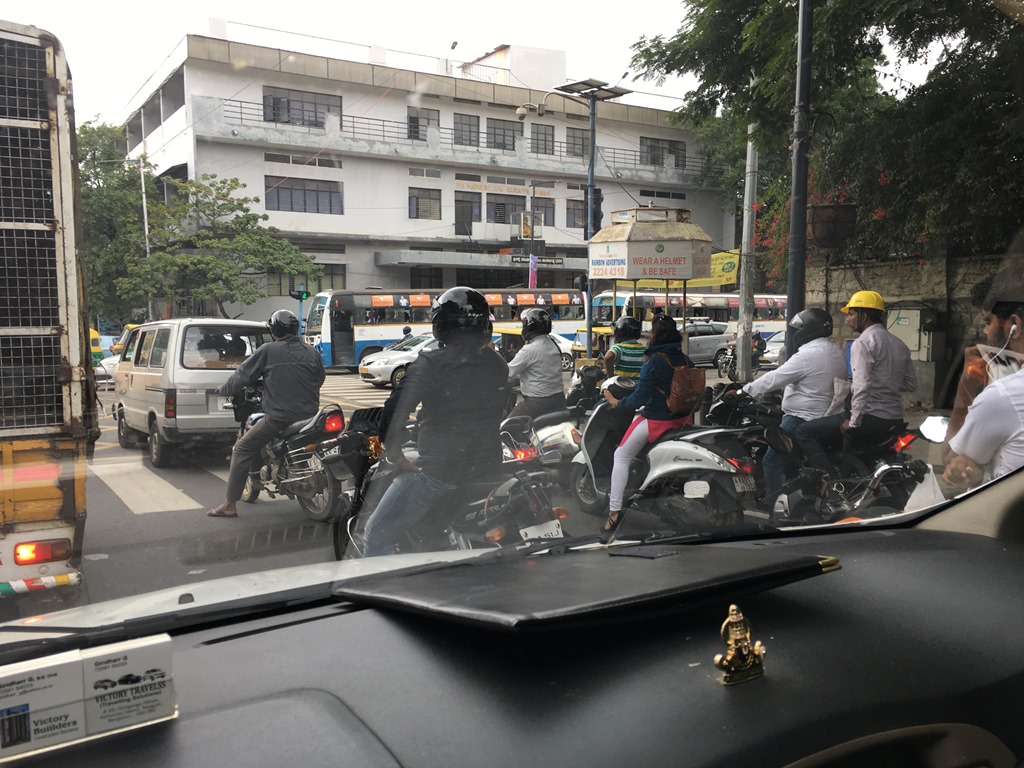
    I was honored to visit the Data Platform Summit 2017 and get to speak at the event. Since this was in India, on the other side of the world (12 hours from Denver in time zones), I took an extra week of vacation with my family before the event. India was amazing and we all enjoyed the trip. It’s a culture shock for a US guy that lives in a rural area, but I really enjoyed the experience overall. Traffic, however, was a shock.

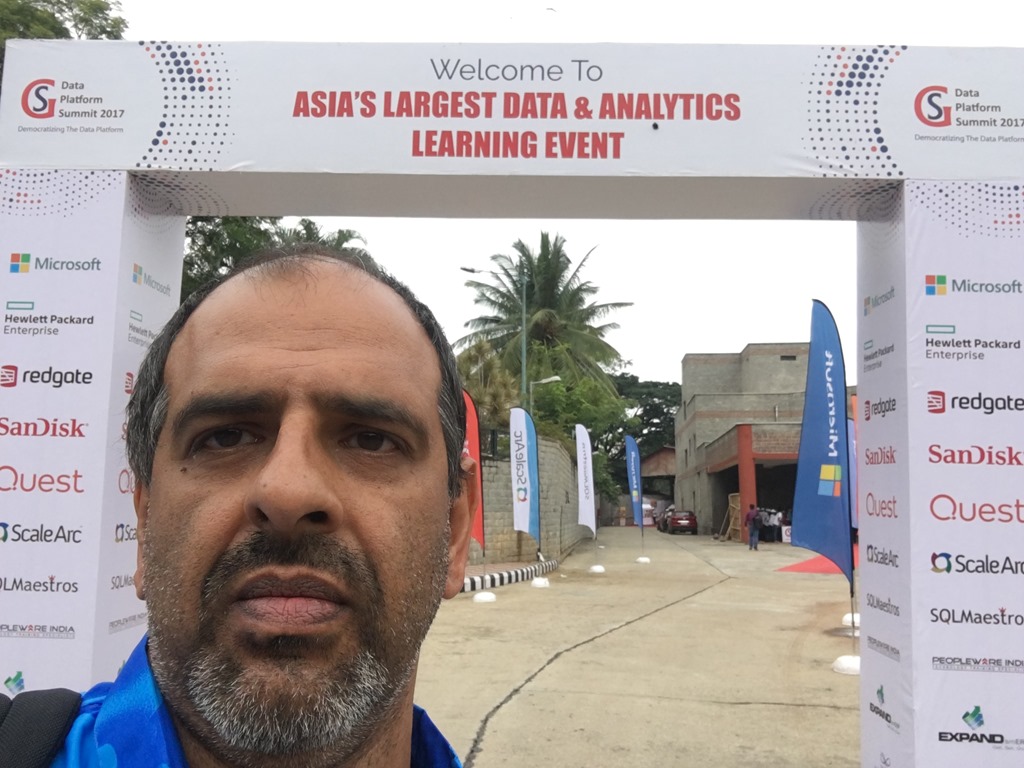
    IMG_2348

    The event was fun, and well attended. It was held in a conference center in Bangalore, with quite the entrance for everyone walking in each day.

    IMG_2474

    There was also a large display at the parking lot.IMG_2448

    The schedule was interesting for me, with lots of commitments. I tend to speak 2-3 times at most events, but here I had a pre-con + 5 other sessions. Granted, 3 were shorter ones, but still, that’s a lot.

    IMG_2463

    There were normal, 75 minute sessions, which are what most other conferences schedule. However, alongside these were 30 minute sessions, which were held in a number of smaller rooms. Some were open talks, which are lectures. No screen, no computer. Others were chalk-talks, where a whiteboard was available, but again, no slides/computers.

    IMG_2476

    The idea was that we’d just talk about a topic and answer questions from the audience. I wasn’t sure how the Indian attendees would respond. In some countries, people are very quiet and shy. In others, they don’t hesitate to ask questions. That meant I had to prepare an outline, which was similar to other talks. The good thing was no demos. The tough thing is that I need to be able to explain things without the crutches of images and code.

    Everything went well, and I am thankful for the opportunity to present. I don’t know if I’ll get the chance to go back, but I certainly would if the stars align.

  • Jumping Ahead

    While on vacation recently, I went to see Spider-Man Homecoming with my family. It was an enjoyable movie on a rainy afternoon, and a nice addition to the Marvel lineup. I think this actually might be my favorite Spider-man movie, and I’d recommend you watch it if you enjoy this genre. It was humorous, well written, and some nice special effects. As with any of these Marvel movies, you definitely need some suspension of disbelief, especially with the technology.

    In the movie, Peter Parker is anxious to join the Avengers and become a full time super hero, going on missions that have a large impact in the world. He chafes as the idea that he needs to stay in school and let his life progress at a more normal pace, which Tony Stark seems intent on pushing. Many of us have felt the same chafing in our own youth, wanting to get out of school, go to work, and move on in life.

    However, even in our careers, I find people wanting to jump forward, moving to new technologies and platforms as quick as possible. I certainly see this in the SQL Server world, often from developers, that want to find the holy grail of database storage in CouchDB, CosmosDB, Neo4J, etc. I’ve often seen this in the development world with different types of technologies, such as web frameworks. Maybe we in the data space are more conservative? Or we like sticking to what we know works well?

    We data professionals are not immune from the desire to jump ahead. I see plenty of data people wanting to jump into some new area to grow their careers. Data Science ( and AI, Machine Learning, etc.) is the newest craze, with quite a few people learning some R, some model training, and wanting to find a use for their skills. Or maybe an employer, preferably one that pays more than they make now. Good luck to you, but I’d encourage you to remember that good data science takes lots of skill, knowledge, and practice. I wouldn’t expect a quick jump into this new area.

    There are certainly other changes in the data world, such as the graph capabilities coming to SQL Server 2017 and the explosion of cloud database implementations. However, don’t get caught up in expecting quick changes in your job or your income. Continue to learn, experiment, build a POC and practice your skills. Change usually comes for most of us at measured paces. This pace is hard to accept if you don’t have the habit of regularly learning something and applying it in small doses, understanding that not everything you learn will be useful (or used) in your current situation.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 4.2MB) podcast or subscribe to the feed at iTunes and Libsyn.