Author: way0utwest

  • SQL Server on Linux (Ubuntu)–Updating from Early CTP

    I’ve been testing the SQL Server on Linux for a long time. After the recent Microsoft Data Amp event, I saw the announcement for CTP-2. So I did what I’ve been doing for some time on my Ubuntu machine:

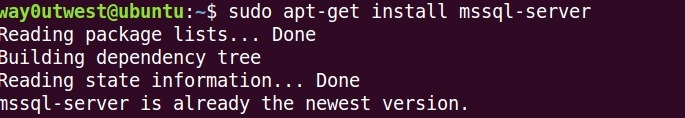
    sudo apt-get update
    
    sudo apt-get install mssql-server

    However, I got a message I didn’t expect.

    2017-04-19 10_59_27-Ubuntu 64-bit SQL Server .210 - VMware Workstation

    A few people on Twitter noted they had updated to CTP 2, but I was still on CTP1.4.

    Hmmm.

    I looked back through the apt-get log and I saw this:

    2017-04-19 11_00_22-Ubuntu 64-bit SQL Server .210 - VMware Workstation

    I’m cutting off part of the path, since I think it’s probably NDA. No worries, apparently the old location for me hasn’t been updated with new packages, which makes sense.

    I decided to check the MS docs and see how a new user would get SSoL running? At the new docs.microsoft site, I found the Install SQL Server on Ubuntu doc.

    Following the instructions, I updated the GPG keys and registered the repository with curl:

    curl https://packages.microsoft.com/keys/microsoft.asc | sudo apt-key add -
    
    curl https://packages.microsoft.com/config/ubuntu/16.04/mssql-server.list | sudo tee /etc/apt/sources.list.d/mssql-server.list

    Once those were done, I re-ran my apt-get update/install and it worked.

    2017-04-19 10_58_46-SQLQuery9.sql - 192.168.1.210.master (sa (51))_ - Microsoft SQL Server Managemen

    If you haven’t worked with Linux, it’s not really that hard. Some of you may get asked to install or manage a system, and while you should seek help for anything production related, in dev areas, play around. Read and learn a bit about Linux (I’d recommend watching the SDTIG book club meetings I, II, III, IV on Linux), download Ubuntu (or anything) and play around. Get used to a command line and try things.

    You’ll love SQL Server on Linux. It’s mostly just SQL Server, but updates and installs as simple in a test world.

  • SQL Server Telemetry

    One of the things that I’ve seen blogged about and noted in the news over the last year is the amount of data being collected by various software systems. In particular, I’ve seen numerous complaints and concerns over what data Microsoft collects with its platforms. Perhaps this is because Microsoft is the largest vendor, and plenty of other software collects usage information, primarily to determine if features are being used or working correctly. I think much of this is overblown, but I can understand having sensitivity about our computer usage, especially for home operating systems.

    Microsoft conducted an extensive review and published data about what is being collected and why. Windows 10 and other products have undergone review and must comply with the published policies. There’s even a Microsoft Privacy site to address concerns and explain things. It’s an easy to read policy that explains what  Microsoft is collectin, if you’re connected to the Internet (if you’re not, don’t worry, no bloating files). That’s a huge step forward in an area that is evolving and something I wouldn’t have expected to see in the past. I am glad Microsoft is making strides here, even if I may not agree with specific items in their policies. I do think that most of the companies collecting this data are doing so to improve the products, not spy on customers. I’m sure some do, but likely smaller organizations with some sort of criminal intent.

    As data becomes more important, telemetry for software is potentially a data leakage vector where private, personal, or customer information might be leaked. Certainly as more speech and other customized services are used in businesses, I worry about what data could be accidentally disclosed. After all, it’s not that super powerful smart phone that is actually converting audio to text in many cases; it’s a computer somewhere in the vendor’s cloud.

    With databases, this has also been a concern from some people. I’ve seen the Customer Experience Improvement Program for years and usually opted in. I’m rarely doing something sensitive and I hope that with more data, Microsoft improves the platform. That’s the stated goal, and I’d seen them talk about this a few times. The SQL Server has moved forward and published an explicit policy that spells out what and when data is collected. It was actually just updated recently and all new versions of the platform must provide this information (if anything is different) and adhere to what they disclose. There is a chance that user data could leak into a crash dump, though users have the opportunity to review data before it is sent to Microsoft. I’m not sure how many will, but they have the chance.

    I would like to be sure that anything sent is secured, and perhaps have an easy way to audit the data sent in a session, but I know this entire process is evolving. One important item to note is that customers can opt-out of data collection for any paid for versions of SQL Server. That’s entirely fair, but if you have regulatory concerns, you should be sure that you don’t restore production data to development machines. You shouldn’t anyway, but just an FYI.

    Usage data is going to be a part of the future of software, especially as more “services” integrate into what we think of as software. Those services aren’t always going to be under our control and certainly part of the reason many of these are inexpensive is that additional data is captured about the people using the software. I hope all companies publish and adhere to some sort of privacy statement, and maybe that’s a good start. Rather than any regulation on specific privacy that must exist, start forcing companies to publish and stick to whatever policy they choose.

    Steve Jones


  • Liable for Data Loss

    When I first installed Windows 7, I was thrilled. Finally, Microsoft had slimmed down and improved the OS performance rather than continuing to bloat it larger. After Vista, Windows 7 was a welcome change. Windows 8 was different, but for me as a desktop user, it wasn’t much different. I moved to Windows 10 as a beta user and thought it performed well. A little slower than 7, but overall a good move. I was glad to get the upgrade notice on a second machine, but it was annoying. Trying to easily delay or avoid the change in the middle of some travel was hard. I certainly could sympathize with the users that complained they didn’t want the upgrade and couldn’t easily avoid it. I’m glad Microsoft changed this process a bit.

    There were people that accidentally, or felt forced, to upgrade. Among those, some of them lost data and decided to sue Microsoft. Let’s leave aside the Windows upgrade process, Microsoft’s decision, and the merits of this particular case. Those are separate issues from the one I want to discuss, which is the liability for data loss. At the core of the lawsuit, the time and information that people have lost is an issue that few of us have had to deal with in our careers. At least, most of us haven’t had to worry we are liable for the issues our software might cause.

    Are we moving to a place where a person, or more likely a company, is going to be held liable for the data loss from upgrades or patches? There is the ability of customers to initiate legal actions, but strong EULAs and prior legal decisions seem to indicate that much of the liability resides with customers and vendors aren’t at fault. Is that a good thing? I’m not sure, but I do think that as data becomes more important and is used to justify decisions or drive business actions, there will be a push to ensure that anyone performing data changes with their software during patches and upgrades is liable for issues.

    I’m surprised we haven’t seen more of accountability from software firms to date, but I think much of the legal issues have been settled without much fanfare and strong non disclosure agreements. I’m not sure this is the best solution for anyone, as to force some improvement and better quality for software, we need to take better care of our data. I don’t want us to move slower with software development or deployment, but I do want quality to improve.

    Steve Jones

  • Agent Phases in VSTS Deployment

    VSTS (Visual Studio Team Services) continues to grow and change over time. It seems every few months I see some new features and changes, which are good and bad. Good in that usually things improve. Bad in that I get confused and lost at times, and sometimes have to re-acquaint myself with the system.

    One of the changes I noticed recently was the Deployment phases, which come as Server and Agent phases. I won’t cover server here, but I wanted to make a quick note on Agent Phases because I think they’re handy and a nice packaging concept.

    Agents

    There are agents that run for VSTS to do work. I’ve written about how to download an agent so tasks run inside of your network (on a server or client).  This post will look at the other side, how do I control an agent from the release process.

    Once I get a new release definition, I’ll see something like this:

    2017-04-02 11_18_05-New Empty Definition 02-Apr - Visual Studio Team Services

    This is a blank deployment definition. To the left I see the environment I’m working with, in this case, just the generic Environment 1 name. For each environment, I can set up tasks. On the right I have the Add Tasks button, but also the “Run on Agent” item. This is the container where I will add tasks.

    I used to just add tasks with VSTS 2015 here, expecting that everything would run on an agent. VSTS has hosted agents that contain a set list of software, and also downloadable agents that you run on your servers or workstations. Things changed recently to include phases.

    Phases

    The phases are place of execution, which allow a series of tasks to be grouped together. VSTS and TFS 2017 give you two choices. We now have Agent or Server phases. The difference between these is that I can choose where items execute, on an agent or on the server (VSTS or TFS). In addition, I can set these to execute in parallel if need be.

    If I click the down arrow next to the Add Tasks, I’ll get this dialog. This allows me to set up a process that can run on the VSTS server, or one that can run on the Agent.

    2017-04-02 11_18_25-New Empty Definition 02-Apr - Visual Studio Team Services

    I haven’t played with server phases, but when I add an agent phase, this gives me a section under which I add tasks. Note that when I click the “Agent phase” item, I get a new blade to the right. Note that the pool for these agents is the default.

    2017-04-02 11_18_43-New Empty Definition 02-Apr - Visual Studio Team Services

    This threw me early on because I have a separate pool of agents for mobile development. As I upgraded some deployment definitions, I couldn’t figure out why I didn’t have any agents available to execute my tasks. It turns out I needed to change the agent pool here.

    There are options here, but I haven’t really played with parallelism or demands since I typically deploy to one system at a time.

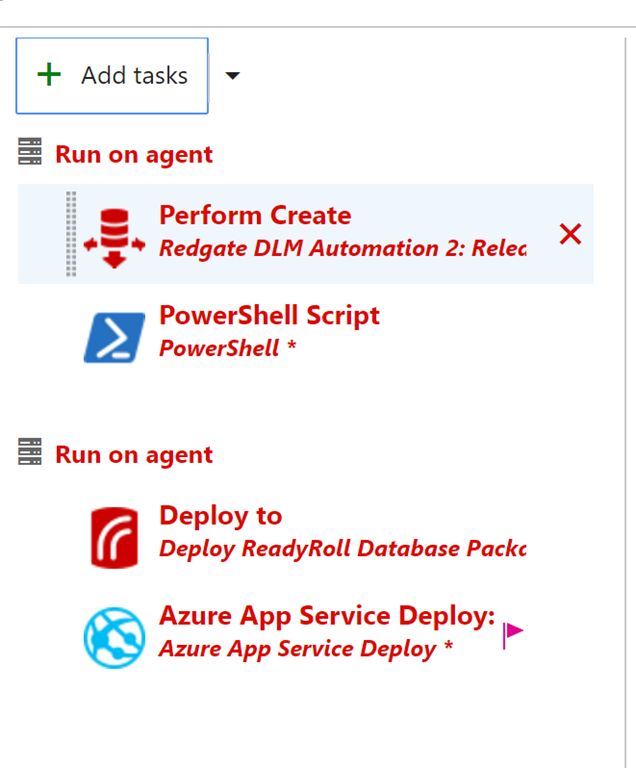
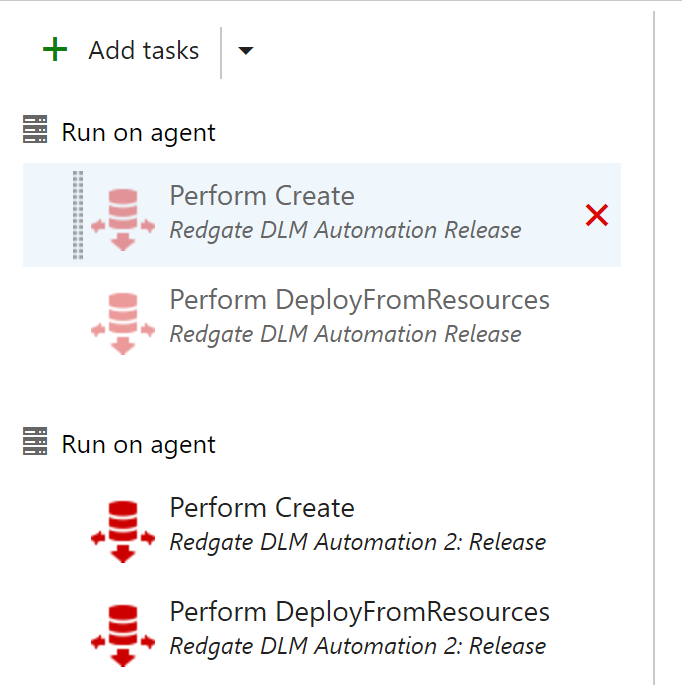
    Once I’ve selected an agent, I can click Add Tasks and then add a series of tasks to that agent. If you look below, I have added a couple tasks to each of the two agent phases. These will run one phase, then the other.

    2017-04-02 11_19_47-New Empty Definition 02-Apr - Visual Studio Team Services

    Each of these phases is independent, and as of the time I wrote this, there’s no way to copy a phase and duplicate it.

    I’ve used this to upgrade my release definitions by adding new tasks, and then copying settings between one phase and the other. This is a manual, copy/paste operation, but I can easily see if I’ve duplicated everything by going back and forth quickly.

    2017-04-02 16_32_43-ST Pipeline_Mobile - Visual Studio Team Services

    Once I’m done, I can just click the “x” to the right of the agent phase and delete the entire phase. I have to confirm this action, and then I’ve removed a complete phase.

    Right now I haven’t see any benefit outside of the upgrade scenario, but that’s useful. I will duplicate my tasks, disable all the ones in one phase and then see if the other one runs. If it doesn’t, I can always enable the old tasks and disable the new ones.

    I expect as I look to perform more complex deployments I will use these to logically separate things, and also perhaps use the server to do some things when I don’t need an agent.