Author: way0utwest

  • Forcing Strong Passwords

    It seems that every week we have some sort of data breach that results in emails and passwords for users being released. That alone is a good reason why you should not have passwords shared across sites or systems. I can’t stress this enough, and if you do this, please go get a password manager today and stop. Really, I mean it.

    However is it just the users that create poor passwords? In many cases, sure. However as the people that develop software, we can help. In fact, we should. Security should be on the mind of everyone that writes software.

    I ran across a piece on The Hacker News that says far too many sites don’t require users to choose strong passwords. I think this is changing, but far, far too many sites don’t check a user’s password for strength, or reuse. Some even force users to choose less than ideal passwords. I’ve run into plenty of sites that don’t accept the characters in my strong passwords for some reason. Often the length or addition of any special characters if prohibited.

    I’ve said it before, but I’ll note it here. Most of us aren’t competent at writing authentication routines and should just use one that’s already written and been vetted. More importantly, we should be sure the code, application and database, is modular enough and can be replaced if we find that our application needs stronger security. Because it will. We are constantly racing Moore’s law to implement better security.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 1.9MB) podcast or subscribe to the feed at iTunes and LibSyn.
  • Should Production Databases Be in a VCS?

    There was a great discussion recently on my true version of code editorial. It was interesting to see how some people viewed the idea of a version control system as the source of code, while others truly see the production SQL Server database as the truth. No matter how you view things, I had an interesting conversation with somebody later.

    This person asked if we could put the production database code into a VCS. Not as a way of tracking development tasks, but as a way of auditing production and ensuring that any changes in the VCS match with a separate VCS repository. This person noted that they would even like a process that automatically scripts objects and checks changes into a VCS. It’s an interesting idea, and one I hadn’t considered. However as I think about it, keeping a separate repo for production makes some sense.

    When I speak about Version Control, I usually recommend that the production database not be linked to a repo, but that’s usually because I don’t want production changes impacting ongoing development tasks. However, having a separate, production repo means that you have an independent way for the production DBA to verify what versions of code are deployed, and previously existed. This is separate from the development repo, which has to manage it’s own branches, merges, and potentially make mistake about tracking the versions sent to other environments.

    Production DBAs are often conservative about depending on others for the integrity and auditing of their own systems. After all, even when another individual or group makes a mistake, it’s the production DBA that is ultimately responsible. Keeping the object changes and deployments in a VCS, using tooling like SQL Source Control or even automated scripts, can give the DBA their own version of history, an audit trail, and a way to recover from problematic deployments without depending on developers or a full database restore.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.1MB) podcast or subscribe to the feed at iTunes and LibSyn.
  • T-SQL Tuesday #75–Power BI

    This month’s host is Jorge Seggara, the @sqlchicken, who works for Microsoft. A busy schedule caused a slight delay, so we’re posting the third Tuesday of this month, but that is OK. This is a great topic for T-SQL Tuesday.

    Power BI Data

    While Power BI is a great visualization tool, you can’t do anything without data. That means you need to find data, which is both easy and hard. Easy if you’re working within your own organization on a specific project. Slightly more complex if you want to look at data out in the world.

    However I saw this in a talk last year and I was amazed. This is the type of thing I’ve written before, and it’s cumbersome and problematic. I would think that SSIS would have made things this simple years ago.

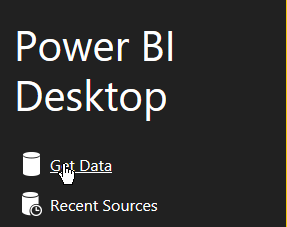
    I love sports, and wanted to play with some sports statistics awhile back. Finding good data is tough, at least in a format like CSV, that you can easily import. However Power BI makes this easy. Start up the desktop and you’ll see this:

    2016-02-10 14_07_40-Calendar

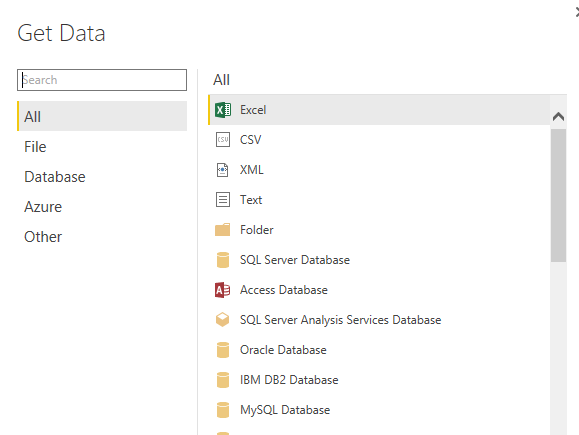
    Right away Power BI wants to get data. Click on this and the Get Data dialog opens, with lots of choices.

    2016-02-10 14_07_57-

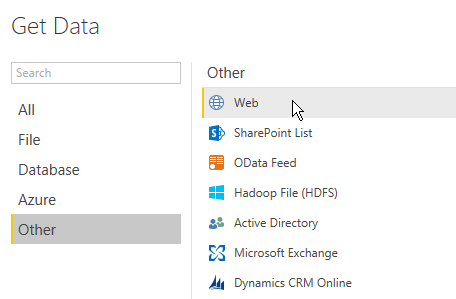
    However if you pick “Other”, you’ll see one more that I love. Web.

    2016-02-10 14_13_55-Calendar

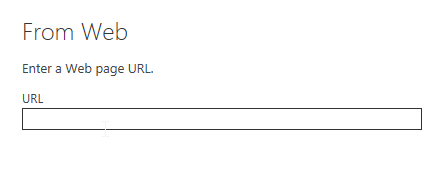
    Click this. You get asked for a URL. Any URL.

    2016-02-10 14_14_35-Calendar

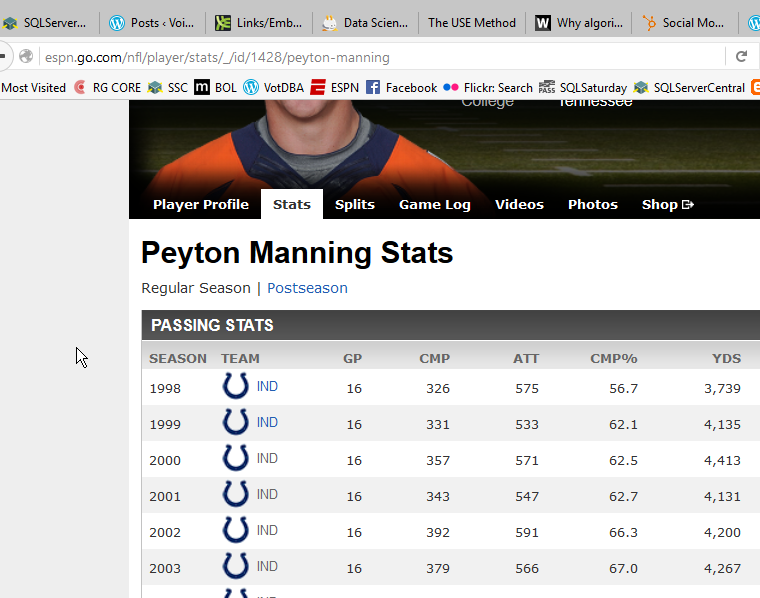
    I happen to have one handy. After the win for Denver in Super Bowl 50, I thought I’d look back at Mr. Manning’s career.

    2016-02-10 14_14_44-Calendar

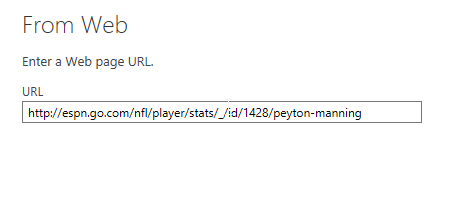
    I take that URL and drop it in the dialog.

    2016-02-10 14_14_52-Calendar

    Once I click OK, this will analyze the URL for tables of data. In this case, I get quite a few.

    2016-02-10 14_16_32-Calendar

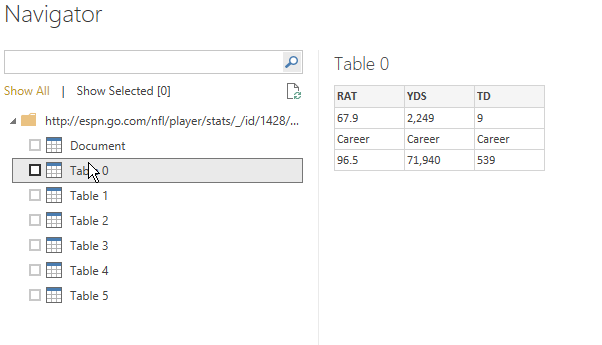
    Now, I can click each one to see what data this is. This isn’t what I want

    2016-02-10 14_16_32-Calendar

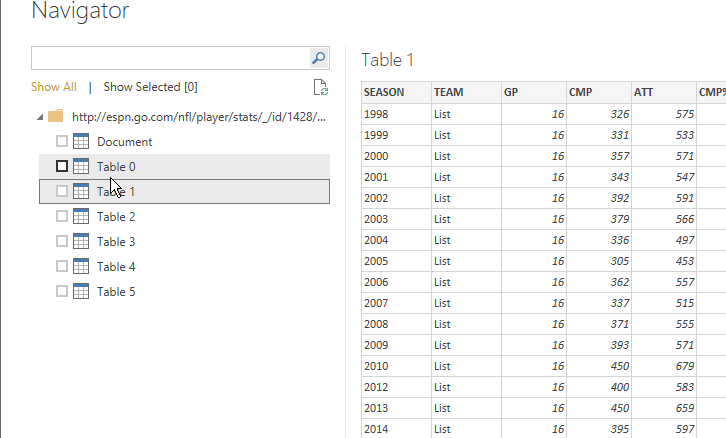
    But this is.

    2016-02-10 14_16_37-

    I now click “Edit” at the bottom to clean my data. I could just load it, but there are a few issues.

    2016-02-10 14_16_47-Untitled - Power BI Desktop

    I see all the data in the designer, and I have lots of options for working with this data.

    2016-02-10 14_17_11-Calendar

    First, since I’m going to do a comparison, let me rename the table.

    2016-02-10 14_17_02-Untitled - Power BI Desktop

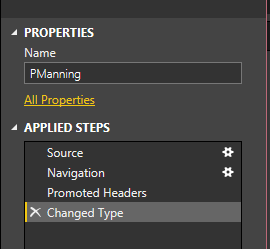
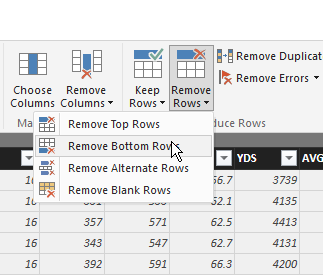
    Next, I see the steps below the name. I’ll add more steps, but I’ll do this in the designer GUI. First, let me remove the last row, which is a career summary.

    2016-02-10 14_19_28-Calendar

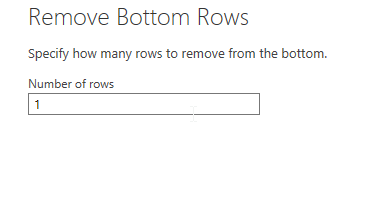
    In this case, I’m only removing one row.

    2016-02-10 14_19_36-Calendar

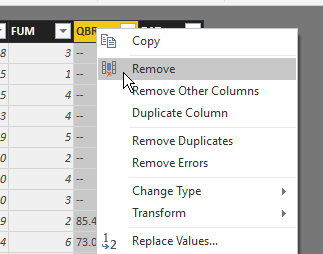
    Now, I want to remove a couple columns. In my case, I don’t care about a few of the data items, so I’ll pull them away. I can right click a column or choose “Remove Colums” in the ribbon. Either way, I get rid of QBR and Team.

    2016-02-10 14_20_50-Untitled - Query Editor

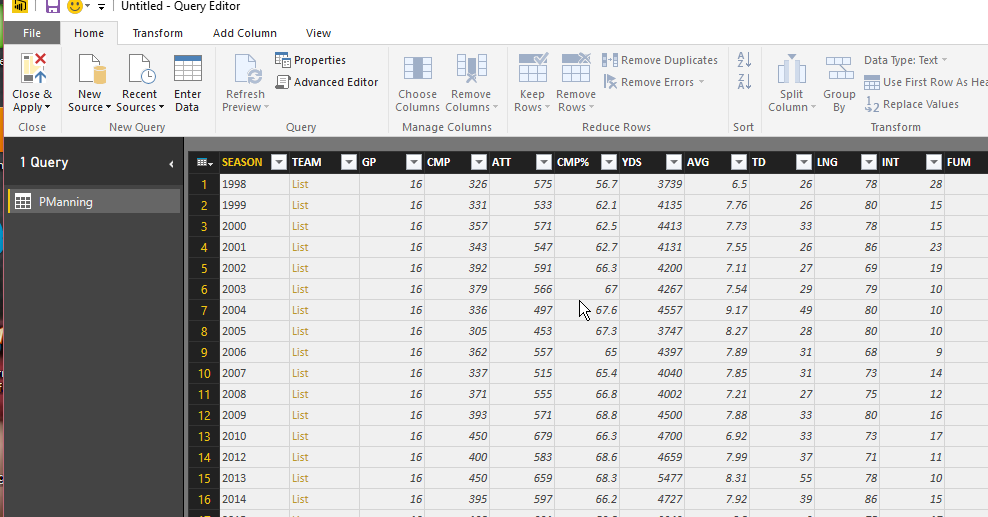
    Now I’ve got a nice year by year summary of Peyton Manning’s career. When I close and apply the query, my data is loaded into a data set for use by my Dashboard. I can then repeat this, and I’ll have two sets of data.

    And, here’s my PowerBI Dashboard. It’s not terribly useful, or interactive, but it’s got data from the web that I didn’t have to copy or move.

    https://app.powerbi.com/view?r=eyJrIjoiMWNmYzBiYjUtMTU3Yi00NWFhLWFiZjQtNTY0NzY4NDRkZTJmIiwidCI6IjY2NjBkOGZkLTJjNmItNDg0Mi1iZmZmLTcxOTY1YzE2NTczYSIsImMiOjN9

  • Zero Downtime for 2016

    I’ve never felt that zero downtime is possible for a system over any length of time. There are no shortage of companies that seek to prove me wrong, and some are doing very well. For example, when is the last time that the Google search engine was down? It happens, though I haven’t seen this in a long time. Many of the highly available applications out there are built using as distributed applications across many machines, so that even if there are failures, they don’t cascade to interrupt users.

    I was thinking about this as I saw a post asking database engineers to architect for zero downtime in 2016. That’s a good goal, and certainly if you work at a high profile retailer or service company, you should look for ways to improve availability.

    In fact, I would guess that anyone struggling with specific events, like Black Friday, would be working on this problem constantly. I remember years ago Michelle Ufford spoke about the challenges at GoDaddy during the Super Bowl due to the advertisements the company ran. They had log files that couldn’t catch up to the load for hours and spent an entire year working to build a better database system.

    Ultimately I think the best way to handle large spikes of activity is by building an application that avoids putting large spikes of activity on your database. Use messaging and queues to buffer traffic. Use read only copies of your database for traffic that doesn’t need to write to the main database. Anywhere that you can limit the load on your system can help prevent the database becoming a bottleneck for your system.

    Perhaps more importantly, if you can spread the load, you don’t need to purchase more and more hardware. If nothing else, I think this is a good argument for better database architectures for applications. However if you’re like me, most of your systems will have to deal with the hardware that is available. In that case, the best you can do is write better T-SQL and ensure you have given SQL Server enough, but not too many, indexes.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.6MB) podcast or subscribe to the feed at iTunes and LibSyn. feed