Author: way0utwest

  • The Last Job

    I was chatting with one of the more experienced SQL Server professionals I know recently and was surprised to know this person had actually retired, but come back to technology because they were bored with not working. I suspect that’s how I’ll be later in life, and am not really looking forward to retiring anytime soon.

    However I do think about jobs and employment as I age. I know that it can be tougher to keep a job over the long term. It seems the flexibility many of us appreciate as younger workers can be a detriment later in life when you value stability. With that in mind, here’s this week’s question:

    Is this the last full time, technology job you’ll have?

    I have an amazing job, perhaps the best one I could have imagined. I love what I do, but I do think about my options every year. I take some time to think about how my employment has gone in the past year, what else I might do and what I want to do in the future. I re-evaluate how I feel and try to be honest with myself about how I feel about my career. If I decide to make a change, I want it to be my decision, not something that’s forced upon me by a change in my employment status.

    I wonder if this will be my last job. I certainly think it could be, and the way it’s gone the last few years, I hope it is.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 1.5MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • T-SQL Tricks – Trigger Your Memory

    I was scanning Twitter the other day and saw a note from someone that they had written a query using an obscure T-SQL command and were glad it had worked. I exchanged a note with the person and they mentioned that they had to look up the command and syntax periodically when they had to write a similar query.

    I mentioned templates.

    If  you haven’t used these, you should, and I wrote a basic post about how to access them and one on customizing these for yourself. These templates are like Snippets in SQL Prompt (Which are way more useful to me), and they are a tool every DBA should use.

    Here’s one way I think they’re really helpful:

    Suppose I need to write a PIVOT query. I rarely do this, and it’s not too hard, but I write this query:

    select
        *
      from
        ( select
              runner
            , miles
            , mins
            from
              results
        ) as rawdata pivot ( avg(mins) for [miles] in ( [3], [5], [10] ) ) as pivotresults
    ;
    GO

    That’s easy enough, but it’s specific for my tables. However when I glance at it, I can see that there’s an aggregate columns, and I know the PIVOT requires that I list the values that are to be used in the columns.

    What if I change the query? I can do this:

    select
        *
      from
        ( select
              runner
            , <pivotcol, varchar, miles>
            , <aggcol, varchar, mins>
            from
              results
        ) as rawdata pivot ( avg(<aggcol, varchar, mins>) for [<pivotcol, varchar, miles>] in ( [3], [5], [10] ) ) as pivotresults
    ;
    GO

    Now if I make this a template:

    templates7

    I can drag this into a new query window. When I see it, I can CTRL+Shift+M and get this:

    templates8

    Now I change a few values and I have a pivot.

    templates10

    Of course, I need to actually enter the values I want, but this gets my PIVOTs done quickly without the need to decode BOL or swing by SQLServerCentral. Once I do that, I have a query I can use.

    templates11

    I’d encourage you to use templates. They’re very, very handy for quick sections of code that you use often, or want to remember in the future.

  • Citizen Programmers

    The Citizen Programmer, a piece at Simple Talk, really made me stop and think a bit. On one hand, the idea of building a platform that enables any end-user to perform rudimentary programming is a noble goal. If you can do that, then you can dramatically reduce the costs associated with waiting for developers to build applications.

    On the other hand, the article praises the Visual Basic of the 90s, which allowed almost any one to build an application.

    And that was a problem. Despite the tremendous number of applications built, far, far too many of them were poorly written, prone to crashing computers, unable to scale to more than a single user in many cases, and were almost un-maintainable over time. These applications removed people from their knowledge work, having them spend time programming instead of their regular job. That might be good in some cases, where people had talent and desire to build software. It certainly forced the person coding the system to better understand the idea behind the work that they were doing.

    However in many cases, I think we might have ended up wasting lots of time. Certainly the people spending more and more time maintaining an application weren’t necessarily getting more work done. People dealing with buggy software might have been doing their job more slowly overall. There were also the problems with turning a VB application over to professional programmers who were loathe to work on it, and perhaps did little work to keep the application running. A lack of responsiveness from technology departments might restart the whole process with another poorly written VB application, each one a custom work of art that stumbled along inside of a business.

    I do think that giving tools to enable end users to perform some of their own analysis and review of data is important. I like the idea of PowerPivot and other tools that let users query data and build their own reports. I don’t know if we need professional developers for every piece of software, though I am sure we need software to be written faster and in a more agile fashion. In all cases, however, I know we do need professional DBAs to manage data and ensure it’s protected and intact as the speed and scale of our systems continue to grow.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.7MB) podcast or subscribe to the feed at iTunes and LibSyn. 

  • Converting Dates

    I ran across a post recently where someone had dates stored as characters (never good), but also in this format: CYYMMDD. I’d never seen that, and thought it was strange. The person was asking for a way to convert this to YYYY-MM-DD, which I think it fairly easy.

    Let’s set up some data:

    CREATE TABLE RandomDates
    (
        myid INT
        , mydate VARCHAR(7)
    );
    GO
    INSERT dbo.RandomDates
            ( myid
            , mydate
            )
        VALUES
            ( 1, '0600102' )
           , ( 2, '1121004' )
           , ( 3, '0920415' )
           , ( 4, '1040611' )
            ;
    GO

    The format for the data is 7 characters denoted as century, year, month, day. The century is encoded, with the single value representing:

    • 0 = 1900
    • 1 = 2000

    That’s pretty straightforward and it means that we have two dates in the 1900s and 2 in the 2000s. The dates are:

    • January 2, 1960
    • April 15, 1992
    • June 11, 2004
    • October 4, 2012

    Querying these dates and converting them is straightforward, but there are a couple ways to do this. If we are just looking to convert these to characters, I saw this solution from ZZartin.

     SELECT CONVERT(DATETIME, CASE 
                                WHEN LEFT(mydate, 1) = '1' 
                                    THEN '20' 
                                    ELSE '19' 
                                END 
                                + RIGHT(rd.mydate, 6)
                    , 112)
      FROM dbo.RandomDates AS rd;

    That’s fairly straightforward, and overall I like it. It uses simple functions and puts things together.

    I had another idea, mostly because I initially favored keeping the items separate as parts of the date in case I needed them. I thought about DATEFROMPARTS, which is a SQL Server 2012+ function. My thought was to calculate each of the parts and send them into the function like this:

    SELECT DATEFROMPARTS(
                        CASE WHEN LEFT(mydate, 1) = '0'
                            THEN 1900
                            ELSE 2000
                            END + SUBSTRING( rd.mydate, 2, 2)
                        , SUBSTRING( rd.mydate, 4, 2)
                        , SUBSTRING( rd.mydate, 6, 2)
                        )
     FROM dbo.RandomDates AS rd
     ;

    My idea has more function calls, and I’d think it would take longer to build, but I’m not sure. Let’s test.

    I’ll use Data Generator to insert a few million rows into this table. Then let’s run both pieces of code.

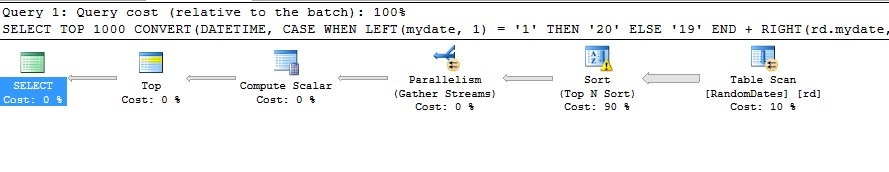
    The first code, from ZZartin, required about 19,000 logical reads and this execution plan when I ran it a few times. The CPU execution was in the 40k ms, and about 9 sec of real time.

    dates1

    The second code, mine, had about 30,000 logical reads, with only 8k CPU ms, but about 40sec of real time. The execution plan:

    dates2

    That’s interesting, and it matches what I’d expect. The first code is much simpler, intuitively, and it’s easy to read. With the format of the date essentially in order, it doesn’t make sense to try and "assemble" the date from parts. It’s easier to convert the first character to two (with the CASE) and then just cast this as a date.