Author: way0utwest

  • No Shortcuts for the SQLCMD Batch Terminator: #SQLNewBlogger

    I was messing around with SQLCMD and I realized something I hadn’t known. I’ve never tried it, but the batch separator has to be separate, which I’ll show.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    The Batch Terminator

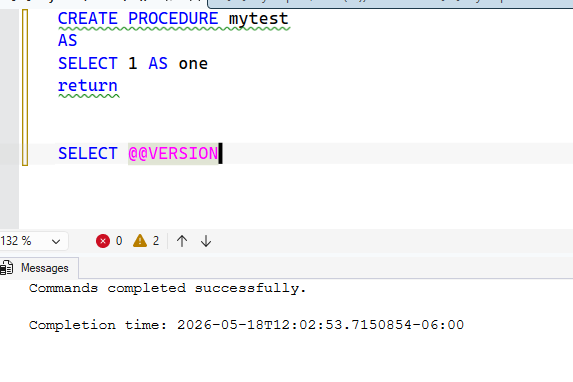
    The default batch terminator in SQL Server tools is “GO”. We tend to use this in SSMS, and many of us know to type this in SQLCMD when we use it. In SSMS, we sometimes need it. Here’s an example where I create a proc and add a RETURN, which some people think means the proc ends.

    It doesn’t.
    2026-05_0092

    The SELECT @@VERSION is a part of the proc. Now, if I drop the proc and then add a GO at the end of a line, , I get this:
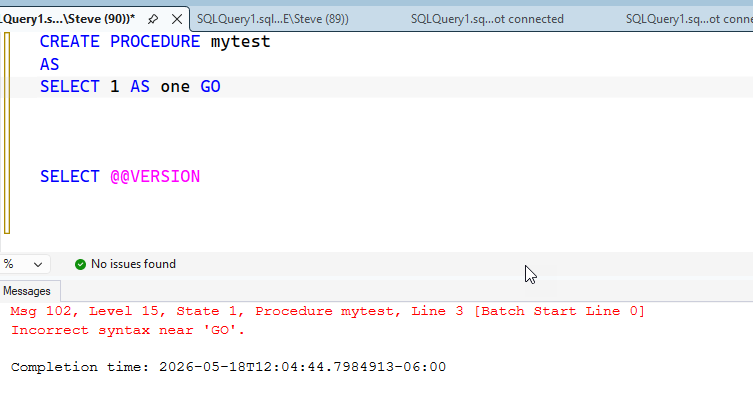
    2026-05_0093

    Makes sense. Let’s try two commands. In this case, the GO is skipped and I get two results.
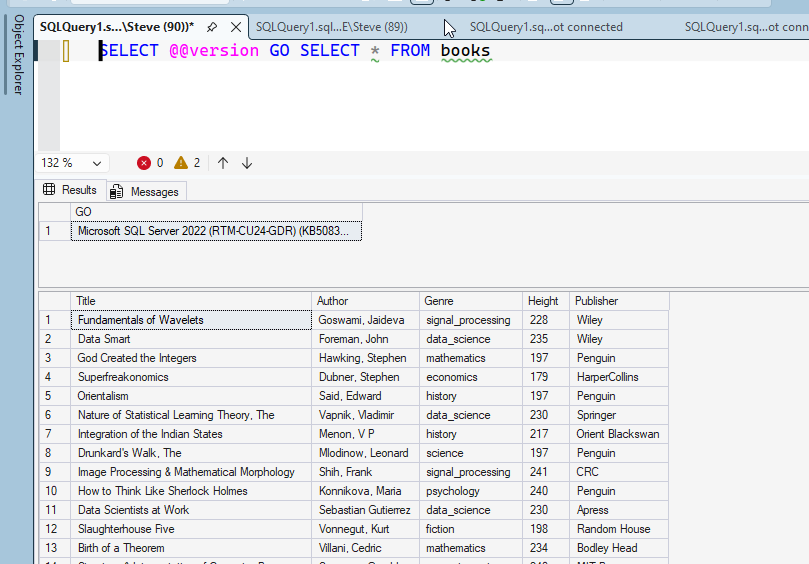
    2026-05_0094

    Using SQLCMD

    If I run SQLCMD and enter that code, I get a new prompt. That’s because the batch separator in SQLCMD is a batch terminator. This is in the SQLCMD docs, and since I haven’t terminated a batch, nothing happens.
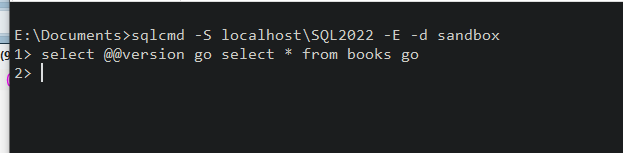
    2026-05_0095

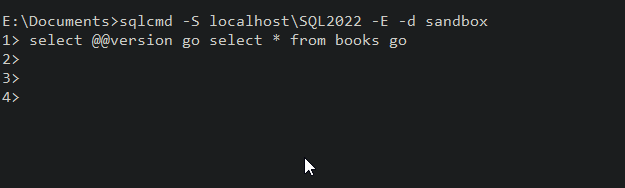
    If I hit enter, I get a new prompt. This continues until I enter a go.
    2026-05_0096

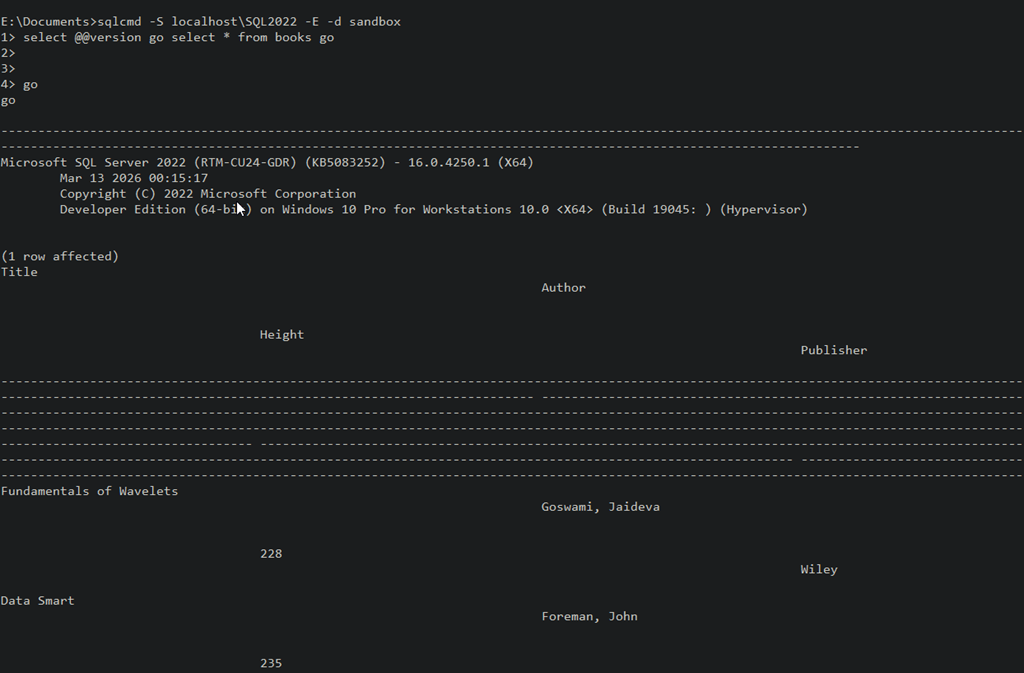
    Once I enter Go, I’ll see my results.
    2026-05_0097

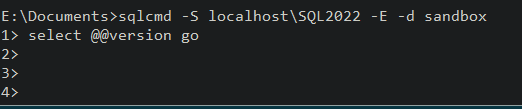
    A good thing to know, as you might think you can enter “select * from @@version go” and think it might execute. It won’t, as you see below:
    2026-05_0098

    This isn’t likely a problem for most people as they’ll instinctively enter GO if something doesn’t run, but newbies might miss this.

    SQL New Blogger

    This was about a 10 minute post, based on an experiment to see if I could get something to run quickly. Since I ran the experiment, I captured some screenshots and built this post.

    Showcase continued learning, especially in this era of AI where you might need to guide an LLM along a better path.
  • The Slow Growing Problems

    Both as a DBA and developer, I’ve had plenty of immediate, this-is-broken, fix-it-quickly issues. Usually, I, or someone else, wrote some bad code and somehow got it deployed. I mean, I do test things, and I would (probably) never change code after I’d tested it to fix that one little annoying thing, like the formatting. I’d (almost) never do that, and I’m sure you wouldn’t either.

    Yet somehow bugs slip in at times.

    Those are the acute issues, and they can be hard to fix at times, but often we can reproduce the problem in development and build a fix. Sometimes we even spot the issue quickly and just fix it in production. I’m sure you never do that, but I have had that experience myself a few times.

    However, in the database world, we can have other, slow-growing problems. I saw this post from Jacob Sebastian about production issues that don’t trigger alarms. There are just slowdowns that trickle across multiple systems and cause issues for clients. These aren’t things you instrument for, as a slowdown isn’t necessarily an issue. These things can resolve themselves, or they can develop into a major issue.

    I think about this like vehicle traffic. A minor fender bender on a highway might not be a problem, but it can become one. Cars don’t get out of traffic quickly enough, or traffic police don’t arrive soon and move the cars. Traffic starts to back up, which slows down the response, including that important tow truck that might keep things moving. Suddenly, it’s not a few people inconvenienced by an accident, but thousands.

    There are likely signals in your environment that would let you know about a potential issue coming soon. These are subtle and not always indicative of a problem individually, but taken together, they indicate a production issue is going to occur. To me, this is a place AI can eagerly be taught to look for these signals and then happily keep looking for them every day.

    The future of monitoring is the active examination of correlated data that precede an issue, hopefully giving humans, or other AIs, enough time to respond and prevent customers from experiencing a slowdown.

    I’d certainly welcome this in both traffic motorways and database systems.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • AI Experiments: Parsing Payment Memos

    As part of my running the SQL Saturday charitable foundation, I get sponsorship money from vendors. Primarily Microsoft and AMD, but I hope to change that in the future. In any case, I recently got a payment notification that my invoice had been paid.

    I knew I had a few invoices outstanding, so I wasn’t sure what was included. MS tries to bundle payments, but I don’t get an email for each one. For this one, I didn’t see an email, so I suspected I’d put the wrong one in or typo’d it.

    The Usual Process

    When I get payments, I have to reconcile those in my General Ledger, recording the amount and allocating to the events. I then send out payments to the event organizers and record those.

    This is a mostly manual process, but since I sometimes submit multiple invoices at once, I have to figure out what was paid. I could submit 3 invoices and get 1, 2, or 3 payments. Microsoft Finance usually bundles things, but since I can have a lot of events in flight, I need to know where money gets allocated.

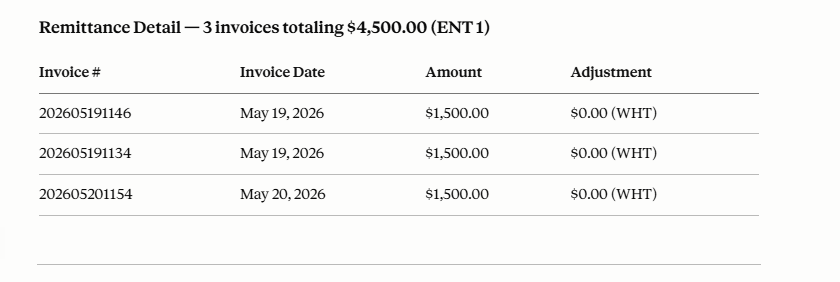
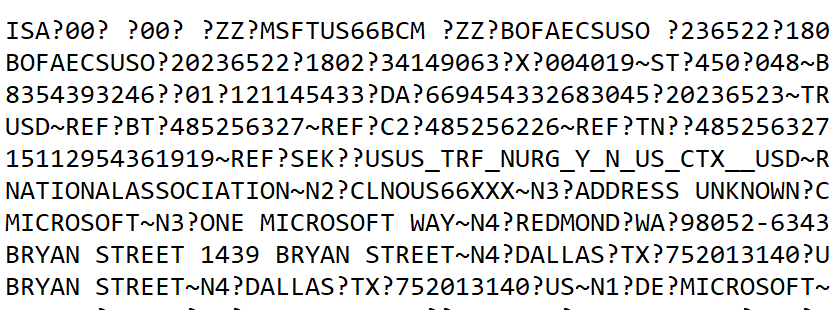
    In this case, I didn’t see an email and didn’t want to log into the invoice system and start finding the various invoices paid and clicking through details. Instead, I logged into the bank to verify the amount and I saw a memo. It was something like this (I’ve changed a bunch of data in here.

    2026-06_0123

    I thought it would be obvious which invoices were paid, but I couldn’t quickly figure this out. I decided to turn to AI.

    AI to the Rescue

    First, I knew I had a “no training” AI plan with Claude, so I wasn’t concerned about data release here.

    I had this prompt and then pasted in the data: “can you help me separate this by ? and make sense of what is included?”

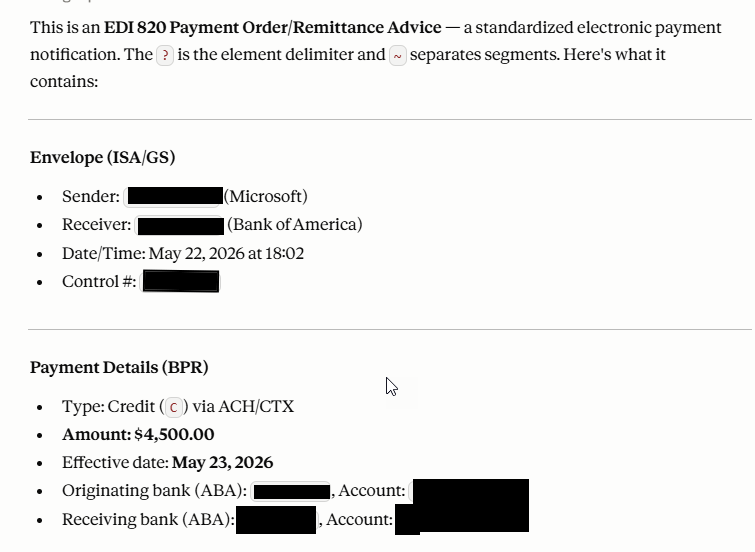
    The result was interesting, and useful. It labeled this task as EDI 820 parsing, so apparently this is EDI format. The last time I worked with EDI is was XML based, but perhaps this is the new way of doing things.

    The results were great. I got a summary, none of which I needed, but good to know this was easily recognized and parsed.

    2026-06_0124

    The really interesting part was below some of the acronym descriptions, where my invoices were found.

    2026-06_0125

    I knew this would be certain events, but wanted to double check the numbers. When I put in an invoice number, I use the date and event. Here I got 3 of my events (1146, 1154, 1134) paid from a day where I invoiced 5 events. This let me quickly enter my GL and also know to whom I was sending money.

    A cool time saving AI trick. Rather than 10-15 minutes to reconcile things, AI gave me answers in seconds and I had fixed the GL in a couple of minutes, allocating the funds to events.

    Of course, I needed to ensure data security with my plan and I verified these were events where I had planned to send money. Still me as the expert reviewing things and making decisions, but way easier than trying to sort out invoice numbers from a bunch of EDI text.

  • Liability for AI Errors

    This week there was an article that speculated that doctors in the UK could be liable for errors made by AI tools unless rules are changed. The argument is that AI tools should be treated as products, which isn’t necessarily the case right now. Right now doctors may face all the liability instead of AI tool makers having some responsibility. From my reading, this doesn’t appear to say that doctors aren’t still accountable for mistakes, but they aren’t wholly accountable. The Medical Protection Society wants the technology vendors to bear some responsibility.

    I have to admit I’m torn here. If doctors are using tools, they should be sure the tools work well and they agree with the recommendations or results. However, I think AI changes things somewhat. If I read a medical device, say one that analyzes blood, I expect that the results are deterministic and accurate. If they aren’t, how could I, as a doctor, know that. The companies the built (or maintain) the device would be culpable for errors.

    Using AI assistance, however, is a little different. This is a non-deterministic interpretation of data. In the same situation, if an AI were to interpret blood results and summarize them, perhaps failing to point out a deviation of a value and this impacted patient care, is the AI responsible? The doctor for not realizing there is an issue? Joint responsibility?

    I think it’s unclear. I’m not 100% sure how I feel here, and I lean towards both being liable. If someone is training an AI model to help with medicine, then they ought to bear (and feel) accountable for results.

    This seems different than software engineering to me. In medicine we have humans overloaded and AI is supposed to help, but has to be responsible. I don’t think the stakes are as high in producing software. It’s an arbitrary decision to say we need to get xx work done with yy resources. AI can help, perhaps amplify the abilities of people to produce code, but the people still have to verify the AI results. Any time pressure is a decision we make, not one brought on by medical issues.

    Perhaps this seems hypocritical, and I will admin I’m not 100% sure how I feel, but I’m more concerned with AI technology bearing responsibility in healthcare than software. Do you feel the same way? Or perhaps in either case the AI is just a tool? Let me know what you think,

    Steve Jones