Author: way0utwest

  • Faster Cloud Warehouses

    I think the cloud is a perfect place for a data warehouse. In many organizations, I’ve found that a data warehouse system is often the largest SQL Server database, both in size of database and also in terms of resources allocated. These systems often handle many complex queries for business users and are allocated a large number of CPUs as well as lots of RAM. Even then, many ad hoc BI tools or lots of “what-if” queries can bring the system to its knees, often causing lots of stress for database administrators during the periods of time when the system is in heavy use.

    Fortunately, many of these systems aren’t in use all the time. Often these are systems used by financial departments to “close the books” at month, quarter, or year end. It’s at these times when lots of resources are needed. Outside of these times, the data warehouse might be one of the least used systems, which makes it a perfect choice for a cloud, scale on demand, environment. Scale up when needed, down when not, limit your costs to the resources you need, when you need them.

    Microsoft has increased the capabilities of the Azure SQL Data Warehouse quite a few times across the last few years. I was thrilled to see ASDW separate out storage from compute, allowing customers to scale up the query, or compute, nodes independently of the storage used. Changes last year improved the ability to move data around between compute nodes as well as increased the number of concurrent queries.

    These improvements are perfect for data warehouses, and if you are looking to build a more responsive SQL Server based warehouse, you ought to take a look at ASDW. More and more customers are finding it valuable and cost effective in their businesses. What seemed to once be a niche idea has grown into a business that quite a few customers are using, with the demand growing.

    What’s more, the move to Big Data Clusters in SQL Server 2019 seems to have adapting some of this technology to the regular SQL Server product many of us use. These will separate out the storage from compute, something that should help many of us scale our systems to meet the demand of our workloads. I haven’t tried a big data cluster yet, but I’m looking forward to seeing how well one works and if it truly scales SQL Server further than I would have dreamed.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.6MB) podcast or subscribe to the feed at iTunes and Libsyn.
  • The Lost Time

    Last year when Daylight Savings Time moved clocks back, I was wondering how the time change might affect different devices and situations in the world. One area that I wondered about was medicate and health care devices. While I’m sure most (hopefully all) medical device software developers have thought about this, it was something that struck me this year as I was fighting a cold.

    I was taking a medicine designed to help reduce the length of illness and was supposed to take this every four hours. That meant if I took this at 10pm, the next dose should be 2am. However, if I woke up at 2:10am, it would actually be 1:10am since the clocks would have moved back an hour. If my clock adjusted itself, then it would be 3:10am. Not a big deal for my dosage, but for some people, this might really matter.

    Certainly software can adjust for this, but can we humans? If I’m dosed every four or six hours, common time frames, both me and my caregiver might get used to a schedule. We might assume that 7am, 11am, 3pm, 7pm is the schedule. We know that 7, 11, 3 repeat throughout the day. Daylight savings time changes that. Once the clock resets, I need to move to 2, 6, 10 the next day. Or to 1, 5, 9 depending on the time of year. It would be easy for someone to think they’d missed a dose and double dose, or assume that medicine was given last out and skip a dose.

    What about sales transactions? I’m sure this is a slow time of the day and year, but still, I’ll get a skewed view of that hour. Either zero sales or double sales. What about auditing? Is this the perfect time to break into a system or perhaps game the tracking of events? If I came and went from a facility during the hour in question, could I leave before I arrived? How could we actually capture a true audit record here?

    Daylight Savings Time might have been a good idea at some point, but these days I think it’s silly and causes more potential issues than it solves problems. I’d like to see it go away and have us stick to some consistent schedule throughout the year. Standard time, savings time, split the difference. I’m fine with anything, just don’t arbitrarily move my clock during the year.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.2MB) podcast or subscribe to the feed at iTunes and Libsyn.
  • Starting a Proof of Concept with SQL Change Automation

    One of the ways that you can more easily perform database development tasks is with SQL Change Automation (SCA). This is a plug-in from Redgate that works with Visual Studio, and while there are tutorials on Setting up SCA and starting in VS, I wanted to add my own take that might make this a little easier for some people.

    This is a short Proof of Concept (PoC) that gets you started, and I’ll add in more features over time in future articles. I’ll use the idea of a database of builds for SQL Server, which is a project that you might find useful in your organization.

    Starting in Visual Studio

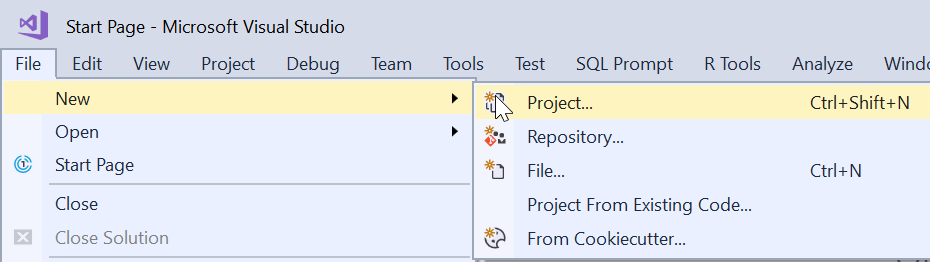
    If you’re an application developer, you are familiar with building new projects. If you’re not, you can probably figure this out, but I’ll just describe and explain the process. In the File Menu, we start our PoC with a File New.

    2018-09-18 20_17_49-

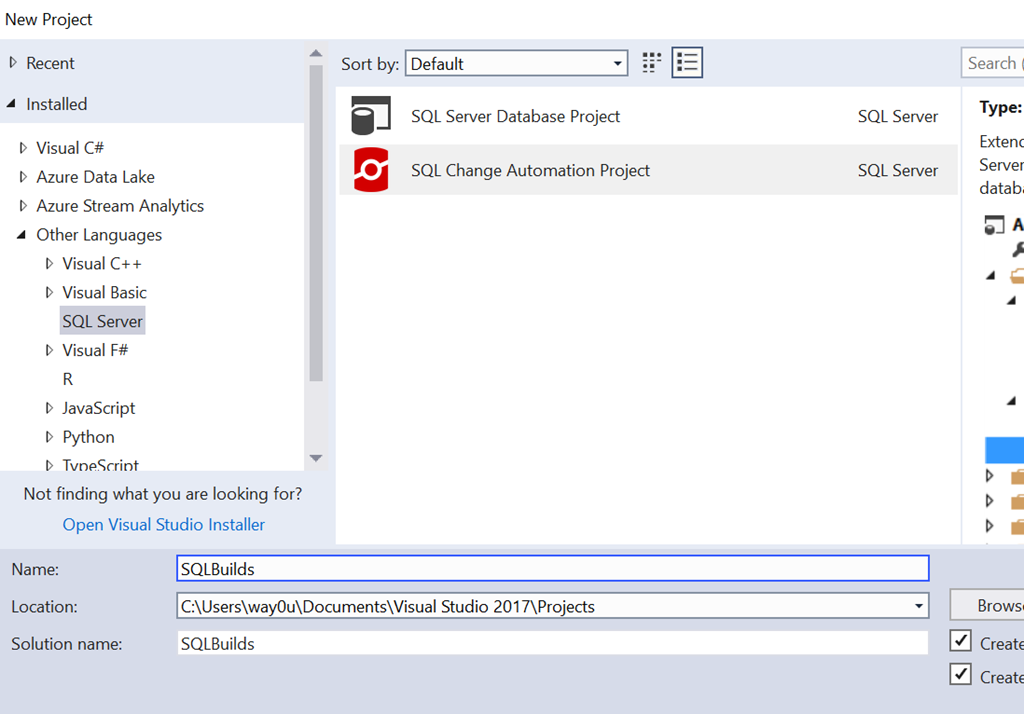
    Once you do this, you’ll see a large list of project templates or types. You can see the recent, installed, or even online types. These are broken into a weird mix of languages and target platforms, but in any case, SQL Server is relegated to the “Other”. Along with SSDT projects, if SCA (or ReadyRoll) is installed, you can choose this type.

    2018-09-18 20_19_14-New Project

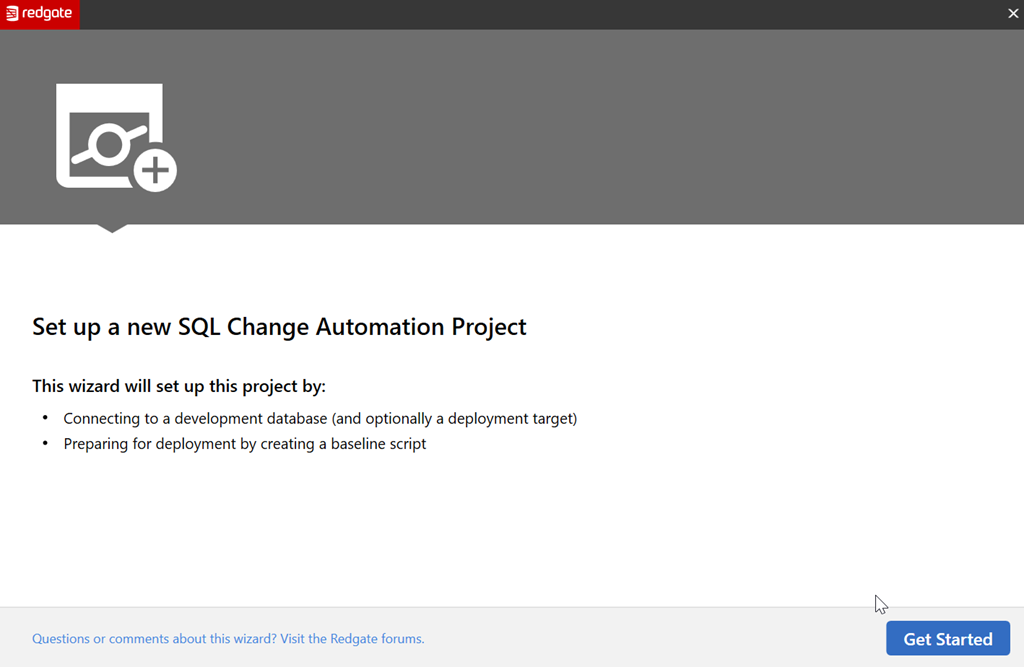
    Once we do this, the project is created, and an outline appears in the Solution Explorer. Before you can go there, SCA pops up a Getting Started dialog. This is designed to help you get moving since the project doesn’t necessarily lend itself to an intuitive flow.

    2018-09-18 20_19_30-

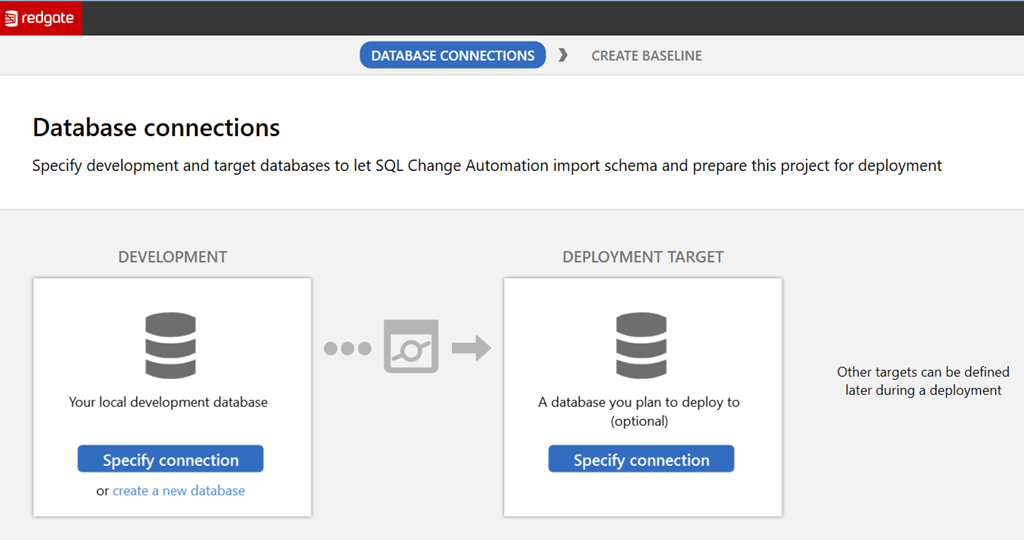
    Let’s get started, as it says. The next screen you see is the database connection. This is a slightly confusing dialog to some, but it makes sense once you understand the purpose. We have two connections with buttons and some links, as shown here.

    2018-09-18 20_19_40-

    The left side is the development database. The instance chosen is also going to be the place where your shadow database is created. You can pick an existing database here by picking the instance and database in the connection dialog. Alternatively you can create a new database, where you’ll specify the details.

    The right side is the target database, which is the downstream target you’ll use for deploying code. This could be production, or it could be a QA database. Either way, this is a default target, and this can be overridden with parameters in the SCA PowerShell cmdlets.

    For now, let’s ignore the left and leave it blank. For the right, let’s create a new database. Once we click the link, we get this.

    2018-09-18 20_20_04-

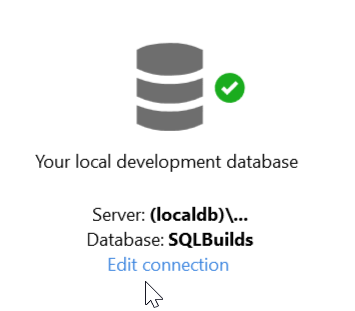
    The default database is the name of the project. The default instance is a LocalDB instance, which is an in process SQL Server. This is named (loadldb)\Projectsv13 in the  current (Aug 2018) versions of SCA. I’ll leave this alone, but the Edit Connection link would allow you to pick a new instance and database.

    Once this is created, we return to the dialog, seeing the dev database and the target, which we left blank. When we move forward, we see this dialog.

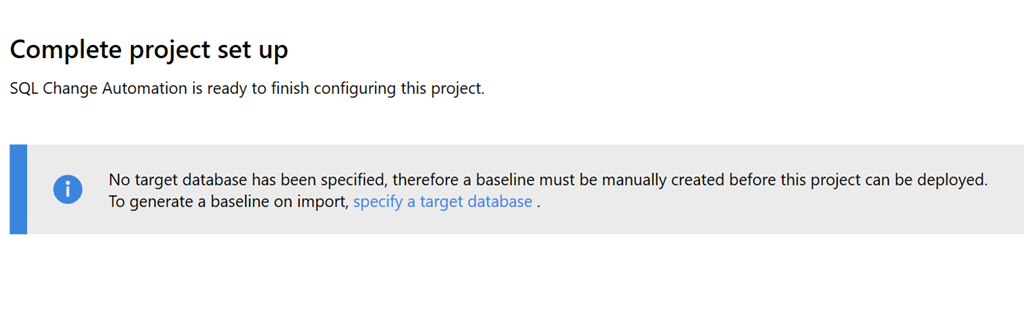
    2018-09-18 20_20_16-

    This is a reminder that we didn’t create a target, but that’s OK. We can do that later, especially since this is a new project. There is no baseline, which would be an initial script to rebuild the database to its current state. Right now our baseline is nothing.

    I’ll create the project and go back to VS. Once I go that, I can see the database on the LocaDB instance in the Object Explorer. I also see the Shadow database here.

    2018-09-18 20_27_51-SQLBuilds - Microsoft Visual Studio

    If I click Refresh in the SCA pane, I’ll get no results since there are no objects in the database.

    2018-09-18 20_27_35-SQLBuilds - Microsoft Visual Studio

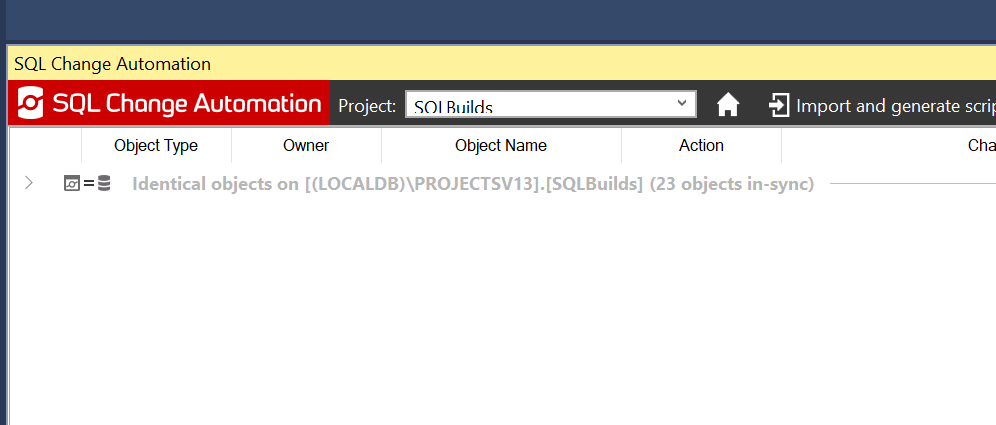
    Once this runs, I see that all objects are identical. This means the dev database and the shadow database have verified each other.

    2018-09-19 00_43_59-SQLBuilds - Microsoft Visual Studio

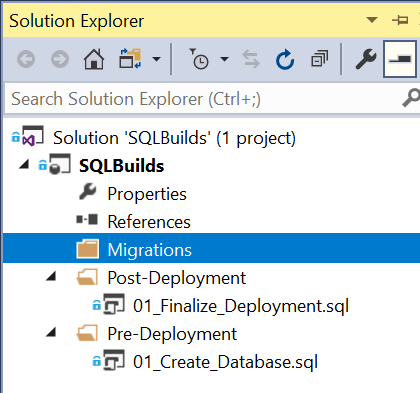
    My project is similarly blank. In solution explorer, I see the outline of the project.

    2018-09-19 00_46_24-SQLBuilds - Microsoft Visual Studio

    At this point, I can begin development. Migrations scripts I create will appear under the Migrations folder and if necessary, I can edit the pre and post scripts. Or add more scripts here. The default scripts are in place already, but I can change them as needed.

    In the next post, we’ll start development.

  • The Justification Database

    I saw an article on the security at various Department of Defense facilities that control the ballistic missile systems in the US. It’s interesting reading, especially if you want to shake your head at bad practices. I think this article summarizes just how quickly the digital world has grown faster than the ability of humans to keep up and adopt new practices, especially where constant staff turnover is the norm.

    This is a good read for anyone in an organization that must plan for security and account for new staff on a regular basis. It certainly made me think a bit about how information is presented, disseminated, and the view from the other side. It’s easy for me to consider security and focus on that from my position, but for others that are tasked with other jobs, their view is completely different.

    There was one item in here that made me stop and think. There is a section, titled “No database with written justifications”, that notes that there wasn’t a database of reasons why someone was granted access. Through random sampling, the found that lots of employees didn’t have forms filled in completely with justifications and approvals. In some cases there weren’t even forms. I assume these are digital forms, but they could be paper.

    That made me think about the ways in which I’ve granted access to individuals in databases in the past. Often in small companies the request is verbal or in email, with approvals made the same way. Certainly there’s no tracking. In larger companies there might be tickets in some helpdesk system, but how do I track those back to clicking in SSMS to add a user to a role?

    This week I’m wondering how well managed your system is for managing and approving security changes? If someone was concerned that a hacker gained access through social engineering, could you track down where, when, and why someone was granted access? Are you regulated or audited? I know some people have great processes that limit the potential for abuse, but I also know that far too many people use exceptions to get work done. I wonder how many of you allow for exceptions to your process.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.4MB) podcast or subscribe to the feed at iTunes and Libsyn.