Author: way0utwest

  • Testing BackBlaze Restores

    The most important thing for a data guy is having a way to restore data. If security, performance, etc. are broken, those can be fixed is we have the data. If we don’t have data, does security matter? It’s important, but secondary.

    When Crashplan stopped providing a multi computer setup, I needed to get a new solution for home. I asked on Twitter and then wrote a bit about my evaluation and choices.  These were my particular requirements, and yours may be different. In any case, I decided to evaluate BackBlaze under their couple week evaluation and keep the system simple for both my wife and I. As a part of that evaluation, I tested restores.

    Missing a File

    I didn’t simulate a crash and restore all my files, but instead decided to test this while out of town. I was in the UK, at the Redgate Software office and wanted to check an expense report I’d submitted. I also wanted to get the latest expense report to add some items to it. I keep these on my desktop, but I haven’t setup a home VPN for access, nor would that have helped. My desktop was powered down for my 11 day trip.

    I decided to see how BackBlaze was working. My first step was to connect to my account on the BackBlaze.com site. I logged in and saw my machine listed in the Overview. (I reshot these images later, so the dates aren’t shown)

    2018-06-28 08_41_14-Window

    Note: I didn’t have Backblaze software installed on my laptop.

    I selected Restore and went to a new screen where I had a choice for the restore. I selected getting a ZIP file, but it’s nice to have other options for large files. If I were pulling back 2TB of images, I might just pay for a hard drive.

    2018-06-28 08_41_24-Window

    Below this, I saw my drives and I could navigate to select select files.
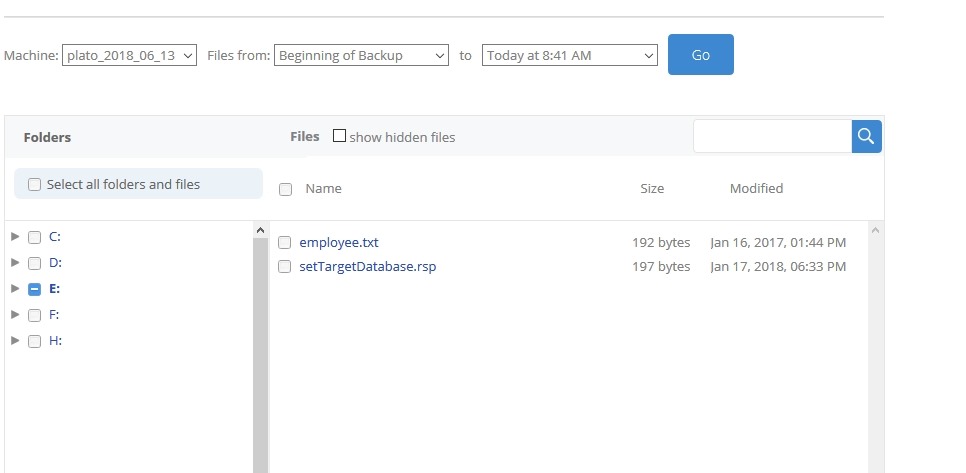
    2018-06-28 08_44_21-Window

    I also had options to  see different versions of backups.
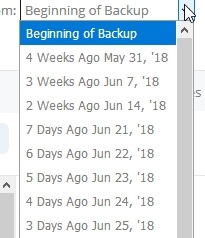
    2018-06-28 08_44_42-Window

    Once I found files, I picked the one I needed and started the restore. Just for a test, I picked a file on a different drive to see what would happen.

    2018-06-28 08_42_14-Window

    I went on with my day, and within an hour, I’d gotten an email. This let me know my restore was ready and I needed to securely sign in to get the download. I like that this was a sign in and now just a link to some random file.

    2018-06-28 08_47_19-Window

    I downloaded the zip file and inside were the files I’d selected. I unzipped them and filled out more of my expense report.

    This was a smooth process and validates my decision to use BackBlaze. It’s easy for my wife, which she’ll appreciate, and I can easily access things on the road.

    My trial goes until the end of June, but I’ll sign up for the service once I return home as this will work well for me.

  • Updating VSTS to SQL Change Automation

    We (Redgate) released SQL Change Automation a few weeks back. This is the first stage to implementing a combined toolset that works with both state/comparison development and migrations based development. The change updated both our migrations toolset (previously ReadyRoll) and our build/release cmdlets (DLM Automation) to SQL Change Automation (SCA).

    I have pipelines that are setup with Redgate DLM Automation tasks. This post shows how I updated the first of these to SCA.

    Finding the Build

    Here’s my current VSTS build pipeline for a project. Note that these are DLM Automation 2 tasks. There is a single task that you configure with the Operation (on the right) to build, test, or sync a database.

    2018-06-28 16_56_49-SQL Server Builds - SOC-CI - Visual Studio Team Services

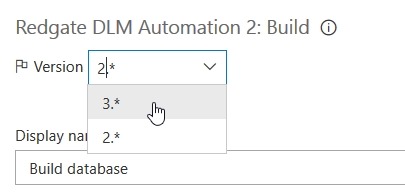
    Note that there is a version drop down at the top of the right side. Here I need to drop this down to find the SCA task, which is version 3.

    2018-06-28 16_58_05-SQL Server Builds - SOC-CI - Visual Studio Team Services

    Once I select this, you’ll see that my task changes to SCA, both on the left and right.

    2018-06-28 16_58_14-SQL Server Builds - SOC-CI - Visual Studio Team Services

    I can change both tasks to v3 and I’m set. This is really the change that we’ve done, and we’ve combined operations. If you drop this down you will see there are SCA (migrations) projects here along with SQL Source Control state projects.

    2018-06-28 16_59_28-SQL Server Builds - SOC-CI - Visual Studio Team Services

    This means that if I convert from a SQL Source Control/state project, my pipeline stays intact. I’ll just change the operation from a build with SQL Source Control to one with SCA.

    This mostly works, but there are some path differences for release, so I’ll talk about those in another post.

    This is a simple change, but it’s important for future strategy. You can watch a bit of our strategy in this SQL in the City video on the database deployment pipeline. If you want to give this a try, download SQL Source Control and/or SQL Change Automation and start a test project.

  • Where’s the schema?

    Across the last few years, I’ve read many articles and listened to quite a few talks that discuss the advantages of NoSQL databases. I’ll admit that I’m often skeptical of the advantages of other datastores overcoming the disadvantages with a relational system, but I try to keep an open mind. I do appreciate that there are some benefits to using another data store in certain situations.

    One of the talks I heard recently discussed the fact that in many of these stores, we can add data in a “schemaless” fashion, and it’s stored in a flexible format that allows the developer to quickly capture the data they are using and retrieve it without requiring up front design work to build a particular format.

    That had me pondering the question of whether or not here really are schemaless data structures. If a developer  (or whatever SDK or framework they use) looks to persist come data, clearly there is a format of sorts, which means there is a schema. That schema might not be transferred or persisted in the data store, but there is some schema they expect, both on storage and retrieval. Whether this is a JSON, XML, some proprietary structure, or something else, there’s an known structure that the developer uses to work with the data.

    Is there really schema-less data? I tend to think no. All of the data we have contains some schema. That schema might vary from row to row, which is often what developers like when building applications. There is, however, a structure. The developer knows it, and must serialize and deserialize the data, or depend on some library like ADO.NET to do so. This often appears to a developer to be a lower barrier to entry. There’s less complexity and often no need to map the objecct-like structure of properties to some relational schema and make decisions on sizes.

    That’s not completely true, as the schema of the data still exists and must be persisted in the application. There is code that must handle the various values stored in some hierarchical fashion. If this changes over time, as values are added, the the application must deal with the missing values in older properties or arrays. If items are removed in the application, then would older sets of data just disappear? Perhaps, but the developer must make a decision, which may have implications for users of their application. This doesn’t even deal with the issues of aggregation and reporting, which might force other systems to implement the same schemas and business logic. Those rules and specifications don’t easily transfer from one application to another, especially when different teams or developers are involved.

    There’s always a schema, and the rules have to be implemented up front, or later on. Whether you use a RDBMS or a NoSQL store, you are going to be dealing with a schema. The question is do you want to deal with it in a central location or in every application? I lean towards the former, but you might prefer the latter. Neither is wrong, but you should be sure you understand all the advantages and disadvantages of your choice.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 4.1MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Building Better Test Data on the Redgate Hub

    I have a new piece published over at the Redgate Hub: Building Better Test Data with SQL Provision. Part of my job is helping people learn to use our products better, and provide not only solutions to issues, but also ideas that might help them think about new ways to use products.

    I’m a big believer in testing and having good test cases in your data. This piece gives a technique I’ve used in the past to ensure we test everything we need.