Author: way0utwest

  • DevOps Debugs the Demo

    I had my 24 Hours of Pass session today, Database DevOps to Ensure Compliance, and my demo broke. At least, it broke for me. I kept going and talked over things, but I hate that. It would have been impressive if it had worked.

    Debugging

    In a live session, I might have debugged this a bit more. I’ve had things fail a few times over the years, but before I was doing the DevOps thing, I couldn’t usually figure things out until I got back to a desk. With DevOps, I’ve solved a few things with the instrumentation.

    In this case, I was cognizant of time, as another session was starting after mine, without the break that usually comes. Plus since it’s online, I can’t tell if anyone really wants to know what happened.

    I do, and as soon as the webinar ended, I looked at the release and realized what happened.

    The Error

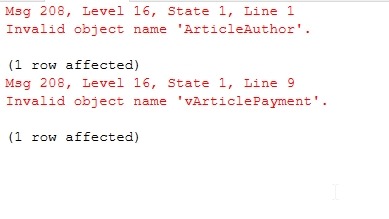
    I had this error.
    2018-06-12 16_11_47-Window

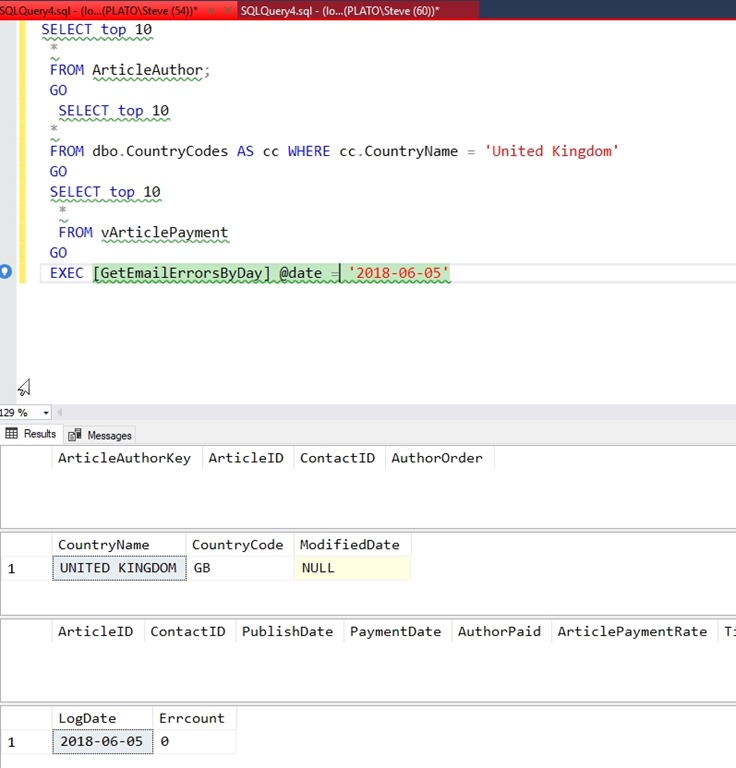
    I’d made four changes in Development that were supposed to deploy through to Production. I know they do because I’d done this not 15 minutes before the webinar, so the process was working. No errors, so what was wrong?

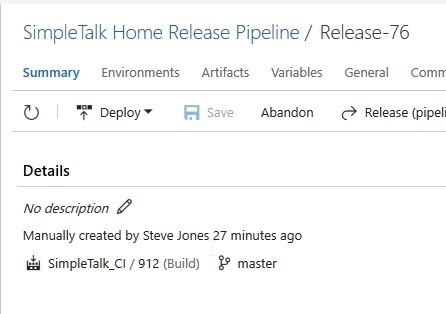
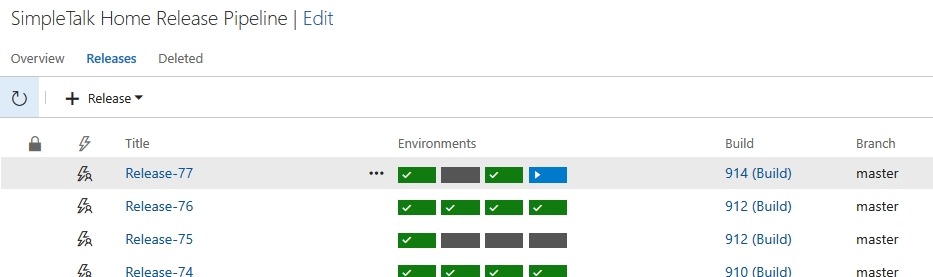
    One thing I’d done was to practice a change, which created a build. I didn’t deploy this forward, so it was essentially sitting in the VCS, but wasn’t in downstream environments. When I looked at my release, I saw this:
    2018-06-12 15_55_38-Window

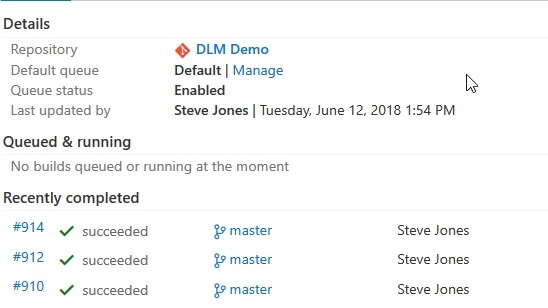
    Note the build number above, 912. This was my previous build. As soon as I clicked to the CI process, I saw that my last build was 914.
    2018-06-12 16_14_09-Window

    I’d been in such a hurry to kick off the release that I clicked too soon. The build completed, but the release page hadn’t gotten an update and picked build 912. Since I hadn’t deployed this, I didn’t get the warning that I was re-deploying a build that had already gotten to the QA database.

    I created a new release after the webinar, and it went. With ultimate confidence in myself, I just sent it to Production from QA.
    2018-06-12 16_17_29-Window

    And it worked:

    2018-06-12 16_17_53-Window

    Apologies for the issues. I’m not sure why Visualstudio.com was so slow here. Apparently the audio worked, so I’m guessing it was their site.

    In any case, I’ll be hosting a webinar doing DevOps in a slightly different way on June 28. Register and join us if you want to see something similar but different.
  • It’s Azure T-SQL Tuesday #103

    tsqltuesdayI’m slightly surprised that there haven’t been more invitations about Azure, with the main development branch of SQL Server being in the Azure cloud, but I’m glad this one came along.

    The invitation is from Björn Peters, and he asks us to write about Azure SQL Database or Managed Instances. We can really write anything that’s a part of the platform, which gives us lots of choices.

    I’ve got two quick items.

    T-SQL Tuesday

    Did you know tsqltuesday.com is hosted on Azure? It’s actually at http://tsqltuesday.azurewebsites.net. When Brent gave me to the domain, and Adam wanted a quick site, I provisioned a WordPress site on Azure in a few minutes. It actually took longer to square away the initial DNS and domain name movement than getting the site up and configured. Templates and known configuration settings help to ensure that you can build a new version of xxx, very quickly.

    The cost was low as well, about $3.60/month and initially $5/month for the hosted MySQL database.

    This changed last year, when the MySQL hosting option was discontinued. I could have upgraded to $15/month, but decided to experiment. Azure has a MySQL as a Service PaaS offering for the same $15/mo, so I moved to that. I was somewhat amazed how easy it was to provision this database on my own and get things running. While the site costs me a little money, it’s a donation to the community, and I’m happy to see so many people participating in the monthly event.

    Quick Labs

    One of the things that I needed to do last year was setup a new cluster and Availability Group for a proof of concept. I have typically done this by getting some VMs ready on my desktop, making connections, etc. However, in this case, I decided to use Azure instead. I was curious about whether this was faster or easier.

    It was.

    Across a few days, as I learned a bit about provisioning new machines and connecting them with networking, I was able to get my set up with 3 machines, a load balancer, storage, etc. I had a working set of Availability Groups, that I could access from anywhere.

    Then I tore it down and started again.

    One of the great things about Azure is that you can use the Azure Resource Manager to provision new services fairly quickly. It’s not as instantaneous as you would like, though it’s not bad. I think the fact that you request actions and then wait until you are notified of something completing in the portal makes the process seem slow.

    In my case, the few days became < 1 hour the second time around.

    Plus, I didn’t use resources on my local machine, where I might have to balance the load with other tasks. I could also shut down my system and reduce costs. With ARM, I could even get rid of the lab and rebuild it in an hour in the future.

    To me, this is the place where the cloud makes lots of sense. If you have a load that is sporadic and can be up or down on demand, then the cloud is helpful. You can remove resources you don’t need, only paying as you go.

    If I were using this every day, I’d probably stick with the local system, but for a periodic use item, it makes sense to fire up the lab when I need it, rather than keeping it alive all the time.

    I look forward to doing more with Azure in the future and learning even more about how to build up the resources I need, when I need them.

  • Machine Learning in the Database

    When SQL Server added the ability to execute R code, the decision seemed to split the customer base into two groups. One group was impressed and thought the idea of executing R code to analyze data in the database was a good idea. They were excited and impressed by the loan classification demo. If you haven’t read about this or seen the demo, it’s very interesting, and it’s something you might take a few minutes to read or watch it.

    The other group of customers felt this was a poor use of CPU cycles for a very expensive SQL Server CPU license. Running a complex analysis, training models, and other functions commonly associated with R scripts aren’t a good use of scarce resources. They would rather have R code execute on a separate server, much like any large messaging workload might be better served by a service such as AWS’ Simple Queue Service rather than Service Broker.

    I tend to be in the first group, as is Dr. Low. He writes that there is a place where Machine Learning Services (MLS), with both R and Python, are a good use of resources. Not in all cases, and certainly not for all work. The difficult parts of training models and doing the hard work of coming up with new ways to perform an analysis is definitely better left to workstations and data scientists. Those actions might not be worth the resources they take.

    Once the models are trained, however, the executable load of submitting parameters to a model and getting a prediction is small. SQL Server allows us to load pre-trained models into the database and just call them as needed. Plus, the R models run in a multi-threaded fashion, unlike the single threaded execution in clients such as R Studio.

    As with any feature of SQL Server, it’s important to test and evaluate the real world impact of new code on production sized workloads. Not only will you want to measure the load of your model execution, but you should also measure any changes in your existing workload with the additional R or Python code load. While I wouldn’t prevent the use of MLS in SQL Server, just like SQL CLR code, I would be careful about introducing without extensive testing, including dark deployments and simulated loads.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.2MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Be Prepared with Baselines

    I visited a doctor recently, and he told me a measurement he’d made. I asked if it was good or bad, and he said he had no idea. The value varied too much from person to person, and without values from the past, he couldn’t really evaluate the significance of it. He will be able to in the future, now that he has a value, but there’s nothing that can be done now. At this point, he has a baseline (of sorts) and can now start to judge how things change over time.

    After that visit, I started thinking about Page Life Expectancy (PLE). PLE is one of those counters that so many DBAs look at early in their career. Often they’ve read guidance that they should worry once this is below 300, which isn’t true. There are calculations for this, but they are based on your system, and really, they’re a rough rule of thumb. Really you need to measure this for your system, so that you know what a the value often is and then worry when it dips.

    To do that you need a baseline. You need to measure various metrics about your system over time so that you understand what’s a normal value. Plenty of experts, like Erin Stellato and Tim Radney have written about baselines, why they’re important, and what you might want to capture. In fact, we have quite a few articles on baselines at SQLServerCentral.

    If that sounds like a lot of work to you, I agree. I’ve built systems in the past that captured metrics on my instances and stored the data. I wrote reports to view data, alerts to let me know when something is breaking (or broken), and maintenance that kept data storage under control. I essentially had to be both the software developer and operations staff for my systems. That works, but I’d try to avoid repeating that effort from now on. As Tim mentions in his piece, there are better ways to do this. There are products, such as SQL Monitor and SQL Sentry, that capture this data for you, that won’t have typos, mistakes, or holes in their operation.  Some will even show you the baseline visually to see if things are withing expected ranges.

    The monitoring software does lots for you, though at a price. It’s tested, and it does all the gathering, storage, basic analysis and alerting in a way that allows you to spend time on actually fixing issues, tuning queries, and providing value for your organization. I think it’s worth the cost, since I know that my time is better spent on solving problems, not writing monitoring software. You may feel the same way or youj may not. You may prefer to write your own system, or you may not have a budget and be forced to build your own. Whichever route you go, make sure you set up a baseline. You’ll appreciate having one the next time your phone rings with a call that the server is slow.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.6MB) podcast or subscribe to the feed at iTunes and Libsyn.