Author: way0utwest

  • An AI Loophole

    I’ve been working through some of the GDPR legislation, trying to find ways to explain this more clearly to customers and ensure that our products make sense in light of this law taking effect. Redgate is focused in this area and not only do we need to ensure we are compliant, but we also want to ensure we are building tools that help ensure you are compliant.

    In article 14, there’s this text: “the controller shall provide the data subject with the following information… the existence of automated decision-making, including … meaningful information about the logic involved.” That sounds a little concerning for those of us that work with data. It’s not always easy, but we can explain how a SUM or AVG function works, even with a complex OVER() clause and lots of joins and criteria.

    What do we do with a model running under SQL Server Machine Learning Services? The output from those scripts and models is often created by the model, without any obvious way to determine how the results are determined. The requirement to explain is enshrined in a law, one that many people are concerned about. With all the ways that ML and AI systems can get gamed and perhaps contain biases based on the data used to train the model, I can certainly see no shortage of people asking for explanations of decisions or conclusions.

    Fortunately Article 14 also has this part: “the provision of such information proves impossible or would involve a disproportionate effort …” That seems to give companies an out if they are using current systems about which little is known about the black box of machine learning. Certainly organizations are still charged with protecting the data subjects rights and freedoms, but this seems allow for the use of technologies that we can’t quite understand.

    I doubt this was the intention of the authors, though I do hope that this doesn’t prevent the use of newer tools and technologies. What I’d like to see take place is more research and understanding into how the various algorithms we want to use for ML and AI technologies work, perhaps with some more detailed analysis of the inner workings of the models.

    GDPR is going to be an interesting regulation that may have dramatic impacts on the world of data. I’m both excited and concerned to see how things move forward from here. Hopefully this results in better and more responsible data handling and doesn’t degenerate into a series of long term legal battles.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.5MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Brush Up on Your ETL Skills

    Many of us that work with data will find requests and demands to import or export data at some point. Plenty of us have regular processes that perform these actions, and we may regularly troubleshoot or enhance these activities. In fact, I know some people have a full time, or nearly full time, position just dealing with ETL operations.

    Working with data in disparate formats and the myriad of inconsistencies even when formats are known is a challenge. Integration Services is a useful tool, but many us find that we need to pre or post process data separate from a simple import or export. Some of us may prefer using T-SQL or other languages, such as R or Python, to process data rather than programming SSIS. It seems that I often find that every client wants a slightly different format or change to their data that a simple query export won’t handle.

    These days, as we add in Machine Learning and other downstream processing activities, it seems that there is more and more of a need to process data beyond imports and exports. After all, it seems that the majority of the time in any ML project is spent preparing and transforming data. In addition, in Article 15 of the GDPR, there is language that notes a data subject has the right to request a copy of the data relating to them when it is being processed by an organization. I don’t know how often someone will want to get data about themselves or their organization, but I’m sure it will happen more than it happens today.

    I think this means I’ll need to brush up on ETL skills, perhaps to ensure I can easily extract out a copy of an individual’s data. In fact, I probably should compile some scripts now to ensure I can let someone know what we information keep at SQLServerCentral that would fall under GDPR. I think it’s just email addresses, but I could be wrong.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.9MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Classifying Data with SSMS 17.5

    I upgraded SSMS to 17.5 recently and found an interesting addition. This version has incorporated the ability to classify data. With the GDPR coming for many of us, this is a welcome addition.

    This is a quick look at this feature.

    Classify a Database

    If I select a database and right click it in SSMS, I get a few new items in the Tasks menu (as shown).

    2018-02-16 13_15_58-SQLQuery1.sql - Atlas.master (sa (51))_ - Microsoft SQL Server Management Studio

    I’ll select “Classify Data”, and I get a new tab opened. I see there are some recommendations and also a list of classifications of data.

    2018-02-16 13_16_28-Data Classification - NBA - Microsoft SQL Server Management Studio

    There’s a getting started link, which takes me to the SQL Server Security Blog. I suspect that’s an incorrect link. I think it should go here: SQL Data Discovery and Classification.

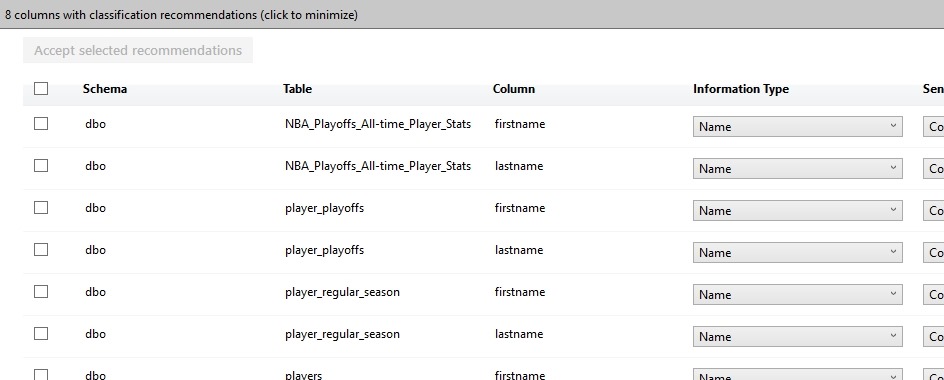
    Below this, I see a list of the recommendations. This has grabbed tables that appear to continue to contain some data that might be sensitive and require classification. One of the tenets of the GDPR  is that you know your data. You aren’t allowed to figure this out later, but rather you must proactively know what data you are collecting and processing.

    2018-02-16 13_17_47-Data Classification - NBA - Microsoft SQL Server Management Studio

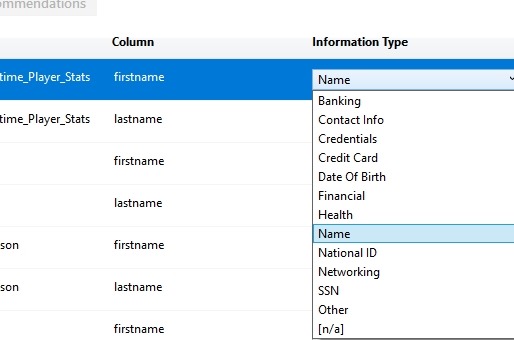
    Here we can see a few drop downs to the right. I’ll scroll and look at these. First is the Information Type. This is listed as a name, but I have other options I can set. The list is the types of that that might be sensitive information about a data subject (a human or entity) that I need to classify.

    2018-02-16 13_19_36-

    Beside this is the sensitivity label. My choices here are shown below. These range from public information, which removes some of my responsibility to highly confidential and applying to the GDPR.

    2018-02-16 13_21_14-Data Classification - NBA - Microsoft SQL Server Management Studio

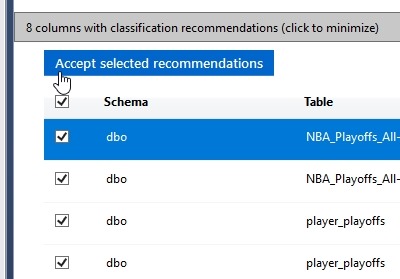
    If I’m happy with these recommendations, I can select them all (or a subset) on the left. I can click the “Accept” button to add them to the classifications I have for this database.

    2018-02-16 13_22_07-Data Classification - NBA - Microsoft SQL Server Management Studio

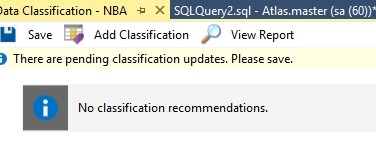
    This doesn’t save them, but adds them to the list. At the top of this tab I can see the need to “Save” my changes.

    2018-02-16 13_22_13-Data Classification - NBA - Microsoft SQL Server Management Studio

    Once I’ve done this, I could add more, or view a report. The report shows me this:

    2018-02-16 13_22_26-Data Classification - 2_16_2018 1_22 PM - PLATO_SQL2016 - Microsoft SQL Server M

    Implementation

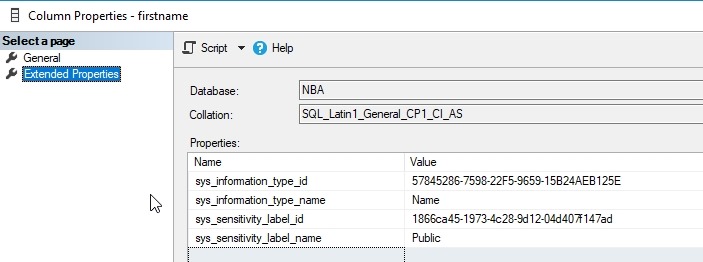
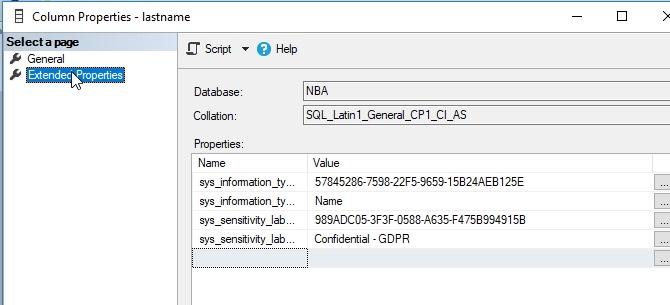
    My guess was that these are implemented as extended properties, which makes sense. That’s how many things could make SQL Server better, and I’m right. If I examine the EP for the firstname column in one table, I see this:

    2018-02-16 13_26_46-Column Properties - firstname

    This was the column I changed to public information. The lastname column in the same table is marked as confidential.

    2018-02-16 13_26_55-Column Properties - lastname

    Helpful?

    Ultimately is this useful? Yes. I can see other products taking advantage of this, such as the new Data Masker from Redgate, which could let you know which columns are sensitive and not masked. I’d also expect that this is useful and important for ETL and other operations to carry this metadata to new columns that might contain transformations or movement of this data.

  • Virtual Data

    Yesterday I republished an editorial from 2014 for the holiday. The topic was production subsets of data, which has been something that many data professionals have struggled with for years. Many of us have built scripts to delete, change, obfuscate, or alter production restores as a way of providing useful, but manageable development database sets. Or maybe it’s just some of us. I’m sure more than a few of us have given up on this task and just restored production databases in entirety to test and development systems.

    I changed over my career to become a fan of additively building a known dataset rather than deleting extra data. I advocate adding rows from production (properly masked/obfuscated) and maintaining this set over time as requirements change. However, this isn’t without it’s own administrative headaches. I think it’s easier, but this does require commitment from everyone to keep going over time. It’s certainly better than each developer adding their own 10 rows of data to a table for testing.

    A year ago, Redgate released SQL Clone, designed to solve some of these issues. Once an image is created, new databases for test and development and be provisioned in seconds. I found this to be an amazing product that really changes how I develop against databases, though it does require me to stop getting caught up trying to undo changes or manage a single database. Instead, I need to ensure I am saving code to version control and then build the habit to drop and rebuild a baseline database.

    As we’ve worked on SQL Clone, I’ve found that there are lots of companies that offer similar ways of virtualizing your data, giving you access to large, production scale systems in seconds. Data masking, obfuscation, and more are features, with some vendors requiring specific hardware. Others, like Red Gate, have software add-ons (Data Masker).  All of these products cost money, which can be an issue for many organizations, but I’m glad that this technology is growing and advancing. With GDPR and other draft legislation, many of us need to take better care of our data and build more secure architectures.

    Containers are another interesting way to virtualiza data, though they don’t solve the scale issues. If you can work with a smaller data set, and maintain that, then containers might provide a fantastic way for you to learn to build, teardown, and rebuild databases in seconds.

    The world of databases hasn’t changed a lot in some ways across my career, but in others, I’m amazed. Data virtualization is one of these areas, and if you haven’t trialed the technology, maybe you should give it a whirl this year.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.6MB) podcast or subscribe to the feed at iTunes and Libsyn.