Author: way0utwest

  • Moving Lookup Data with ReadyRoll

    I’ve been using ReadyRoll for a small project and wanted to move some lookup data. There are some tables where I want to keep data in sync across environments, so if my build and release pipeline can do this, great. ReadyRoll makes this easy, and this is a short post to show how.

    The Current Environment

    I’ve got a table in my dev database that has SQL Server versions. I can see the list here:
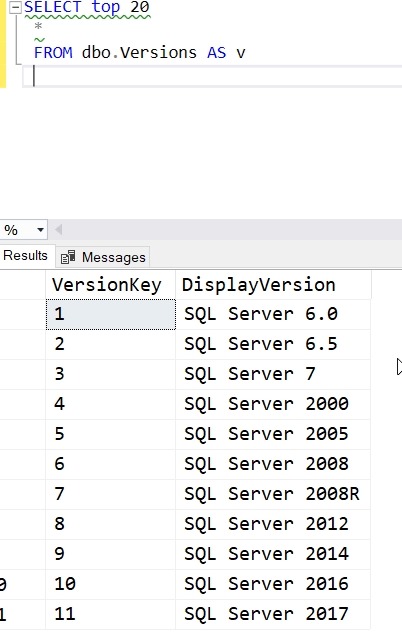
    2018-01-31 12_15_05-SQLQuery6.sql - (LocalDB)_Projectsv13.SSBuilds_1Dev (PLATO_Steve (51))_ - Micros

    In my QA and staging systems, I see this (only one is shown, but it’s the same in both).
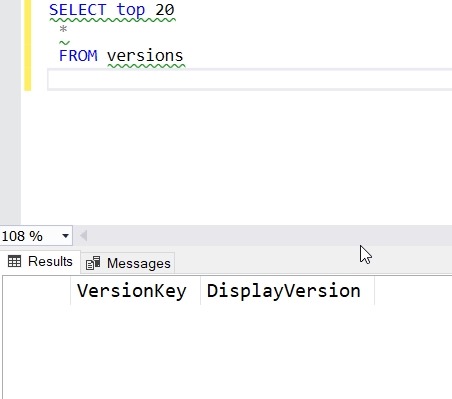
    2018-01-31 12_13_41-SQLQuery5.sql - dkranchstaging.database.windows.net.ssbuildsRRstaging (vstsdeplo

    The goal is to have this data migrate with other changes in a build and release pipeline.

    Adding Data to the Project

    I’ve already built this as a ReadyRoll project and set up a build and release pipeline in VSTS. Now I want to include my data.

    In the ReadyRoll tool window, I have refreshed the project and I see everything in sync. That’s good, and that’s how I want to be starting a small section of development.
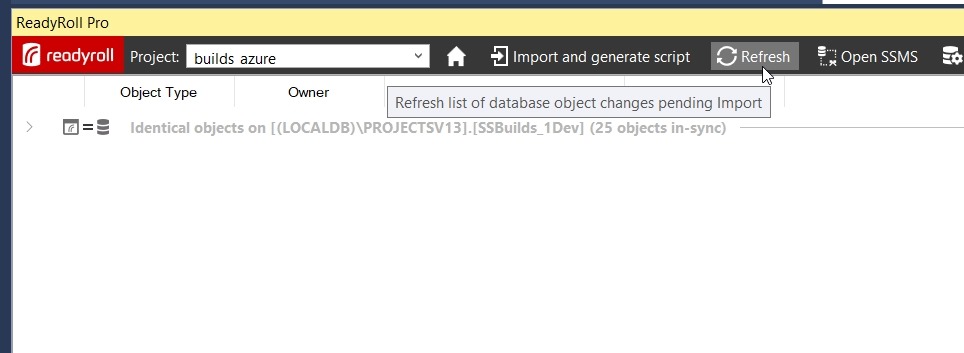
    2018-01-31 12_11_09-builds_azure - Microsoft Visual Studio

    I want to find my table, so I need to expand the “Identical Objects”. When I do that, I see a list of all objects in the database.
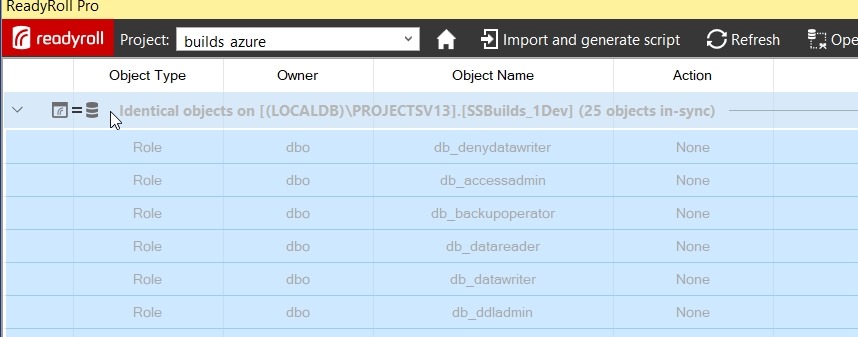
    2018-01-31 12_17_22-builds_azure - Microsoft Visual Studio

    I can scroll down to find my table. When I do, I’ll right click it to get a few options. One of these is “Include Table Data”. We want to pick this one.
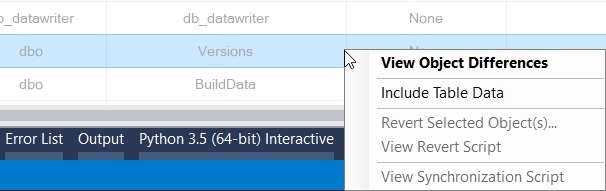
    2018-01-31 12_20_01-

    Once I do that, I get a note to refresh again. This is so RR can determine what table data needs to be added to a migration script.
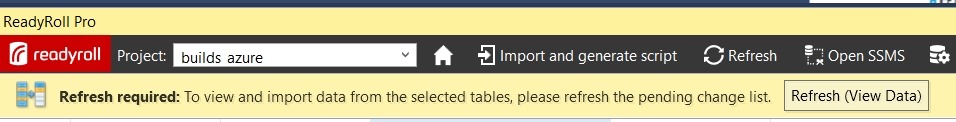
    2018-01-31 12_21_07-builds_azure - Microsoft Visual Studio

    My changes show that I need to get 11 rows of data into a new script.
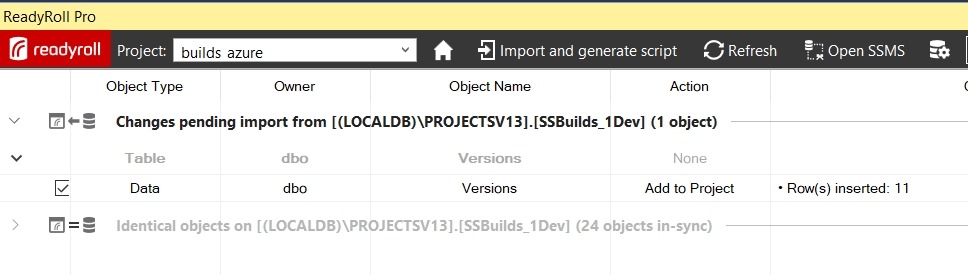
    2018-01-31 12_21_44-builds_azure - Microsoft Visual Studio

    I click Import and generate script, which will build my migration script and add it to the project. In my case, this is script 4.
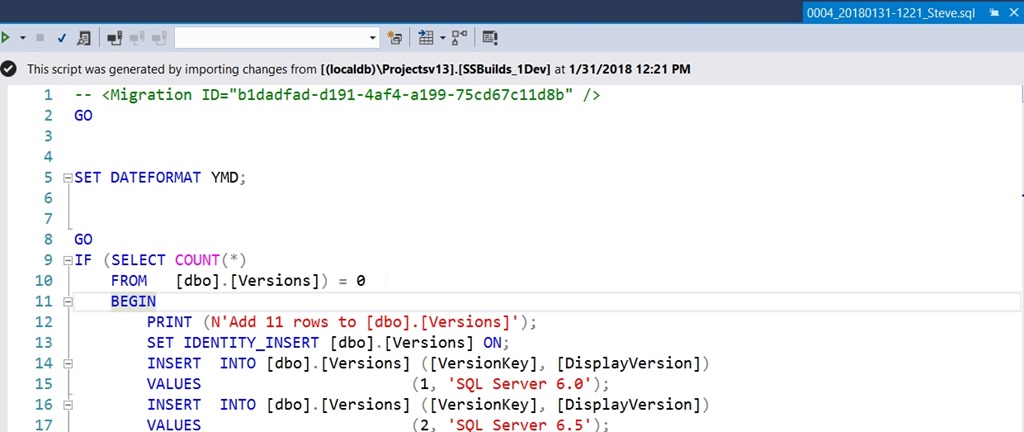
    2018-01-31 12_23_00-builds_azure - Microsoft Visual Studio

    Note that this script has a few things in it, based on a call to SQL Data Compare in the background. First, it sets a dateformat. Next, it does the insert for an empty table, since that is the situation I’m in. Last, this uses the SET IDENTITY_INSERT option.

    If you don’t like these options, change them here. You can alter this script to suit your environment. Remove the IF, let the identities be what they are, make the changes that matter to you.

    The only thing I’ll do is click the script name twice to edit it.
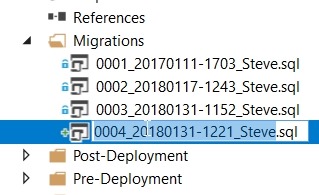
    2018-01-31 12_25_08-builds_azure - Microsoft Visual Studio

    The numeric sequencing is important. The rest, not so much. I’ll choose something simple here.
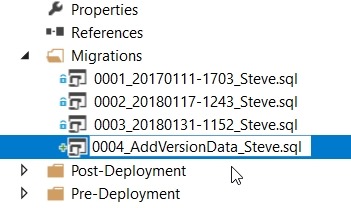
    2018-01-31 12_25_21-builds_azure - Microsoft Visual Studio

    Build the Project

    I can build locally, and I always should to be sure things work. Once I see this and I’ve tested a few things, I’ll let the “system” do more work.
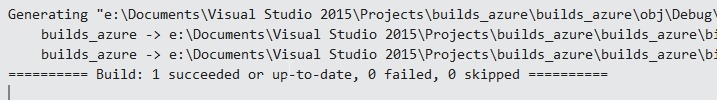
    2018-01-31 12_28_32-builds_azure - Microsoft Visual Studio

    The nice thing about ReadyRoll is that I can include my database project alongside application projects, if I want. For application developers or hybrid developers, I can use a consistent interface for saving changes to version control.

    In Team Explorer, I’ll check changes, add a comment, and then Commit and Push.
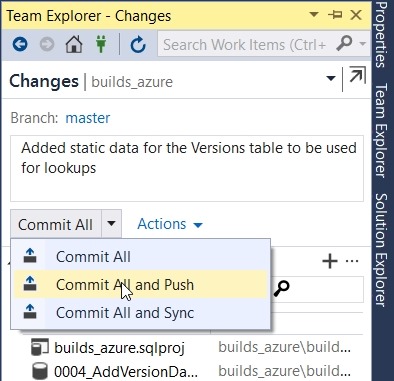
    2018-01-31 12_30_36-builds_azure - Microsoft Visual Studio

    If I go to VSTS, I’ll see the build in progress. I’m using a local build agent and usually within 15 seconds, my build will start. Sometimes it’s really fast.
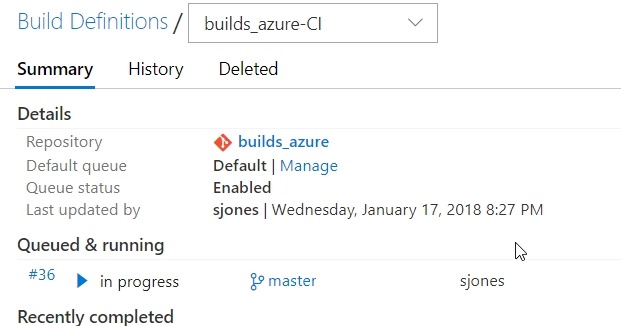
    2018-01-31 12_31_04-builds_azure-CI summary

    If I click the build number, I can see I’ve barely caught this before it finished.
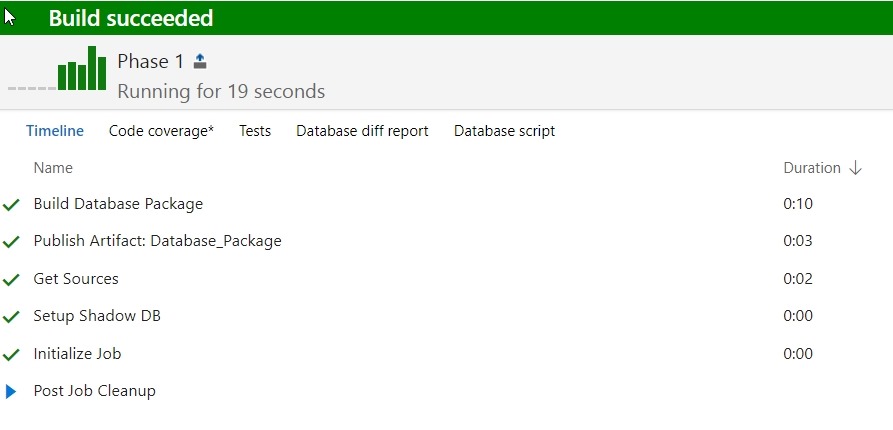
    2018-01-31 12_31_19-Build 36

    The build completes, so now I need to check releases. I have a CD trigger that will deploy to a local QA instance when the build succeeds. If I go look at the release, I’ll see that’s occurred.
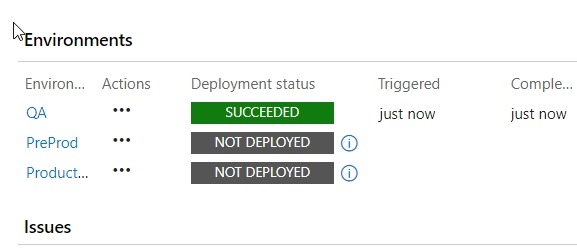
    2018-01-31 12_35_49-Release-14 - Visual Studio Team Services

    This worked, so let’s check the QA instance. As you can see, my data was deployed.
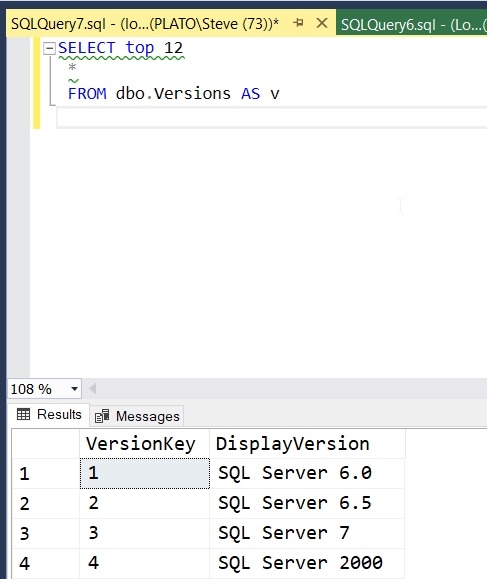
    2018-01-31 12_36_43-SQLQuery7.sql - (local)_SQL2016.ssbuilds_rr_sjones_2_integration (PLATO_Steve (7

    If you were watching closely, you see I have a small data issue. I need to correct that, but that’s for another post.

    ReadyRoll is a part of the SQL Toolbelt, and if you’re a customer, I’d urge you to start a PoC and see what you think of the tool. ReadyRoll Core, with limited features, is included with Visual Studio Enterprise, and if you’re a customer of Microsoft, you can try that. We also have 14 day trials if you’d like to do this on your own.

  • The Learning Choice

    I advocate learning constantly for those of us in technology. This might be especially important for data professionals as we are at the nexus of so muc activity these days. Data is important, our systems are under scrutiny for security, there is an every growing set of applications that want to connect, and we often struggle to keep up in a fast-paced, DevOps world. It feels like my plate is overflowing with the need to understand PowerShell, JSON, the cloud, Hadoop and its myriad of related technologies on the Microsoft Stack, machine learning, data science, statistics, and when I have time, make sure I’m up to date with SQL.

    Recently I’ve run across a few pieces that ask the question about where to spend time. There’s a blog on R v Python (I’ve seen quite a few of these) and a thread on deciding if ML skills are something a database developer should learn. These are just a few of the ones I’ve seen in the last month, as I guess lots of people are thinking and writing about New Year resolutions and goals.

    We have a limited amount of time for learning each day, week, month, or year. We might be able to increase that for a short time, perhaps months, but all of us need some balance in life. Given that there’s a limited amount of time, and that we need some focus and practice over time to absorb skills, where do you spend your effort in learning?

    Jeff Moden is an advocate of you sharpening your T-SQL skills with deep learning, as he sees this as one of the main reasons that applications perform poorly (and people post in our forums). Others lean towards adding new skills, perhaps adding SSIS proficiency or transitioning your analysis skills to Extended Events. Still others might seek to become more generally rounded by spending time on C# or Python.

    There are also other views, such as focusing on the skills you need in your current position. If you’re not happy, maybe you want to devote learning effort to get a job in an area where you’re passionate. Or maybe you just want to make more money, and are willing to spend time in those technologies that are paying more.

    The choice is up to you, and I can’t give you the answer that suits your path. You must find a balance between work and the rest of life, and make the choices that best fits you. I don’t want to imply this is easy. Thinking about the things that really matter to you and affect how you approach each day is a difficult exercise. My advice is that you go in one of two ways. If your career is something that you feel passionate about, focus your learning in a way that will help you find a job that brings you purpose. If you just need a job to pay the bills, learn things that increase your earnings, but ensure that you have family, faith, hobbies, or some other endeavor outside of work that brings purpose and fulfillment to you.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 5.0MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Getting Your SET Options

    Have you ever used @@options? I haven’t typically needed this, but there are times that you might wonder what options are set for a session. You can check in SSMS, look for defaults, etc., but there’s an easy way.

    SELECT @@OPTIONS

    This uses the @@options function, which contains a bitmap of your session settings. There are defaults with the sp_configure user options, but these can be overridden.

    If you want to get the options, which are also stored as bitmaps in various places, you can code them with this BOL article.

    Or use a script like this:

    DECLARE @i INT;
    SELECT @i = @@OPTIONS;
    SELECT ConstraintChecking = CASE WHEN (@i & 1 = 1 ) THEN 'ON' ELSE 'OFF' end,
            ImplicitTransactions = CASE WHEN (@i & 2 = 2 ) THEN 'ON' ELSE 'OFF' end,
            CursorCloseonCommit = CASE WHEN (@i & 4 = 2 ) THEN 'ON' ELSE 'OFF' end,
            AnsiWarnings = CASE WHEN (@i & 8 = 8 ) THEN 'ON' ELSE 'OFF' end,
            AnsiPadding = CASE WHEN (@i & 16 = 16 ) THEN 'ON' ELSE 'OFF' end,
            AnsiNulls = CASE WHEN (@i & 32 = 32 ) THEN 'ON' ELSE 'OFF' end,
            ArithAbortSetting = CASE WHEN (@i & 64 = 64 ) THEN 'ON' ELSE 'OFF' end,
            ArithIgnoreSetting = CASE WHEN (@i & 128 = 128 ) THEN 'ON' ELSE 'OFF' end,
            QuotedIdentifer = CASE WHEN (@i & 256 = 256 ) THEN 'ON' ELSE 'OFF' end,
            NoCount = CASE WHEN (@i & 512 = 512 ) THEN 'ON' ELSE 'OFF' end,
            AnsiNullDefaultOn = CASE WHEN (@i & 1024 = 1024 ) THEN 'ON' ELSE 'OFF' end,
            AnsiNullDefaultOff = CASE WHEN (@i & 2048 = 2048 ) THEN 'ON' ELSE 'OFF' end,
            ConcatNullYieldsNull = CASE WHEN (@i & 4096 = 4096 ) THEN 'ON' ELSE 'OFF' end,
            NumericRoundAbort = CASE WHEN (@i & 8192 = 8192 ) THEN 'ON' ELSE 'OFF' end,
            XactAbort = CASE WHEN (@i & 16384 = 16384 ) THEN 'ON' ELSE 'OFF' END

    For the row-based people, how about this:

    DECLARE @i INT;
    SELECT @i = @@OPTIONS;
    SELECT 'ConstraintChecking', CASE WHEN (@i & 1 = 1 ) THEN 'ON' ELSE 'OFF' END
    UNION 
    SELECT  'ImplicitTransactions', CASE WHEN (@i & 2 = 2 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'CursorCloseonCommit', CASE WHEN (@i & 4 = 4 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'AnsiWarnings', CASE WHEN (@i & 8 = 8 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'AnsiPadding', CASE WHEN (@i & 16 = 16 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'AnsiNulls', CASE WHEN (@i & 32 = 32 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'ArithAbortSetting', CASE WHEN (@i & 64 = 64 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'ArithIgnoreSetting', CASE WHEN (@i & 128 = 128 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'QuotedIdentifer', CASE WHEN (@i & 256 = 256 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'NoCount', CASE WHEN (@i & 512 = 512 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'AnsiNullDefaultOn', CASE WHEN (@i & 1024 = 1024 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'AnsiNullDefaultOff', CASE WHEN (@i & 2048 = 2048 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'ConcatNullYieldsNull', CASE WHEN (@i & 4096 = 4096 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'NumericRoundAbort', CASE WHEN (@i & 8192 = 8192 ) THEN 'ON' ELSE 'OFF' end
    UNION 
    SELECT  'XactAbort', CASE WHEN (@i & 16384 = 16384 ) THEN 'ON' ELSE 'OFF' END

    UPDATE: From the comments, an UNPIVOT might be easier to read for some of you.

    DECLARE @i INT;
    SELECT @i = @@OPTIONS;
    SELECT [Option], [Value]
    FROM(
    SELECT ConstraintChecking = CASE WHEN (@i & 1 = 1 ) THEN ‘ON’ ELSE ‘OFF’ end,
    ImplicitTransactions = CASE WHEN (@i & 2 = 2 ) THEN ‘ON’ ELSE ‘OFF’ end,
    CursorCloseonCommit = CASE WHEN (@i & 4 = 2 ) THEN ‘ON’ ELSE ‘OFF’ end,
    AnsiWarnings = CASE WHEN (@i & 8 = 8 ) THEN ‘ON’ ELSE ‘OFF’ end,
    AnsiPadding = CASE WHEN (@i & 16 = 16 ) THEN ‘ON’ ELSE ‘OFF’ end,
    AnsiNulls = CASE WHEN (@i & 32 = 32 ) THEN ‘ON’ ELSE ‘OFF’ end,
    ArithAbortSetting = CASE WHEN (@i & 64 = 64 ) THEN ‘ON’ ELSE ‘OFF’ end,
    ArithIgnoreSetting = CASE WHEN (@i & 128 = 128 ) THEN ‘ON’ ELSE ‘OFF’ end,
    QuotedIdentifer = CASE WHEN (@i & 256 = 256 ) THEN ‘ON’ ELSE ‘OFF’ end,
    NoCount = CASE WHEN (@i & 512 = 512 ) THEN ‘ON’ ELSE ‘OFF’ end,
    AnsiNullDefaultOn = CASE WHEN (@i & 1024 = 1024 ) THEN ‘ON’ ELSE ‘OFF’ end,
    AnsiNullDefaultOff = CASE WHEN (@i & 2048 = 2048 ) THEN ‘ON’ ELSE ‘OFF’ end,
    ConcatNullYieldsNull = CASE WHEN (@i & 4096 = 4096 ) THEN ‘ON’ ELSE ‘OFF’ end,
    NumericRoundAbort = CASE WHEN (@i & 8192 = 8192 ) THEN ‘ON’ ELSE ‘OFF’ end,
    XactAbort = CASE WHEN (@i & 16384 = 16384 ) THEN ‘ON’ ELSE ‘OFF’ END) AS options
    UNPIVOT (
    [Value] FOR [OPTION] IN ([ConstraintChecking],[ImplicitTransactions],[CursorCloseonCommit],[AnsiWarnings],[AnsiPadding],[AnsiNulls],[ArithAbortSetting],[ArithIgnoreSetting],[QuotedIdentifer],[NoCount],[AnsiNullDefaultOn],[AnsiNullDefaultOff],[ConcatNullYieldsNull],[NumericRoundAbort],[XactAbort])
    ) AS T1
    ORDER BY [Option]
    GO
  • Influence the Program

    When I first started going to the PASS Summit, I was enthralled with the speakers, no matter what the topic. Meeting Kalen Delaney at the first Summit was a milestone in my career. In those early years, there weren’t many speakers, and they submitted the talks they were interested in giving. The program committee made their decisions, and many of us went to watch whatever was available. The surface area of SQL Server was much smaller, so we could probably guess many of the topics, and that worked out well.

    As SQL Server has grown, some of us have questioned the makeup of the sessions over time. At one point it seemed we were very light on BI, almost as if the conference hadn’t kept pace with the changes in the platform. It seemed that the next conference was based on ratings and attendance from the previous Summit, but that’s a slowly changing way to pick talks.

    Things changed, and for a number of years PASS has been trying to understand what content you’d like to see. There have been surveys and polls to understand not only what worked last year, but what changes should happen this year. Last year’s tracks were set not by technology, but by the Analyze/Build/Design/etc. monikers. I’m not sure I loved that, but it was a worthy experiment.

    There’s a survey open from PASS from now until Feb 14, trying to understand what you’d like to see. Once again, they are asking what you’d like to see. I’d encourage all of you to fill it out, as you can truly influence the balance of sessions that will be presented. Do you want more ML/AI/bots, and other advanced topics? Do you need more beginning content for your junior DBAs? Is the core engine still important for you, or are you looking for SSIS, SSRS, or other content. Power BI on your radar?

    Speakers often have preferences, and I see no shortage of conferences that just pick talks from what they get. This can make a disjointed event at times. I like the idea of having submissions in areas that I might not consider as an organizer, but I also think that inviting speakers to talk on specific topics is good. I’m glad PASS does a mix of these things, inviting some speakers, asking for topics, and also taking community submissions. Many of us that present are happy to slightly tailor our talks if we know that’s what the audience wants.

    So take the survey, with a chance to win a Summit admission. Tell the committee if DevOps and testing are important (they are), or if you want to see more SSAS content (are there that many of you using this?). Even if you aren’t going, it’s useful for us as a community to learn what’s of interest to everyone. I’d also request that you ask PASS to release the data, which will help SQL Saturdays and other events better plan their schedules.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 5.1MB) podcast or subscribe to the feed at iTunes and Libsyn.