Author: way0utwest

  • Finding the Titles in R

    PASS has released the videos to members from this past Summit. I say TJay Belt today ask about relating a video name to a session. I have the USB drive, so I looked on there. Here are the videos:
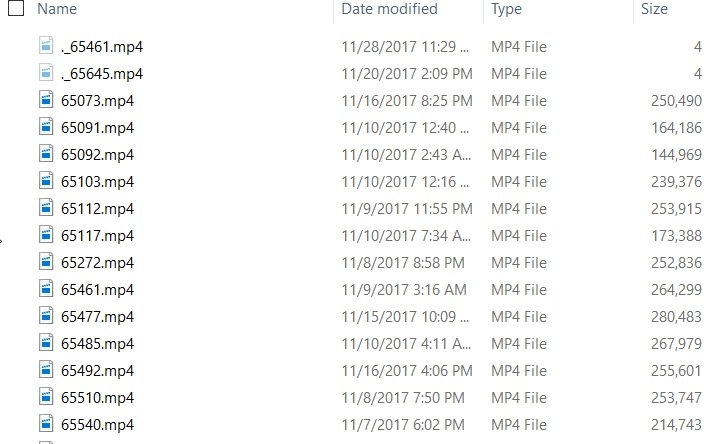
    2018-01-10 13_25_47-Video

    Not terribly helpful. If you run the HTML file from the stick, you see this:

    2018-01-10 13_26_23-PASS Summit 2017

    If I hover over a title, I see the link as a specific video file. For example, the first one is 65545.mp4. With that, I looked around and found a javascript file with information in it.

    The structure was like this:

    //SID
    Col0[0] = "65073";
    Col0[1] = "65091";
    
    …
    
    //Speaker Name
    Col2[0] = "Steve Stedman";
    Col2[1] = "Kellyn Pot'Vin-Gorman";
    
    …
    
    //Session Name
    Col4[0] = "Your Backup and Recovery Strategy";
    Col4[1] = "DevOps Tool Combinations for Winning Agility";

    All the data is in one file, but the index in each array matches. So Col0[0] is the SID for video 65073, which has Col2[0] as the speaker and col4[0] as the title.

    Now I want to get these in some sort of order. First, let me copy this data into separate files. That will make importing easier. I’ll copy the SID array into one file, the speaker array into a second file and the title array into a third.

    This gives me data like the list above, but I need to clean that. This is easiest in Sublime, with a few replacements. I did

    • “COL[“ –> “”
    • “] = “ –> “,”
    • “;” –> “”

    This gives me a clean file that looks like this:
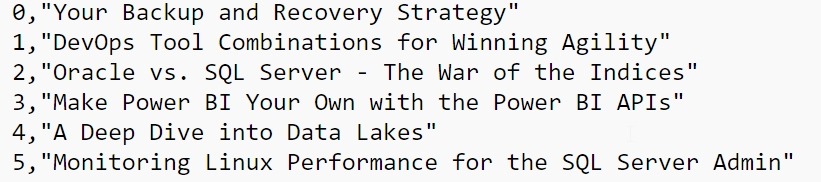
    2018-01-10 13_29_18-e__Documents_R_titles.txt - Sublime Text

    Working in R

    I almost started to move this into T-SQL and a table, but since I’ve been playing with R, I decided to see what I could do there. First, I know I need to load data, so I the first file into a data frame.

    session.index = read.csv("e:\\Documents\\R\\videosid.txt", sep=",")

    The column names aren’t great, so we’ll fix those:

     colnames(session.index) <- c("Index", "SessionSID")

    Now
    let’s get the other data.

    session.speaker = read.csv("e:\\Documents\\R\\passspeaker.txt", sep=",")
    > session.title = read.csv("e:\\Documents\\R\\titles.txt", sep=",") 
    > colnames(session.speaker) <- c("Index", "Speaker")
    > colnames(session.title) <- c("Index", "Title")
    

    I have three data frames. I want to combine them. Let’s do that. I’ll use the merge() function to do this. Since I’ve got common column names, I’ll use those.

    > pass.videos <- merge(session.index, session.title, by="Index")
    
    > pass.videos <- merge(pass.videos, session.speaker, by="Index")

    This gives me a data frame with the index, title, and speaker. Now I’ve got the data merged, let’s produce a file..

     write.table(pass.videos, file="e:\\Documents\\R\\passvideos.txt",sep=",")

    With that done, I can see I have a list of video numbers, titles, and speakers.

    "Index","SessionSID","Session","Speaker"
     "1",1,65091,"DevOps Tool Combinations for Winning Agility","Kellyn Pot'Vin-Gorman"
     "2",2,65092,"Oracle vs. SQL Server - The War of the Indices","Kellyn Pot'Vin-Gorman"
     "3",3,65112,"Make Power BI Your Own with the Power BI APIs","Steve Wake"

    I did something in R. Smile

  • Customize Software or Process

    Many of us work with software and often wish that we something was designed differently. I’m sure many of us feel the same way about our database schemas, which is usually even harder to change. In any case, we often want to mold software to fit our thought process. We’re often asked to alter software to meet the expectations of our customers as well, trying to alter visuals or workflows to match some method of working that our customer desires.

    We often try to do this with COTS (Commercial off the shelf) software, notably ERP systems. SAP and Oracle applications, and similar software packages, have made many consultants rich and required millions (maybe billions) of dollars of investment by companies that look to ensure their logos, their workflow, the specific process is implemented in software. Even many of us that purchase some infrastructure software, or even get open source applications, may spend lots of resources on getting the software to fit our organization.

    The thought that most people have had is that it’s cheaper to make the software fit the system, or the people, than vice versa. However, is that the best way to proceed? Do we want to customize software to work in a way different from the way in which is was designed? Or should we learn to alter some of our processes to better fit with how the tools work? Do we think that we really have some special secret in our process that makes us more efficient? Or are we resistant to change?

    For some software, like SAP, the system is designed to morph and fit an organization. Certainly when there are hundreds, or thousands of users, it might be worth the cost of customizing the software to fit the users. However when we have more specific software, such as that used to monitor infrastructure or deploy software or track features, with dozens of users, do we want to spend a lot of time changing the way things work? I sometimes wonder if we should instead focus on getting our people to learn a new way of working that flows with the software. After all, upgrades, patches, and other minor changes are less disruptive.

    I don’t think there’s just one answer here, and certainly there are valid reasons to spend time and money on changing a system. I just think it’s worth some thought to be sure that changing software is a better decision that adapting our process to work with the application.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.9MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Reading GDPR

    In case you’re interested, the GDPR law is actually not bad to read. You might be affected by this, so go through the regulations. I’m doing that this week.

    You can also see a nice article from David Poole at SQLServerCentral.

    I do think GDPR will affect many of us, but to what extent, I’m not sure. Comments on what you think welcome.

  • tsqlt Tests for Advent of Code 2017 Day 2

    This is day 2 of the Advent of Code 2017. If you want to read about the puzzles, start with Day 1. As I worked through the puzzles, I decided that I should be testing using their test sets and solving the issues that way. This lets me use the sample data, but also add in my own sets to cover strange situations.

    Here are the tests that I used for each part of day 2.

    Part I

    This wasn’t a tough puzzle, and the test is fairly simple. I had a function that solves the puzzle with the help of input. My test just sets up the sample input in the table, tab delimited, and then calls the function to calculate the total.

    EXEC tsqlt.NewTestClass @ClassName = N'tDay2'
    go
    CREATE OR ALTER PROCEDURE tDay2.[test day2 sample input]
    AS
    BEGIN
         ---------------
         -- Assemble
         ---------------
         DECLARE
             @expected INT  18,
             @actual   int;
         
         EXEC tsqlt.faketable @TableName = 'Day2', @SchemaName = 'dbo';
         INSERT dbo.Day2 (DataRow)
          VALUES ('5    1    9    5')
               , ('7    5    3')
               , ('2    4    6    8')
    
        ---------------
         -- Act
         ---------------
         SELECT  @actual = SUM(b.diff)
          FROM day2 a
          CROSS APPLY dbo.AdventChecksum (a.DataRow) b
    
        ---------------
         -- Assert    
         ---------------
         EXEC tSQLt.AssertEquals
             @Expected = @expected,
             @Actual = @actual,
             @Message = N'An incorrect calculation occurred.';
    END
    GO
    EXEC tsqlt.run 'tDay2.[test day2 sample input]';

    Part II

    The test here just calls a different function and has different input.

    CREATE OR ALTER PROCEDURE tDay2.[test day2 b sample input]
    AS
    BEGIN
         ---------------
         -- Assemble
         ---------------
         DECLARE
             @expected INT = 9,
             @actual   int;
         
         EXEC tsqlt.faketable @TableName = 'Day2', @SchemaName = 'dbo';
         INSERT dbo.Day2 (DataRow)
          VALUES ('5    9    2    8')
               , ('9    4    7    3')
               , ('3    8    6    5')
    
        ---------------
         -- Act
         ---------------
         SELECT  @actual = SUM(b.divmatch)
          FROM day2 a
          CROSS APPLY dbo.AdventChecksum3 (a.DataRow) b
    
        ---------------
         -- Assert    
         ---------------
         EXEC tSQLt.AssertEquals
             @Expected = @expected,
             @Actual = @actual,
             @Message = N'An incorrect calculation occurred.';
    END
    GO
    EXEC tsqlt.run 'tDay2.[test day2 b sample input]';
    
    GO