Category: Blog

  • Advice I Like: Celebrate Success

    “On the way to a grand goal, celebrate the smallest victories as if each one were the final goal. That way, no matter where it ends, you are victorious.” – from Excellent Advice for Living

    I believe in celebrating small things. I am a big “smell the roses” and “celebrate your success” even if the bigger part of the success feels like a failure. If I deliver a good demo in a talk, or one of my players makes a good hit/pass/etc., let’s celebrate that. If the rest of the talk wasn’t smooth and people are confused, or we kept hitting the ball in the net, that’s a bit of a failure and something to work on.

    There’s always a bright side and a dim side. One is likely larger, but both are there.

    I think if we look at something in black and white terms, and reduce it to success or failure, then you create a psychology that you win or something wasn’t worth doing. The sports teams, the musicians, the friends I have, my kids, we aren’t defined by whether we win every time. We can’t be the best all the time.

    Even the best of the best isn’t the best most of the time. Tom Brady (7 rings) and Michael Jordan (6 rings) might be considered the best at what they did. However, they played more years (Brady 23, Jordan 15). Were they failures those other years?

    The Beatles had 19 #1 albums, the most of all time. However, they released more. They had lots of #1 songs, but plenty that didn’t get to #1. Were those not worth doing?

    Celebrate your success. You might write a great query, but ultimately there are plenty others that don’t perform well or some might even return the wrong results. Hopefully you’ll fix and improve those, but celebrate the things that go well.

    Work on those that don’t and turn them into victories later.


    I’ve been posting New Words on Fridays from a book I was reading, however, a friend thought they were a little depressing. They should be as they are obscure sorrows. I like them because they make me think.

    To counter-balance those, I’m adding in thoughts on advice, mostly from Kevin Kelley’s book. You can read all these posts under the advice tag.

  • Upgrading SQL Server Containers on the Laptop

    I don’t have SQL Server installed on my laptop. In an effort to keep things clean and smooth in case I need to rebuild things, I’ve gone with containers. I can easily copy a folder with all my docker compose files and data to another machine and be up and running.

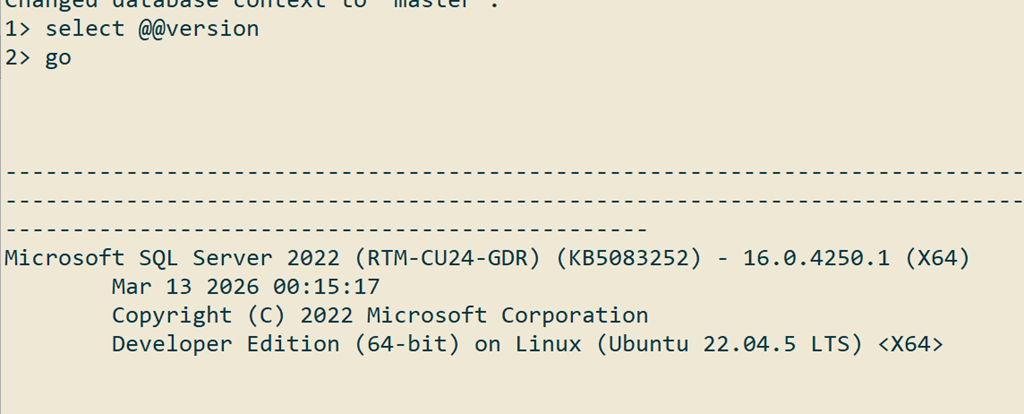
    One other benefit is upgrades. This post looks at the process of upgrading/patching SQL Server on my laptop.

    Getting the Latest Version

    A normal process for me in the past (and on my desktop) is to download a patch, run the installer, and then have SQL Server upgraded. Sometimes there’s a reboot involved as well. With a container, things are a little different. Here is the process:

    • Edit the docker-compose.yml
    • Restart the container

    That’s it.

    Once the image downloads and the container restarts, I have a new version. If I want to go back and test the previous CU/patch, I change my docker-compose file back. Most of the time, the database version hasn’t changed with a CU or GDR, so I can upgrade and downgrade easily.

    Here’s how this works in practice.

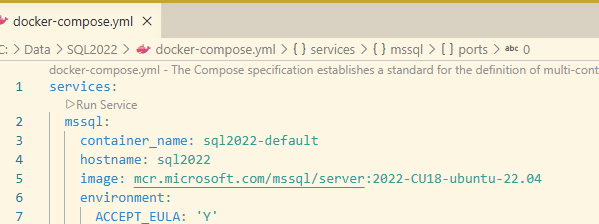
    There were a number of SQL Server patches released recently, including a few for SQL Server 2022. When I looked at my docker-compose file, I saw this:

    image

    The latest version of SQL 2022 is CU24+the Apr 2026 GDR (I’ve been remiss here in patching this machine). If I want to patch this, I update line 5. I know that there is a page on the MS Artifact Repository that lists the tags for each CU. It’s an easy Google search away.

    I change from this:

    image: mcr.microsoft.com/mssql/server:2022-CU18-ubuntu-22.04

    to this:

    image: mcr.microsoft.com/mssql/server:2022-CU24-GDR1-ubuntu-22.04

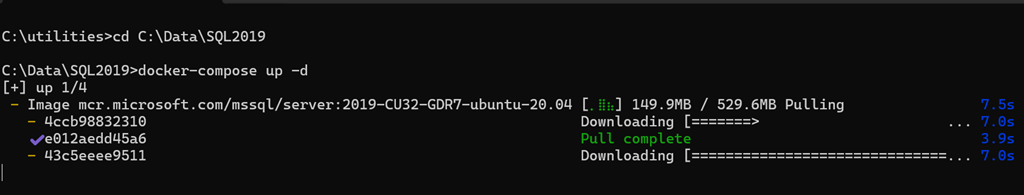
    Now, when I restart my container, I’ll see the new image downloading. Since images are built in layers, this isn’t the complete SQL Server image, but rather the changes from other images, so the download size and time are shorter.

    2026-04_line0001

    As soon as this finishes, the container starts and SQL Server is patched.

    2026-04_line0002

    Now I need to check the other SQL compose files I have for 2019 and 2025 and update those version.

    Video Walkthrough

    Below is a video showing me doing this process.


  • Questions and Answers from Running a Local LLM

    I had a few random questions from my Running a Local LLM on Your Laptop session at the Houston AI-lytics 2026 event last week, so this post looks at a few of those questions and my answers.

    Note: This stuff is changing rapidly, and there aren’t a lot of factual answers. A lot of what you should look for is guidance and rational reasons for leaning in some direction.

    Questions below:

    • Do we need an NPU? (Or what do I think of NPUs)
    • How do we audit or Test an AI LLM and know what is happening?
    • In which situations would you run a local model?
    • Which Model is Best?

    Do we need an NPU? (Or what do I think of NPUs)

    You don’t need an NPU to run a local LLM model, but they help with efficiency. An NPU is a Neural Processing Unit, which is a type of CPU that is designed to work with AI-type applications and process instructions more efficiently. This could be training a model or running LLM workloads.

    I think an NPU is a great idea for efficiency. We already know AI applications use a lot of compute and power. Just look at all the concerns over power/water and investments being made in new data centers for AI. Being more efficient helps.

    Just like a GPU helps with graphics and makes your laptop more efficient, an NPU will help, but it’s not required.

    How do we audit or Test an AI LLM and know what is happening?

    First, LLMs aren’t deterministic, so they might not return the same thing all the time. It’s hard to test a non-deterministic thing because we look to assert if a is passed in, b is returned. If I pass in a and sometimes get b, sometimes c, and rarely f, this is hard to test.

    I have no idea how to test a model for behavior in this case.You get useful results from experiments, and more often they are useful than un-useful to continue using it. If that happens, faster, then you have a better model. If it’s slower/more expensive/less useful, it’s a worse model.

    Auditing is looking at what happened, which means reaching into the processing of these GPT-type tools. There are some tools to help (AuditLLM), but I can’t speak to whether these are a) worth the effort, b) effective, or c) junk. I’m still learning here, too.

    In which situations would you run a local model?

    This is a hard one because there are a few situations in which I’d seriously consider a local model (including Amazon Bedrock/Azure AI/Google Vertex).

    First, when I’m worried about costs and I want to control them. While the vendors give you some limits and throttles, it can be expensive. In many cases, if I want to set controllable spend, a known spend, I might consider a local model in some service because I can allocate out capacity and know what is available, what it will cost, and who will be using it. Perhaps the cloud vendors will give us more controls and ensure we aren’t on “shared” systems, but any efficient use of hardware to do this will be for their benefit, not mine.

    Second, when I’m really concerned about data security. While most companies might promise they won’t use your data and will delete sessions, they might not, and they might make mistakes. And if they do, would they accidentally use my data, or send it in response to some sort of legal subpoena accidentally? If I’m outside the US or really worried, I’d run local models.

    Third, if I want to ensure that I have complete control over the training of the model or the prompts, I might use a local model where I know there aren’t any system prompts being injected into my context.

    Which Model is Best?

    Yes.

    There’s no good answer here. If you look at the list of models on Hugging Face, for example, there are lots and lots of models. None of us has time to test many of them, or even a small fraction. I think you have to depend on the community here to help you decide that any of these models are better for your situation.

    Think about what you want a model to do, what things are important to your problem space, and then look for a model that people think works well and does the type of things you want to do. Similar to how you interview a person for certain types of work, think about that for a model.

    The nice thing outside of the large LLMs is that you can use smaller models to fill in certain situations if you find you want to provide that capability a lot to your organization. I would see interpretation and linting of best practices in code, for example, using a smaller model that uses less compute, but it trained, or you fine-tune it for your particular situation (and save money).
  • Houston AI-Lytics 2026–Powerpoint Slides

    Thanks to everyone for attending my session on running a Local LLM.

    If you have any questions, please feel free to reach out with them. The slides with links embedded is below:

    Slides: Running a Local LLM.PPTX

    I’ll blog next week on a few of the questions people asked, so if you have anything you want answered, please reach out.