Category: Blog

  • SQL Saturday #390 – Philadelphia Recap

    I was at SQL Saturday #390 in Philadelphia last week and it was an exciting, but short time. The event was at the end of a  five day trip for me, Seattle first and then Philadelphia, so I was tired by Saturday morning. However I enjoyed it, met lots of people, and learned a few interesting things.

    Unit Testing with SQL Server and tSQLt

    Friday I taught a pre-con event with Sebastian Meine on unit testing your T-SQL code with tSQLt. We had 9 people signed up, which was encouraging. Not a raging success, but certainly better than the 2 people that some friends had predicted. Everyone was interested in unit testing and producing better code.

    The day went well, and we ended a touch early. There were some good comments and suggestions from people on unit testing techniques, including a solution to one of our exercises that I hadn’t expected. I learned a few places need the demos to be expanded a bit, but overall it felt like a good start to teaching unit testing. I’m looking forward to trying this at a few other events in the future.
    standing in front of the class

    Better Development at SQL Saturday

    I was really only able to attend a few sessions (in addition to the one I taught) at SQL Saturday #390. However I was pleased to see that after my CI session, there was one on Continuous Delivery, and then one on Git for DBAs. Both of these topics are important, and well attended, which makes me think that more people are starting to lean towards building more engineered database development processes.

    My CI session went well. I didn’t get to show the failing CI process based on a test and more data, but I did get lots of good questions that I need to answer in the next few weeks. A few of them (for me to remember).

    • How do I get started with a small development team?
    • How do I start adding tests in an existing software project?
    • Can you demo a column rename (or table rename)?
    • Show static data flowing through the process

    It’s good to get questions, and I hope I answered them all. If I didn’t, or you need clarification, let me know.

    Once I finished, I wandered over to see Mark Wojciechowicz talk about Continuous Delivery. Mark is a consultant that’s trying to keep a CD process working at a client’s site. He’s been working at it for awhile and we talked about it Friday (he was in my class) and Saturday. It sounds like he has some good things going, and using a home grown process that works well.

    He showed some of the reasons why CD matters, especially for his client. They make lots of changes, and use a smooth process to push through bug fixes as well when there are issues with something in production. I hope he gets his deck up soon because he had some good quotes and notes in the PPT.

    I especially like his thoughts that if something hurts in software, you should do it more. That comes from Thoughworks and some of the progressive companies that are rapidly building high quality software and don’t let the problems of deployment slow them down. They tackle those issues just like others, and you should, too.

    From there I saw Justin Dearing talk about Git and DBAs. He’s a developer and tends to like the command line, but he showed how we can use Git for a VCS in the command line, but also from SSDT. That’s an interesting approach, and while I liked his message, I think some of the people there using a CVCS, like TFS, didn’t understand why Git matters. I need to write more on this as well.

    Justin had a minor issue with branching, not because he doesn’t do it well or understand it, but because he’s moving fast and talking. That’s what I am, in general, against branching. The real world moves fast, it’s easy to get caught up with some other thoughts and get lost with branching. I need to formalize my thoughts as I’ll be talking branching at DevConnections (register and come see me in September).

    Overall a good time and people seemed to really enjoy the SQL Saturday. I had about 20% of my attendees that were new, which is great. I hope to see more and more people coming to the events in the future.
  • FORMATing Dates

    I’m writing this post as a way to help motivate the #SQLNewBloggers out there. Read the bottom for a few notes on structuring a post.

    FORMAT is a function that was introduced in SQL Server 2012. It is designed to format dates and numbers as date/times. It was added to try and reduce the complexity and cumbersome nature of CONVERT and CAST.

    What I didn’t know, which I did like, is that the FORMAT command can be driven by language settings. For example, if I take a specific date, like today, I can reformat the date based on a language code.

    DECLARE @d DATETIME = GETDATE();
    SELECT FORMAT ( @d, 'd', 'en-US' ) AS 'US English Result'
          ,FORMAT ( @d, 'd', 'en-gb' ) AS 'Great Britain English Result'
          ,FORMAT ( @d, 'd', 'de-de' ) AS 'German Result'
          ,FORMAT ( @d, 'd', 'zh-cn' ) AS 'Simplified Chinese (PRC) Result'


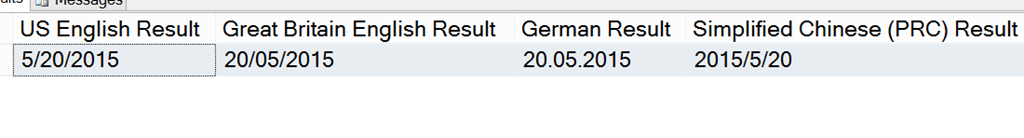
    The results of this code are different, based on the cultural settings. Of course, the Chinese settings is really the only good way to show dates without confusion.

    dateresults

    This is interesting in that if you can get the regional settings for the client, you can easily return data in a format that makes sense to the user. Of course, we typically don’t want to do too much formatting on the server.

    The default language is that of the current session. For dumb uni-lingual people like me, this isn’t an issue, but it might matter for people that speak multiple languages and might move from system to system.

    It is interesting in that you can easily format the data from a date with FORMAT. For example, I change orders to match the Chinese format:

    DECLARE @d DATETIME = GETDATE();
    
    SELECT FORMAT( @d, 'YYYY/MM/DD');


    That gets me “2015/07/20”.

    I can easily change to other formats, adding in times, or even partial times that might not make sense. For example, the result below named “Hours” has only the date. The “Date and hours” has the date and the hour only.

    DECLARE @d DATETIME = GETDATE();
    
    SELECT  'Default' ,
            FORMAT(@d, 'd')
    UNION
    SELECT  'Full Date' ,
            FORMAT(@d, 'YYYY/MM/DD hh:mm:ss.ffff t zzz')
    UNION
    SELECT  'Date and hours' ,
            FORMAT(@d, 'YYYY/MM/DD hh')
    UNION
    SELECT  'Date and minutes' ,
            FORMAT(@d, 'YYYY/MM/DD mm')
    UNION
    SELECT  'Hours' ,
            FORMAT(@d, 'hh');


    --      ,FORMAT ( @d, 'yymmdd', 'en-gb' ) AS 'CleanUS'


    The results are:

    Date and hours    2015/11/20 04

    Date and minutes  2015/11/20 11

    Default           5/20/2015

    Full Date         2015/11/20 04:11:28.9600 P -06:00

    Hours             04

    I think that there are lots of reporting queries where the formatting of dates would be handy and easier with FORMAT than CONVERT. It certainly is more intuitive to read than seeing something like “,110” in code.

    I still have the habit of using CAST and CONVERT when I’m changing types, and I’ll continue to do that. Especially as FORMAT is really limited to date types.  However when trying to get dates to render in proper formats, it’s a good choice.

    SQLNewBlogger

    This post came about while I was checking on another issue. I happened to run into the FORMAT command and hadn’t used it much, so I spent a few minutes messing around. This post came out of around 5 minutes of experimentation and 15-20 minutes of writing.

    References

    FORMAT – https://msdn.microsoft.com/en-us/library/hh213505.aspx

    Formatting Types in the .NET Framework – https://msdn.microsoft.com/library/26etazsy.aspx

  • Visualizing the Tally Table

    I was reading Dwain Camps’ article on Time Slots and thought it was a very interesting solution to a problem I’ve had a few times. Getting time slots inside of a period that I want to query. If you have a similar need, or want to learn more, I’d urge you to read the article.

    It’s always easier to join to a set of data that matches what you need than to try and filter out other rows. SQL excels at joins, so whenever possible you want to join to data. As such, when I was looking at Dwain’s code, I thought the way he listed the tally table was very interesting. I’ve seen plenty of these generated, but I hadn’t run across someone spelling it out in comments. In case you are wondering, Dwain had code like this:

    WITH Tally (n) AS ( SELECT ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) - 1 -- zero-based -- Returns exactly 86400 rows (number of seconds in a day) FROM (VALUES(0),(0),(0),(0),(0),(0)) a(n) -- 6 rows CROSS JOIN (VALUES(0),(0),(0),(0),(0),(0),(0),(0),(0),(0),(0),(0)) b(n) -- x12 rows CROSS JOIN (VALUES(0),(0),(0),(0),(0),(0),(0),(0),(0),(0),(0),(0)) c(n) -- x12 rows CROSS JOIN (VALUES(0),(0),(0),(0),(0),(0),(0),(0),(0),(0)) d(n) -- x10 rows CROSS JOIN (VALUES(0),(0),(0),(0),(0),(0),(0),(0),(0),(0)) e(n) -- x10 rows ), -- = 86,400 rows

    That’s a great visualization, and one I plan on using in the future. It makes it easy to see what’s being generated and at what scale.

    For example, I can easily do this:

    SELECT ROW_NUMBER() OVER ( ORDER BY ( SELECT NULL ) ) FROM ( VALUES ( 0), ( 0) ) a ( n ) -- 2 rows

    which returns a single column table with the values 1 and 2 in it. Two rows.

    Let’s say I want to now build a list of 12 rows. I could do this a few ways. One is to multiple 2 x 6 and get 12.

    SELECT ROW_NUMBER() OVER (ORDER BY ( SELECT NULL)) FROM ( VALUES (0), (0) ) a(n) -- 2 rows CROSS JOIN ( VALUES (0), (0), (0), (0), (0), (0) ) b(n); -- x 6 ;

    Or I could give myself more flexibility to add and remove data with comments by doing factorials. How about 2 x 3 x 2 = 12?

    SELECT ROW_NUMBER() OVER (ORDER BY ( SELECT NULL)) FROM ( VALUES (0), (0) ) a(n) -- 2 rows CROSS JOIN ( VALUES (0), (0), (0) ) b(n) -- x 3 CROSS JOIN ( VALUES (0), (0) ) c(n) -- x 2 ;

    That gives me the same result: 12 rows. Of course, I can easily expand this quickly to thousands of rows.

    The technique isn’t anything new, but the visualization is interesting, and to me, this is much easier technique to see and understand when you run into it in code. Right away I know I’m generating xx rows and I can easily see how to grow or shrink the number of I have the need.

  • Who Am I?

    I saw Brent Ozar updating his About Me slide, and thought it was interesting. Not sure if I like what he’s done, but it’s different, which usually attracts attention.

    I updated mine last year, with some help from the people at Red Gate. Here’s my slide.

    2015-05-26 18_30_25-CI for Databases.pptx - Microsoft PowerPoint

    No description of jobs, what I’ve done, my age, company, etc. No MVP or other awards or certifications.

    I wasn’t sure about this early on, but I like it. I can tailor the talk about me to the situation, making it short or long. I also include the information on the right at the end of the deck as the last slide, so people can grab it there.

    I’m not sure if this works, but I have seen a bit more traffic to my blog and more Twitter/LinkedIn activity.

    I also get some fun comments when I’m actually wearing this shirt at a talk.