Category: Blog

  • Reframing to Overcome Filtered Index Limitations

    I’m continuing on with the Blogger’s challenge in this post.

    Turning the Problem Around

    In the last post, I wrote about limitations in filtered indexes. I proposed that my table had lots of data with NULL or blank spaces in the gender column, and I wanted to avoid indexing those rows. I tried this code

    CREATE INDEX Users_Gender_Filtered2
     ON Users (gender)
      WHERE (gender IS NOT NULL OR gender = ' ');


    However, that failed. I can’t use two sets of criteria in the filtered index. But I can use one, so I need to re-frame the problem.

    If I look at the data, I have four choices: ‘M’, ‘F’, NULL, ‘ ‘. I can group two of those choices together, looking for a positive (matching) set of data rather than a negative (non-matching set. The easy way to do that is with an IN clause.

    CREATE INDEX Users_Gender_Filtered2
     ON Users (gender)
      WHERE gender IN ('M', 'F');


    This works, and I’ve got a filtered index. In the real world, I’d actually drop the first index (gender is not null), and only go with this one.

    References

    A few places I used to research this post.

    Quick and Easy Blogging

    This post occurred to me as I was writing the other post. I almost added a note on turning the index around, but realized this is a separate topic, and it makes a nice, second post. This post required < 10 minutes.

    This post continues the April Blogger Challenge is from Ed Leighton-Dick, aimed at new bloggers, but anyone is welcome. I’m trying to motivate and cheer people on.

  • Learn tSQLt and Unit Testing in Philadelphia

    SQL Saturday #390 is in Philadelphia on June 6, 2015. This is my second time attending the event, and not only am I speaking on Saturday, but I’ll be delivering information on Friday at a pre-con.

    My first SQL Saturday pre-con is taking place in Philly. I’m lucky to be asked by Sebastian Meine to co-present a day of training. We’re delivering a precon on Unit Testing in SQL Server with tSQLt. It’s available for the low price of only $99.99 now, with the price rising to $149.99 when the event begins.

    We’ll be covering quite a bit of the framework, showing you the ways in which you can write tests with examples and code that you can run that day. We’d like you to bring a laptop to write tests along with us, but we’ll have the code available later if you want to test back at the office. Here’s our agenda.

    • Introduction to Unit Testing
    • What is tSQLt?
    • Your First Test
    • Executing Tests correctly
    • Effective use of Assertions
    • Separation of Concerns
    • Testing Exceptions
    • Test Case Heuristics
    • Dealing with Test Data
    • Other Types of Testing
    • How Unit Testing fits into your Development Process

    Sebastian is the owner and developer of the tSQLt framework, which I’ve been using quite a bit over the last few years. It’s an amazing project, and really expands the ability of SQL Server developers to build better code and prevent regression issues in their applications. Quite a few SQL Server MVPs and highly successful consultants are using the framework, and I’d urge you to give it a try.

    If you’re in the Philadelphia area and want to jumpstart your testing knowledge, consider coming to our pre-con. It’s a great way to rethink how you write SQL code and put testing in place in a fairly low impact fashion.

    Register today

    Database Source Control

    If you’re in town on Thursday and want to learn about Version Controlling your databases, Redgate is also working with Ike Ellis to put on a full-day workshop covering Database Source Control. It’s $500 for the day, and you’ll get some in-depth knowledge on how to work with SQL Server code and version control as well as participate in hands-on labs that will give you the skills to implement the processes yourself. Find out more..

  • VMware and DBAs

    Disclosure: I’m a VMware fan and run it on my laptop. I definitely prefer it to other hypervisors. This workshop and all travel expenses was also paid for entirely by VMware.

    I was fortunate and grateful to be invited out to VMware recently for a multi-day workshop for SQL Server on VMware. Michael Corey wrote about the workshop here, which was an interesting way for VMware to reach out to the SQL Community and both talk to us about what they’re doing as well as get feedback from us on how SQL Server performs and interacts with the VMware platform. They will do more in the future, so if you’re active in the community or a heavy user, read Michael’s post and see if you can get yourself nominated.

    The week was full of speakers from both VMware and Tintri, a storage vendor doing interesting things. We had quite a few executives talking about their plans to make SQL Server run better, and we (as a group) provided lots of feedback. Certainly I think we helped to ensure executives understand that a database server is fundamentally different from a file server, mail server, or other workload.

    Of course, it wasn’t all work.

    Mrdenney

    I can’t talk about lots of what we discussed, as much is under NDA, but I will say that you should keep an eye on how VMware is going to improve their interaction with SQL Server. Hopefully we’ll see more products, information, and help at some of the SQL Saturdays and other SQL Server specific events.

    We also got a night out at ATT Park in San Francisco where the various attendees and speakers could interact in a casual atmosphere. An exciting game, with two of the best pitchers in the game throwing that night (Kershaw and Bumgarner).
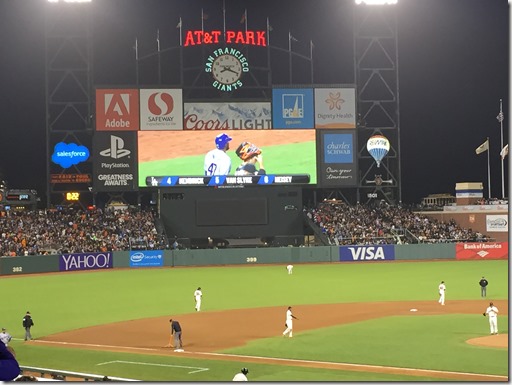
    Photo Apr 22, 8 19 09 PM

    I’d never been there, so it was a treat for me. I walked around and enjoyed the baseball game, the first one I’ve seen live in a couple years.

    Photo Apr 22, 8 26 19 PM

    Overall it was a very interesting time, with lots of points raised by everyone that I hadn’t considered or thought of. The more I hear about what the ESX platform does and handles, as well as hearing about how people have set up the platform. There are truly some powerful instances being run in a virtualized environment and I’m not sure there are many workloads that couldn’t be run successfully on VMware.

    I’m sure that there are hardware and budget restrictions for many people, but the issues aren’t VMware or virtualization, they’re the setup. In the labs we worked on, quite a few of the systems pressed a SQL Server instance hard, and the hypervisor and storage system kept up nicely.

    Photo Apr 22, 10 27 32 AM

    Not to disparage Hyper-V, but I haven’t had the experience there. I suspect both hypervisors could be tuned to a high level. Both also have some holes and places where the system might not run as smoothly as you’d like, but at least I think VMware is more aware of what we, as SQL Server professionals, see as problems.

    Tintri

    I have to admit that I have mostly though of storage as a utility. It needs to work and respond fast, but beyond that, I don’t care about it. It’s like a water faucet. I turn it on and it works.

    Tintri was the guest storage vendor that provided appliances for us to use. I didn’t’ think much of them on Tuesday morning, but by the time their founder had talked with us, I was very intrigued. I still don’t really care about storage other than needing it to work, but I was very intrigued by how this particular product works.

    Most storage is presented as a LUN to a host, which may or may not share that among guests running on a box. Tintri changes that, with what they call VM aware storage, with VM level QOS. Essentially, the storage box is aware of each guest connected as a VM. It manages the storage response and bandwidth on a VM basis, with separate FIFO queues for each drive in the VM. Essentially each VM is treated separately and the storage capabilities (min and max IOPS) can be managed separately.

    It seems as though VMs get better response from the appliance this way, with less dependency on heavy management by storage admins. They also use a lot of flash memory (SSDs) with disks to ensure fast responses. They do 100% write to flash for speed and tune the systems to aim for 99% reads from flash. Because the device is aware of VMs, it can move blocks around from flash to disk to ensure that the heavily used data is quickly available.

    If you have heavy needs, check them out. If you’re looking for a SAN, I’d look at them as well. Not sure what the pricing is, but I bet it’s competitive with other SAN devices.

    We also got a lecture about low level storage technologies from a VMware exec. The talk looked at the advances taking place in storage, which seem to be finally leaping forward. With the price of SSDs crashing, and the research into 3D flash, it seems that though more and more of us might move to flash based SAN storage quicker than we expect. Fascinating stuff, and I suspect that database systems will start to see better performance from hardware upgrades across the next 6-7 years.

    A Break

    It was nice to get away and learn something without any pressure to work on much else. This was a short workshop, close to home, and in an area that had me concentrating and paying attention in ways that sometimes don’t happen at SQL Server events. I enjoyed it, and I learned quite a few things.

    Photo Apr 22, 10 27 27 AM

    I’m not sure how much I’ll use this stuff moving forward, but I am thinking that I’d like to play around with an ESX server at home and use that to experiment with SQL Server features and especially setup. I’m looking forward to trying to get a system ready that can build a new SQL Server instance in minutes.

  • April Blogger Challenge 4–Filtered Index Limitations

    The April Blogger Challenge is from Ed Leighton-Dick and aimed at new bloggers, but anyone is welcome. I’m trying to motivate and cheer people on.

    Filtered Index Limits

    I ran across a limitation recently with filtered indexes and was surprised. Apparently, you can’t make complex filters in your definitions.

    In the last post, I wrote about creating a filtered index on gender, looking for non-null columns in a table. That code looked like this:

    CREATE INDEX Users_Gender_Filtered
      ON Users (gender)
      WHERE gender IS NOT NULL;


    However, what if I find that I have lots of NULL values, but also lots of spaces, ‘ ‘, in my table because this is an optional field, and the data entry code changed at some point. Neither of these rows actually helps me in finding the rows with an ‘M’ or a ‘F’.

    I tried creating an index like this:

    CREATE INDEX Users_Gender_Filtered2
     ON Users (gender)
      WHERE gender IS NOT NULL OR gender = ' ';


    That didn’t work, so I tried parenthesis.

    CREATE INDEX Users_Gender_Filtered2
     ON Users (gender)
      WHERE (gender IS NOT NULL OR gender = ' ');


    That didn’t work either. No matter how I moved parens around, they didn’t allow a complex (if two criteria are “complex”) filtered index.

    This is a limitation of a filtered index right now. I’m not sure if it will be changed, though I would like it to be. There are other limitations, so read the docs carefully, and think about what might work well in your environment.

    References

    A few places I used to research this post.

    Quick and Easy Blogging

    This post occurred to me while I was writing some code. I mocked up a table in about 2 minutes, and then ran a quick search on the Internet. Reading a few links was about 10 minutes and then testing the code (including dropping the table and recreating it a few times) was less than 5 minutes. All told, I solidified some knowledge and completed this in about 20 minutes. I also have drafts and ideas from this post for 2 other posts that cover this same topic in a similar way.

    Look for the other posts in the April challenge.