Tag: administration

  • Limit the Blast Radius

    You still need DBAs (that know how to back up systems and test restores). If you think you don’t, or if you manager does, then perhaps they ought to read this piece on how an AI agent deleted a production database. This wasn’t the case of an agent just running around with sysadmin access to all resources, or a lack of tests that allowed bad code to flow through a CI/CD process.

    This was a system design that had a hole in it. An API call to change infrastructure that could change both staging and production. Not something an AI set up, but humans did. A hole from both PocketOS and the API vendor that allowed the AI agent to make the same type of mistake we’ve seen humans make. A mistake of not double checking, not verifying, not following the rules of getting a second set of eyes, even a second set of virtual eyes, on the code that could drop resources.

    Reading this, I can imagine this is how some of the AWS and Azure outages occurred over the last decade. Not the 2025/2026 AI inspired ones, but the 2010-2015 human mistakes that didn’t expect a change to have such a far reaching blast radius,

    You still need guardrails, for both humans and AIs. Don’t get slack and assume either truly knows what they are doing and deserves rights everywhere. Don’t assume that your guardrails were setup correctly. AI agents make great helpers. Use some read only ones to examine your setup and look for holes. If/When we get the next Claude Mythos model (or the equivalents from Google/OpenAI/etc.) have it look for precisely the types of holes that come from bad code that looks to reset, redeploy, or re-anything in your environment.

    We separate out roles for different people to limit the blast radius of the mistakes we inevitably make. AIs aren’t necessarily smarter or better than humans. Just faster. We need separate roles, separate rights, and governance for AI agents, precisely because they can make decisions faster than humans.

    There’s tremendous potential, but and tremendous danger in allowing anyone, or anything, too many rights in any organizations. RBAC, audits, and all the other things we implement to try and reduce the number of silly mistakes are still needed. At some point we’re going to see amazing social engineered emails, messages, XSS, and other items that are designed to fool the AIs just like humans have been fooled in the past.

    We need to ensure we set good guardrails and limits when that starts to happen. Or we’re going to lose control much quicker than expected.

    PS If you want a fun and slightly scary read on how AI could go sideways, I enjoyed The Final System recently, which made me not want to deploy any sort of AI agent beyond tightly scoped ones with very, very limited rights.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • Who is Using CAGs?

    While talking to a customer a few weeks ago, they mentioned that they used Contained Availability Groups (CAG) everywhere. They also said they were amazing and wondered why everyone wasn’t using them in other environments. Of course, I questioned the “everywhere”, which turned out to be more of a default for new systems than a standard across all systems. That’s likely true of most things since it’s rare we get to update/patch/set something across an environment of any size and ensure every system is the same.

    Still, setting a CAG as a default makes some sense for enterprises. This ensures that in an HA situation I have my logins, jobs, etc. already on a secondary node. That’s been one of the challenges of using lightly linked systems that only sync up database level information. Log shipping, Replication, Availability Groups can all work to keep a secondary ready to take over, but they all miss information that is stored in master or msdb.

    That’s the stuff we have to sync manually. It can be done, but it’s work. We’ve had numerous articles at SQL Server Central on syncing logins and other objects outside of your database.

    Today I wonder how many of you are using CAGs in your environment? As the default for new systems? Moving all ones to this setup?

    Or do you even know about them? They are relatively new, since SQL Server 2022, and I have to admit I’ve heard relatively little about them in the community or from customers. Many people use Availability Groups, but not many seem to use Contained Availability Groups.

    Maybe another question is would you want to use them? There are a few things you have to consider and they can be slightly tricky, but they do some reduce some of the work when you have failovers. Of course, like any other technology, you need to test that your failovers work and you understand  the ins and outs of how they work, just in case that switch isn’t as smooth as you expect.

    It should be, but sometimes things break. If they do, you want to ensure you, or someone on your staff, knows how to fix them.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.
  • Impactful Sessions I’ve Seen: T-SQL Tuesday #196

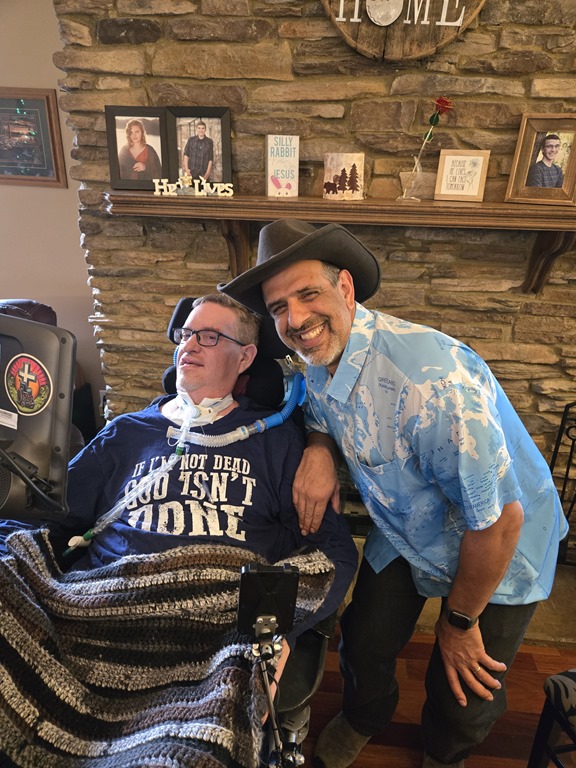
    This month I’m thrilled that Steve Hughes is hosting. I’ve read this Data on Wheels blog for a long time and I appreciate all that he does, especially given his struggles with ALS. I kicked myself a few times for not asking him to host earlier, but I’m glad I finally did.

    I also was honored to meet him a few weeks ago and spend a little time with him.

    20260329_184753

    With that, let’s get to Steve’s invitation.

    Lasting Memories from Events

    These days I don’t go to a lot of sessions at events. It’s not that I can’t learn from others, or be inspired, but I find myself often viewing the time spent with others as more valuable. I can (and often do) work through articles, tutorials, and other resources online. For me, the time talking to others if more valuable than sitting in sessions.

    However, I wasn’t always like that. Early on in my career, and even throughout, I went to a lot of sessions to learn things. Over the years, a few things have stood out to me. There is some recency bias here, and I’m sure I’m forgetting about some great sessions along the way. I don’t always remember titles, so forgive if I’ve made a mistake.

    Tempdb in Early SQL Server – This was at the very first PASS Summit in Chicago, where Kalen Delaney have a talk on tempdb. I remember this because we had lots of contention in tempdb on SQL Server 6.5 and I was struggling. Finding solutions was one of the main reasons I got my boss to pay for the conference. I know I learned a few things and worked to restructure some queries after this. I even got to ask Kalen a question, which was a thrill for me.

    Reporting Services CI – I think this was a Nigel Sammy session, but it might have been Roy Ernest or another friend. I was working to get DevOps style checks for SQL code at the time and I wondered how someone would do this for SSRS. It was an interesting session as it reaffirmed a lot of my guesses for how to approach this, but taught me an interesting way to try and verify parts of reports while ignoring others. The session focused on ensuring your clients were happy with report data more than visual layout.

    The BI Power Hour – I went to a few of these, but the first one was with Donald Farmer, Euan Garden, and others at TechEd in 2003 or 2004. It was wildly entertaining and I appreciated the humorous approach to showing ways to use the BI platform. While I am not quite as entertaining, I try to add a few minor funny things in sessions.

    Basic Backup for SQL Server – Sean McCown gave this at a few SQL Saturdays. I am not sure if I saw him in Dallas or elsewhere, but I think I was sitting in the room and decided not to go anywhere. Instead, I was curious what Sean might cover that I didn’t know. While I knew most of the material, there were a few tweaks in settings that made a different to performance. This session reminded me there is always more to learn, even when you think you know a topic well.

    Clustering in 60 Minutes – Early in the SQL Server Central days, Brian was doing a lot of HA for his company. He presented this session at a PASS Summit where he built a SQL Server 7 or 2000 cluster live onstage in 60 minutes. It was cool to see and it reminded me that I should practice my demos and make them smooth.

    Live Encryption Changes – Simon Sabin gave an interesting talk at SQL Bits where he showed a live app running against his database and how he could implement encryption without breaking the app. The app just ran a workload against his database in a loop. He made changes to the db in the background without causing errors, which was cool. I enjoyed learning the encryption techniques, but more this inspired my Architecting Zero Downtime Deployments, where I wrote my own app to do this.

    There are plenty more, but I’ll stop here.

    There’s always a lot to learn, and going to sessions is a great way to get inspired and help you build your own solutions.

  • Not Just an Upgrade

    Upgrading my database server and moving from version 6 to version 7 because of a support cycle has always felt a little funny to me. In many cases, I’ve had systems that were running smoothly and performing as needed. If people were complaining, often this was because of a lack of resources, where we needed more hardware. In other cases, this was a lack of quality code, often from other developers who were unwilling to change their approach. In neither case was an upgrade likely to change anything.

    However, an upgrade can be more than just buying new license and accessing new features. I was reminded up this by John Sterrett, with a post on how he talks to CEOs about upgrades. The upgrade isn’t just a new database server. It’s a chance to re-evaluate the system and consider something besides the application.

    In the list, John looks at this as a cost, security, and compliance decision. These days, Standard might be a better fit than Enterprise and can save on licensing. Better security can lower risk and potentially prevent issues. Being out of support, which is going to happen 3 times in the next 3 years, can be an issue for some companies. New features might reduce the costs of maintaining existing systems.

    I don’t know that this list would have made a lot of sense in the 2000-2005 timeframe, or even in the 2008-2014 range, but it might now. There are considerations beyond just the license cost. Certainly I’d be re-examining my Standard v Enterprise choice in many situations and perhaps using this argument as a reason to press developers to learn to better structure their data models and write better queries. Lowering the resource usage can lower costs. Even archival might be something I’d press on, as less data is less data to query, and honestly, are those old records in tables truly adding value?

    Or are they muddying the waters of analysis?

    Better security matters, and I do think modern auth systems are better, but often this might require a security change in other parts of the org, and still might require application redesign to account for a directory authenticating users. That might be entail its own costs and not be worth effort.

    I don’t think upgrades should be automatic, and I am a fan of running a database server for ten years, but I also think that running one for 20 years might be a bad idea. Upgrades ought to be approached with the rational, logical view that this is an opportunity for us, but one that we might choose to take advantage of or pass on.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.