Tag: administration

  • Sparse Columns Can Use More Space: #SQLNewBlogger

    I saw this as a question submitted at SQL Server Central, and wasn’t sure it was correct, but when I checked, I was surprised. If you choose to designate columns as sparse, but you have a lot of data, you can use more space.

    This post looks at how things are stored and the impact if much of your data isn’t null.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Setting Up

    Let’s create a couple of tables that are the same, but with sparse columns for one of them.

    CREATE TABLE [dbo].[NoSparseColumnTest](
         [ID] [int] NOT NULL,
         [CustomerID] [int] NULL,
         [TrackingDate] [datetime] NULL,
         [SomeFlag] [tinyint] NULL,
         [aNumber] [numeric](38, 4) NULL,
      CONSTRAINT [NoSparseColumnsPK] PRIMARY KEY CLUSTERED 
    (
         [ID] ASC
    )WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON, OPTIMIZE_FOR_SEQUENTIAL_KEY = OFF) ON [PRIMARY]
    ) ON [PRIMARY]
    GO
    CREATE TABLE [dbo].[SparseColumnTest](
         [ID] [int] NOT NULL,
         [CustomerID] [int] NULL,
         [TrackingDate] [datetime] SPARSE  NULL,
         [SomeFlag] [tinyint] SPARSE  NULL,
         [aNumber] [numeric](38, 4) SPARSE  NULL,
      CONSTRAINT [SparseColumnPK] PRIMARY KEY CLUSTERED 
    (
         [ID] ASC
    )WITH (PAD_INDEX = OFF, STATISTICS_NORECOMPUTE = OFF, IGNORE_DUP_KEY = OFF, ALLOW_ROW_LOCKS = ON, ALLOW_PAGE_LOCKS = ON, OPTIMIZE_FOR_SEQUENTIAL_KEY = OFF) ON [PRIMARY]
    ) ON [PRIMARY]
    GO


    Once we have these, I used claude to help me fill this with data. That’s coming in another post, but I uploaded the script here. This is for the SparseTable Test, where I replaced the select on line 59 with NULL values. In the NoSparse table, this selected random data.

    If I select data from the tables and count rows, I see 1,000,000 rows in each. However, the Sparse table is all NULL values in these columns.

    2025-09_0228

    Checking the Sizes

    I can use sp_spaceused to check sizes. The results of running this is below, but here is the summary

    • NoSparse Columns – 42MB and 168KB for the index
    • Sparse Columns – 16MB and 72KB for the index

    A good set of savings. Here is the raw data:

    2025-09_0229

    Adding Sparse Data

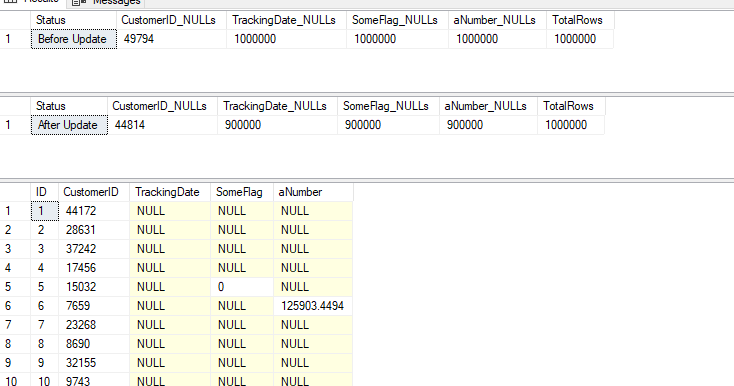
    I’m going to update 10% of the rows to be not null in different columns. Not 10% total, but a random 10% amongst all the columns. Again, Claude gave me a script to do this and I have run it. This is the SparseTest_UpdateData.sql in the zip file above.

    After running this, I have 900,000 nulls i the TRackingDate, as well as the other columns. You can see the counts below, and a sample of data.
    2025-09_0230

    If we re-run the size comparison, it’s changed. Now I have:

    • NoSparse Columns – 42MB and 168KB for the
      index
    • Sparse Columns – 33.7MB and 88KB for the index

    Not bad, and still savings.

    Let’s re-run the update script and aim not for 10% updates, but 65% updates. This gets me to only 315k NULL values in the tables, or a little over 70% of my sparse columns are full of data. My sizes now are:

    • NoSparse Columns – 42MB and 168KB for the
      index
    • Sparse Columns – 67MB and 192KB for the index

    My sparse columns now use more space than my regular columns.

    Beware of using the sparse option unless you truly have sparse data. I didn’t test to find out where the tipping point it, but I’d hope it was less than 50% of data being populated.

    SQL New Blogger

    This is another post in my series that tries to inspire you to blog. It’s a simple post looking at a concept that not a lot of people might get, but which might trigger a question in an interview. That’s why you blog. You can share knowledge, but you build your brand and get interviewers to ask you questions about your blog.

    This post took a little longer, about 30 minutes to write, though the AI made it go quicker to actually generate the data for my tables. There were a few errors, which I’ll document, but pasting in the error got the GenAI to fix things.

    This post showed me testing something I was wondering about. In a quick set of tests, I learned that I need to be careful if I use a sparse option. You could showcase this and update in 10% increments (or less) and keep testing sizes until you find when there is a tipping point. Bonus if you use a column from an actual table in your system.

    https://learn.microsoft.com/en-us/sql/relational-databases/tables/use-sparse-columns?view=sql-server-ver17

  • Guidelines and Requirements

    I saw a post from Brent that Microsoft had changed the default memory guidance. At first glance I read this as they’d changed the default values, which would be interesting. However, this is a guideline, set to 75%. I also saw a few thoughts from Randolph West on LinkedIn, and quite a few comments. The comments were interesting in a few ways.

    It is easy to look at 75% and say that won’t work for this server that’s on my mind right now because I keep getting woken up. That might be true. However, the 75% number isn’t a hard requirement. It’s a guideline, a recommendation to ensure you have enough memory for the OS, but you’re trying to use most for SQL Server. Feel free to adjust it if you feel the need.

    There are certainly people who will also look at that number and then go to a DBA and say, “you’ve set this to 70% (or 85% or whatever) and that’s not what Microsoft says.” Which isn’t true. What the text says is this under the recommended column: “75% of available system memory not consumed by other processes, including other instances. For more detailed recommendations, see max server memory

    If you go to the “max server memory” section, you see something else. It asks you to monitor before you set this, then do some calculations. Then it says: “This is a generic approximation, and your mileage might vary.”

    That’s a great statement. What they’ve written might not work for you. That’s true. Maybe you have little RAM and some other stuff on your server, so 75% might be way too high. Maybe you have 4TB of RAM, in which case, if you blindly set 75% you should be asked to work elsewhere. Anyone managing systems with 4TB of RAM should know how to monitor, measure, and then choose something different, which might be 85% of RAM.

    While there might be some requirements for managing database systems, there really are a lot of guidelines. You have to make decisions, which means you need some knowledge on which to make good decisions. If you don’t have that knowledge, or are unsure, ask others, ask the GenAI’s, conduct experiments, test things. That’s the job. Learn what you need to make things run better.

    Better being what your clients need, want, and desire.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.

  • T-SQL Tuesday #186–Agent Jobs

    It’s that time of the month again, when the T-SQL Tuesday blog party takes place. I manage this site, and am looking for hosts all the time. This month I managed to convince Andy Levy to host, and I’m grateful for his participation.

    His invitation is asking about SQL Agent jobs and how they are managed. It’s focused, but he gives a lot of choices for how to examine this subsystem in SQL Server.

    Note: if you work in Oracle or PostgreSQL or anything else, how do you schedule work in an automated fashion? Cron? Something else? You can still write.

    If you want to host, ping me and I’ll get you a month.

    Designing Jobs for an Enterprise

    I used to work in a fairly large enterprise (5,000+ people, 500+ production SQL instances) with a small staff. It was 2-3 of us to manage all these systems, as well as respond to questions/queries/issues with dev/test systems. As a result, we depended heavily on SQL Agent.

    We decided on a few principles which helped us manage jobs, with a (slow) refactoring of the existing jobs people randomly created with no standards. A few of the things we did are listed below. This isn’t exhaustive, but these are the main things I remember.

    Name schedules clearly

    Scheduling gets crazy. As a result, we would try to name with the days and times something ran. For days, we’d use SMTWRFSa. If something ran every day, that was in the name. If it were week days, then it had MTWRF in the name. Thursdays only were R.

    We’d include a time, such as 0200 or 1830 in there. If there were just one or two times, we’d list those. If it were more often, we had “every hour” or “every 15 minutes”.

    This wasn’t perfect, but it made most schedules clear.

    Job Names and Descriptions

    We tried to make job names clear with a starting noun (Backup, Maintenance, Sales), which was a little overloaded. It was a DBA thing for most work that DBAs might run and a department for those business level things.

    Job Steps

    I tried desperately to get away from code in the job step and use stored procedures instead. This helps us tune and watch things that run, and it keeps code in code places.

    For DBA stuff, we had a DBA database on each instance for our procs. We’d put our code in there (Ola’s procs, our own custom maintenance things, checks, ETL, etc.). This way we could more easily run server level stuff.

    For business level jobs or things related to a db, we want a proc in there. Then call that. This also let us often have a logging table alongside the proc where we could track progress.

    Alerts/Operators

    Luckily we had a monitoring solution that notified us when jobs failed. We didn’t use these systems. However, we did have an auditing report that queried DMVs and noted job failures and stored this data in a table (rolling 30 days) and used it to produce a daily report we archived in a folder.

    This was for our ISO compliance and auditors loved it. We would store a daily report and then add a daily note of any actions we took. That way we knew what we did and had a record.

    Summary

    For most of the other options (categories, etc.) we ignored them. The goal was to keep things very simple and streamlined. We had a standard job we deployed to most servers as part of a build process.

    We also drove a lot of activity in code off queries as much as possible and only used a table to log exceptions. We might have a table that stored the “FinanceDW” db name as an exception. The backup process would get a list of all dbs, and then delete those in the exception table. Then run as normal.

    K.I.S.S. worked very well for us.

  • Create a Linked Server: #SQLNewBlogger

    I had a customer recently that was asking about Linked Servers and some development advice. I was going to show them a few things and realized I hadn’t created a linked server in my demo environment, so I did it and decided to create a quick post on this.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    The Scenario

    I have a few demo instances of SQL Server in my local environment: Aristotle and Aristotle\SQL2022. In this case I was connected to the named instance, and decided to create a connection to Aristotle. As you can see, I don’t have any linked servers in the named instance.

    2025-04_0125

    To create a linked server, I can use this simple code:

    EXEC master.dbo.sp_addlinkedserver   
         @server = N'Aristotle',   
         @srvproduct=N'SQL Server';  
    GO

    This creates the linked server (as you can see below), with a number of defaults. In this case, the security is made with whatever login queries the linked server.

    2025-04_0126

    You can see the security properties here:

    2025-04_0127

    This might be OK in your enviroment, or it might not be. Perhaps you need to ensure everyone querying the remote server uses the same login. In which case, the sp_addlinkedserver procedure doesn’t do this. You would need to use sp_addlinkedsrvlogin to do that. That’s for another post.

    NOTE: Be sure you understand what a linked server does, how to use it, and the downsides. There are many and this can slow down your application or overload servers

    I can test this connection by right clicking the Linked Server in SSMS:

    2025-04_0128

    This works, as expected.

    2025-04_0129

    I can also run a query through the linked server, using 4-part naming with the linked server, then the database, schema, and table. This also works:

    2025-04_0160

    That’s it to get started. I recommend you be careful when using linked servers as this creates a bit of a tight coupling and makes development harder. I might recommend you get away from querying database server to database server when possible and let an application do this work if it’s possible.

    SQL New Blogger

    Linked Servers aren’t that common, but they aren’t rare. This is a skill that SQL Server people should have and understand a bit about. This post is very basic, but it provides a jumping off point where I could write a number of other posts related to linked servers and perhaps guide an interviewer along a path of asking me about them. I certainly showcase some knowledge here if someone asks me if I’ve ever created one.

    This post took me about 10 minutes to test and write, and you could probably do this in your environment. You don’t even need to servers, as you could create a loopback linked server.