Tag: administration

  • Extended Event Comfort

    I saw an interesting thread recently in the SQL Server Community Slack where someone posted about extended events (XE). They were asking about whether XE would have a problem with a situation. The problem wasn’t so interesting, but a quote from one of the responders was. The quote was:

    The best time to have learned Extended Events was ten years ago. The second best time is today.

    I love that, and I tend to agree. If you need to trace what is happening inside your SQL Server, you need to learn how to capture information with Extended Events. That’s the best way to dig into the details of how queries affect your system.

    It’s also hard. I know that whenever I need to use it, which is rare, I have to dig through some articles and docs to understand what thing I need to do. Even having some scripts hasn’t helped because it’s a sufficiently complex system that unless I use it regularly, I forget how all the filters, targets, events, etc. work.

    On one hand, I think it’s amazing, and on the other, it’s too hard to use. Even when I try the Extended Events profiler, it’s so different from Profiler that I find myself getting frustrated at times trying to dig through the information.

    I am curious how many of you think XE is easy to configure and if you use it often. What are the places it works well? For those of you that don’t use XE or haven’t learned, why not? Do you not have to trace what’s happening with queries in some detail? Or do you have another way that you dive deep into your system? Or do you not have the need?

    If you do want to learn more, we have a short Stairway Series on Extended Events to help you get started, as well as a few other articles. If you’re an expert, we’d love a few more on using XE in specific situations.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.
  • How Do You Patch 100 Database Servers?

    In most of the organizations I’ve worked for or consulted with, patching was always a challenge. Patching hasn’t usually been given a priority and is often skipped when operations staff is busy. This has resulted in lots of un-patched, or slowly patched systems. I assume this is one reason Microsoft continues to release RTM-GDR patches because some people won’t patch at all unless there are critical fixes.

    I also know that much of IT management sees patching systems like patching parking lots. Needs to be done, but tomorrow, after we do other important work today.

    Patching isn’t easy, in fact, Allan Hirt says it was never easy, but these days we don’t get the downtime over a weekend to patch, and there is a desire to patch security issues immediately because of the potential reputational (more likely) or regulatory (less likely) risks. Also, we often need to patch dozens, if not hundreds or thousands, of systems.

    So is there a way that most organizations do this? It’s interesting in the piece above that Allan notes that most of us have technical debt, and this debt consists of more than just code and systems. It’s also people, budget, politics, and more. This is even more of an issue if you didn’t write the software. Applications often limit patches or upgrades, and it can be hard enough to get applications certified on new platforms when you control everything. If you purchased something from a vendor, you might be bound by their timelines not your own.

    So how do you patch a lot of systems? There are lots of ideas and potential solutions. I’m sure Allan covered some recently in his session at the PASS Data Community Summit. For me, this boils down to building part of a process, using it, evaluating it, and then rolling it out wider. This might mean I need two processes because some systems will lag behind others for various reasons. I’d probably spend a year or two slowly adding to this process and getting it better, all the while ensuring I used automation as much as humanly possible to process notifications, approvals, and actually deploy code.

    Start small, experiment, test, evaluate, make changes. Always codifying things that I can. It’s a method that has worked for a long time.

    Steve Jones

    Listen to the podcast at Libsyn, Spotify, or iTunes.

    Note, podcasts are only available for a limited time online.
  • Rename a Database: #SQLNewBlogger

    I had someone ask me how to rename a SQL Server database recently. They were doing some development work and wanted to rename databases to test an application. I thought I remembered, but in this post, I show I learned something.

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    Using sp_rename

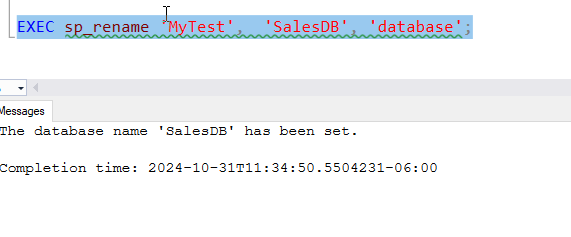
    I thought sp_rename would work, and sure enough, it did.

    2024-10_0232

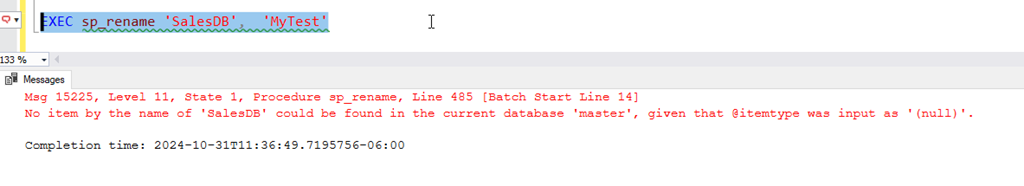
    However, I need to object type. If I remove that parameter, it fails:

    2024-10_0233

    The command is looking for an object in the current database by default.

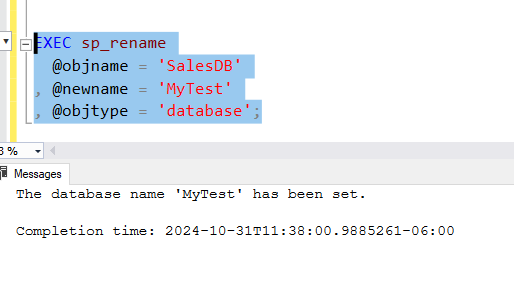
    Technically, I ought to do this to be explicit, naming the parameters.

    2024-10_0234

    I have a better way, however. Note: it’s not sp_renamedb, which is marked for deprecation.

    ALTER DATABASE

    I don’t know when this changed, or if, but you can use ALTER DATABASE to change the database name. There is a MODIFY NAME option for this command that works well. You can see this below.

    2024-10_0235

    This is very clear and seems like better DDL For this process, which can easily be captured as code without worrying about parameters or ordering or anything else. I’d recommend using this.

    SQL New Blogger

    This post took me about 10 minutes to write. Easy. I had done a few experiments and I had code ready (which went to the customer), so I didn’t spend time there. Just rewrote what I did and learned in a few minutes.

    You could do this, add to your blog, and maybe get an interviewer to ask you about this after they saw your post.

  • Monday Monitor Tips: Tracking The Cost of Instances

    One of the things that I’ve been asked in every operations situation is what licenses do we need for our servers. This is a rare request, often once a year, but it results in a bunch of work to figure out what’s running.

    I hate these requests because they always cause delays in other work.

    This is part of a series of posts on Redgate Monitor. Click to see the other posts

    What’s Running?

    Redgate Monitor makes this easy to track (if you’re monitoring all your servers). In the Estate tab, there is a Licensing item. If you check this out, you see something like this:

    2024-10_0192

    This is a quick view of our systems, letting me know what cores we have in service based on the edition. This is a quick report, and if you’re monitoring all prod systems, this gives you a pretty close look at what you need.

    The exceptions here are that we are reporting all cores for all nodes in HA/DR setups, and that might be more licenses than you need. However, you can subtract all the standby nodes if you have Software Assurance on those systems since you do not need to license those.

    Of course, you shouldn’t need to license dev/test systems if you run developer edition, and you should.

    You can filter by groups or other items that can help you focus on part of your estate. This is the standard Redgate Monitor at the top set of filters.

    2024-10_0193

    There also is an “Export” button on this page, so you can save off your data as an Excel XLSX.

    Summary

    This section of the Estate tab gives you a quick view of your obligations to Microsoft for licensing. It’s a nice way to track this and report on it when you need to audit this information without spending a lot of time compiling the information.

    Your Finance group will thank you.

    Redgate Monitor is a world class monitoring solution for your database estate. Download a trial today and see how it can help you manage your estate more efficiently.