Tag: administration

  • Why Does My Log Grow–SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    This is a great topic, and really, every DBA or admin should blog this and be sure they understand the issue.

    I saw a posting from someone that said this: they kept running low on disk space where the transaction log was kept. They would shrink the log, and they had 3 log backups per day, but the log kept growing, and this was an issue. What can they do?

    Let’s examine what happens: first, assume you have a trans‌‌action log that gets 2 transactions an hour. You have enough log space for 4 transactions in your log file. You back up 3 times a day (every 8 hours). Here’s your log size in transactions:

    1:00am - 2 transactions
    2:00am - 4 transactions‌‌‌
    3:00am - 6 transactions (log grows)
    4:00am - 8 transactions (log grows) 
    ‌5:00am‌‌ - 10 transactions (log grows)
    ‌5:00am‌‌ - 12 transactions (log grows)
    ‌5:00am‌‌ - 14 transactions (log grows)
    8:00am‌‌ - log backup with 14 transactions. Log is large enough for 14 transactions
    ‌9:00am - 2 transactions
    10:00am - 4 transactions‌‌‌
    11:00am - 6 transactions 
    12:00pm - 8 transactions 
    1:00pm‌‌ - 10 transactions 
    ‌2:00pm‌‌ - 12 transactions 
    ‌3:00pm‌‌ - 14 transactions 
    4:00pm‌‌ - log backup with 14 transactions. Log is large enough for 14 transactions
    ‌4:30 - you shrink the log back to 4 transaction size
    5:00pm - 2 transactions
    6:00pm - 4 transactions‌‌‌
    7:00pm - 6 transactions (log grows)
    8:00pm - 8 transactions (log grows) 
    9:00pm‌‌ - 10 transactions (log grows)
    ‌10:00pm‌‌ - 12 transactions (log grows)
    11:00pm‌‌ - 14 transactions (log grows)
    12:00am‌‌ - log backup with 14 transactions. Log is large enough for 14 transactions
    ‌

    Repeat this every day.

    Now, how does this change if we run log backups more often? Let’s say we decide to run log backups every hour. Now I get:

    1:00am - 2 transactions‌‌‌, log backup runs
    2:00am - 2 transactions‌‌‌, log backup runs
    3:00am -2 transactions‌‌‌, log backup runs
    4:00am - 2 transactions‌‌‌, log backup runs
    ‌5:00am‌‌ - 2 transactions‌‌‌, log backup runs
    ‌5:00am‌‌ - 2 transactions‌‌‌, log backup runs
    ‌5:00am‌‌ - 2 transactions‌‌‌, log backup runs
    8:00am‌‌ - 2 transactions‌‌‌, log backup runs
    ‌9:00am - 2 transactions, log backup runs
    10:00am - 2 transactions‌‌‌, log backup runs
    11:00am - 2 transactions‌‌‌, log backup runs
    12:00pm - 2 transactions‌‌‌, log backup runs
    1:00pm‌‌ - 2 transactions‌‌‌, log backup runs
    ‌2:00pm‌‌ - 2 transactions‌‌‌, log backup runs
    ‌3:00pm‌‌ - 2 transactions‌‌‌, log backup runs
    4:00pm‌‌ - 2 transactions‌‌‌, log backup runs
    5:00pm - 2 transactions‌‌‌, log backup runs
    6:00pm - 2 transactions‌‌‌, log backup runs
    7:00pm - 2 transactions‌‌‌, log backup runs
    8:00pm - 2 transactions‌‌‌, log backup runs
    9:00pm‌‌ - 2 transactions‌‌‌, log backup runs
    ‌10:00pm‌‌ - 2 transactions‌‌‌, log backup runs
    11:00pm‌‌ - 2 transactions‌‌‌, log backup runs
    12:00am‌‌ - 2 transactions‌‌‌, log backup runs

    In both scenarios, the total log transaction load across the day is the same. The total log backup size is the same across the day. However, a log backup allows me to reuse the log, so I never run out of space and get growths in the second scenario.

    If you aren’t sure how things work, or want to write your own blog, I would also recommend you read this:  http://www.sqlservercentral.com/articles/Administration/64582/
     

    ‌‌

  • SQL Server is Getting Smarter

    There’s been a lot of press and media about Microsoft on the AI and machine learning work they’re heavily investing in. From Cognitive Services to Cortana to Bots, Microsoft is really investing in developers and applications that will perform detailed analysis and make more complex decisions in any environment. Event SQL Server has gotten Python added to R Services and will change the way we run queries for analysis and reporting.

    The effect this will have on data professionals is not just limited to SQL Server’s machine learning capabilities. This week I saw a couple announcements from Microsoft on changes in SQL Server. Automatic plan correction is coming in SQL Server 2017 and automatic index management is in SQL Azure. I expect the latter to make an appearance in the on-premises product at some point, perhaps 2018 or 2019, but I would certainly count on this coming to your local installations at some point.

    Currently plan correction still requires a DBA to decide which plans need correcting, but once that the decisions are made, SQL Server can handle things. However, with automatic plan correction, we can allow SQL Server to force the last good plan when it detects an regression. This isn’t a huge change, but it can dramatically reduce some of the random calls that DBAs get when plans regress and performance tanks. Over time, we might find that many of those nuisance calls go away. I hope that most of you have other work that you can do instead of tracking down plan regressions, and you certainly should have more.

    There are other changes, such as threat detection, that I expect will allow a single person, perhaps the accidental DBA or developer, to manage a lot of the trivial, but important, administrative items for a SQL Server instance. This means that we need less data professionals that focus on the infrastructure side of databases. There will be more and more ways that SQL Server improves to handle the mundane tasks, amplifying the power of a single human, reducing the management burden, and using less people to manage more and more.

    I expect additional capabilities in SQL Server to simplify most tasks over time, and I’m hoping there’s one in particular that gets built soon. I’d like to see automatic backups (full and log) as a part of the database creation process. Some helpful defaults, perhaps at the instance level, that are applied to ensure that all databases are being backed up and we never see the “transaction log full” error unless we run out of disk space. It will come, as we move to the quick, button click, automatic setting method of managing all the cattle in our infrastructure. At least, I’m planning on this happening.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.8MB) podcast or subscribe to the feed at iTunes and Libsyn.

  • Restore to a point in time–#SQLNewBlogger

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers. This is also a part of a basic series on git and how to use it.

    One of the things I had to show recently was a restore to a point in time, and I needed to actually lookup syntax. That’s a good excuse for a #SQLNewBlogger post, so here we go.

    When you restore, the default is to restore to the end of the backup file, whether full, diff, or log. In the latter, you have the option to stop early, and only restore part of the log. In doing this, you have two choices:

    • restore to a time
    • restore to a marked transaction

    Relatively few of us use marked transactions, but they can be useful. However, this post looks at time.

    Let’s do a few things and show how this works.

    Setup

    The first thing I need to do is get a database, with some data. I’ll create a database, add a table with a row, and then back up the database.

    CREATE DATABASE RestoreTime;
    GO
    USE RestoreTime
    GO
    CREATE TABLE BackupLog
    ( logdate DATETIME2 DEFAULT SYSDATETIME()
    , logmessage VARCHAR(200)
    )
    -- add a message
    INSERT dbo.BackupLog
            ( logdate, logmessage )
        VALUES ( SYSDATETIME(), '1st Log, before a backup' )
    GO
    BACKUP DATABASE RestoreTime TO disk = 'RestoreTime.bak'
    GO

    Next we want to add some data to the table and get some log records. In this case, I’ll use a simple loop to add a new row to the table every second. This gives me some points in time to look for and use to show I  am restoring to a point in time.

    DECLARE @seconds INT = 10,
            @starttime DATETIME2 = SYSDATETIME();
    
    WHILE (SYSDATETIME() < DATEADD( SECOND, @seconds, @starttime))
     BEGIN
      INSERT dbo.BackupLog
            ( logdate, logmessage )
        VALUES ( SYSDATETIME(), 'Log record entered at ' + CAST(SYSDATETIME() AS VARCHAR(30)) )
      WAITFOR DELAY '00:00:01'
     END
    
    GO
    BACKUP LOG RestoreTime TO DISK = 'RestoreTime.trn'
    GO

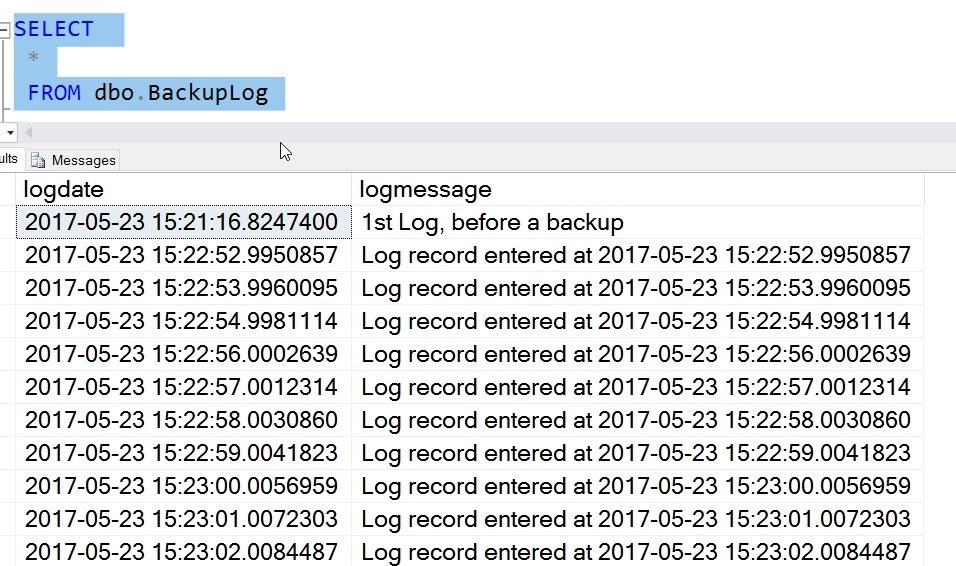
    I’ve added data, and my table looks like this:

    2017-05-23 15_23_12-SQLQuery8.sql - (local)_SQL2016.RestoreTime (PLATO_Steve (57))_ - Microsoft SQL

    My log backup contains all these records. If I restore the full backup and log now, by default I’ll end up in this state, with all these rows in my table. However, what if I want to only get the first 5?

    I can use the STOPAT syntax in my restore. I start by restoring the full with NORECOVERY and then the log. However, in the log, I’ll choose a time that is after row 5, but before 6. In this case, that’s 2017-05-23T15:22:57. Here’s the code:

    USE master
    GO
    RESTORE DATABASE RestoreTime FROM DISK = 'RestoreTime.bak' WITH NORECOVERY, replace
    GO
    RESTORE LOG RestoreTime FROM DISK = 'RestoreTime.trn' WITH RECOVERY, STOPAT = '2017-05-23T15:22:57'
    GO
    USE RestoreTime
    GO
    SELECT 
     *
     FROM dbo.BackupLog

    I have my results below

    2017-05-23 15_31_10-SQLQuery8.sql - (local)_SQL2016.RestoreTime (PLATO_Steve (57))_ - Microsoft SQL

    Only the log activity before this time is restored.

    SQLNewBlogger

    After I’d looked up the syntax, I spent only about 10 minutes setting up the demo and getting this ready. Practice skills and write about it. Show your next employer you are always learning and working.

  • Using DBCC Clonedatabase

    I haven’t messed with the new DBCC CloneDatabase option in SQL Server 2014/12016 (depending on patches), but recently I saw this:

    2017-04-28 17_39_32-Argenis Fernandez on Twitter_ _Anyone out there using TFS that can send me a bac

    On a quiet Friday afternoon, this seemed like a good time to experiment. We (Redgate Software) have a salesdemo VM that we use to show various Redgate products to customers and clients. On the VM, we have a TFS install that shows how we plug into that platform.

    We have a slick demo system on EC2 where I can fire up a self-service VM for use anytime. Since DBCC CloneDatabase needs recent SQL Server versions, I had to use that. My export of the demo VM from late last year is SQL 2012 Sad smile.

    Once the system was up, I found the SQL instance that hosted the TFS databases and connected with SSMS. Then what?

    I ran a quick search and found the MS support article: How to use DBCC CLONEDATABASE to generate a schema and statistics only copy of a user database in SQL Server 2014 SP2 and SQL Server 2016 SP1

    This explains that the basic syntax is

    DBCC CLONEDATABASE (source, target)

    The source is the database to clone, and the target is the new database you want created. Using that, I quickly ran this twice, once for the tfs_config database and once for the tfs_defaultcollection db. I used create names for the targets.

    DBCC CLONEDATABASE (tfs_config, argenistfs_config)
    
    DBCC CLONEDATABASE (tfs_defaultcollection, argenistfs_defaultconfig)

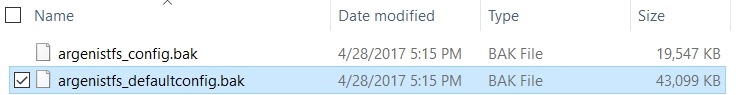
    With these database, I ran backups and uploaded these to a share for Argenis to use. The clones contain schema and stats, but no data, so they’re small. The live databases are a few GB, but the clones are small.

    2017-04-28 17_49_58-Public

    I haven’t used the cloned databases for anything, but there are articles out there that will help you to use this to work on issues in your main system. SQL Performance has one from Erin Stellato and so does Brent Ozar.

    This is going to be one of those tools that will be helpful for DBAs in the future, so play around with it.