Tag: administration

  • The War Room

    I remember the first time I worked in a large, 10,000+ employee company, and we had a crisis with our systems. A number of us crowded into the cold computer room, gathering around a few workstations and trying to solve the issues. We worked furiously to restore service, with various managers and executives periodically knocking on the locked door wanting status updates, unaware they were slowing us down. Eventually we stabilized things, but it was a chaotic and inefficient environment with too many people involved and more time spent talking and discussing problems than solving them.

    Later I worked in a similarly sized, but more mature company. We had various virus issues, including SQL Slammer. When we realized there was a crisis, we’d contact a director who would convene a crisis team. There were designated individuals from various groups (network, security, database, etc.), each of which had a backup, but only one representative from each area was a part of the team. Those were the only people that participated in the meetings, giving status updates, or taking actions to be distributed to their team. Each was responsible for coordinating the activities of their area with others. Status updates were scheduled regularly with a specific individual posting them. The director leading the crisis would update executives.

    I thought back on these experiences (I was the main person in the database area) when I read about the Amazon war room experiences around launching one of their products. While our crisis management wasn’t quite like this, it was fairly well scripted. There were times that the process didn’t proceed smoothly, but it worked well overall for problem situations. I wish that we had handled deployments a little more formally, though not as strictly as Amazon did. Our deployments didn’t have a large an impact as a product launch, but we certainly could have used more coordination between different groups. I remember no shortage of networking/firewall issues, security mismatches, or missed communications with customers from deployments.

    I’d like to see software deployment to be an easier and simpler process. My hope is that more people learn to code better, and they implement unit tests to ensure they meet requirements and prevent regressions. I want to see automated deployments into staging environments to catch potential issues, and eventually, smooth execution from the client perspective. I want these things to happen for both database and application software.

    A better development, test, and deployment process doesn’t mean that there isn’t a need for strong coordination among everyone involved, and certainly doesn’t mean a crisis team isn’t prepared to respond if there are issues. Thinking ahead to potential issues and ensuring everyone is on the same page helps to smooth any of the bumps that will occasionally crop up. At least, I expect they are only occasional if you follow a good CI/CD process.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 5.5MB) podcast or subscribe to the feed at iTunes and Libsyn.
  • Easy Database Space with dbatools

    One of the things that I’ve seen DBAs query for is free space in a database. In fact, this is one of the most common questions posted on SQLServerCentral by newbies that are trying to manage their instances and ensure they don’t use too much space or run out of space.

    The most common way to do this is with sp_spaceused. This system stored procedure has been around for a long time and is commonly used. However, it’s cumbersome to me. I get two result sets, I get data formatted in both MB and KB, it’s hard to use for multiple databases, and incorporating it with some automated tracking gets annoying. Not hard, just annoying.

    Get-DbaDatabaseFreespace

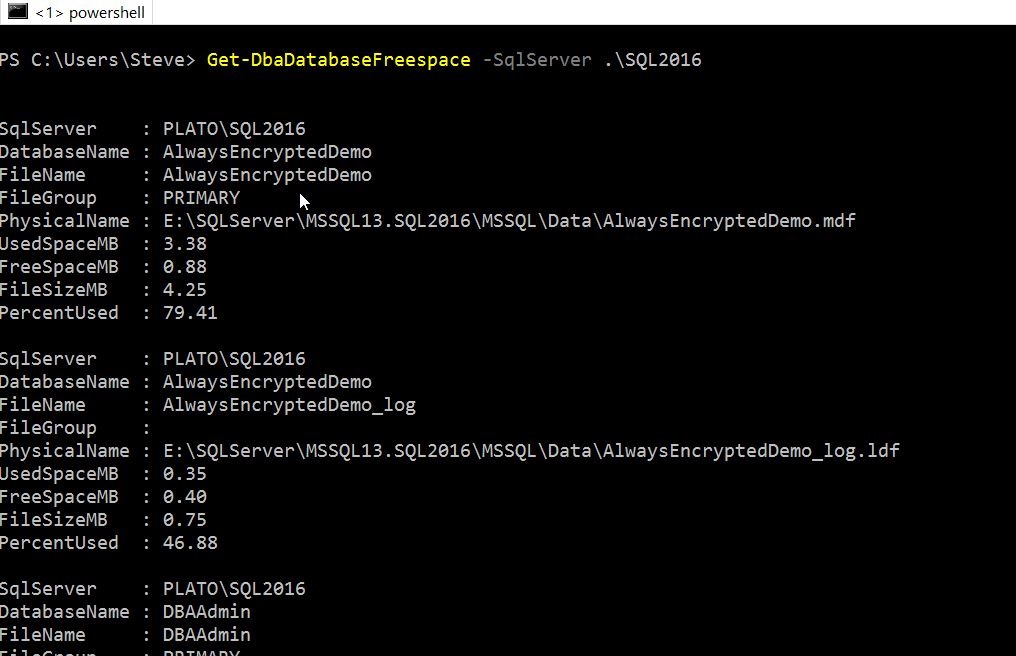
    Enter dbatools. One of the cmdlets included is Get-DbaDatabaseFreespace and this does exactly what you’d expect. This takes the name of an instance as a parameter, and when you run it, you get a bunch of information about your databases and their space usage.

    2016-12-29 09_17_01-powershell

    These are good numbers, but with PoSh, I can easily just get the data I want. For example, I can add a –Databases parameter and see specific databases.

    2016-12-29 09_31_21-powershell

    I can also limit reformat the data in a table and limit what’s returned:

    2016-12-29 09_32_29-powershell

    This flexibility to easily see data is one thing that I like about PosH. I could pipe this into a filter and look for those items that are of a certain size, or have a certain percentage value.

    Putting this into a report, or even an alert that might get sent to DBAs is a great way to keep an eye on space and ensure that you don’t run out of space. Of course, tracking this over time is easier with a tool like SQL Monitor, but for quick checks, this dbatool is very handy.

    If you haven’t played with these, I’d recommend you do this. This collection makes working with SQL Server and PoSh much easier.

  • Provisioning

    This editorial was originally published on May 24, 2013. It is being re-run as Steve is on holiday.

    At a talk recently, the presenter talked about the time lag for an on-premises server to be installed and configured to be on the order of months. Not that many, but it could easily be six months.

    That seems crazy, but in many companies I’ve worked in, that wasn’t an unusual time frame. From the time someone decided that a purchase was allowed, it could be days for the accounting department to approve the funds. A day or two to place an order, assuming that IT had already provided the specifications. Vendors respond quickly, but it could still take a week or two, possibly even more, for a server to arrive at our company.

    One of the advantages of cloud computing services is that new virtual machines can be bought and enabled in minutes. That might be true, but I wanted to ask many of you if you know how longs it actually takes for you to begin working on a new SQL Server.

    How long does it take to provision a new server?

    Imagine that you were to ask for a database server today, and you management agreed to grant the approval, think about how long would it be before you could sign into a SQL Server. I’m sure some of you have virtual infrastructures available, and that should reduce the time it takes, but let us know if that’s your setup and how long it takes.

    The ultimate service would be a cloud like application inside your organization that allowed you to select a SQL Server template, and send you a server name and login with minutes after an automated build took place. I don’t know many companies that have that yet, but I think many of us would appreciate that capability. Especially if we could choose the hardware we required.

    Steve Jones


  • Monitor All the Changes

    Can you monitor every configuration change and setting on all your SQL Server instances? Can you get an alert every time code changes, or even if an option for an object changes, such as the changing of an EXECUTE AS or the rebuild options for an index? Do you want to know about every security change (new logins, grants, revokes, etc.). Can you keep up with every alteration of a SQL Agent job?

    You certainly can, but across any busy enterprise, all these alerts might result in a constant stream of items to review each day. In fact, in some companies, the volume might be high enough that this becomes a full-time job for someone. I’m not sure many of us think that it’s worth an employee’s time to actually review every change.

    Even if you decided it’s worth reviewing every change, is it possible to do a good job actually doing so? Too many alerts usually result in an individual starting to treat all of them as though they are the same priority. It becomes hard to differentiate what’s important to review and what’s not over time if you are always looking at a stream of changes across disparate systems. This is one reason why I never want to get success message, but even failure or change messages can be problematic when the volume is high.

    What can you do in a situation like this? Certainly there are alerts that are critical and need to be addressed right away, aren’t there? There are, but they are probably few. Making the decision about which items are important enough to review daily can be hard. I’ve typically only wanted critical alerts for backup tasks (after some retry) and privileged security alterations (add/change/remove sysadmin/securityadmin/processadmin/serveradmin). Those are items I need to take action on. Most other items, such as failed index rebuilds, job schedule changes, configuration alterations, I just want to capture and log.

    In one of the SQLskills newsletters recently, Paul wrote about an issue where replication settings had changed. The distributor had gone from 72 hours to 72 days, resulting in memory pressure for the workload. While I know this is a problem, is this the type of alert you’d define as critical? I’m not sure I would. In fact, this is the type of alert I’d want logged as a set of changes on this system so that I could review it when it seems that the system is not running as smoothly as it otherwise might be. In fact, this is the type of problem I’d hope I’d catch through performance monitoring, which might pro-actively catch performance degradation that would lead a DBA to review changes and metrics before a user reported the situation.

    Ultimately I want monitoring systems to help me find issues, and only notify me when I might need to take some action. To do this, the system might need to capture everything, but I want most of the items filtered until such time as the information might actually help me solve an issue. This takes some time to setup and tune as you discover holes in your monitoring, or you find that too much data is being passed on. Don’t be more afraid to add more data to capture, but be ruthless about removing extraneous notifications from the system. This is a case when too much information sent to the administrator is as bad as too little.

    Steve Jones