Tag: administration

  • The Writeable Warm Standby

    I saw a question recently that went like this: I get one full backup from FTP. I’ll get daily log backups through FTP after this, but never another full. I need to restore this daily log backup and allow the group receiving the database to read/write the copy, and then reset it with the new log backup overnight.

    First, this is untenable. At some point you’ll have some issue with transfer, lose a log, or the database will go corrupt. I can guanantee you that at some point you will need another full backup. Not every week, or even every month, but you will need one.

    Second, this is a tough situation. I saw some answers, which I agreed with, but I started thinking about ways to get that data moved. My first thought it use STANDBY and move the data every day to a clean database. I’ve done this before, and in the GB range, even 100s of GB, this can work. It helps if you can whack indexes and constraints on the destination, but a copy of data table-by-table goes fast.

    However then I thought about other ways. You can’t take a backup of a standby database, nor can you take a snapshot. However while searching, I saw an answer to this post on SO.

    TL;DR: copy the mdf/ldf to a new database.

    That was interesting, so I decided to test it. Turns out, it works pretty well. HOWEVER, it’s dangerous, and I think you should be very careful about this. I wouldn’t count on this being production stable, and certainly not data stable. You better have other copies of this data.

    Here’s what I did. First, create a database with some data.

    CREATE DATABASE mydb;
    GO
    USE mydb;
    GO
    CREATE TABLE mytable(id INT);
    GO
    INSERT mytable SELECT 1;
    GO
    

    Next, let’s back this up, take if offline, and then copy files.

    USE master;
    GO
    BACKUP DATABASE mydb
     TO DISK = 'mydb.bak';
    GO
    

    Now we can copy the files to new files. There are UAC issues here, so you’ll need to add some rights to the files if you do this regularly. I left a comment in my script, but I actually did a CTRL+C,CTRL+V in the data folder, allowing the UAC permissions to work.
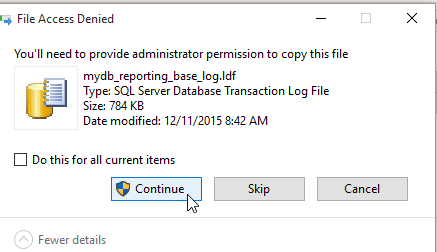
    2015-12-11 08_42_22-Photos

    Once that was done, I had new files:

    2015-12-11 08_28_15-Photos

    I tried to run at attach, but got a permissions error:

    Msg 5120, Level 16, State 101, Line 30
    Unable to open the physical file “D:\SQLServer\MSSQL11.MSSQLSERVER\MSSQL\DATA\mydb_reporting.mdf”. Operating system error 5: “5(Access is denied.)”.

    The solution I found was to run SSMS as an administrator. Annoying, but it works.

    At least for the OS error. However, then you get this:

    Msg 1824, Level 16, State 1, Line 35 Cannot attach a database that was being restored.

    You can’t do this. At least not easily.

    You can do this. First, delete the files you copied over, then run this:

    CREATE DATABASE mydb_reporting
    go
    alter database mydb_reporting set offline;

    The next step is to delete the MDF and LDF files, which will be mydb_reporting.mdf and mydb_reporting_log.ldf  by default. I could specify other names, and would if this were something I needed to script.

    Once those files were deleted, I’d next copy my files again and rename them. That would result in this:

    • mydb_reporting_base.mdf –> mydb_reporting.mdf
    • mydb_reporting_base_log.mdf –> mydb_reporting_log.ldf

    Now I can go back to SSMS. In SSMS, I do a simple ALTER.

    ALTER DATABASE MYDB_Reporting SET ONLINE

    Then I can run this:
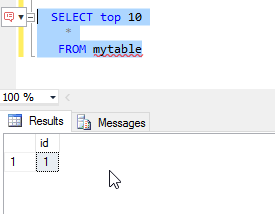
    2015-12-11 09_03_28-Start

    I have a copy of my database. Can I apply logs and move forward? Let’s try. First, let’s add data and make a log backup

    USE mydb
    GO
    INSERT mytable SELECT 99
    GO
    
    BACKUP LOG mydb TO DISK = 'mydblog.trn'   
    GO
    

    Next we restore again. We also set the databases offline again.

    RESTORE LOG mydb_reporting_base
     FROM DISK = 'D:\SQLServer\MSSQL11.MSSQLSERVER\MSSQL\Backup\mydblog.trn'
     WITH  MOVE N'mydb' TO N'D:\SQLServer\MSSQL11.MSSQLSERVER\MSSQL\DATA\mydb_reporting_base.mdf'
        ,  MOVE N'mydb_log' TO N'D:\SQLServer\MSSQL11.MSSQLSERVER\MSSQL\DATA\mydb_reporting_base_log.ldf'
        , STANDBY = 'D:\SQLServer\MSSQL11.MSSQLSERVER\MSSQL\Backup\undo.log';
    GO
    USE master
    GO
    ALTER DATABASE mydb_reporting_base
     SET OFFLINE;
    GO
    ALTER DATABASE mydb_reporting SET OFFLINE
    GO
    

    Once again it’s file copy time. The UAC comes into play again as I copy and rename the _base files. However once that’s done, things work.

    2015-12-11 10_17_02-Photos

    This works, but I am not recommending this as something you should do, especially for critical systems. This can work, but it’s dangerous, and really not supported by MS.

  • Virtual Failback

    I saw a very interesting tweet from Scott Stauffer asking this: “… looking for quick’n’easy way to make workload virtual w/ fail-fast method to physical if performance doesn’t meet expectation.” This was part of a conversation Scott was having in looking to move to a virtual environment from his current physical one. That’s something I think more and more people are being asked to do, whether they do in inside of their own data center, or they move to some type of hosted or cloud environment. There is increasing pressure from management to consider using cloud-type environments to reduce the capital expenditures for new systems and move to an operating cost model.

    I don’t have a fundamental problem with cloud environments, though I think it is important to carefully consider the pros and cons, but I can certainly appreciate Scott’s concern. No matter how well we architect things or prepare for the movement of a physical environment to a virtual one, there could be problems. Having a fall back plan becomes important, and even more important if we discover problems when some time has passed.

    While there are utilities that can move a physical machine to a virtual environment, there aren’t any (or any I know of) to reverse the process. Honestly, though, I think virtualization has so many advantages, that if I really had performance issues and needed to return to a physical host, I’d continue to virtualize my instance, but I’d have only one VM on my physical host, with access to almost all the resources on the hardware. Today’s hypervisors have so little overhead, I wouldn’t hesitate to run one virtual machine on a host.

    Ultimately, moving to a virtual environment is very much like moving to new hardware. There are definitely different configuration options you may need to set, but you can contract for some help with configuring your system. In the worst case, just use a single VM on a host, get hardware abstraction, and manage the machine like any other. Just don’t forget to have the hypervisor and your guest start up automatically after a reboot.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 3.0MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • Learn to Use Filegroups

    This editorial was originally published on May 12, 2011. It is being re-run as Steve is away at SQL Relay today.

    In SQL Server, filegroups are a management technique that I don’t see many people using. It’s amazing how many people ask questions about filegroups on the discussion forums, often unsure of how they fit into a well architected SQL Server. I have tended to use filegroups mostly as a space management technique, when I need to add more disks to my server, but they can be used in many more places.

    We continue to grow our data sizes all the time. While many databases are still measured in the single digits of gigabytes (or smaller), it is fairly common to find many database servers with over a terabyte of disk space. Our disks grow larger and larger, but it seems that data grows faster than disks, requiring larger storage subsystems all the time.

    While our storage grows larger, the tolerance for delays shrinks and demands for better performance increase. That means that data professionals need to be more cognizant of not only how their code is written, but also how they design storage. Tiering storage is one idea that I think has merit, but one that requires some planning.

    In SQL Server, we can’t split a table across filegroups. Or can we? We can partition a table (Enterprise Edition and higher), which can allow us to manage performance and storage appropriately. There is also the recommended practice of only having system objects in the primary partition and using separate filegroups for user data. That allows you to bring a partial database online, again, in Enterprise Edition only, while you restore different filegroups.

    This isn’t the first thing I would recommend you learn about SQL Server, but as you advance your knowledge, you should better understand when and how filegroups can help you. You will use them at some point and being comfortable with a filegroup restore is one of the skills that separates the accidental DBA from the data professional.

    Steve Jones

  • The Work of the Ancients

    I was reading a post from someone recently where they noted that they didn’t worry to much about the architecture of the system since it wouldn’t likely last very long. The poster had a comment that many systems are replaced inside of a few years.

    In my experience, that’s not usually the case. In fact, while I don’t expect many applications I’ve worked on to last for 25 years, I suspect many of them will exist for ten years or more, especially if they are receiving regular development resources. With that in mind, I wanted to see how your databases are faring these days. I suspect a database might last longer than a particular application, as it seems most organizations are loathe to ever let data go.

    What’s the age of your oldest, regularly used database?

    I’m looking for an age in years. If the answer is less than one, I’m not sure I’d call that old at all. I am sure many of your  systems are older, and might have changed, but let us know the year when the system went into production.

    I can tell you the SQLServerCentral systems are old in some ways, not so old in others. We’ve grown from one database to three over the years. The oldest database is circa 2003. Some of the data from that one was migrated to other databases around 2007. We’ve got data in the system since 2001, but we’ve certainly changed structures and storage over the years.

    I’d guess that most of you that are working in companies that are older than ten years will have a database that’s at least that old. However let us know this week, and if you have any interesting notes, feel free to share them.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.4MB) podcast or subscribe to the feed at iTunes and LibSyn.