Tag: DevOps

  • DevOps Basics–Getting Started with Git

    Git is taking over the world as a Version Control System (VCS) and it’s actually fairly easy to use. This is a quick post on getting started using git.

    Git is free and you can get it from: https://git-scm.com/

    I use Chocolatey, and you can also download it for windows with this code:

    choco install git

    or

    choco update git

    In any case, this is a simple install on your machine. If you’re on OSX or Linux, you can download and install it in whatever way you want for those systems.

    Once Installed

    You can check that git is installed at the command line. There are also clients, but I like the command line, especially when getting into DevOps.

    git version

    This code tells you if git is installed. In this case, you can see my version (after I updated).

    2020-03-25 11_25_47-Window

    Now it’s installed, what do I do? Well, I first want to create a repository to track my code. A repository (or repo) is really a folder where all changes to code are tracked. I can do this with the “git init” command, but I need to do this in an empty folder.

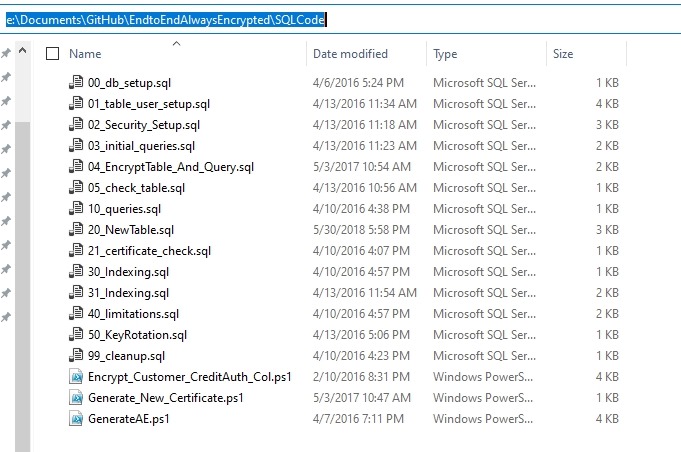
    I have some code in e:\Documents\GitHub\EndtoEndAlwaysEncrypted\SQLCode for a presentation I do. I can see lots of .sql files in here:
    2020-03-25 11_28_03-Window

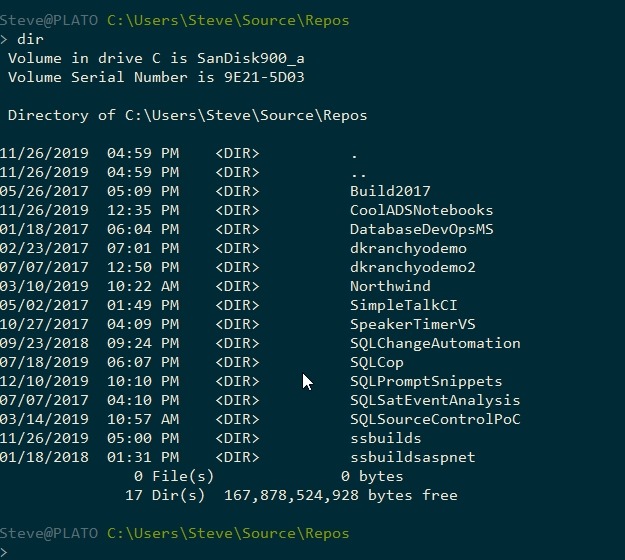
    I want to track this code, so I’ll make a repo for it. On Windows machines, there is a Source\Repos folder under your user profile. For this machine, that is C:\Users\Steve\Source\Repos. You can see I have a few folders here:
    2020-03-25 11_28_59-Window

    Let me create a new folder, called EndtoEndAlwaysEncrypted. Once I do that, I’ll change to that folder and run

    git init

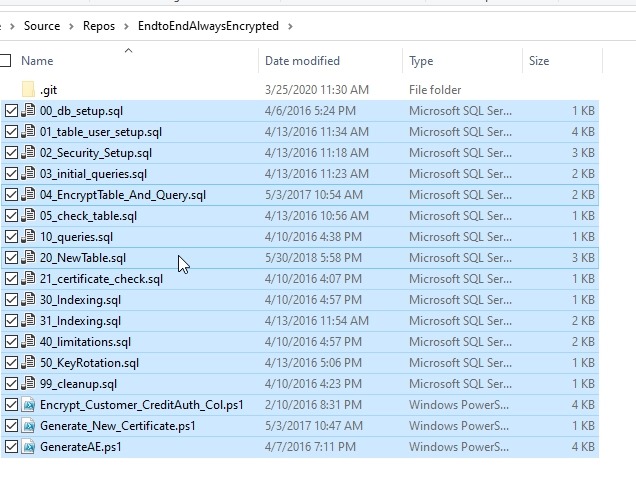
    This initializes a repository. There’s nothing in there bit a hidden .git folder, but that’s fine. I now paste in my code.
    2020-03-25 11_31_57-Window

    So far nothing is different with my code. However, if I check my status at the command line, I’ll see there are no files. I do this with

    git init

    This gives me some results.
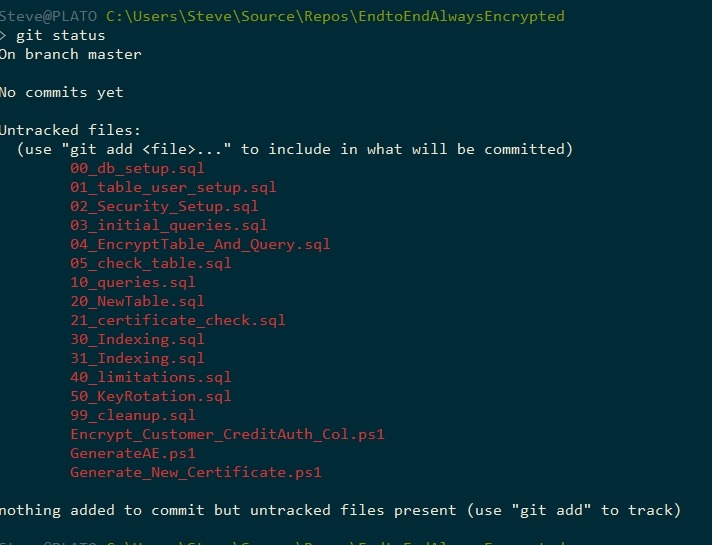
    2020-03-25 11_33_18-Window

    Don’t worry about the master branch item. The thing to notice here is that all the files in red are new and aren’t being tracked by git. To add these to my git VCS, I need to track them and then commit them. To track them, I’ll “stage” them with

    git add –all

    This will add all the files. I could use git add with a filename after it, or use the dot (.) to add everything.
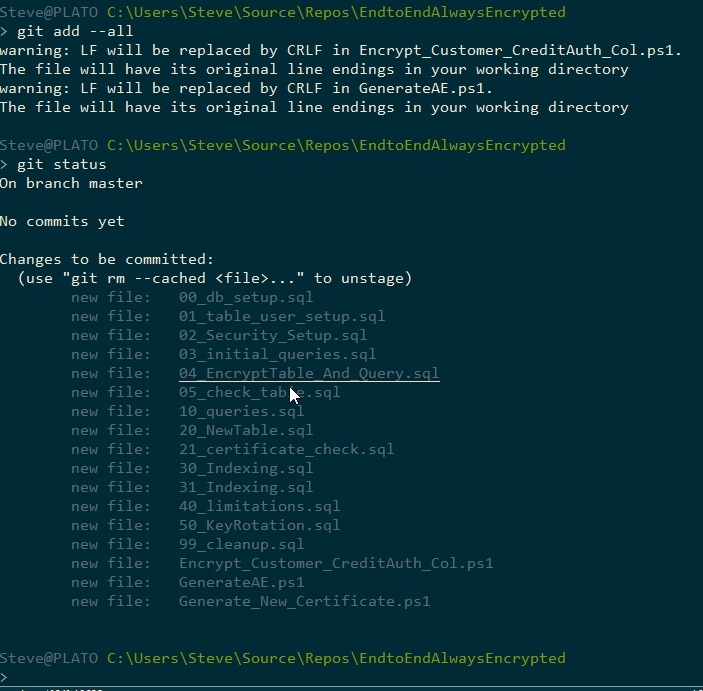
    2020-03-25 11_35_31-Window

    Notice now that the files are in a lighter color, as they are tracked, but not committed. A commit means that git now knows about this version of the code and will be able to return to this version if you need it.

    To commit, use “git commit”. You need a message for the commit. Most GUIs make this easy, and git will pop up a text editor if you want. I prefer the command line, and use the –m parameter with a message. For the first commit, “initial commit” is usually a good message.

    git commit –m “initial commit”

    Once you do this, the status shows clean, which means everything is being tracked by git.
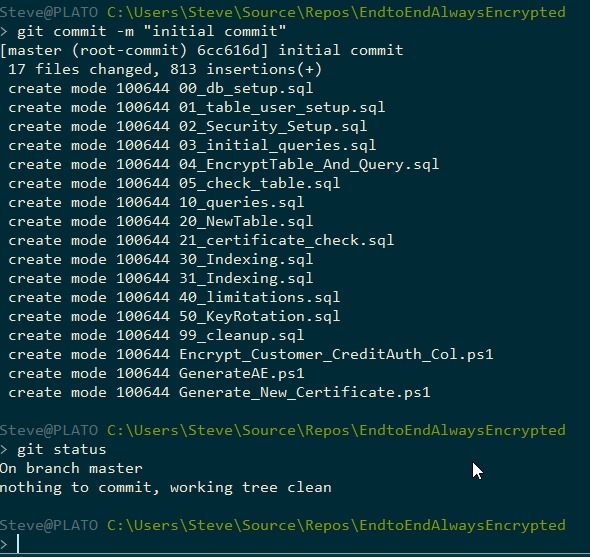
    2020-03-25 11_41_21-Window

    That’s it for getting started. This doesn’t seem like much, but it’s the basis for now tracking code. No more need for me to do something like “00_db_setup_old.sql” or “oo_db_setup_2.sql” for filenames. I can make changes, capture (commit) them, and then easily see what each version looks like.

    I’ll cover more later.

    If you want to see this as a video post, I’ve got it on my Voice of the DBA YouTube playlist here: https://youtu.be/hyyy9obHmw8

  • The Secret Password

    As I work with more server systems that help developers run Continuous Integration and automated releases, one of the things I see used often are variables. These are values you can set for a particular process and reference inside of that process. Great for setting server names, paths, etc. In releases, these are great for specifying specific values that change for each environment, such as the instance name or IP address.

    As with many developer based systems, security is not always set tightly on these systems and any developer can access the build server to kick off builds, reconfigure a process, etc. That makes sense in a CI process, but not so much in a release system. This is one reason I do recommend a separate release server from the CI server. You can use Jenkins or TeamCity to perform releases, but is it a good idea? Have you thought through the security?

    In the release servers, one thing that most systems allow the admin to do is use a variable for a password and mark it secret, so the value cannot be recovered. In this way, if some developer is working on the release process, they can’t get the password to the production server. They can only click the buttons that deploy to that server.

    However.

    They can deploy to that server, and they don’t need the password. If I were to execute a script in the release system that executes the “CREATE USER” and a “ALTER ROLE ” commands to give me access to data, does it matter if I know the deployment password is “G4da%$2h#5f” or $(ProdPwd)? It doesn’t. The actual value isn’t relevant; I just need to be able to use it.

    I think release systems are great pieces of software for reducing the risk of your deployments, but I do think the security models need to be carefully designed and easy to configure, especially when it comes to allowing arbitrary code to be submitted and executed by one person. Be sure that developers can’t necessarily deploy code directly to production servers, whether the password is hidden or not. If there is a way to use the value, someone will find it.

    Steve Jones


  • GroupBy–Bringing DevOps to the Database

    Today was my presentation in the April GroupBy conference lineup. I presented on DevOps and changing your database development to include more agile, DevOps, flexible development practices.

    If you want to get the deck, the slides are here: BringingDevOpstotheDatabase.pptx.

    The video is also up on the GroupBy Youtube channel

  • DevOps Basics– git Cloning Repos

    Another post for me that is simple and hopefully serves as an example for people trying to get blogging as #SQLNewBloggers.

    This continues my series on git, because I think it’s good to know what the command line is and how to use it.

    Once you have git running, the thing I’ve often wanted to do is go get code from somewhere. Certainly the creation of a repo and new code is something you might do, but often you’ll be looking to get code from somewhere else, so let’s look at how we can do this.

    Find a Repo

    Most of the time I find a repo somewhere in the company or on the Internet. Fro example, I have a simple database structure that I’ve used for demos at Github. This is my ASimpleTalkDB Repo, which is at: https://github.com/way0utwest/ASimpleTalkDB. You can see it here:

    2017-04-06 13_54_32-way0utwest_ASimpleTalkDB_ Demo repo for Presentations

    Off to the right is a “clone” button, which is what we want to do. We want to perform a git clone. If you click the button, a URL is in an edit box. The URL is: https://github.com/way0utwest/ASimpleTalkDB, the same as the repo above.

    Let’s clone this. First, get a folder to store code in. I started with a Documents\Github folder on my various machines. I’ll use that, and as you can see, this is a place I have a number of folders, each one a repo. I don’t have this repo set up yet.

    2017-04-06 13_58_06-C__Users_way0u_Documents_GitHub

    I’ll clone this from the command line. The various tools do this, but now you’ll understand how this works. First, open a command line in this folder and then type “git clone https://github.com/way0utwest/ASimpleTalkDB”. This will clone the code, as shown below:

    2017-04-06 13_59_46-way0utwest_ASimpleTalkDB_ Demo repo for Presentations

    By default, the name of the repo becomes a folder name, with all the code below that. If I look in Explorer, I can see this.

    2017-04-06 13_59_58-C__Users_way0u_Documents_GitHub_ASimpleTalkDB

    However, I can control this. I’ll delete the folder and do this again. That’s the power of a VCS. I don’t need to worry about this code, because I’ll go get it from another repo.

    Once I delete the folder, I’ll re-run the git clone command, but with the name of a folder added to the end.

    2017-04-06 14_01_55-cmd

    These objects, 264 of them, copy to my machine in a few seconds over hotel wi-fi. This is code, just text, and it’s quick. If I change to the folder and check the status, I see it is a real repo:

    2017-04-06 14_03_01-cmd

    Cloning Folders

    What if I have code inside the company, and not in Github, Gitlab, BitBucket, VSTS, etc. Can I clone things? Yep, you can, but don’t use this to get a copy of your own code. That’s what branches are for. We’ll talk branches later, but for now, we can assume you might have a repo in your company.

    For example, let’s assume for a moment that my C:\users\%username%\source\repos folder is on the network. I can clone one of these repos like this:

    2017-04-06 14_08_12-cmd

    Again, this isn’t the way to get a copy of my own code to work on. This is for getting a repo that I want to work on for myself, where I’ll then merge changes back to the original repo on another machine. On my own machine, I’d just use branches.

    2017-04-06 14_08_12-cmd

    This will help you get some code, and I’d encourage you to copy some code down and see how it works. Go get some code from my repo and build a db if you have SQL Source Control (point this to your cloned repo), or grab something from Microsoft and play.

    That’s it for this post. There are lots of places to go. I’ll talk about how to now push your code elsewhere once you’ve changed it in another post as well as how to branch and accomplish a few other things.

    A few resources (more boring, but will help you learn if you want):

    git clone (git)

    Create a Repo (Channel 9)