Tag: software development

  • Exercism

    I’ve been looking to work on my programming skills a bit and try some new languages. I’d like to grow my career in a few different ways, as well as investigate where some of the new languages and platforms might be useful for data analysis. As I’ve talked to some developers and been looking around, someone recommended Exercism.io.

    Exercism.io is a site that allows you to practice coding exercises and get feedback from others. When you visit the site, it’s an interesting look, and invites you to log in through GitHub. If you’re not a member of GitHub, and you’re a developer, you probably are making some sort of mistake.

    2015-09-14 11_36_06-exercism.io

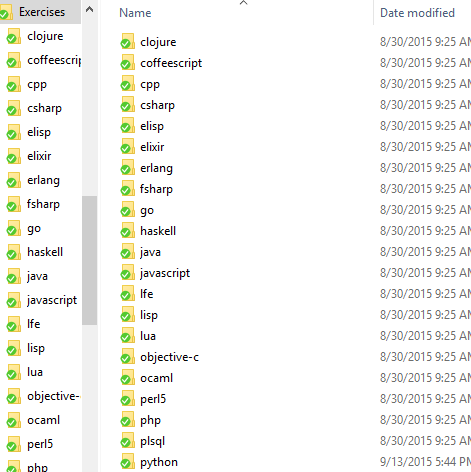
    Once you log in, you really need to download the command line client and execute it. Once you do, you can configure it to connect and download exercises. Each of these is placed in a folder, as shown:
    2015-09-14 12_41_27-Exercises

    For each of these languages, you get an exercise that you need to complete in that language. I’ve been playing with Python, and I had a first exercise of hello-world. In the python folder, were my exercises (you can see I’ve moved on).
    2015-09-14 12_41_38-python

    The hello-world folder had a read me and a test file (it’s since gotten my program in there). The Readme has instructions and the test file is a set of tests that can be executed to check your program.

    2015-09-14 12_46_15-hello-world

    When you pass the tests, you submit your solution from the command line client. The submissions appear on the website and people can comment on your code. I am in no way commenting on any else’s Python code at this point, but I did get a comment on my leap year calculation.

    2015-09-14 12_46_26-exercism.io

    I looked over the comment and then changed some code. I had to futz with the command line to get this to resubmit, but as you can see, I ended up getting a second iteration in there. No comments on that one, but we’ll see.

    It’s an interesting idea to share code and get comments. I think mostly this is a way to formally practice some exercises and get comments from experienced users, but the volume means that potentially you won’t get comments on your solutions. I know many of the SQL users may, or may not, comment on solutions.

    I think this is interesting, and I’m tempted to try to do something like this for SQLServerCentral. The hard part of putting together enough questions that others can practice in an organized fashion.

  • Data Masking for Convenience

    I was at Microsoft in Redmond recently and heard an interesting comment from a SQL Server developer. I was debating the data masking feature with a friend, and we were torn on the value of this for various situations we’d each encountered in the past. There are some restrictions, and it doesn’t seem that data masking is really offering a lot of security.

    The Microsoft developer, however, noted that this isn’t really a high security feature. It’s a developer feature. The design of data masking is to prevent that same code from being rewritten over and over by application developers. The use case is really to help with systems that might read some data, like those that print off part of an account number, ID number, credit card number, etc.

    If you read up on the restrictions, this makes sense. If you are just trying to make development more convenient, the feature makes sense. I hadn’t thought about that use case, but the more I consider this, the more I’m sure that data masking does remove a bunch of code that developers might be re-implementing themselves, perhaps with highly variable levels of quality. It also removes the chance that application developers will accidentally pull sensitive data to a client and (poorly) implement mask replacement there.

    I think this feature is being mis-marketed a bit, really to increase sales to executives and management. I’m sure there isn’t anything we can do about that, but I’d love to see technical documents and information about this for developers and DBAs. Give us a more realistic use case and give us better guidance. I think if we got that for many features, there might be more positive responses and great interest from technical professionals to the changes in the SQL Server platform.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.3MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • Who’s a Good Developer?

    I hear people in all industries and careers say that all of us should hire the best person for the job. We should pick the most qualified person and engage their services. However what’s left out of most of this advice is the most important question: how do you measure the best?

    We talked about this recently in a DLM Workshop led by Ike Ellis. He asked the question: how do you tell who’s a good developer? Think about it for a few minutes. I’m sure you (think you) know who the best developer or DBA is in your company, but how do you know? What’s the measure?

    I suspect you’ll find it to be a very abstract idea. Perhaps it’s like pornography, where you know a good developer when you see them, but if so, then have you always been able to tell a good developer right away? In an interview?

    Embedded in the idea of determining who’s good and who’s not is the idea of ranking. Is there any way to rank one developer over another? I think you might be able to do so, but only in broad ranges. We (as a group) might feel Developer A is better than Developer B, but not necessarily better or worse than Developer C. However, do we have any way of ranking these two that would stand up to outside analysis?

    I don’t have any great ways of measuring one developer v another. A best I think you can trust a developer to get a particular project done, and to the satisfaction of the client. However the trust would be based on previous experience and not any objective measures.

    This isn’t likely to be a problem that we will solve anytime soon, in any industry. I think the best way to gain confidence in someone is to examine their body of work. See how it matches up with the work expected from an individual and then cross your fingers, trusting they continue to perform as expected.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.4MB) podcast or subscribe to the feed at iTunes and LibSyn. feed

  • The History of the VCS

    I’ve been looking for ways to convince more DBAs to use a version control system for their code. I realize that many of you have gotten along without them for years, but that doesn’t mean it’s a good idea. A VCS is like a safety net, and someday you’ll be glad you have one.

    Recently I was reading about the history of VCS, and ran across some interesting posts. One on some amazing things, and another that has a timeline, showing us to be in a Renaissance period. If this is the Renaissance, then what comes next? I can’t even imagine, but I suspect someone will improve the process.

    It’s incredible to think about the ways in which we’ve managed versioning code in the past. I’m sure most of us have used comments to both document as well as preserve old code. Some of us have worked with simple backups of files, one per day (for a week or month), or dealt with a first generation system where only one person could work with a particular file.

    The move to CVCS systems, like TFS or Subversion, was a major improvement, allowing everyone to work on all the code, and merge their code with others when they needed to commit. That’s a system many of us inherently understand. It’s what we would do in an offline system. However the DVCS systems (Git, Mercurial), are much more complex, and they can be confusing. However separating the ability from committing changes to performing the merge can be valuable, especially in distributed development.

    More and more tools are integrating version control, including for database code. Whether you like or hate TFS, it includes lots of additional functionality to allow bugs, features, and other workflow items to link to the VCS items that solve them.

    The choice of which system works well in your environment will probably be driven by arguments from your development staff. Some will prefer one interface over another or feel the need to work offline, but I’m not sure it really matters which system you choose. I’d pick one of the modern CVCS or DVCS systems and use it.

    That’s what’s really important; you need to use the system and track your code. It’s frees you as a developer, allowing you to clean up your code, remove excess comments, and easily find out what worked (or didn’t) in previous code.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.9MB) podcast or subscribe to the feed at iTunes and LibSyn.