Tag: software development

  • Technical Debt

    I was speaking with one of the development teams at Redgate earlier this year. They were working on a product, and had planned out a few sprints worth of work. Each sprint, called a train, was a couple weeks long, with specific goals and ideas to be implemented. That was all good, but I noticed that there was a sprint in the middle of the list that was devoted to technical debt.

    Technical debt is a strange term. It’s one that many managers don’t understand well, often because the code may work fine. I ran across an interesting piece that looks at what the concept means, with what I think is a good explanation. We get technical debt when we sacrifice maintainability to meet another requirement. The piece also looks at the accumulation of the debt and why it becomes problematic later. Certainly the more debt that piles up, the mode difficult it can be to change code. Since we are almost always going to go back and maintain code, this becomes a problem.

    I think the ideas given to keep technical debt under control are good ones. We should make an effort to clean code as we can, though not make it such a priority that we end up causing more work with constant refactoring. We do need to get work done. However the suggestions given require a good amount of discipline and buy in from management, and I’m glad Redgate tries to keep debt under control. I think our developers like the debt trains as well.

    I thought the idea was pretty cool until I was looking for a feature to be completed and the technical debt train was running that week. I thought about complaining, but I decided to have patience and wait a week. After all, if the debt isn’t kept under control, I might be waiting much longer than a week for some fix or feature next year.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.4MB) podcast or subscribe to the feed at iTunes and LibSyn.

  • Python and Tweepy

    One of the projects that’s been on my list lately is to programmatically access Twitter for a few ideas I want to play with. Since I’ve been trying to learn some Python, I thought I would take a look using Python to update status and read status.

    A quick Google search showed me lots of Python clients, but Tweepy caught my eye for some reason. I’m not sure why, but I ended up popping a command line open and downloading the library.

    From there, I saw a short tutorial over at Python Central. I started by creating an app at Twitter for myself, which was very simple. Once that was done, I had a set of consumer tokens (key and secret), that I could use. Another click got me to the access key and secret. Note, the easy way to do this is over at dev.twitter.com.

    My first attempt was using this sample code.

    import tweepy

    consumer_key = “ABCDE”
    consumer_secret = “12345”
    access_token = ‘asdfasdf’
    access_token_secret = ‘98765’

    auth = tweepy.OAuthHandler(consumer_key, consumer_secret)
    auth.set_access_token(access_token, access_token_secret)

    api = tweepy.API(auth)

    public_tweets = api.user_timeline()
    for tweet in public_tweets:
    print(tweet.text)

    This gives me a list of my tweets. At least, the last 20.

    2015-11-06 13_30_24-SDTIG - [C__Users_Steve_OneDrive_Documents_Python_SDTIG] - ..._Last_10_twitter_l

    That’s progress.

    I then went to make an update by using this:

    api.update_status('Hello, Pyton')

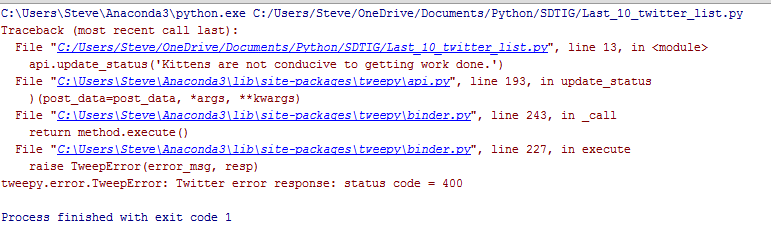
    However that returned an error:

    2015-11-06 13_50_53-Cortana

    Hmmm, I double checked the API, and this should work, but I’m guessing there’s another issue. I searched, and found there’s a bug. However, I should be using named parameters, so no big deal. Change the code.

    api.update_status(status='Hello, Pyton')

    Now it works.

    2015-11-06 13_53_06-Steve Jones (@way0utwest) _ Twitter

    This is the first step for me to look at building an app that might send some tweets on my behalf, perhaps with the data stored somewhere, like, I don’t know, maybe a database?

  • Rogue Software Changes

    Could a group of software developers make changes that fundamentally alter the way a software system should work without management being aware?

    That’s the question being asked of VW right now. Most people are skeptical, but I ran across a piece that wants to lend credence to the idea that a few software engineers acted with few people being aware. They did this, not because they wanted to defraud everyone, but they wanted a solve a problem that they couldn’t do in other ways. They also didn’t see the alteration of test results as much of an issue because they thought the tests were too stringent.

    I’m not sure I believe that’s what happened. Certainly there is some disagreement from various parties, but with my experience in software projects, management always wants to know how things are proceeding, with more and more questions whenever the applications don’t work as expected. When problems are solved, natural human curiosity leads more managers to ask for details, even when they don’t understand. In this case, I can’t imagine lots of VW management weren’t aware that software was being used to pass tests. Many people report to many others, and everyone would have wanted to know how VW solved this engineering problem.

    The stakes for organizations will continue to rise in a global economy, and software will play increasing roles in many companies. Will we see more and more pressure to manipulate our world with software, even in criminal ways? I suspect so, and I sympathize with those that might face the loss of employment for not complying with the requirements they’re given.

    Ultimately I think transparency of software is the best way to bring about better software that complies with regulations and rules. Transparency also ensures that copyrights aren’t violated (since violators code is available), and we can determine if security is being built into systems. Perhaps best of all, developers can all learn from each other, seeing exactly what works and doesn’t in each system.

    I doubt we’ll get there, but transparency would be a nice place to be.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.7MB) podcast or subscribe to the feed at iTunes and LibSyn.
  • Do You Have Scary Code?

    I once worked in a company that had a VB6 application (this was a long time ago), which had been mainly written by three developers working at the company. Two of them left, but we still have one of the original developer and five or six others that had worked on the application for a year or more.

    One day we were discussing changing a section of the application to add functionality. I was surprised to find that none of the developers wanted to work on the code. They were all “afraid” to make changes. Having been a developer and spent time digging through other people’s code, I was surprised. Certainly some tasks are difficult, but being afraid to change code?

    I wish I’d been more knowledgeable then. Today I’d tell the developers the first thing they need to do is write tests. They need unit tests, or integration tests, but they need some way to determine if they are breaking functionality.

    And if they do break something, that’s fine. Go fix the breakage. Refactor other code, write more tests if they are needed, and go for it. You learn by breaking things. Your tests protect you and let you refactor code. As much as I realize we don’t want to spend unnecessary time writing tests, we need something to examine our code as we write. We might as well use a testing framework to help. That way we’re not afraid to change the existing application.

    Steve Jones

    The Voice of the DBA Podcast

    Listen to the MP3 Audio ( 2.2MB) podcast or subscribe to the feed at iTunes and LibSyn.